
 #01
動画
短い動画でわかるAI
1本の動画で1つのアイデアを、わかりやすく。各動画から、ステップごとに解説する無料コースの章へ進めます。
ここから開始 AI 101
- #01
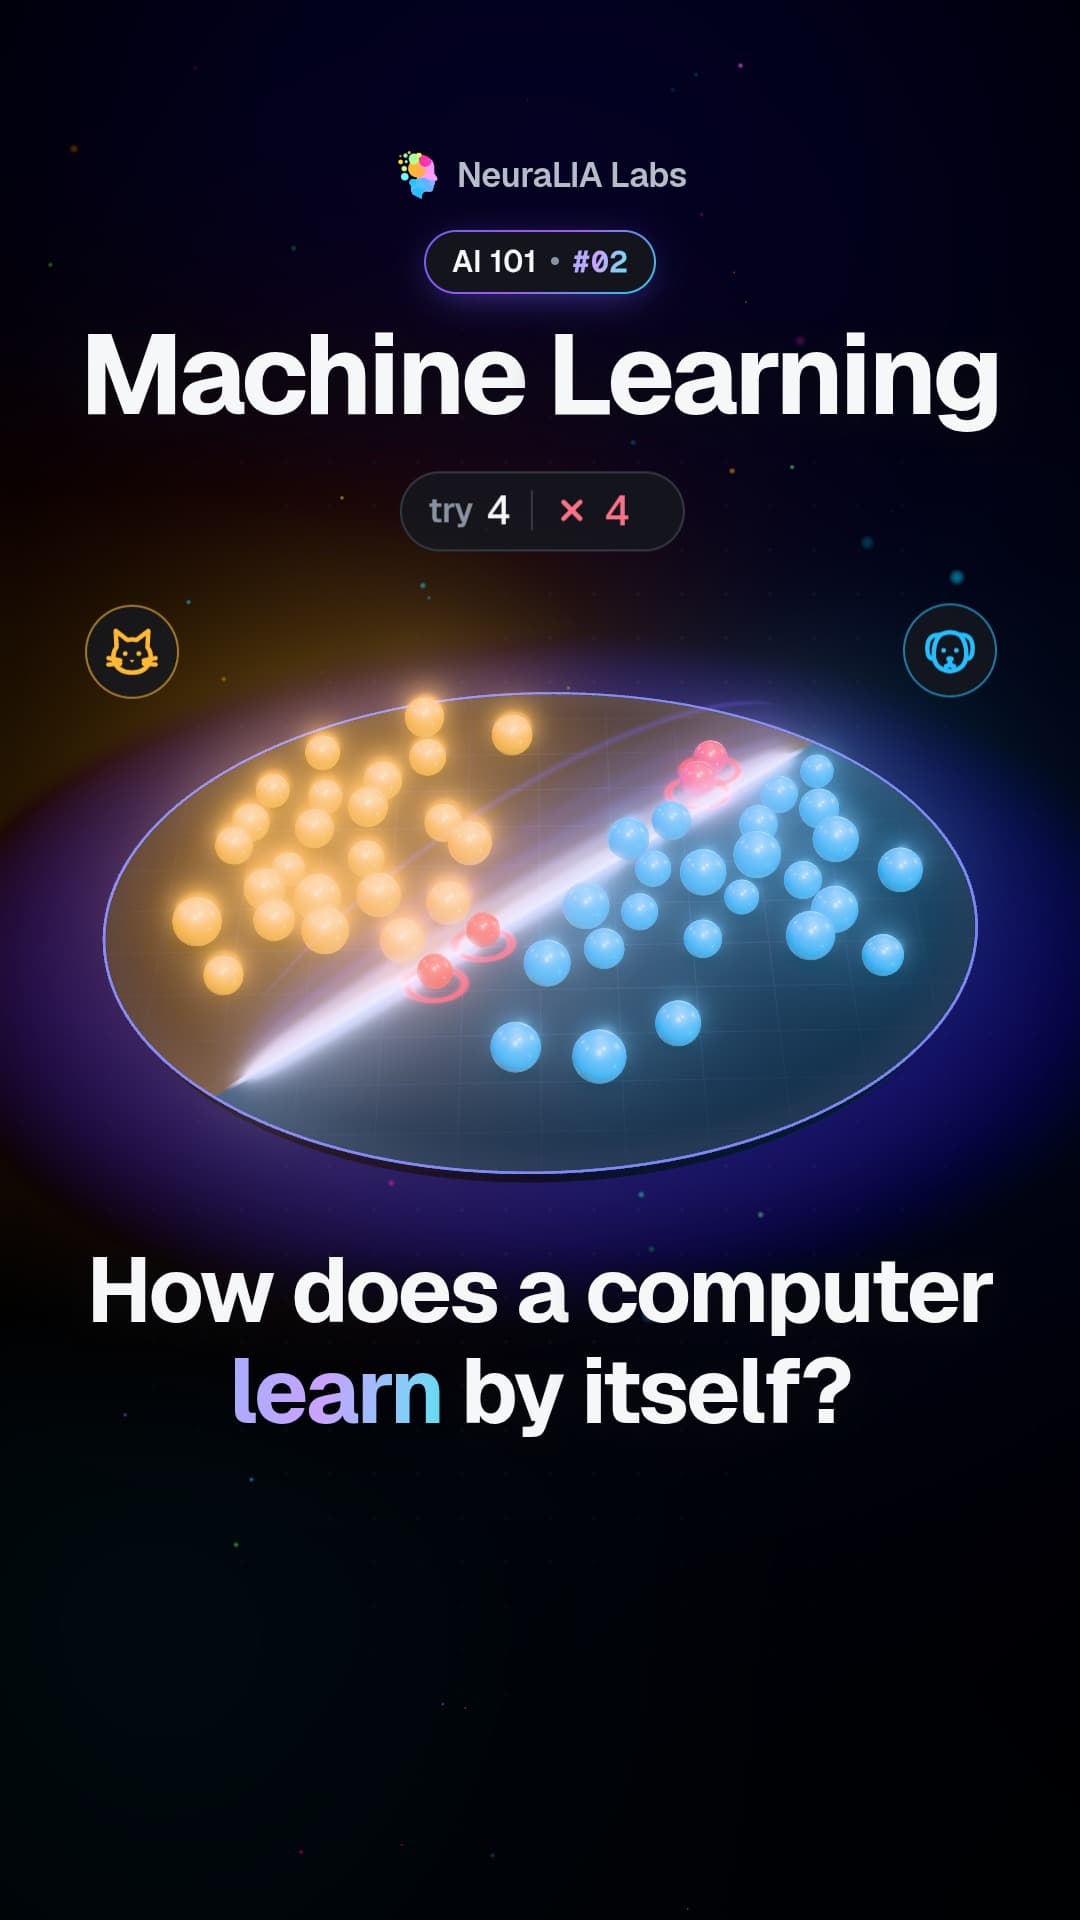 #02
Machine learning: how a computer draws its own dividing line
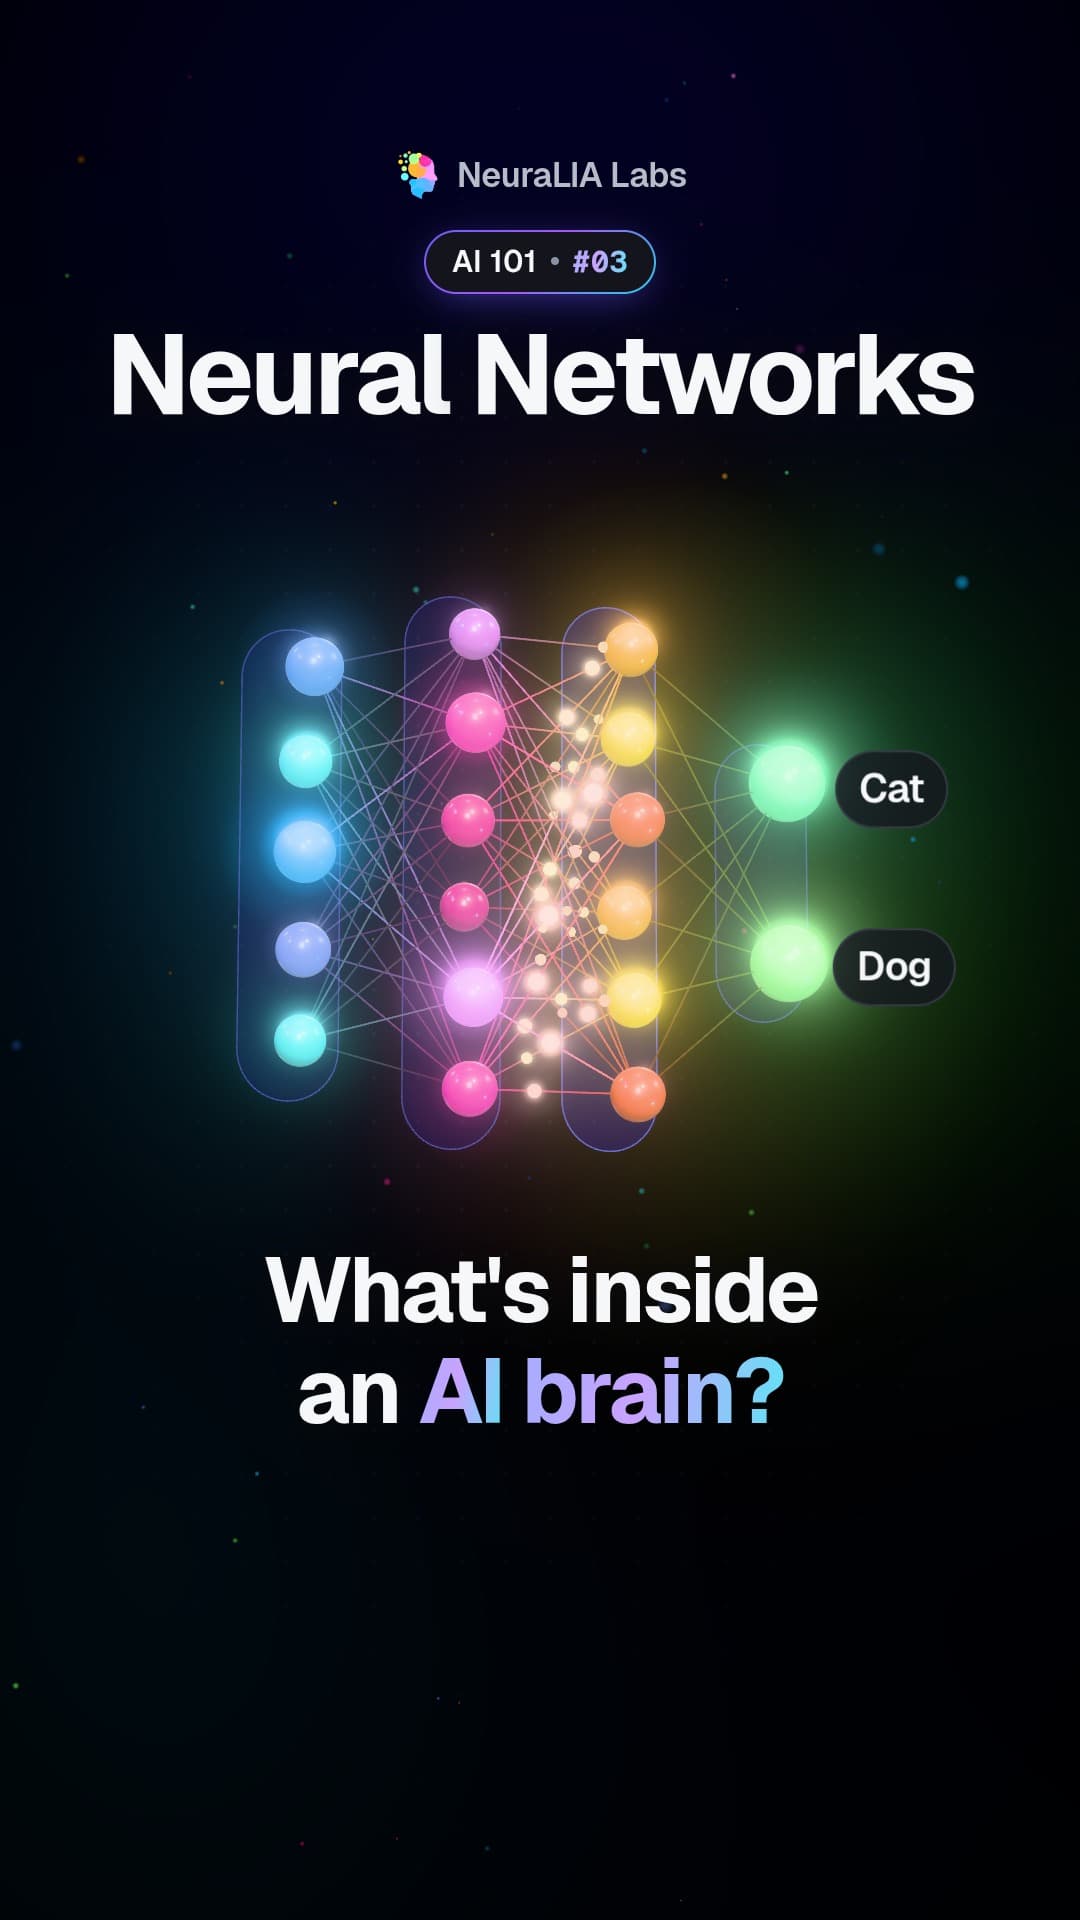 #03
Neural networks: layers of tiny calculators passing signals on
 #04
How AI learns: guess, measure the error, nudge, repeat
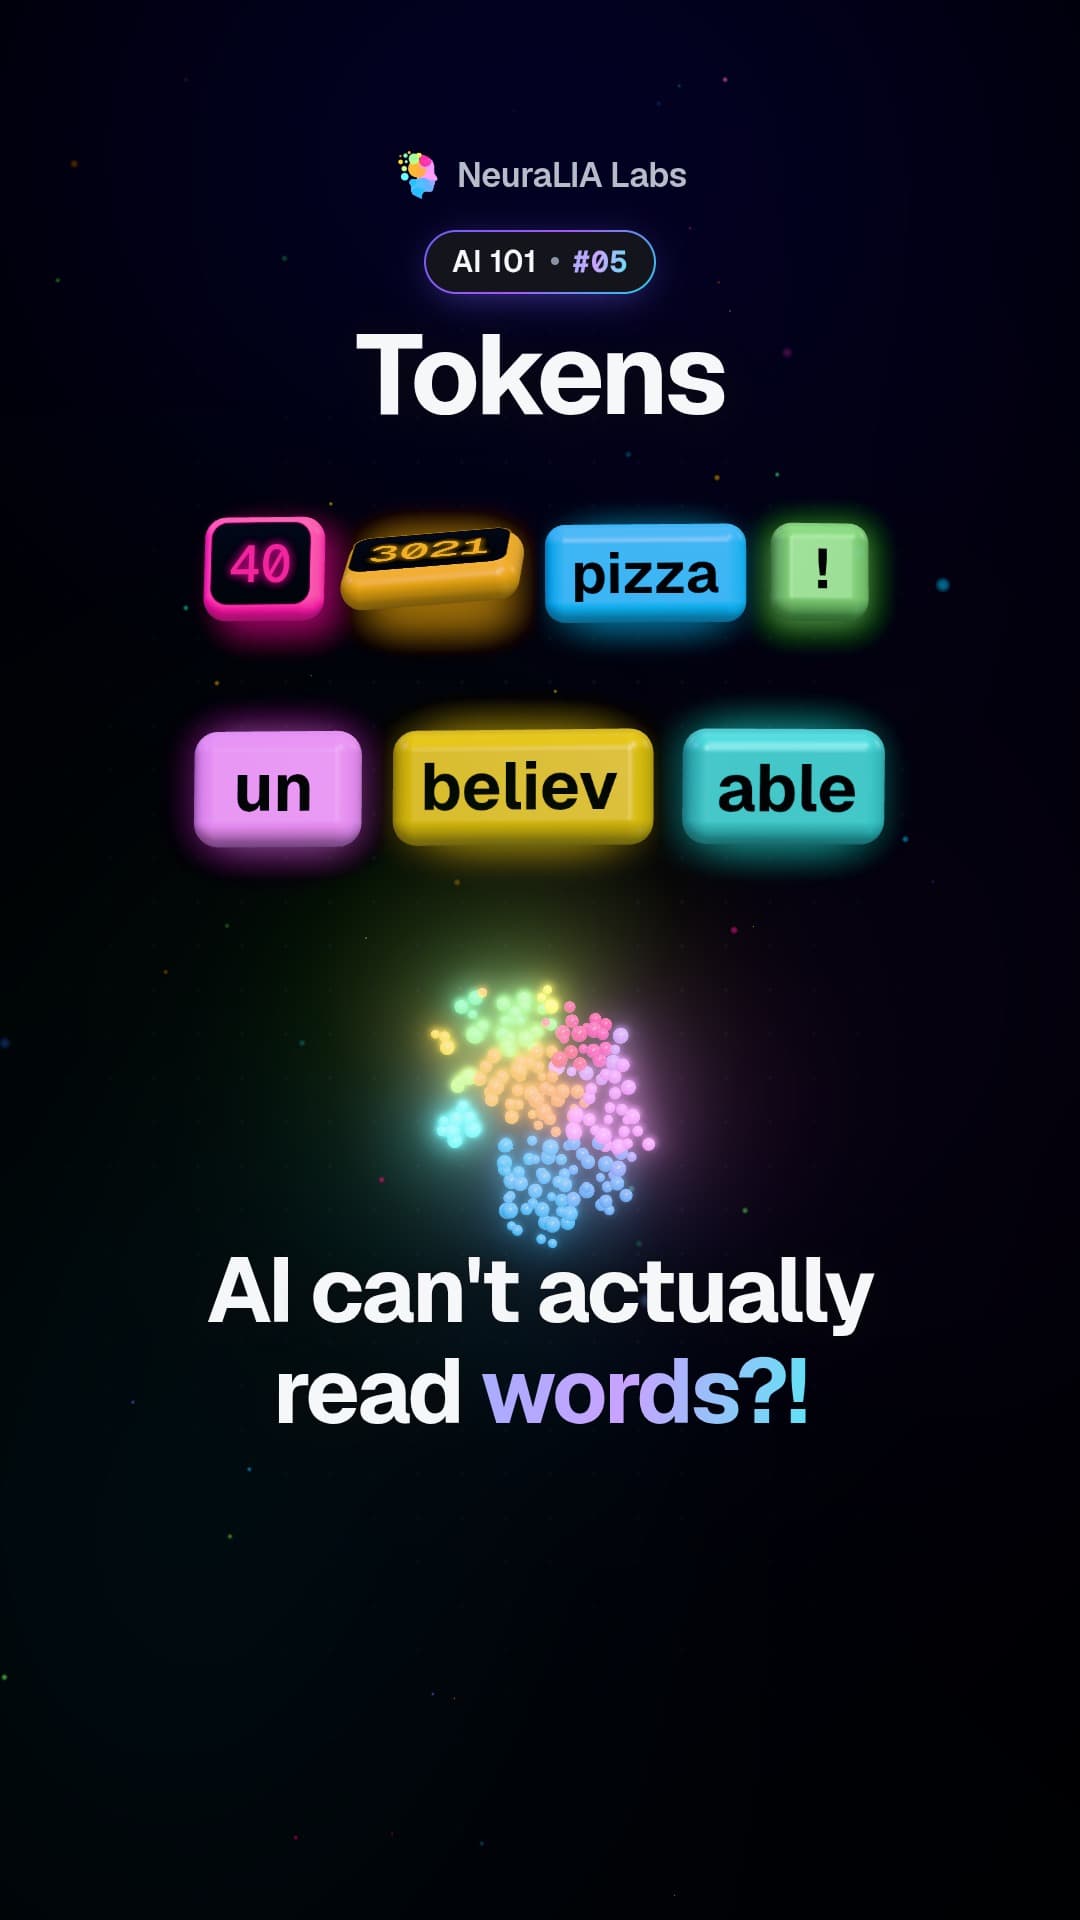 #05
Tokens: how AI chops your words into numbered pieces
 #06
Embeddings: why a puppy lands closer to a dog than to a pizza
最新
 #031
Momentum: how remembering past steps stops AI training zigzagging
 #030
Mini-batches: why AI learns faster from a random handful of data
 #029
Saddle points: where AI training looks stuck but has a way down
 #028
Local minima: why AI training can settle for second best
 #027
Condition number: why a stretched valley makes AI training crawl
 #026
Learning rate: the step size with a ceiling you can calculate
 #025
Gradient descent: how AI finds its way downhill in small steps
 #024
Gradient: the arrow that points uphill, and why AI walks the other way
 #023
Chain rule: how AI traces the effect of every layer
 #022
Derivative: how much the result moves when you nudge one input
 #021
Grid search: why you cannot train an AI by trying every setting
 #020
Robust loss: stop one wild reading from wrecking your forecast
 #019
Heavy tails: when rare, huge errors break the usual average
 #018
Mean squared error: the hidden bet behind squaring your mistakes
 #017
The LogSumExp trick: one subtraction that stops AI math overflowing
 #016
Rounding error: why adding the same numbers can give two answers
 #015
Floating-point numbers: why your computer cannot hold every number
 #014
Negative log-likelihood: turning a fragile product into a calm sum
 #013
Maximum likelihood: the answer that makes your data least surprising
 #012
Bayes' rule: reasoning backwards from a clue to its most likely cause
 #011
Chain rule of probability: how AI scores a sentence word by word
 #010
Loss landscape: training an AI means finding the bottom of a valley
 #009
Loss function: the scoring rule that decides which answer wins
 #008
Feature engineering: the human choice that can beat the algorithm
コースの章別
- 1ゼロから作るパーセプトロン:ニューロンは何を計算しているのか10本の動画
- 2損失関数はどこから来るのか:慣習ではなく likelihood12本の動画
- 3下り坂:Gradient Descentと、誰もが飛ばす2つのステップ12本の動画
- 4分類、クロスエントロピー、そして自分を欺かない方法
- 5Backpropagationをスクラッチから:エンジン、そしてネットワークへ1本の動画
- 6学習させること、そして汎化させること
- 7BPE Tokenizerを作る:モデルがRの数を数えられない理由1本の動画
- 8Next-Token Prediction:embeddingとperplexityの意味1本の動画
- 9平均から導く attention と transformer ブロック
- 10LLMのPretraining:データ、計算資源、Scaling Laws、コスト
- 11ベースモデルからアシスタントへ:SFT、RLHF、DPO、GRPO
- 12Chain of Thought、RLVR、Test-Time Computeを測る
- 13推論コストを下げる:KV Cache、Batching、量子化
- 14初めての本番 LLM 呼び出し:ストリーミング、リトライ、タイムアウト
- 15Prompt Engineeringを測る:何が出力を変えるのか
- 16Context Window、token、請求額を実測する
- 17Temperature、Top-p、そして手に入らない決定性
- 18Tool CallingとStructured Outputs:破綻しない契約
- 19本番RAG:chunking、retrieval、正直な引用
- 20fine-tuning、検索、それともprompt?判断基準は経済性です
- 21Multimodal Pricing:画像・音声・動画で本当に課金されるもの
- 22AI agentとは何か:古典的な5タイプと、競合する2つの定義
- 23Agent harnessを作る:ループと5つの脱出経路
- 24Context Engineering: Turn 40でagentが鈍る理由
- 25Multi-agentオーケストレーション:5つのパターンと、単一agentが勝つとき
- 26MCPを仕様に照らして解説:サーバーとは本当は何か
- 27MCP ServerをShipする:TypeScriptとPythonを実測
- 28Agent SkillsとSKILL.md:プログレッシブディスクロージャーを測る
- 29LLM評価:公開ベンチマークから自社のgolden setへ
- 30Prompt Injectionと致命的な三要素:実際のagentを守る