
 #01
영상
짧은 영상으로 쉽게 배우는 AI
영상 하나에 아이디어 하나를 쉽게 설명합니다. 각 영상은 단계별로 설명하는 무료 강좌 챕터로 이어집니다.
여기서 시작 AI 101
- #01
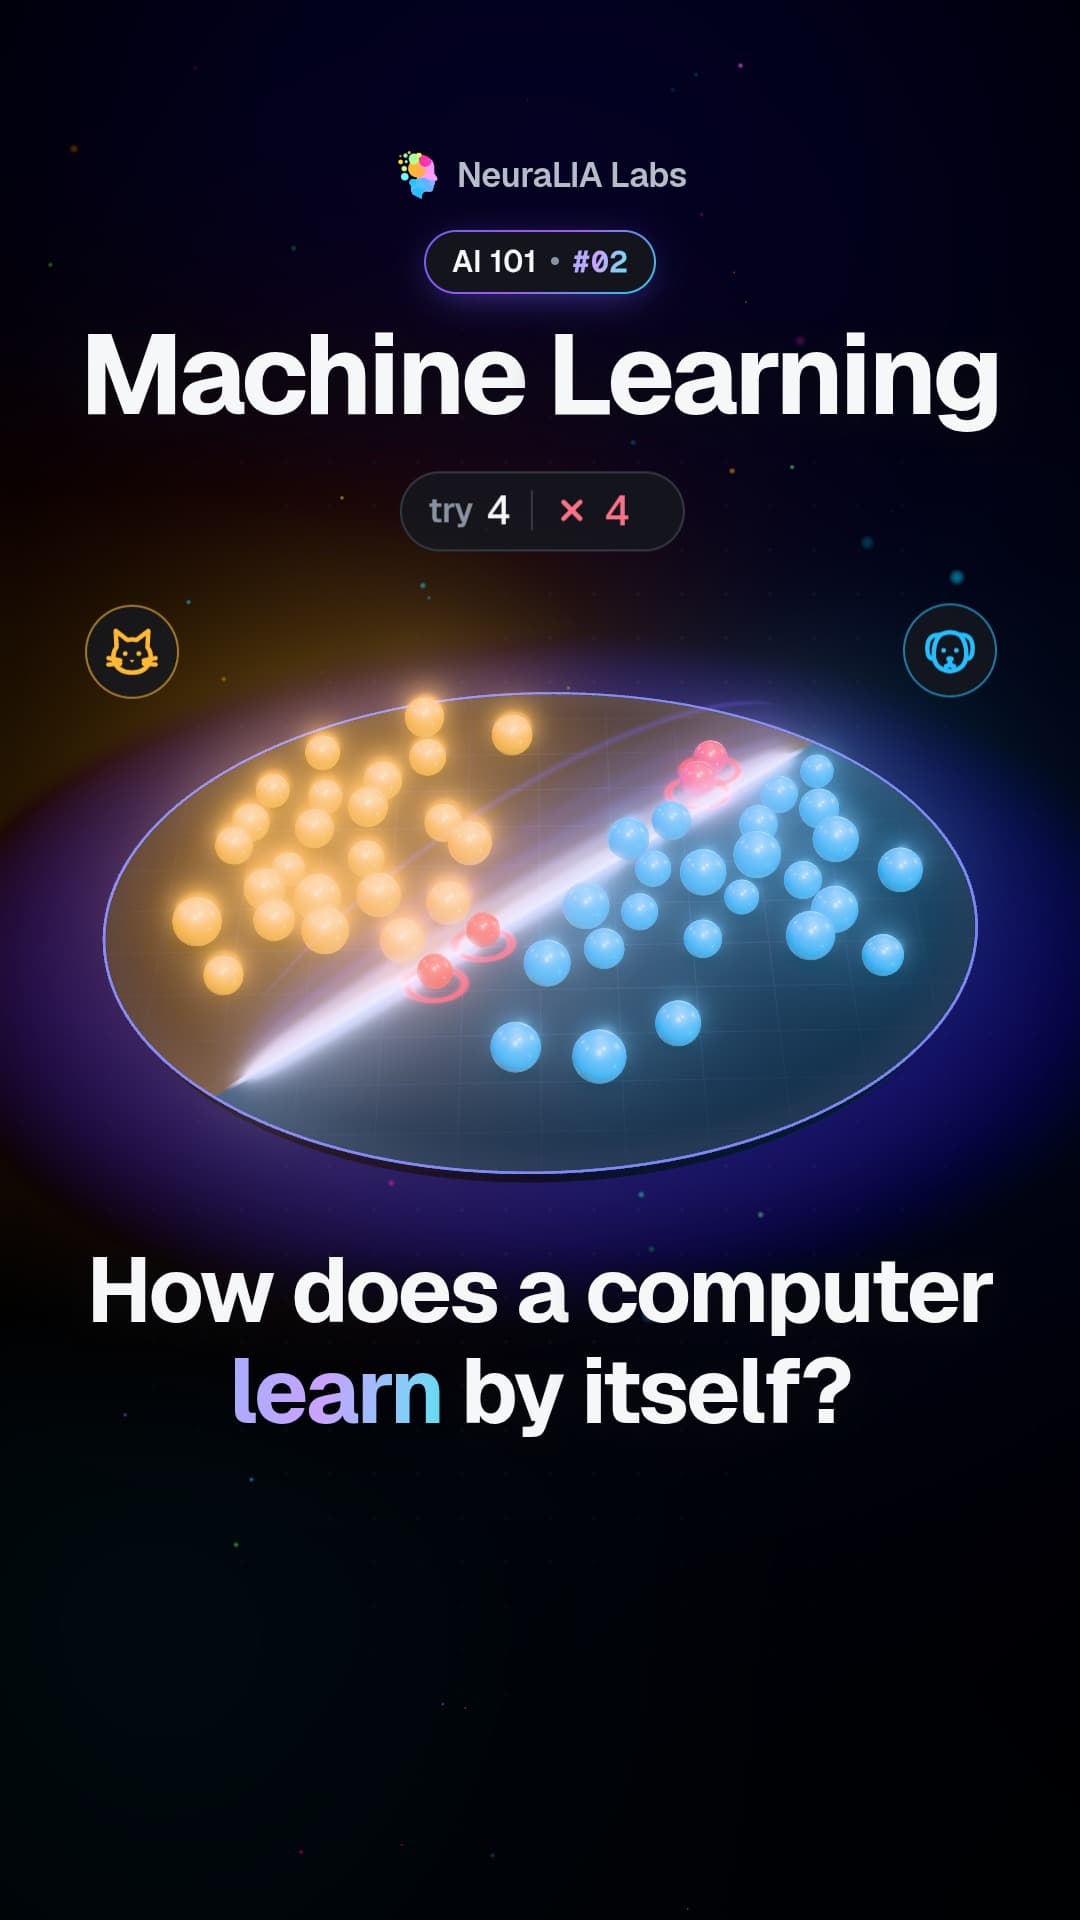 #02
Machine learning: how a computer draws its own dividing line
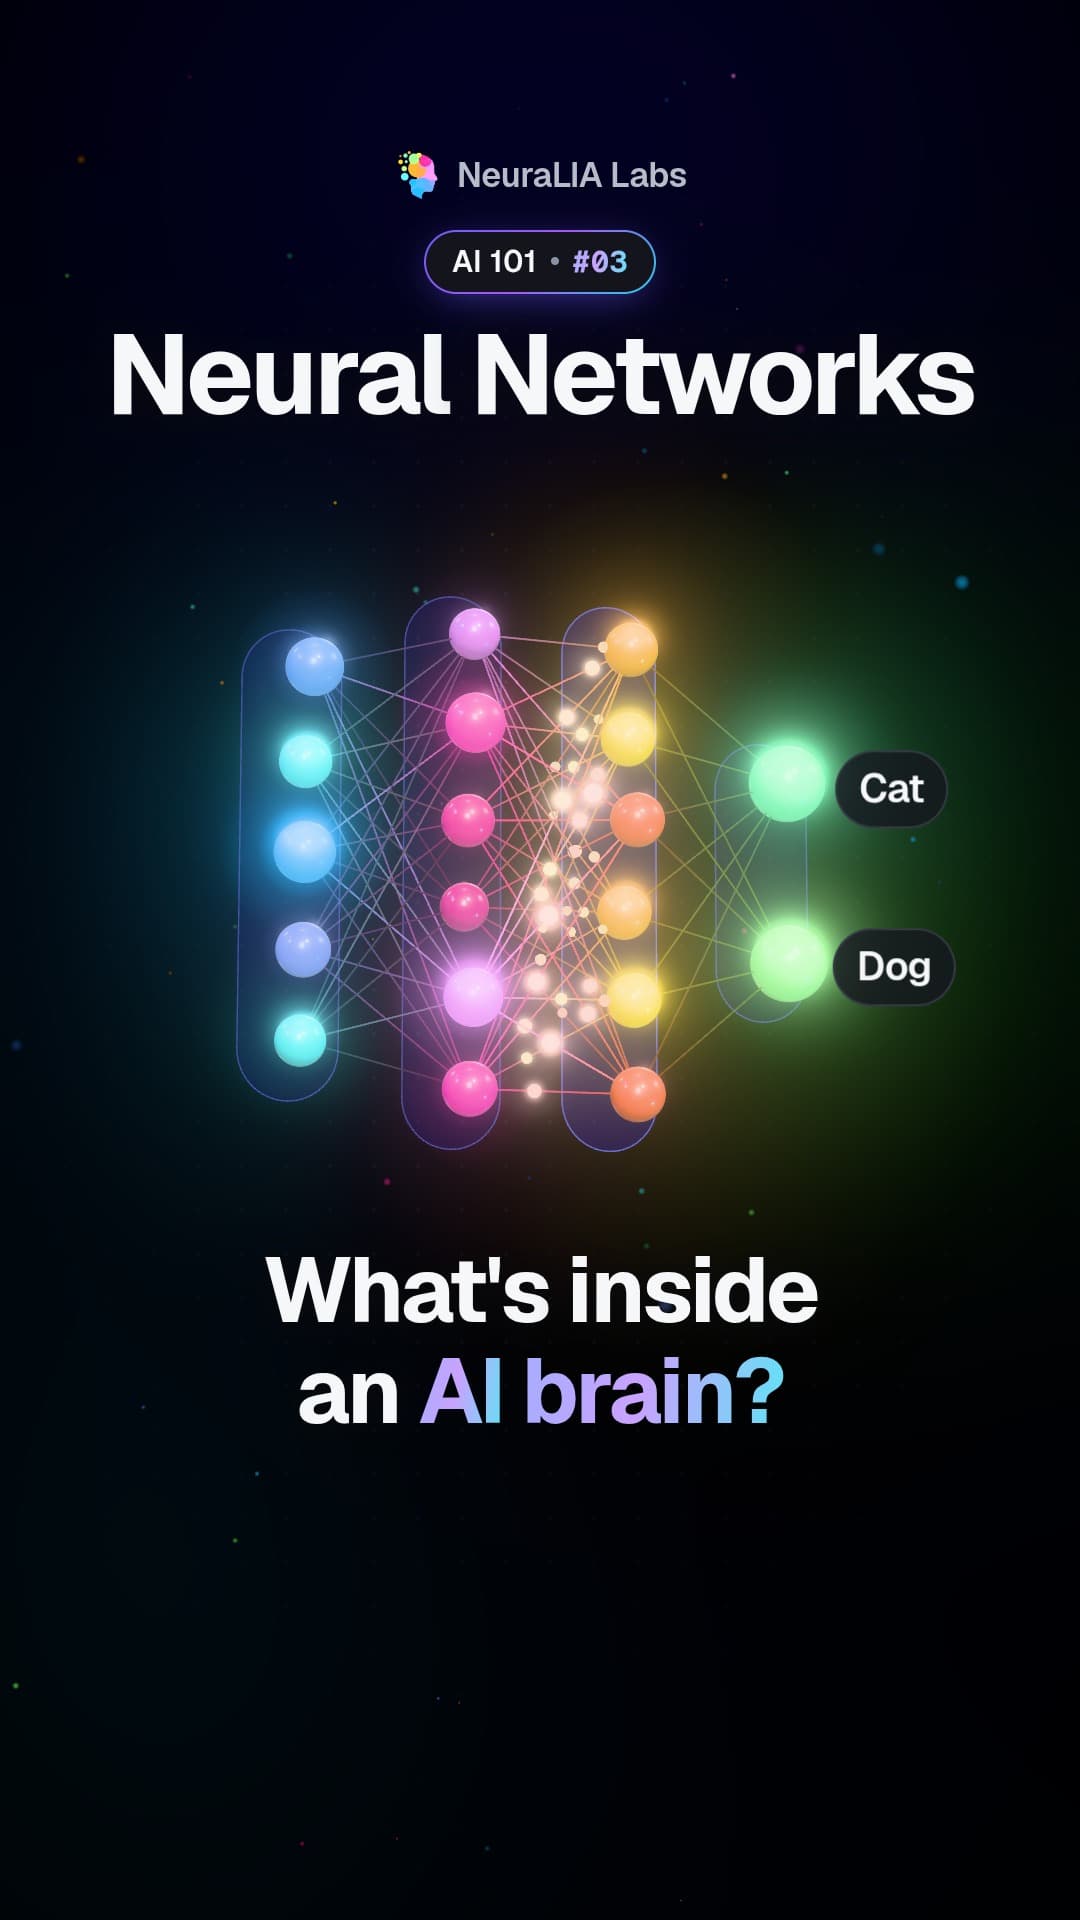 #03
Neural networks: layers of tiny calculators passing signals on
 #04
How AI learns: guess, measure the error, nudge, repeat
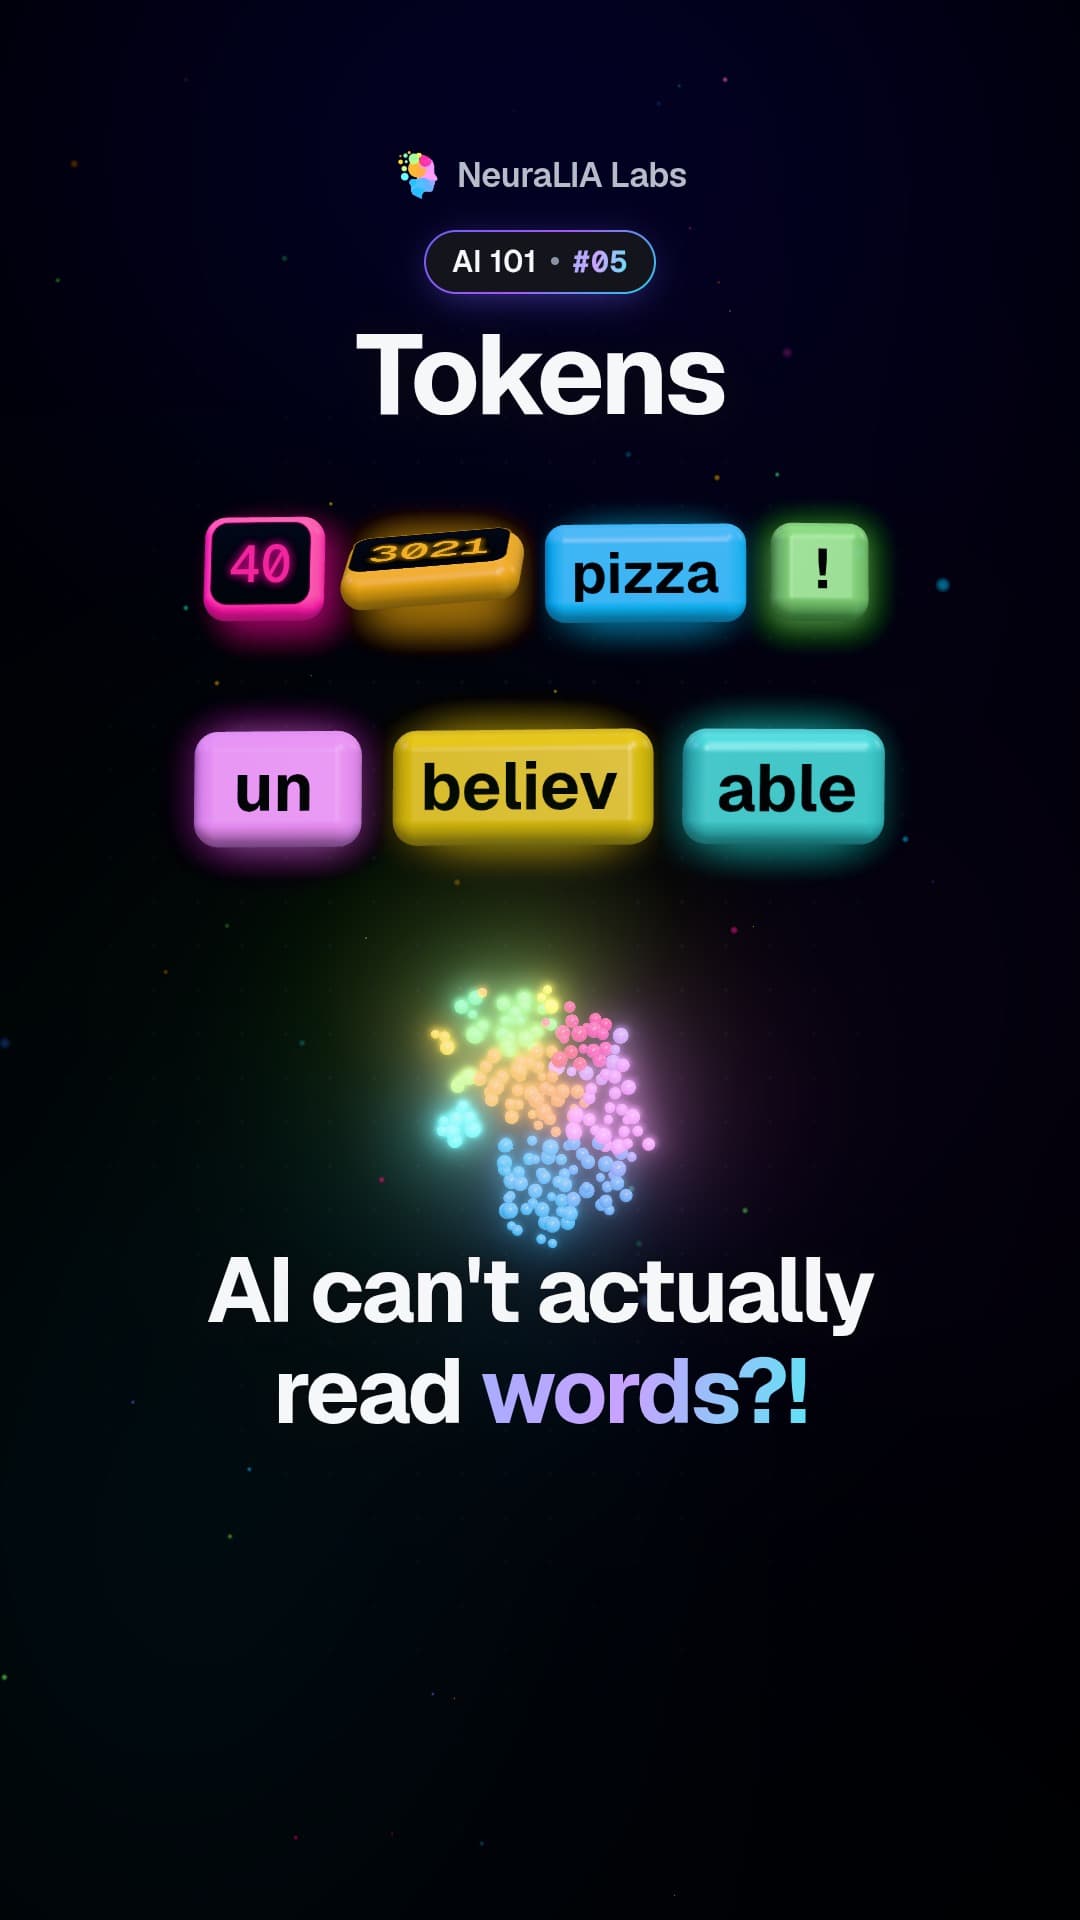 #05
Tokens: how AI chops your words into numbered pieces
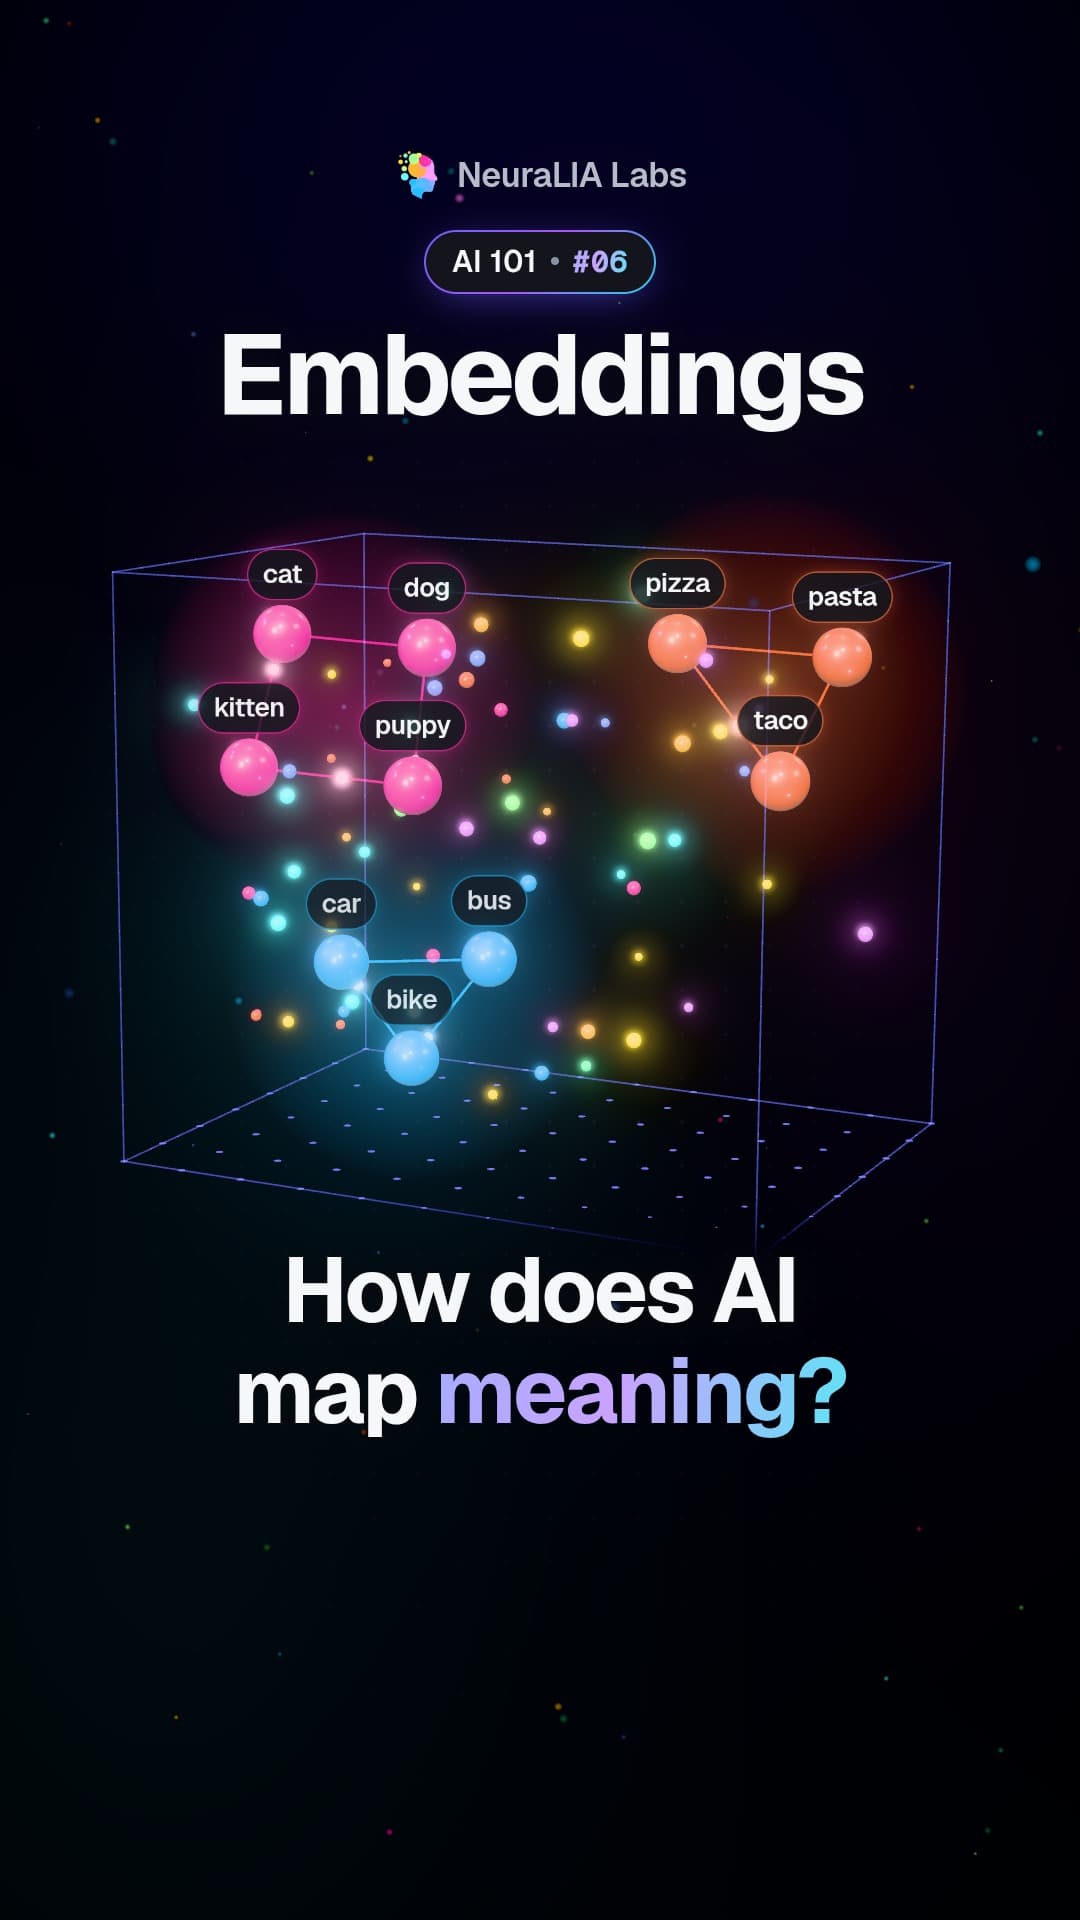 #06
Embeddings: why a puppy lands closer to a dog than to a pizza
최신
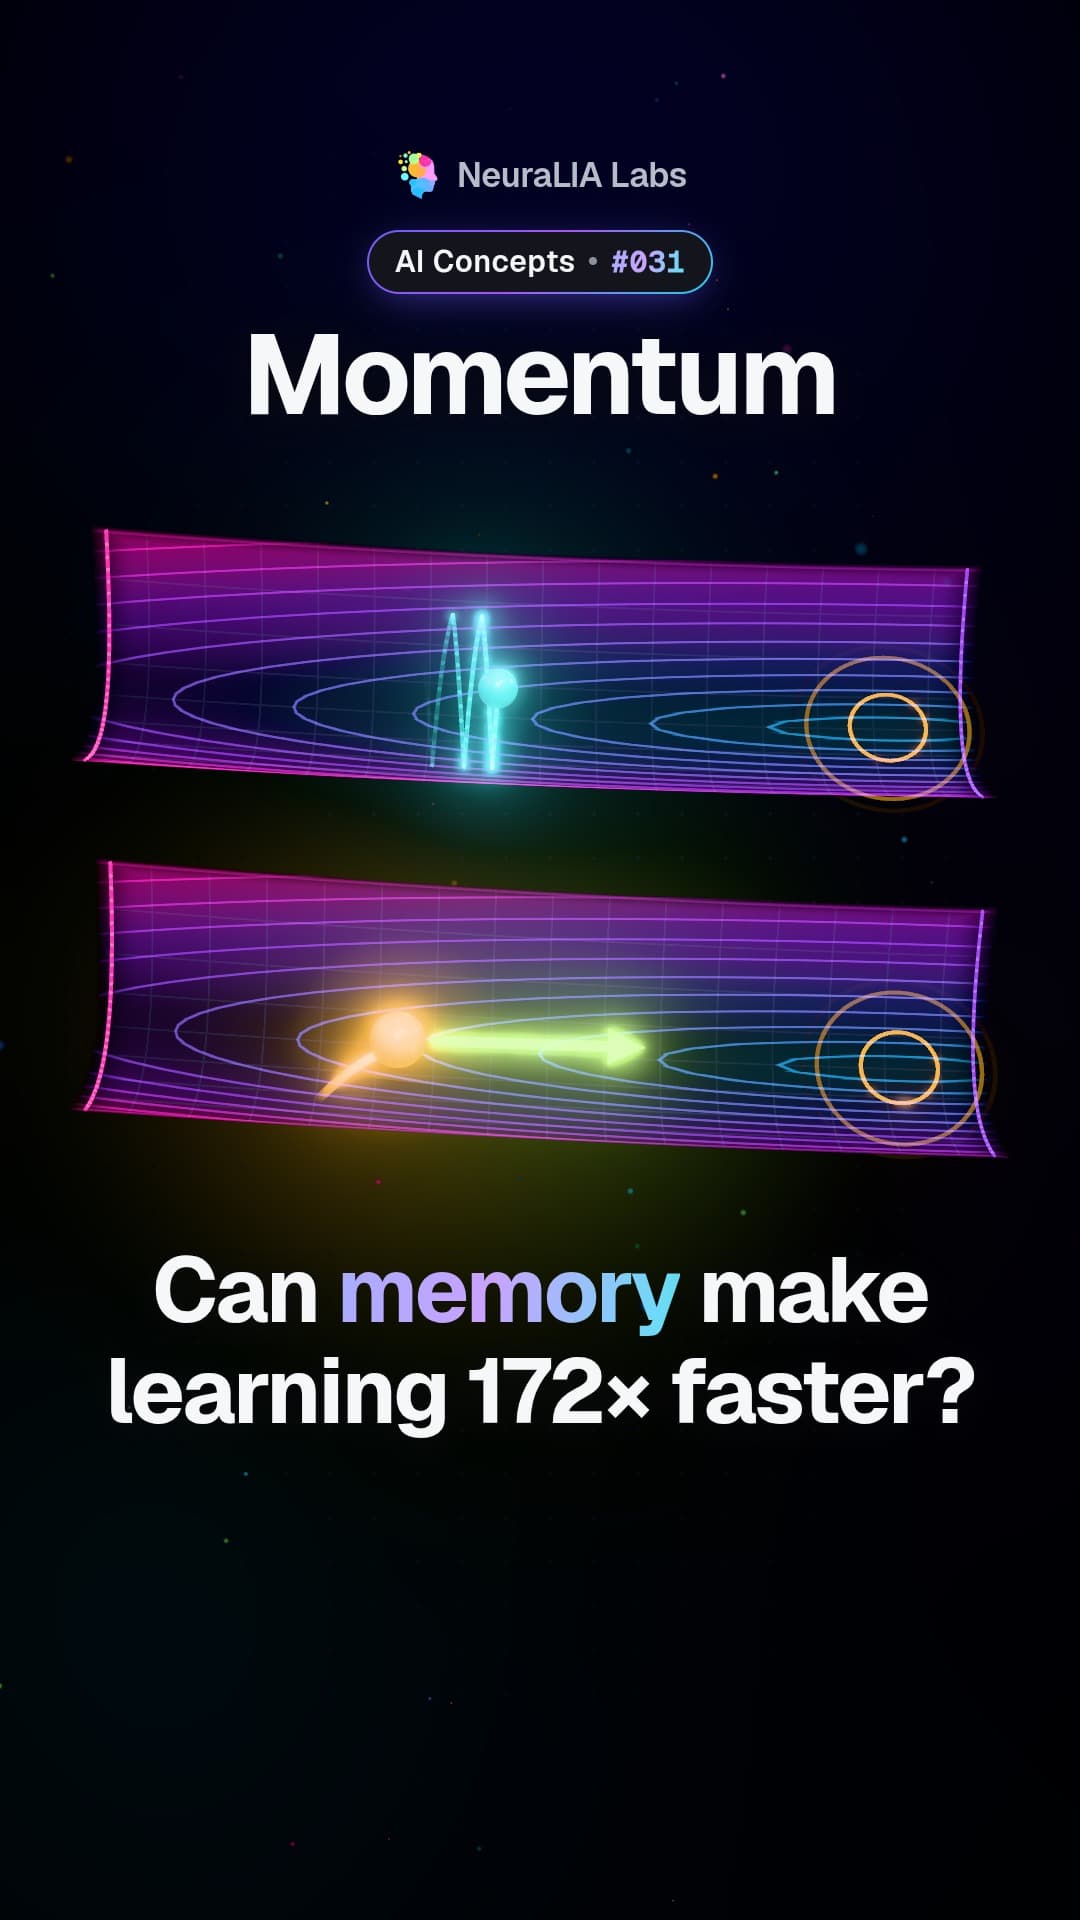 #031
Momentum: how remembering past steps stops AI training zigzagging
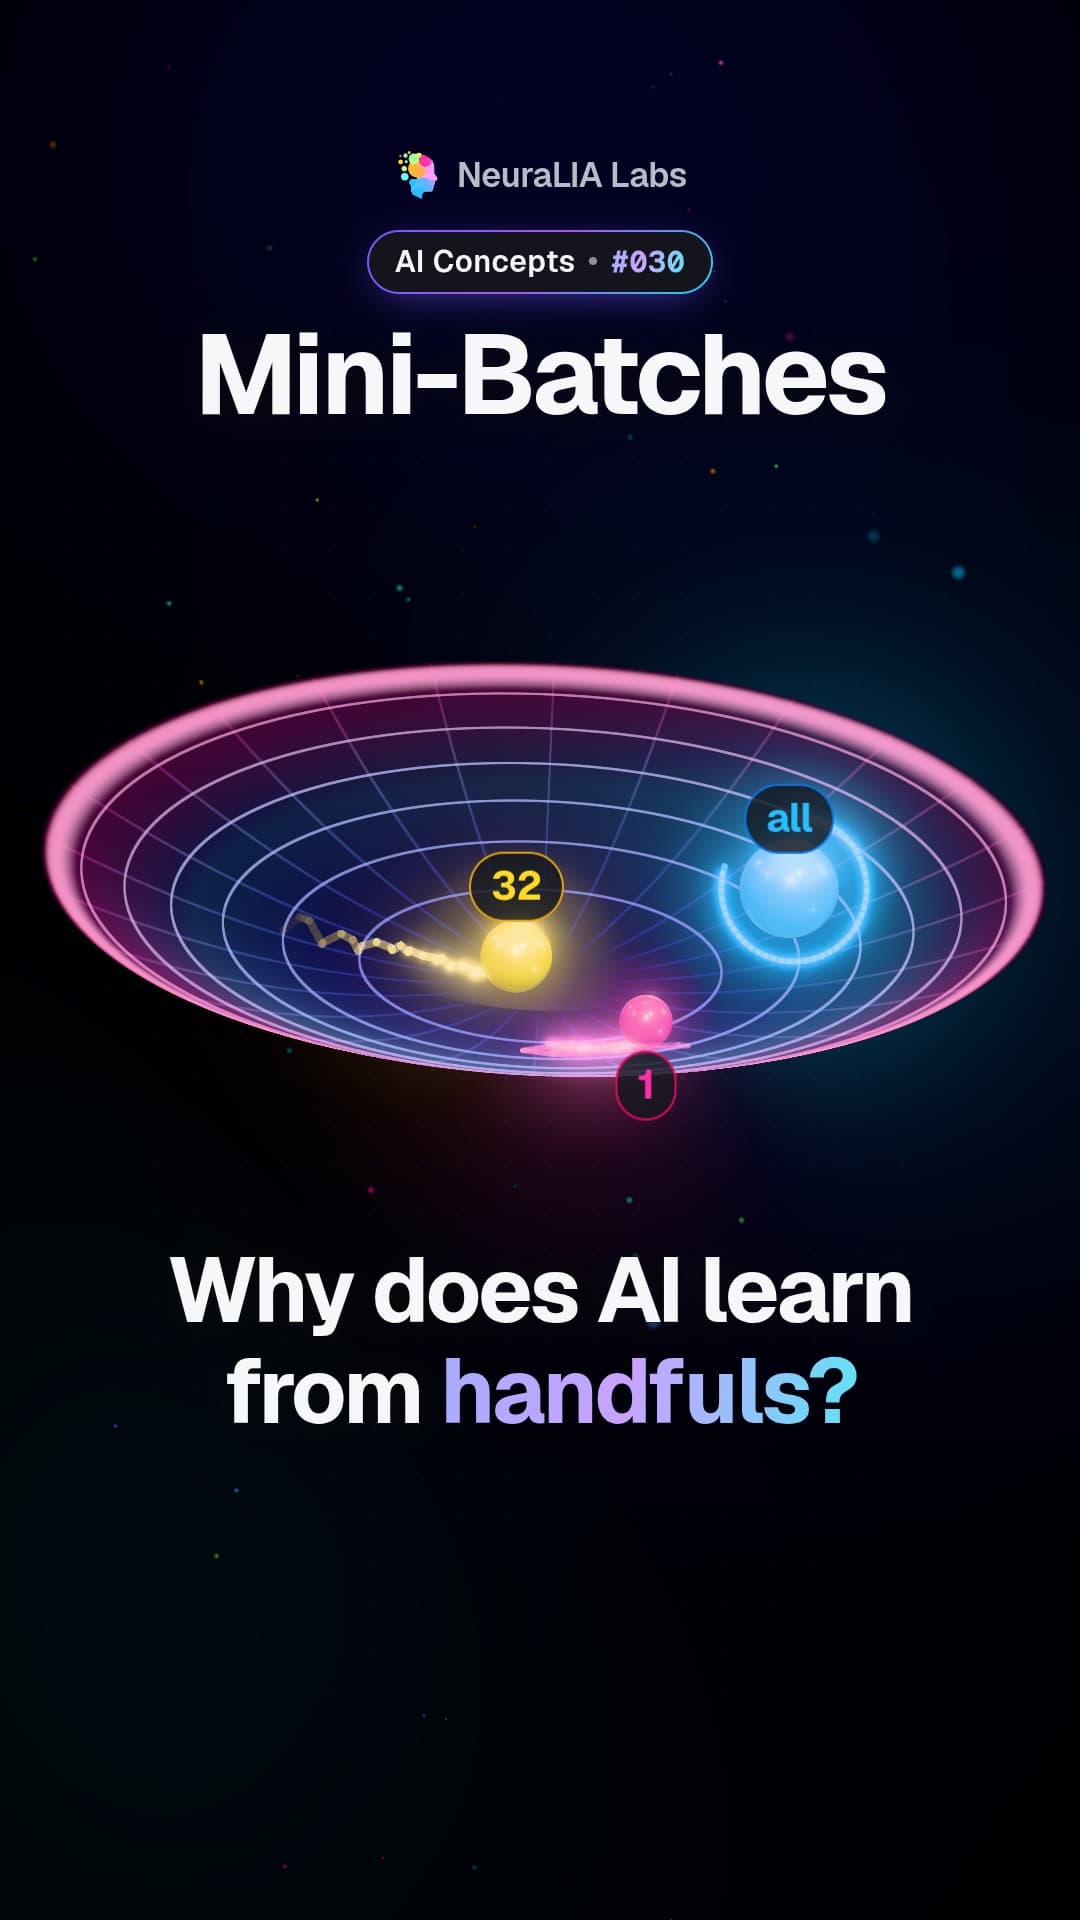 #030
Mini-batches: why AI learns faster from a random handful of data
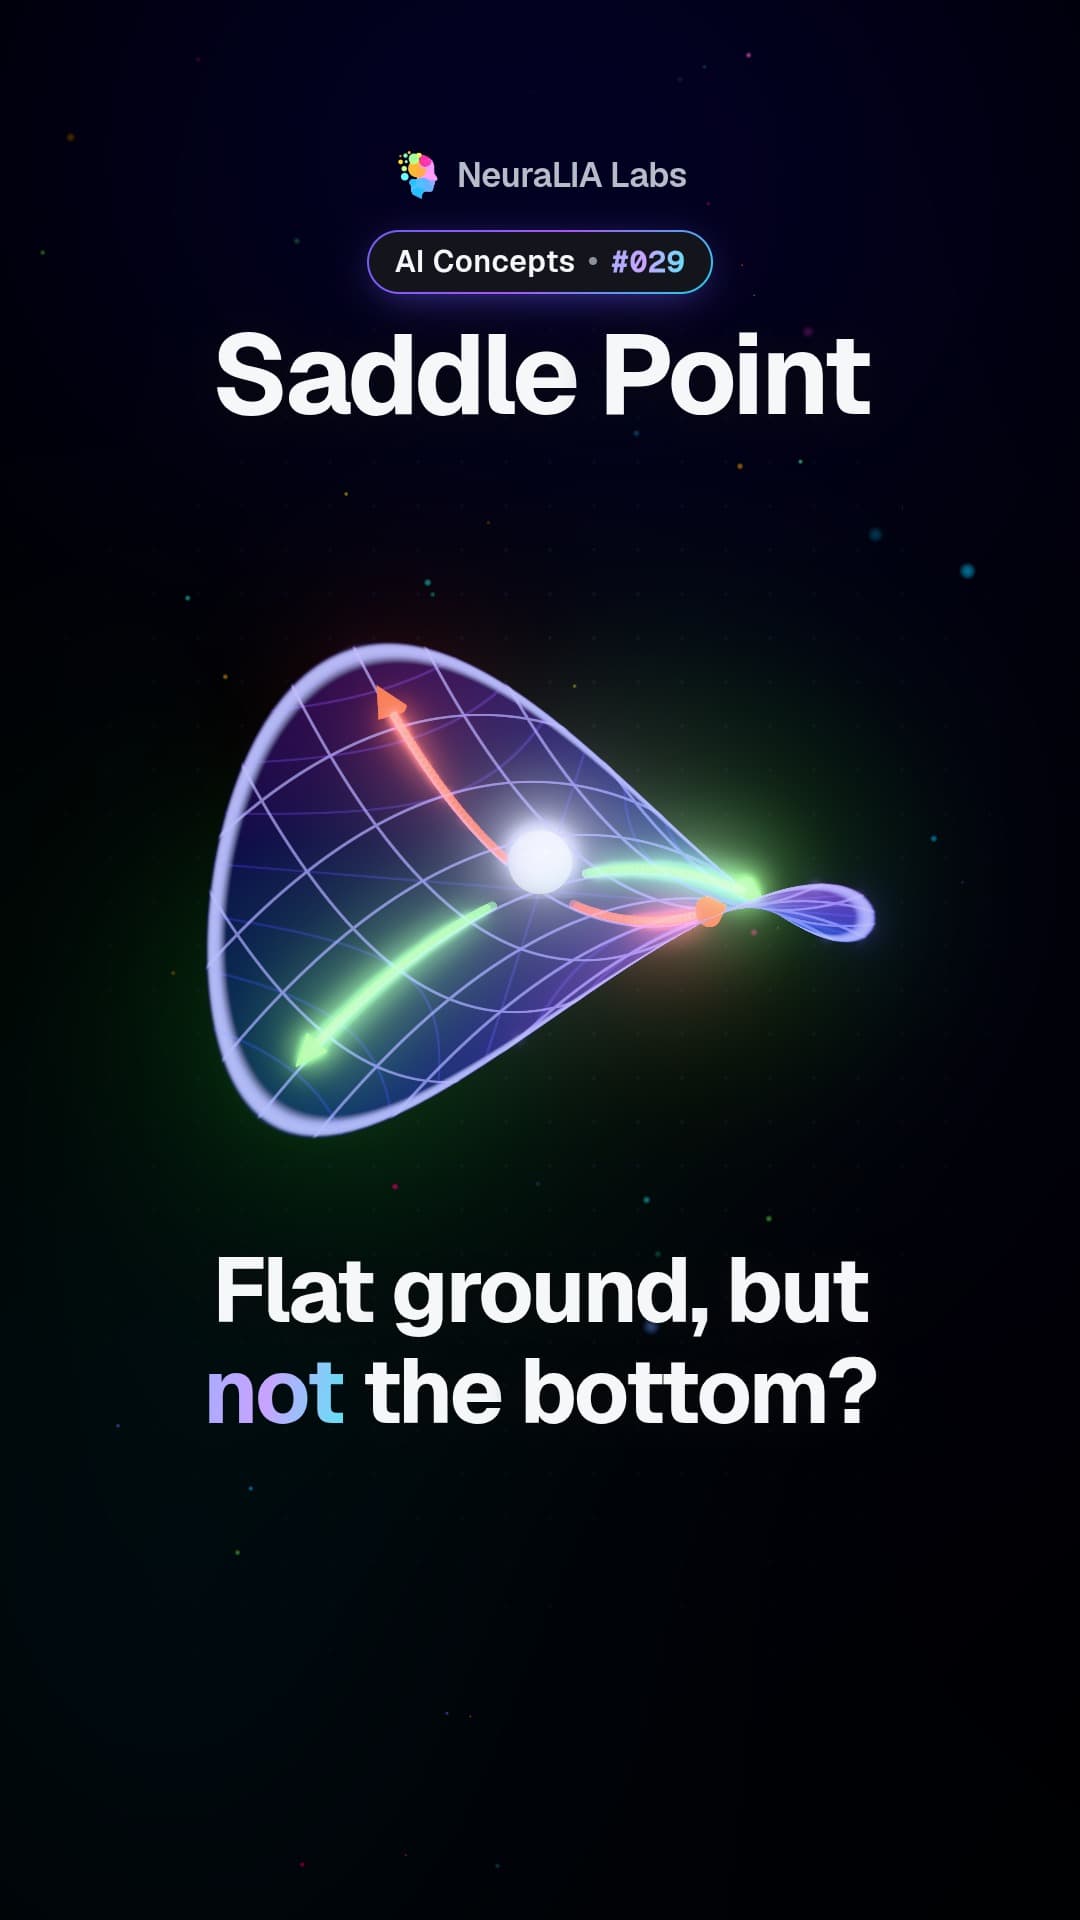 #029
Saddle points: where AI training looks stuck but has a way down
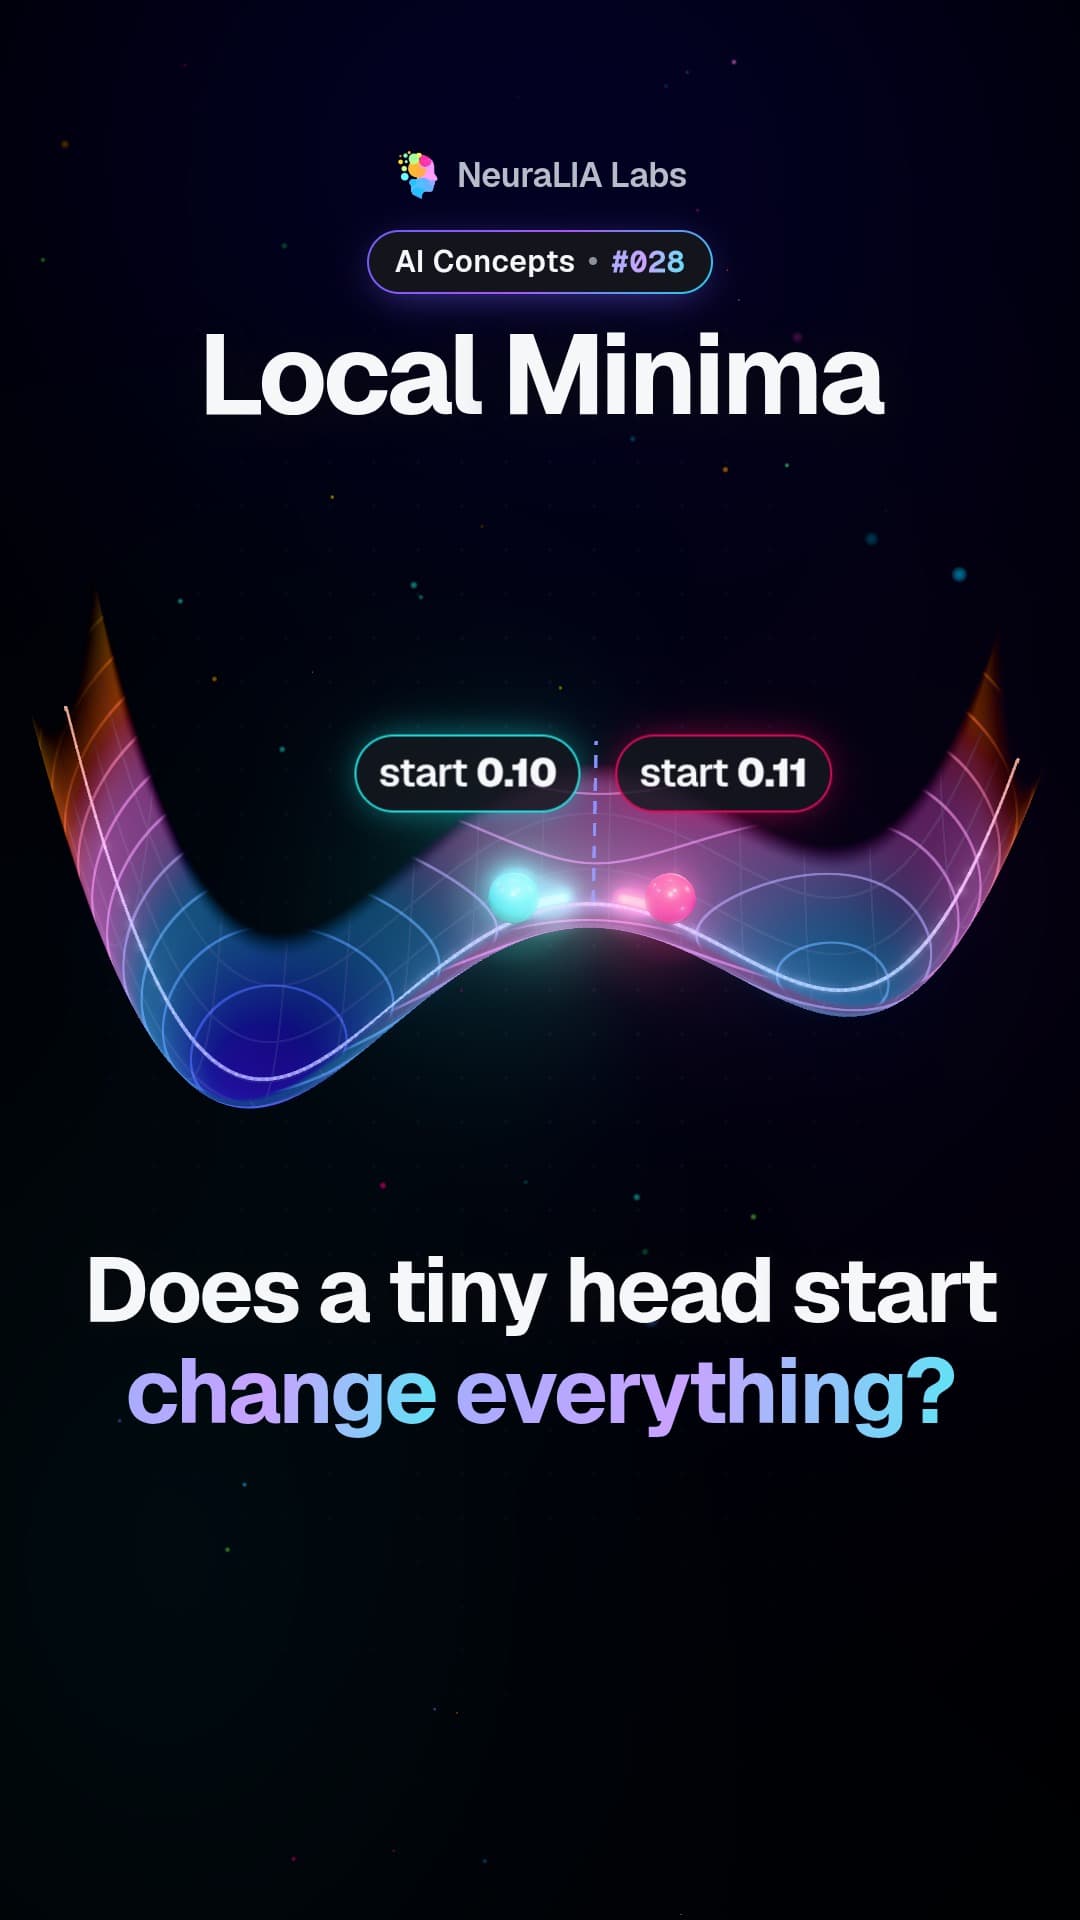 #028
Local minima: why AI training can settle for second best
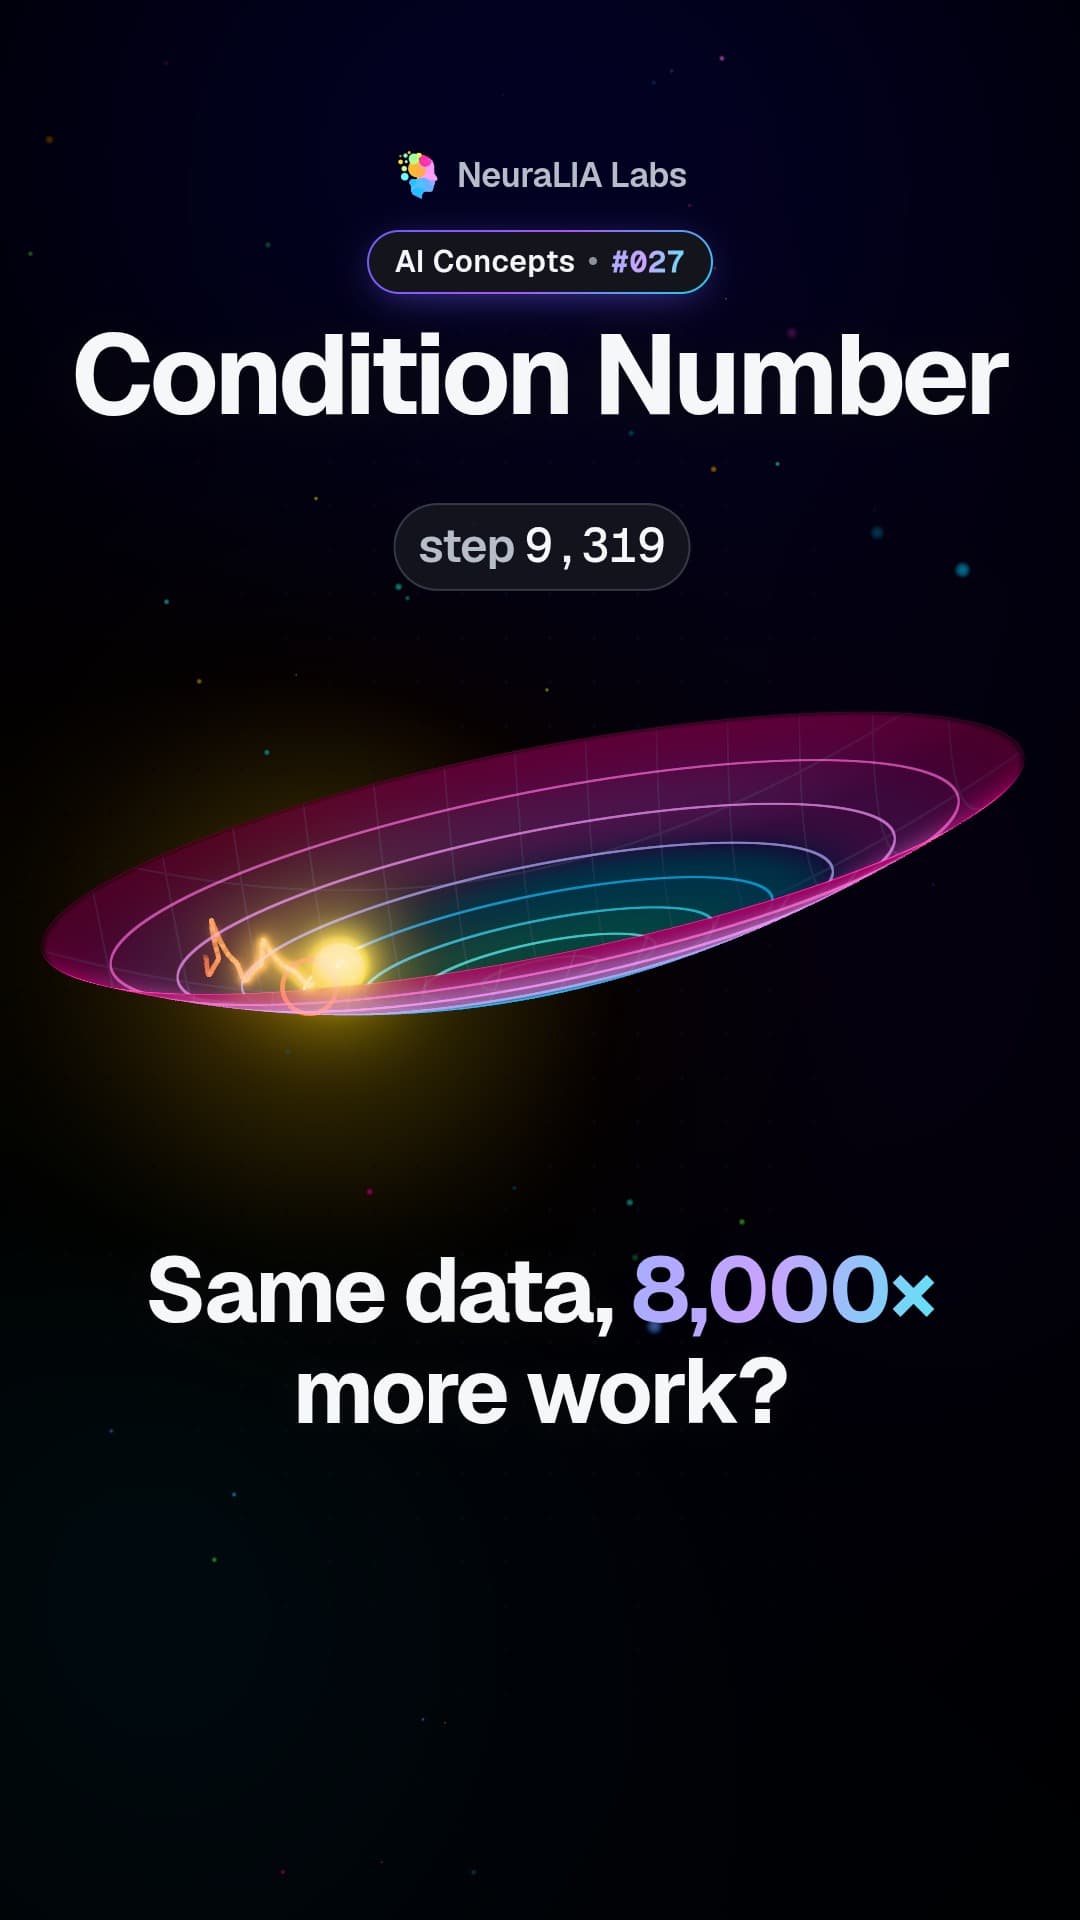 #027
Condition number: why a stretched valley makes AI training crawl
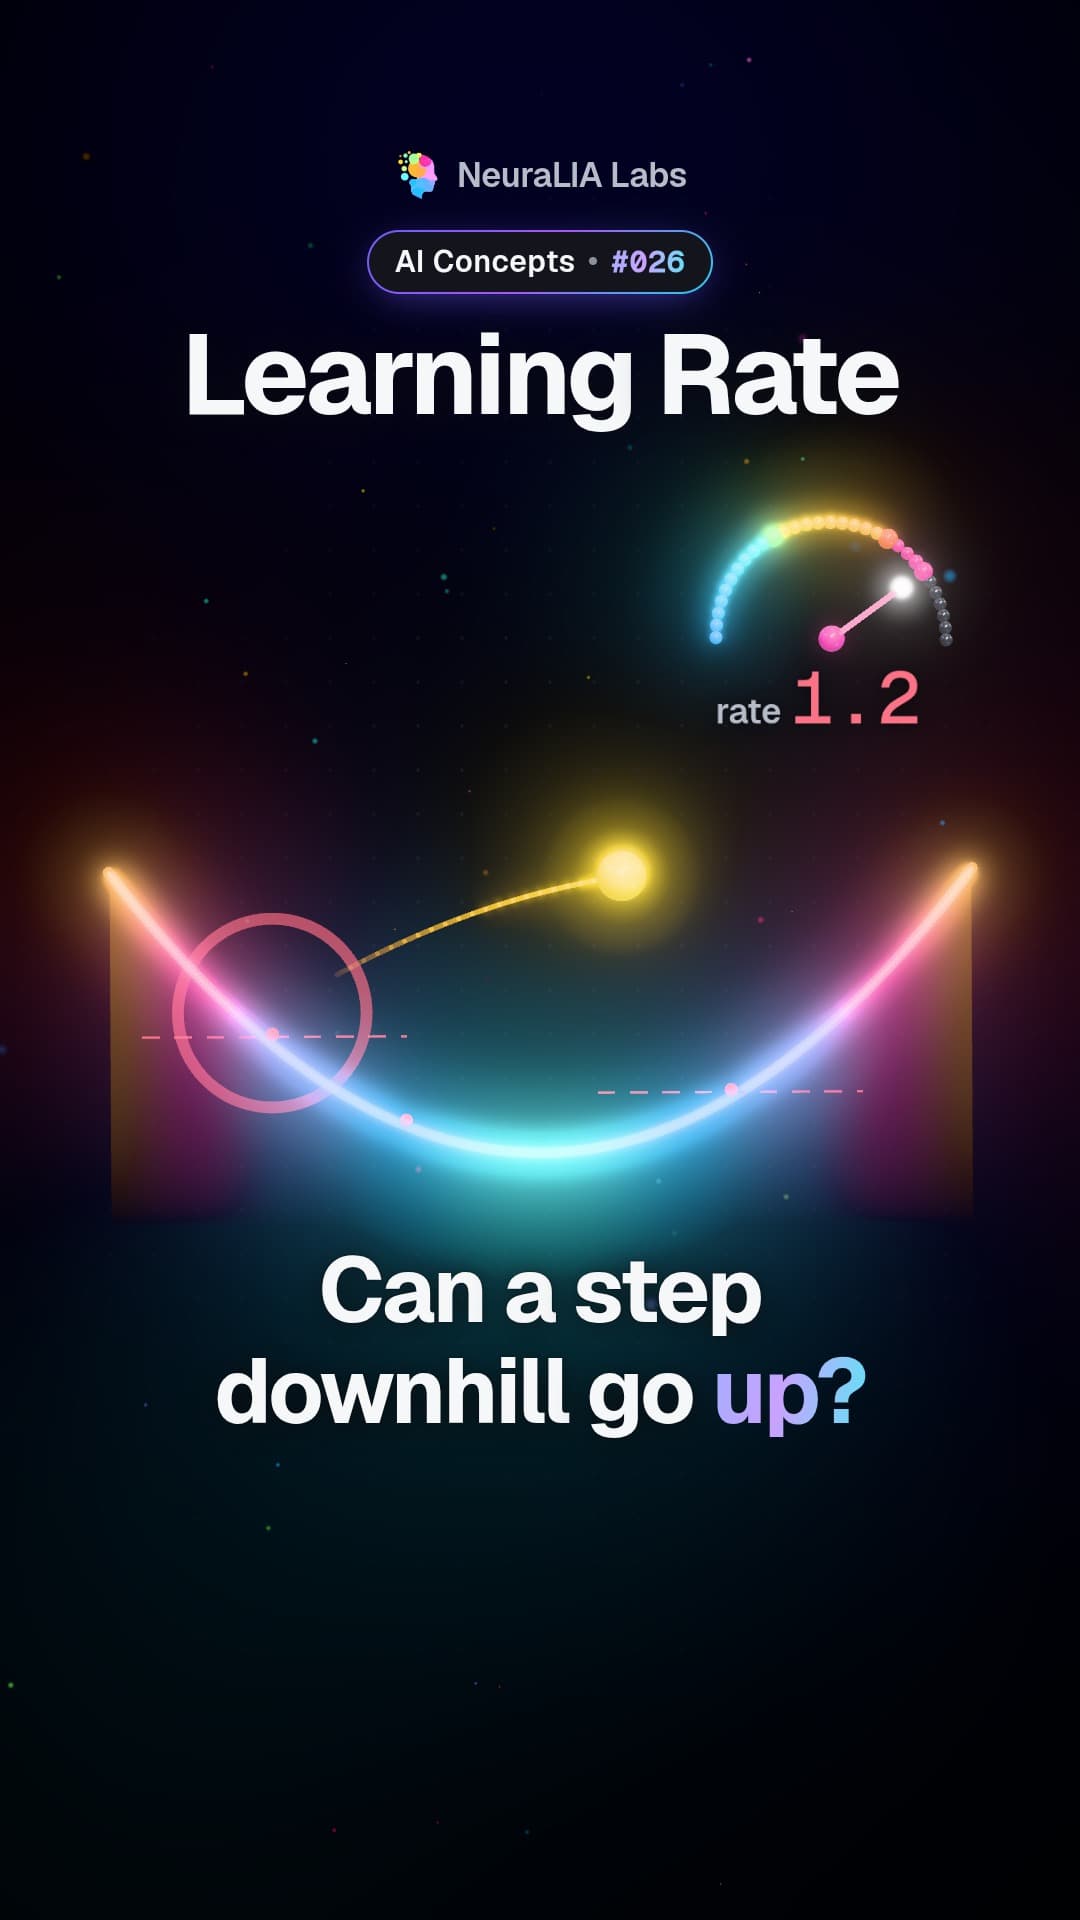 #026
Learning rate: the step size with a ceiling you can calculate
 #025
Gradient descent: how AI finds its way downhill in small steps
 #024
Gradient: the arrow that points uphill, and why AI walks the other way
 #023
Chain rule: how AI traces the effect of every layer
 #022
Derivative: how much the result moves when you nudge one input
 #021
Grid search: why you cannot train an AI by trying every setting
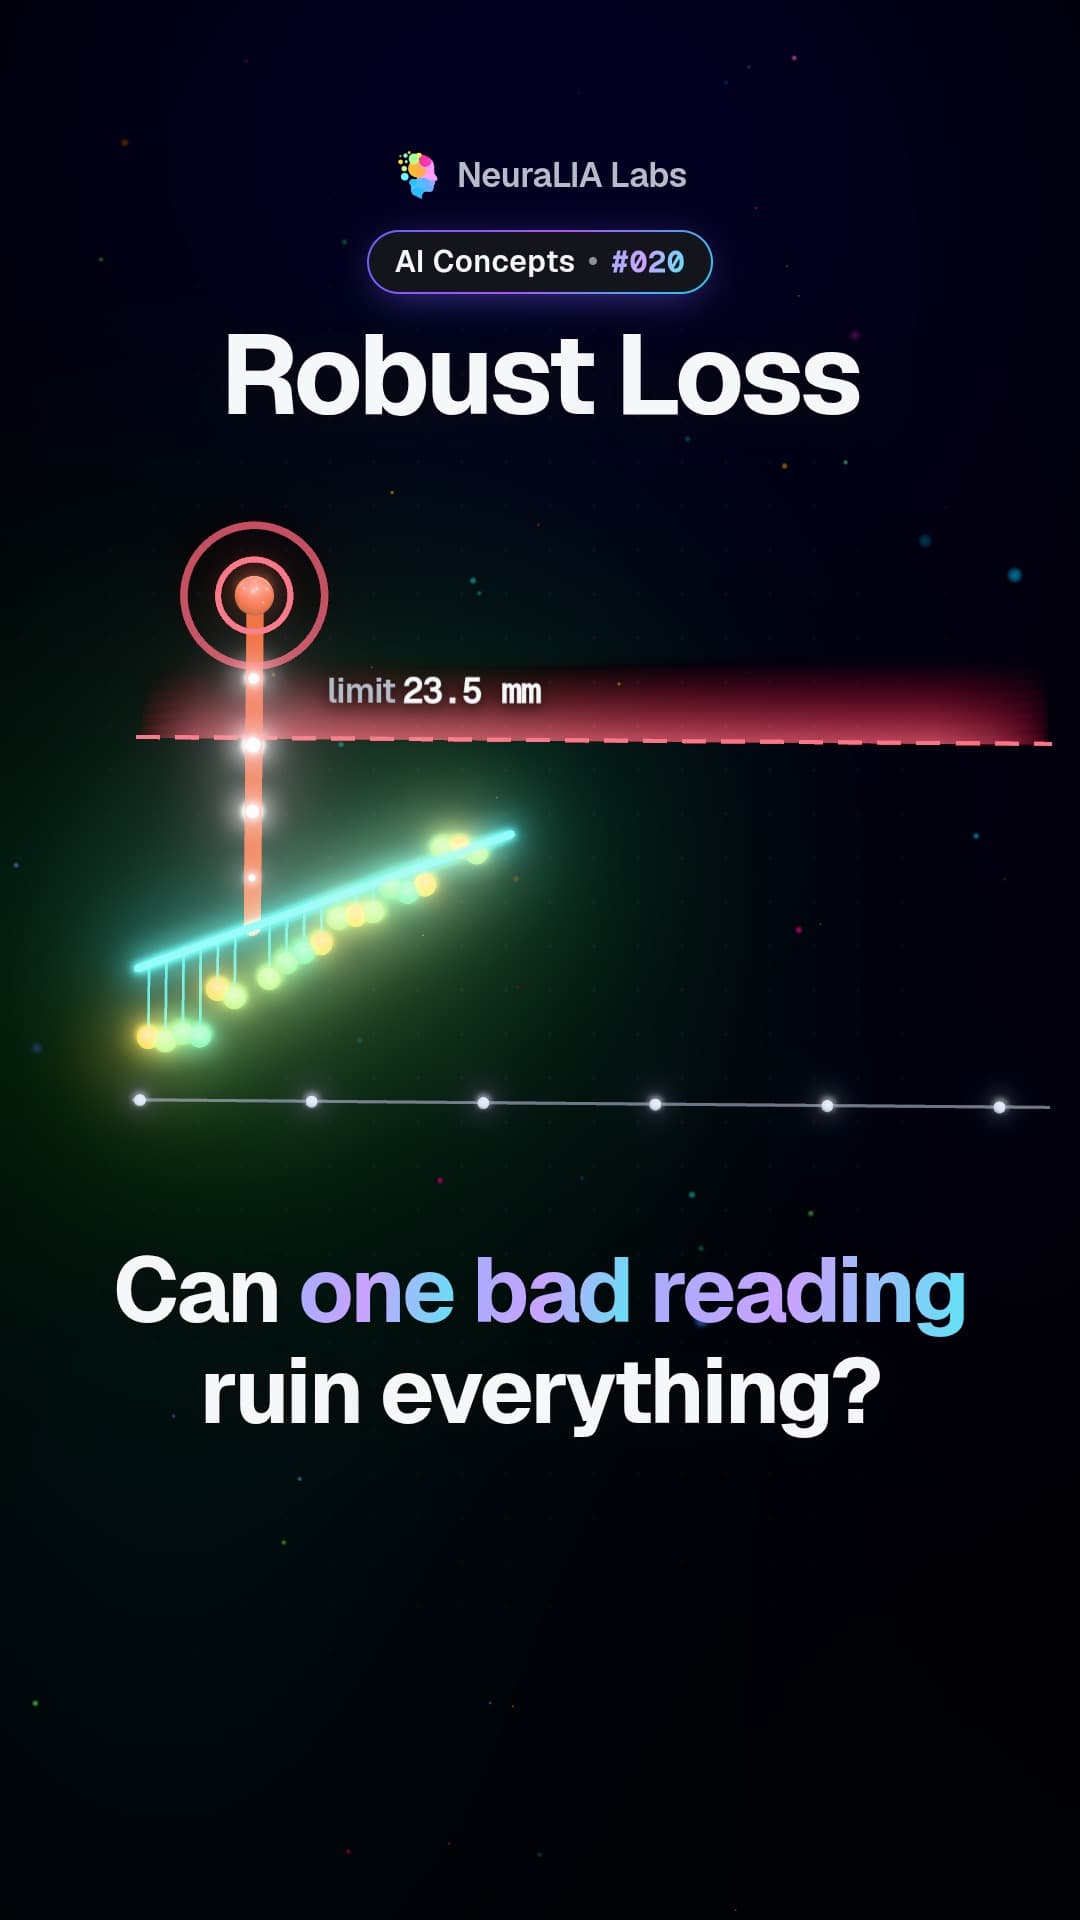 #020
Robust loss: stop one wild reading from wrecking your forecast
 #019
Heavy tails: when rare, huge errors break the usual average
 #018
Mean squared error: the hidden bet behind squaring your mistakes
 #017
The LogSumExp trick: one subtraction that stops AI math overflowing
 #016
Rounding error: why adding the same numbers can give two answers
 #015
Floating-point numbers: why your computer cannot hold every number
 #014
Negative log-likelihood: turning a fragile product into a calm sum
 #013
Maximum likelihood: the answer that makes your data least surprising
 #012
Bayes' rule: reasoning backwards from a clue to its most likely cause
 #011
Chain rule of probability: how AI scores a sentence word by word
 #010
Loss landscape: training an AI means finding the bottom of a valley
 #009
Loss function: the scoring rule that decides which answer wins
 #008
Feature engineering: the human choice that can beat the algorithm
강좌 챕터별
- 1처음부터 만드는 퍼셉트론: 뉴런은 무엇을 계산하는가영상 10개
- 2손실 함수는 어디서 오는가: 관습이 아니라 likelihood영상 12개
- 3내리막길: Gradient Descent와 모두가 건너뛰는 두 단계영상 12개
- 4분류, cross-entropy, 그리고 스스로를 속이지 않는 법
- 5Backpropagation from scratch: 엔진부터, 그다음 신경망영상 1개
- 6학습시키는 것과 일반화시키는 것
- 7BPE Tokenizer 만들기: 모델이 R 개수를 세지 못하는 이유영상 1개
- 8Next-token prediction: embedding과 perplexity의 의미영상 1개
- 9평균에서 유도하는 Attention과 Transformer Block
- 10LLM 사전 학습: 데이터, 컴퓨트, 스케일링 법칙과 비용
- 11Base model에서 Assistant까지: SFT, RLHF, DPO, GRPO
- 12Chain of Thought, RLVR, Test-Time Compute를 측정하다
- 13Inference 비용 낮추기: KV cache, batching, 양자화
- 14첫 Production LLM 호출: Streaming, 재시도, 타임아웃
- 15Prompt Engineering, 측정으로 보기: 무엇이 출력물을 바꾸는가
- 16Context window, token, 청구액을 실제로 재보면
- 17Temperature와 Top-p, 그리고 당신에게 없는 결정성
- 18Tool Calling과 Structured Outputs: 깨지지 않는 계약
- 19Production RAG: chunking, retrieval, 정직한 인용
- 20Fine-Tune, Retrieval, Prompt? 결정은 경제성입니다
- 21Multimodal 가격: 이미지, 오디오, 비디오는 실제로 무엇에 과금될까
- 22AI agent란 무엇인가: 다섯 가지 고전 유형과 두 경쟁 정의
- 23Agent Harness 만들기: 루프와 그 루프를 빠져나오는 다섯 가지 길
- 24Context Engineering: 왜 당신의 agent는 40번째 턴에 더 멍청해질까
- 25Multi-Agent 오케스트레이션: 다섯 가지 패턴과 승리하는 순간
- 26스펙으로 읽는 MCP: 서버란 실제로 무엇인가
- 27MCP Server 출시하기: TypeScript와 Python 실측 비교
- 28Agent Skills와 SKILL.md: 점진적 공개를 숫자로 검증하다
- 29LLM 평가: 공개 벤치마크에서 나만의 골든 세트까지
- 30Prompt Injection과 치명적 삼중 조건: 실제 Agent 보안하기