
 #01
Video
AI qua video ngắn dễ hiểu
Mỗi video giải thích một ý tưởng bằng ngôn ngữ dễ hiểu. Mỗi video liên kết tới chương trong khóa học miễn phí của chúng tôi để giải thích từng bước.
Bắt đầu tại đây AI 101
- #01
 #02
Machine learning: how a computer draws its own dividing line
 #03
Neural networks: layers of tiny calculators passing signals on
 #04
How AI learns: guess, measure the error, nudge, repeat
 #05
Tokens: how AI chops your words into numbered pieces
 #06
Embeddings: why a puppy lands closer to a dog than to a pizza
Mới nhất
 #031
Momentum: how remembering past steps stops AI training zigzagging
 #030
Mini-batches: why AI learns faster from a random handful of data
 #029
Saddle points: where AI training looks stuck but has a way down
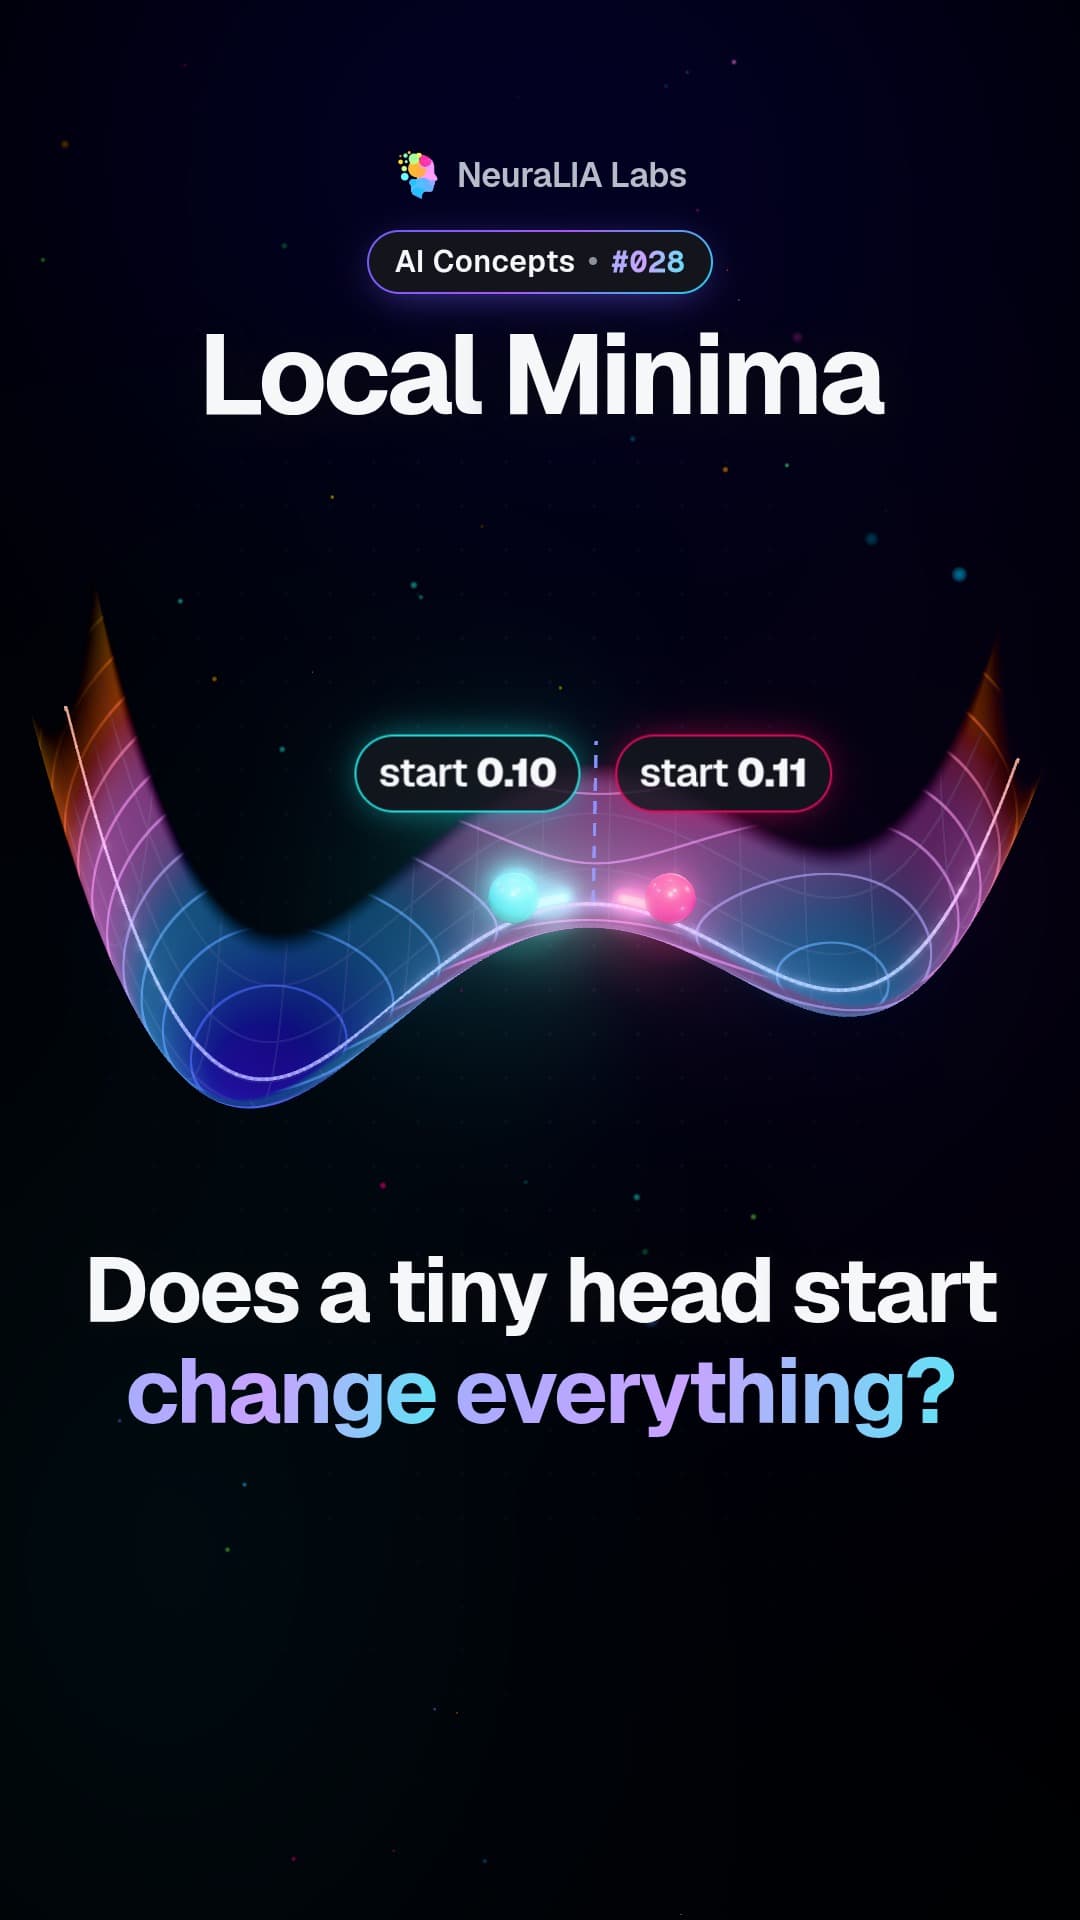 #028
Local minima: why AI training can settle for second best
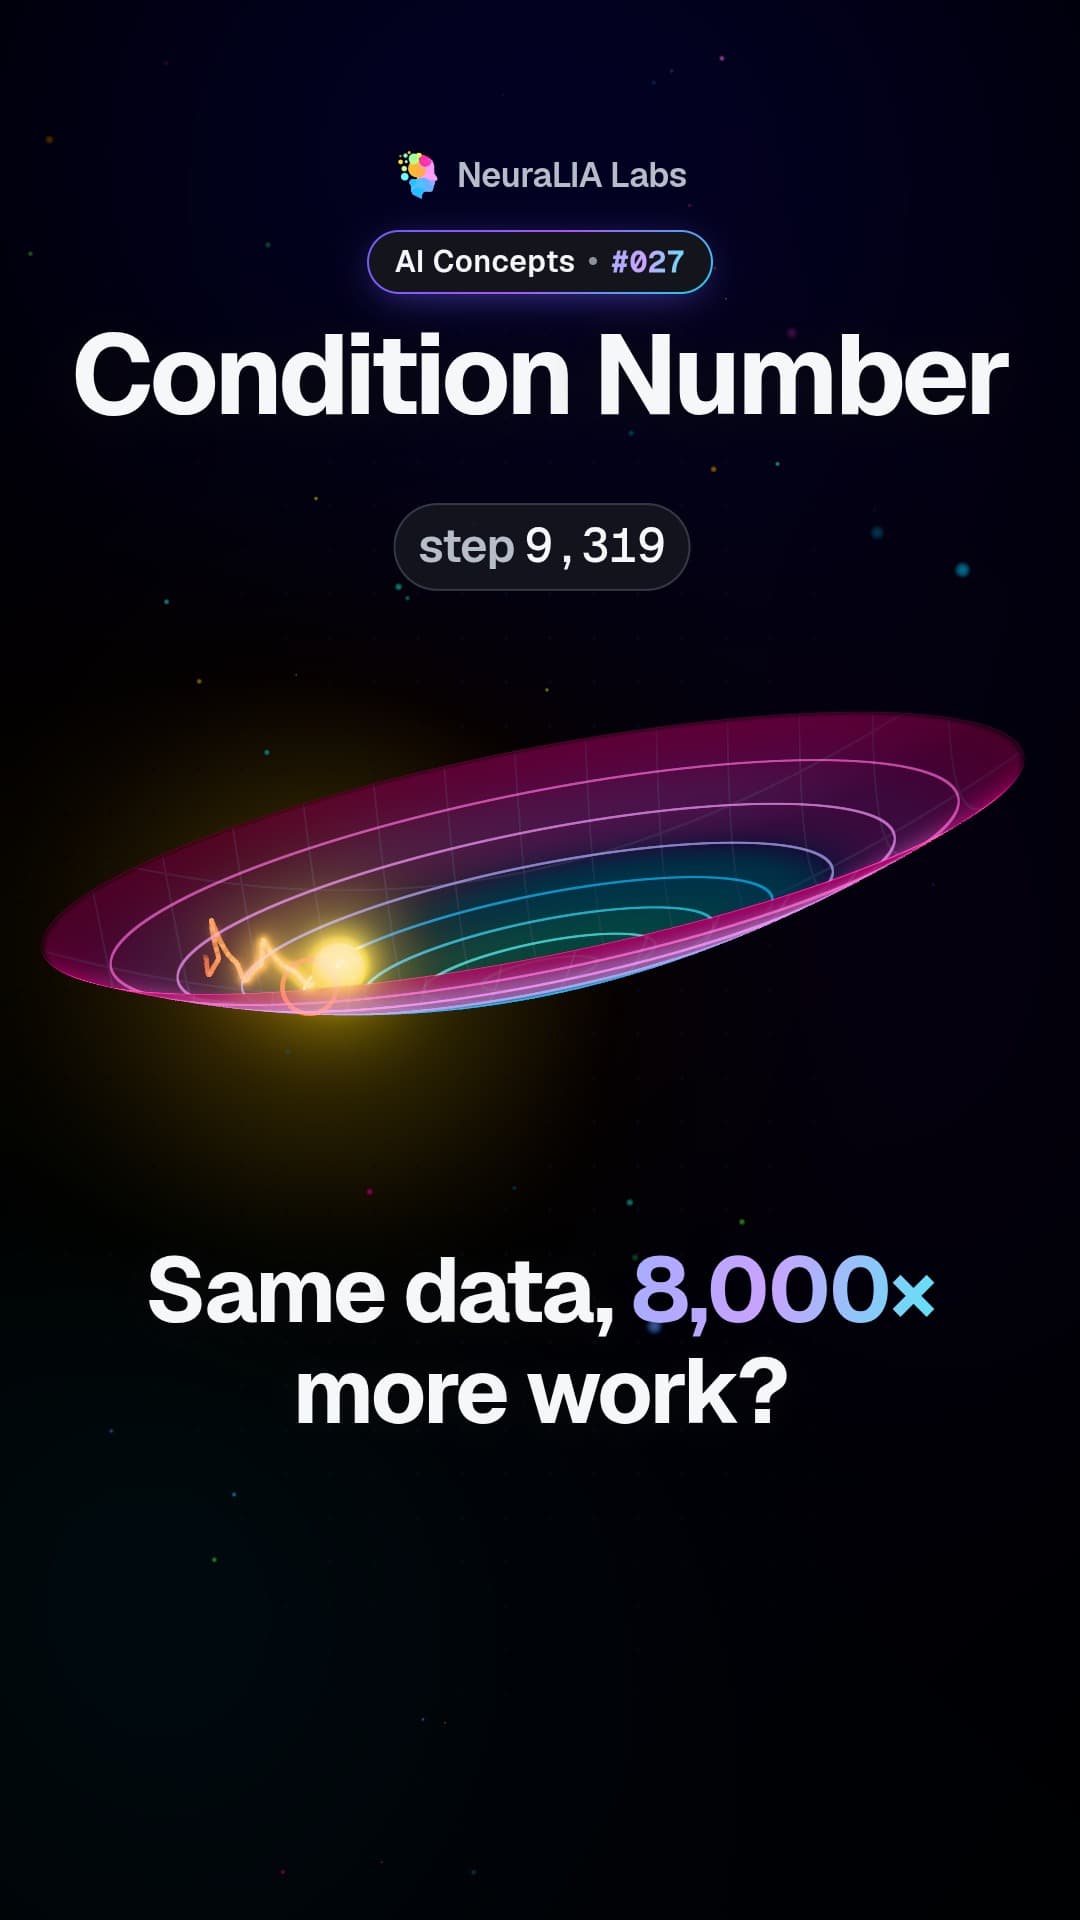 #027
Condition number: why a stretched valley makes AI training crawl
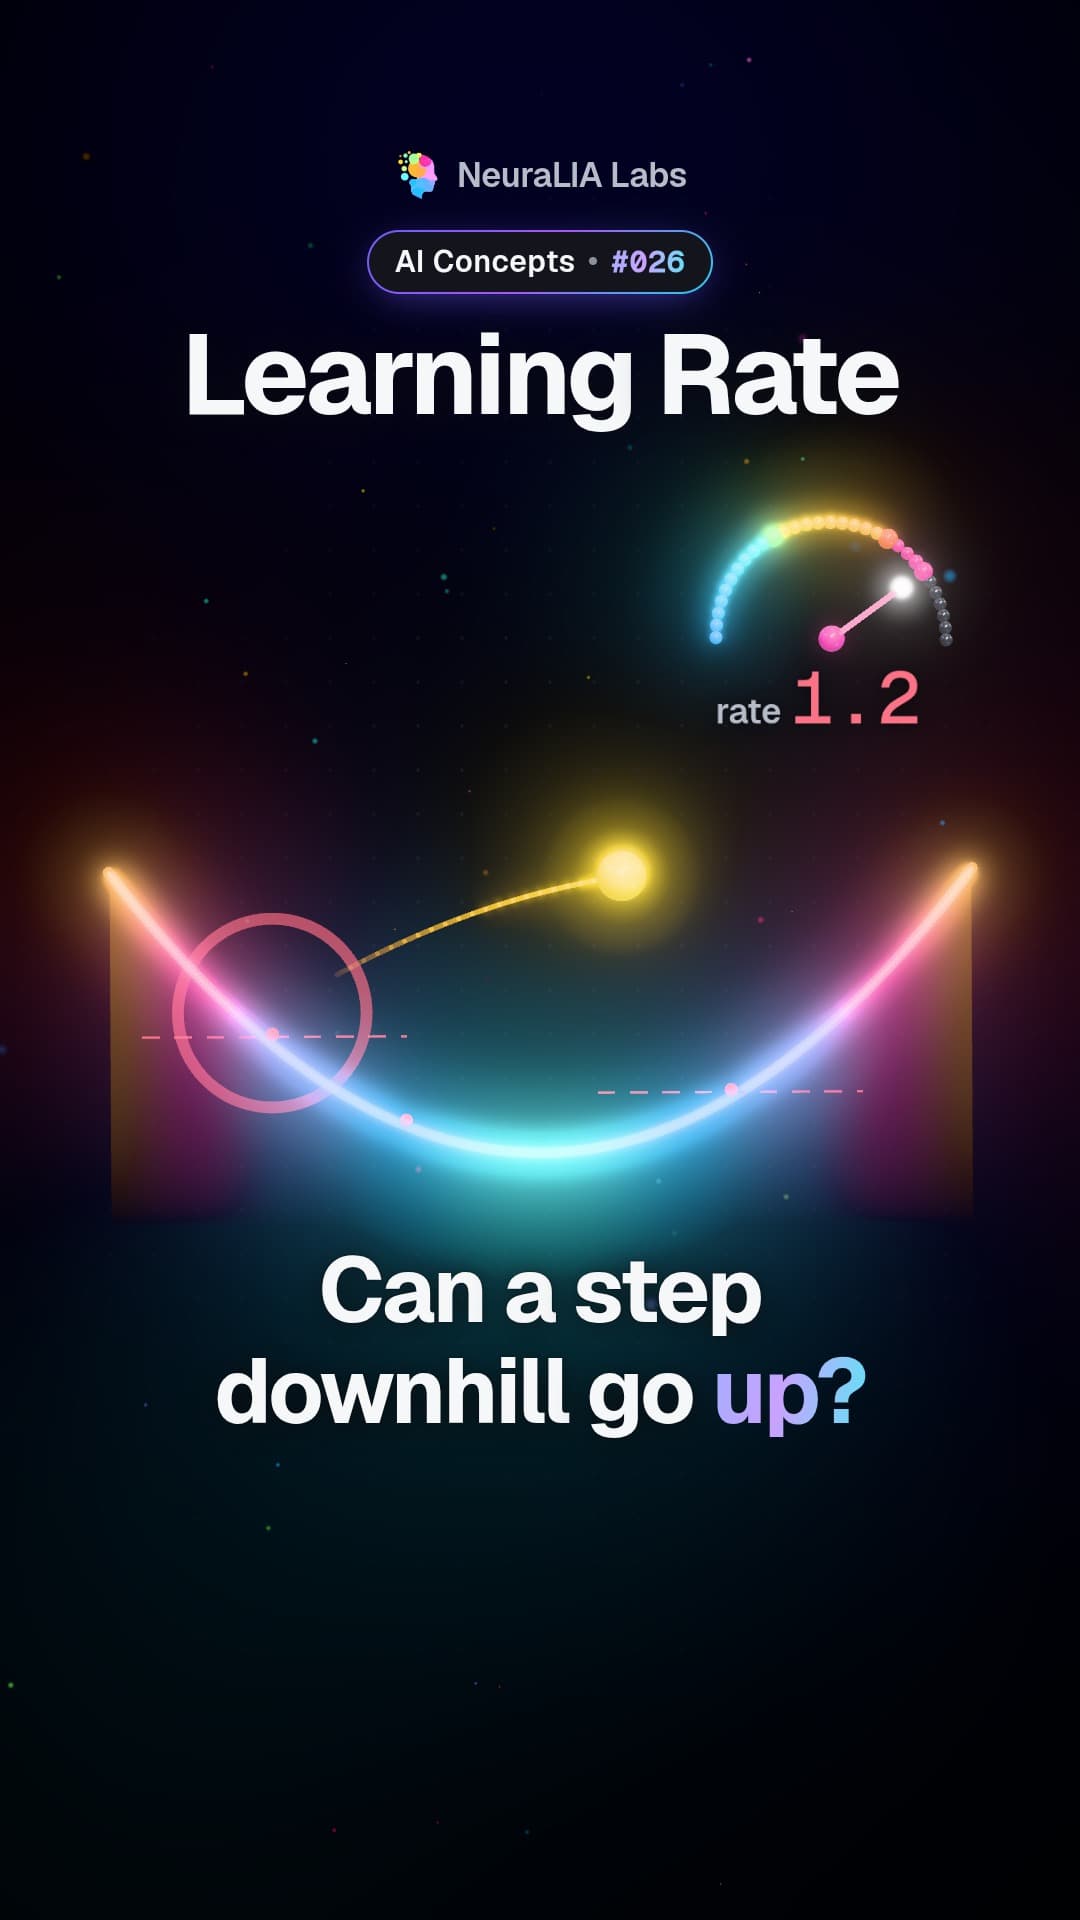 #026
Learning rate: the step size with a ceiling you can calculate
 #025
Gradient descent: how AI finds its way downhill in small steps
 #024
Gradient: the arrow that points uphill, and why AI walks the other way
 #023
Chain rule: how AI traces the effect of every layer
 #022
Derivative: how much the result moves when you nudge one input
 #021
Grid search: why you cannot train an AI by trying every setting
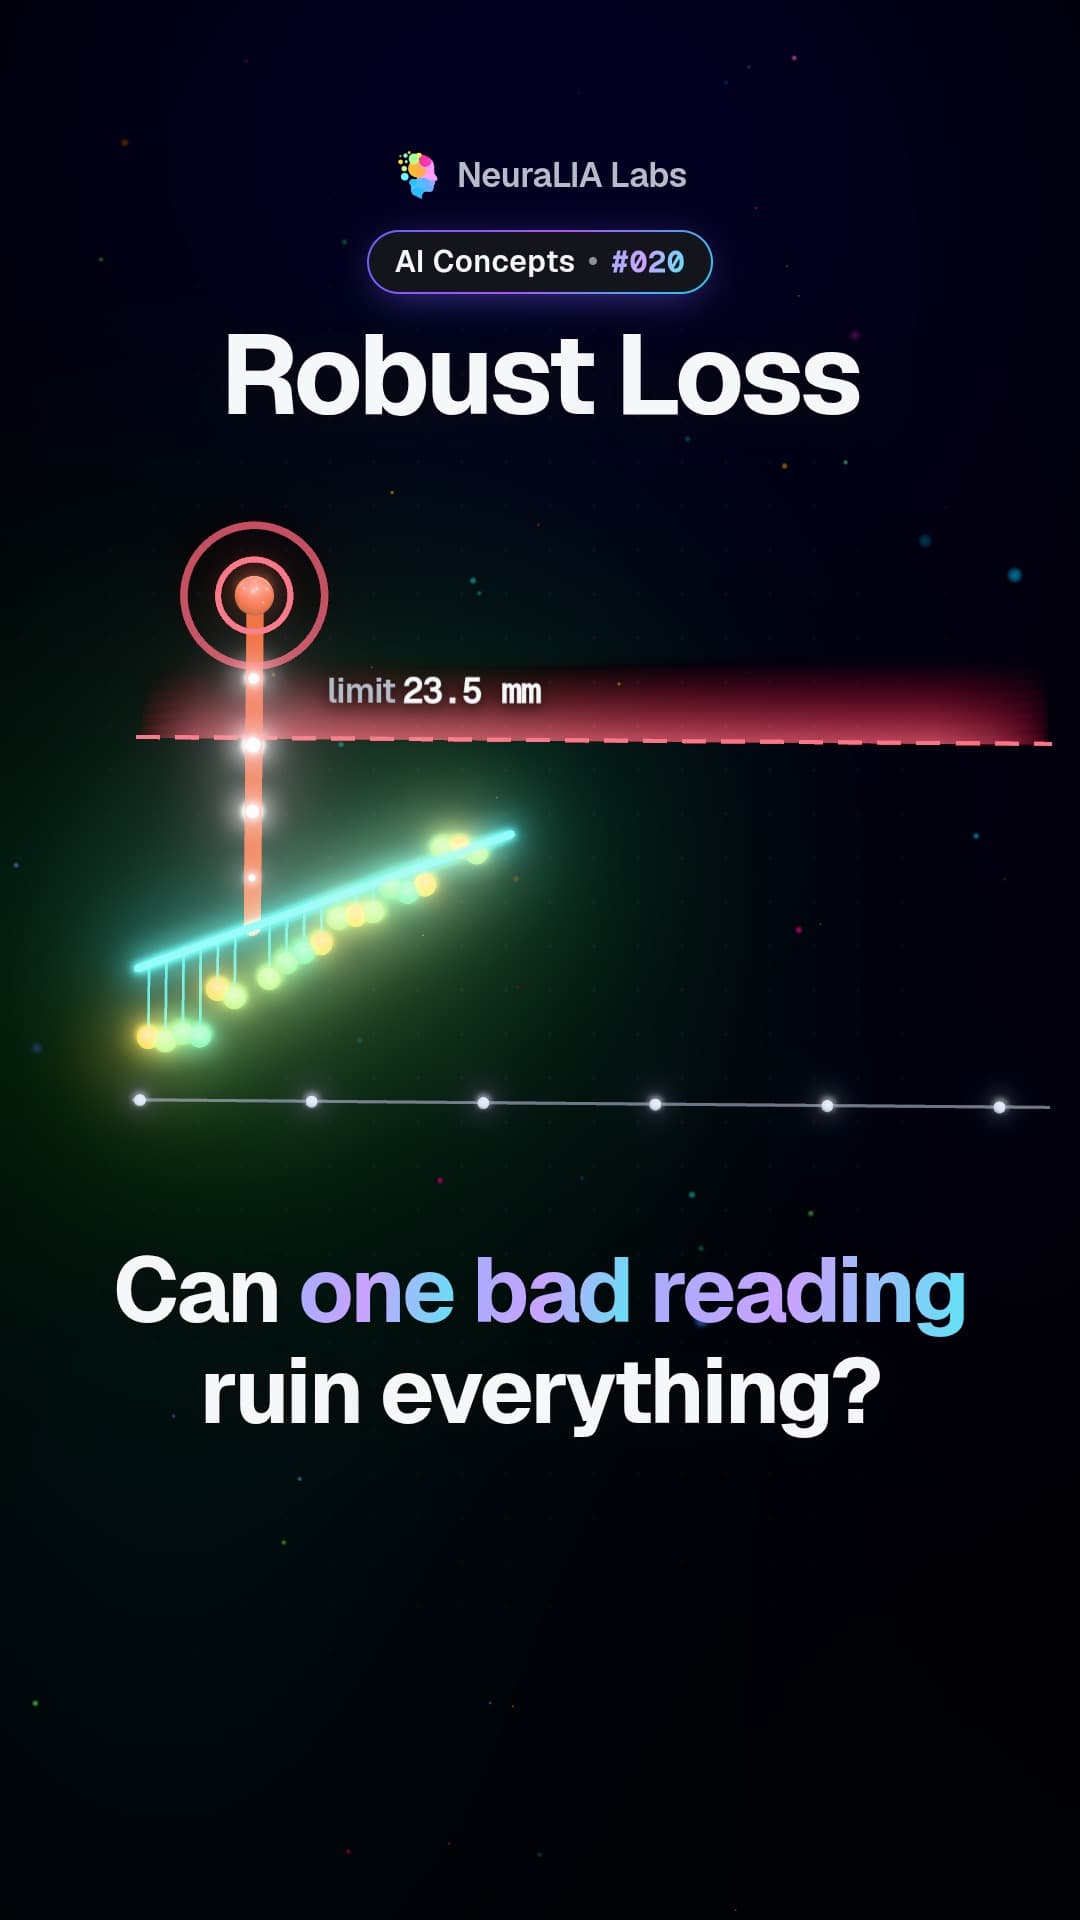 #020
Robust loss: stop one wild reading from wrecking your forecast
 #019
Heavy tails: when rare, huge errors break the usual average
 #018
Mean squared error: the hidden bet behind squaring your mistakes
 #017
The LogSumExp trick: one subtraction that stops AI math overflowing
 #016
Rounding error: why adding the same numbers can give two answers
 #015
Floating-point numbers: why your computer cannot hold every number
 #014
Negative log-likelihood: turning a fragile product into a calm sum
 #013
Maximum likelihood: the answer that makes your data least surprising
 #012
Bayes' rule: reasoning backwards from a clue to its most likely cause
 #011
Chain rule of probability: how AI scores a sentence word by word
 #010
Loss landscape: training an AI means finding the bottom of a valley
 #009
Loss function: the scoring rule that decides which answer wins
 #008
Feature engineering: the human choice that can beat the algorithm
Theo chương khóa học
- 1Perceptron từ đầu: một neuron thật sự tính gì10 video
- 2Hàm mất mát đến từ đâu: likelihood, không phải quy ước12 video
- 3Xuống dốc: Gradient Descent và hai bước ai cũng bỏ qua12 video
- 4Phân loại, cross-entropy và cách đừng tự đánh lừa mình
- 5Backpropagation từ đầu: Động cơ trước, rồi đến mạng1 video
- 6Làm cho mạng train được, rồi khái quát hóa được
- 7Tự xây BPE Tokenizer: Vì sao model của bạn không đếm được chữ R1 video
- 8Dự đoán next-token: embeddings và ý nghĩa của perplexity1 video
- 9Attention và khối Transformer, suy ra từ phép trung bình
- 10Huấn luyện trước một LLM: dữ liệu, compute, scaling laws và chi phí
- 11Từ mô hình gốc đến trợ lý: SFT, RLHF, DPO và GRPO
- 12Đo lường Chain of Thought, RLVR và Test-Time Compute
- 13Làm inference rẻ hơn: KV cache, batching và lượng tử hóa
- 14Lần gọi LLM production đầu tiên: streaming, retry, timeout
- 15Prompt Engineering qua đo lường: Điều gì làm thay đổi đầu ra
- 16Context window, token và hóa đơn, đo bằng số liệu
- 17Temperature, top-p và tính quyết định mà bạn không có
- 18Tool Calling và structured outputs: Bản hợp đồng vẫn đứng vững
- 19RAG trong production: chunking, retrieval và trích dẫn trung thực
- 20Fine-Tune, retrieve hay prompt? Quyết định nằm ở kinh tế
- 21Định giá multimodal: hình ảnh, âm thanh và video thực sự tính phí gì
- 22AI agent là gì: năm kiểu kinh điển, hai định nghĩa đối nghịch
- 23Xây dựng Agent Harness: Vòng lặp và năm lối thoát
- 24Context engineering: Vì sao agent của bạn kém thông minh hơn ở lượt 40
- 25Điều phối multi-agent: Năm pattern và khi nào một agent thắng
- 26Giải thích MCP theo đặc tả: Server thực sự là gì
- 27Ship một MCP Server: TypeScript và Python, đo đạc rõ ràng
- 28Agent Skills và SKILL.md: Đo lường cơ chế tiết lộ dần
- 29Đánh giá LLM: từ benchmark công khai đến golden set của bạn
- 30Prompt Injection và bộ ba chí mạng: Bảo mật một agent thật