
 #01
ویدیوها
توضیح AI در ویدیوهای کوتاه
هر ویدیو، یک ایده به زبان ساده. هر کدام به فصل مربوطه در دوره رایگان ما وصل است که آن را مرحلهبهمرحله توضیح میدهد.
از اینجا شروع کنید AI 101
- #01
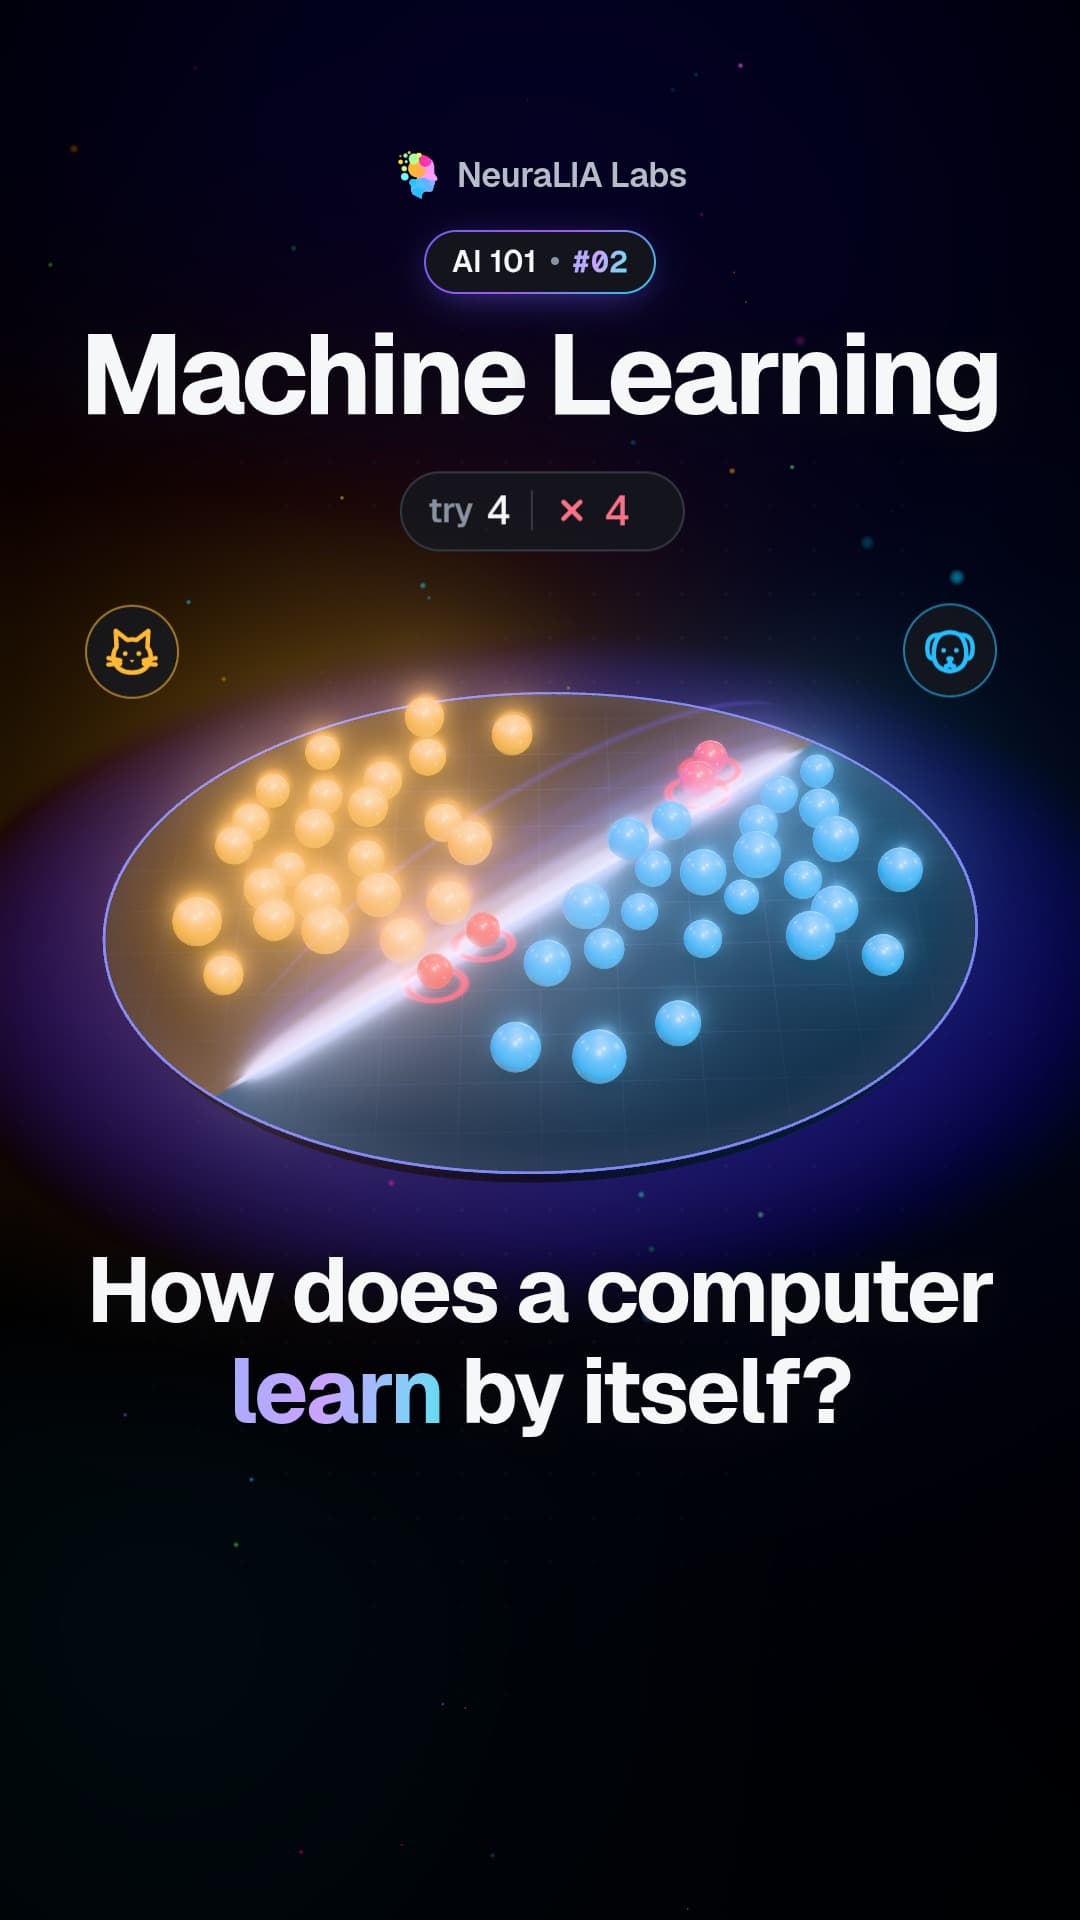 #02
Machine learning: how a computer draws its own dividing line
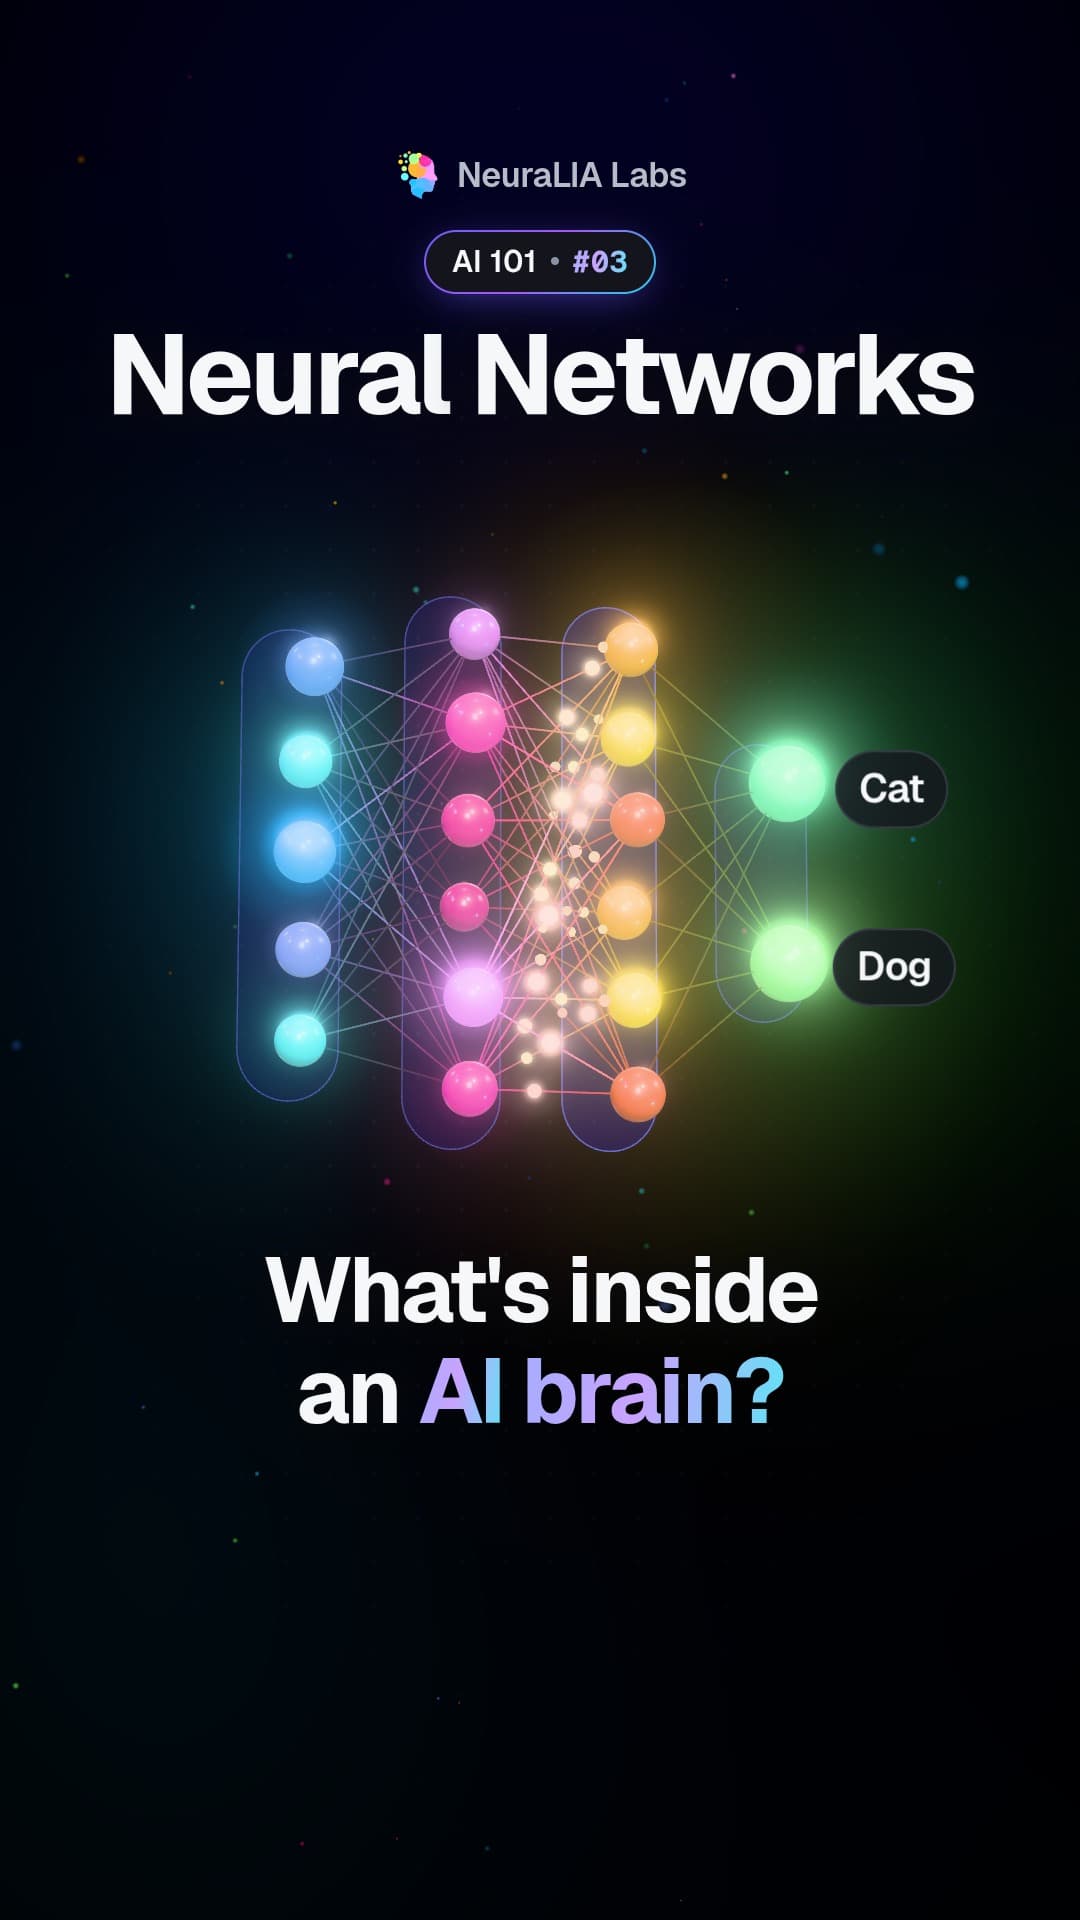 #03
Neural networks: layers of tiny calculators passing signals on
 #04
How AI learns: guess, measure the error, nudge, repeat
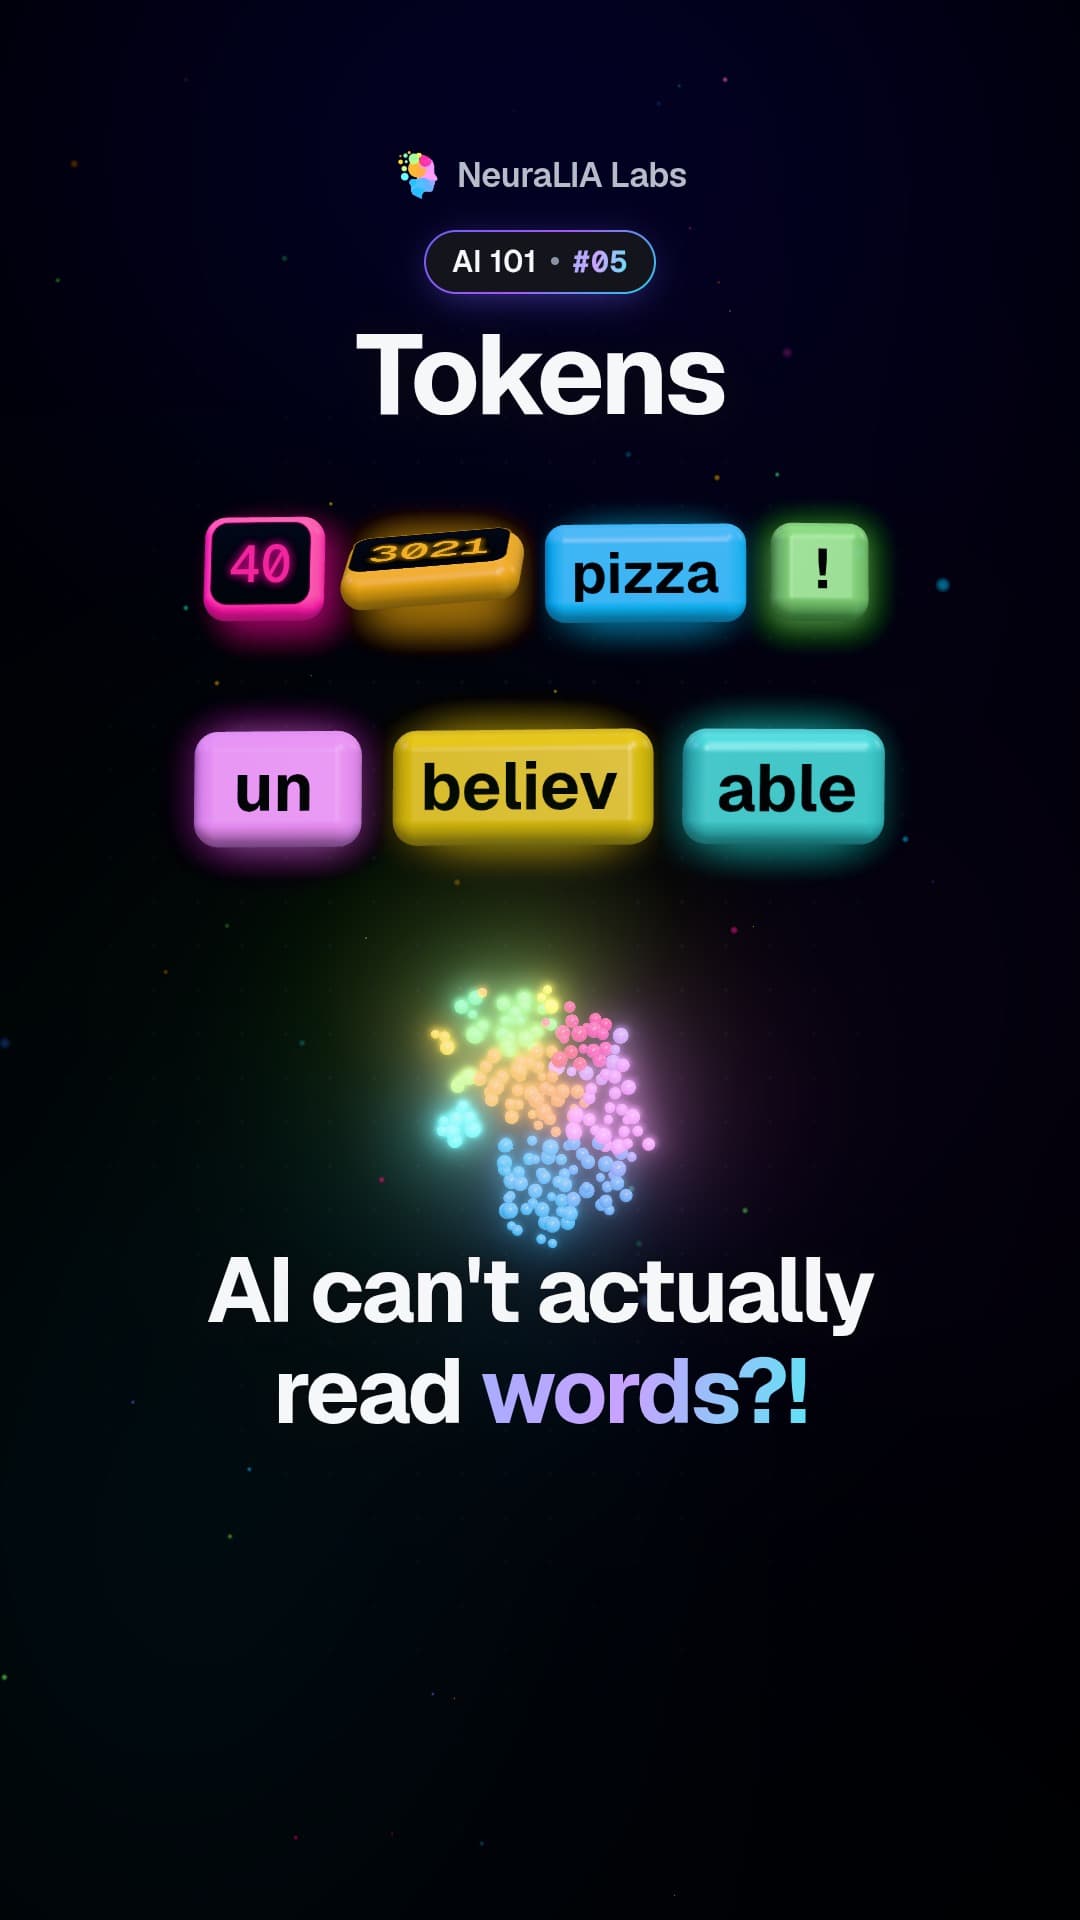 #05
Tokens: how AI chops your words into numbered pieces
 #06
Embeddings: why a puppy lands closer to a dog than to a pizza
جدیدترینها
 #031
Momentum: how remembering past steps stops AI training zigzagging
 #030
Mini-batches: why AI learns faster from a random handful of data
 #029
Saddle points: where AI training looks stuck but has a way down
 #028
Local minima: why AI training can settle for second best
 #027
Condition number: why a stretched valley makes AI training crawl
 #026
Learning rate: the step size with a ceiling you can calculate
 #025
Gradient descent: how AI finds its way downhill in small steps
 #024
Gradient: the arrow that points uphill, and why AI walks the other way
 #023
Chain rule: how AI traces the effect of every layer
 #022
Derivative: how much the result moves when you nudge one input
 #021
Grid search: why you cannot train an AI by trying every setting
 #020
Robust loss: stop one wild reading from wrecking your forecast
 #019
Heavy tails: when rare, huge errors break the usual average
 #018
Mean squared error: the hidden bet behind squaring your mistakes
 #017
The LogSumExp trick: one subtraction that stops AI math overflowing
 #016
Rounding error: why adding the same numbers can give two answers
 #015
Floating-point numbers: why your computer cannot hold every number
 #014
Negative log-likelihood: turning a fragile product into a calm sum
 #013
Maximum likelihood: the answer that makes your data least surprising
 #012
Bayes' rule: reasoning backwards from a clue to its most likely cause
 #011
Chain rule of probability: how AI scores a sentence word by word
 #010
Loss landscape: training an AI means finding the bottom of a valley
 #009
Loss function: the scoring rule that decides which answer wins
 #008
Feature engineering: the human choice that can beat the algorithm
بر اساس فصل دوره
- 1پرسپترون از صفر: یک نورون چه چیزی محاسبه میکند10 ویدیو
- 2تابع زیان از کجا میآید: درستنمایی، نه قرارداد12 ویدیو
- 3سرازیر: Gradient Descent و دو گامی که همه جا میاندازند12 ویدیو
- 4طبقهبندی، Cross-Entropy، و چطور خودتان را فریب ندهید
- 5Backpropagation از صفر: اول موتور، بعد شبکه1 ویدیو
- 6وادار کردن شبکه به آموزش، و وادار کردنش به تعمیم
- 7ساخت یک BPE Tokenizer: چرا مدل شما تعداد Rها را نمیشمارد1 ویدیو
- 8پیشبینی token بعدی: embeddingها و معنای Perplexity1 ویدیو
- 9Attention و بلوک transformer، از دلِ یک میانگین
- 10پیشآموزش یک LLM: داده، محاسبه، قوانین مقیاسپذیری و هزینه
- 11از مدل پایه تا assistant: SFT، RLHF، DPO و GRPO
- 12Chain of Thought، RLVR و Test-Time Compute، اندازهگیریشده
- 13ارزانکردن Inference: KV cache، Batching و Quantization
- 14اولین فراخوان LLM در production: streaming، retry و timeout
- 15Prompt Engineering با عدد و سنجش: چه چیزی خروجی را تغییر میدهد
- 16Context Window، tokenها و صورتحساب؛ با عدد و اندازهگیری
- 17Temperature، Top-p و قطعیتی که ندارید
- 18Tool Calling و خروجیهای ساختاریافته: قراردادی که پابرجا میماند
- 19RAG در Production: chunking، بازیابی و ارجاعهای صادقانه
- 20Fine-tune، بازیابی یا prompt؟ تصمیم اقتصادی است
- 21قیمتگذاری چندوجهی: تصاویر، صدا و ویدئو واقعاً چه چیزی را صورتحساب میکنند
- 22AI Agent چیست: پنج نوع کلاسیک، دو تعریف رقیب
- 23ساخت یک agent harness: حلقه و پنج راه خروج از آن
- 24Context Engineering: چرا agent شما در نوبت 40 کمهوشتر میشود
- 25هماهنگسازی multi-agent: پنج الگو و زمان برندهشدن یکی از آنها
- 26MCP بر اساس مشخصات: سرور واقعاً چیست
- 27انتشار یک MCP Server: TypeScript و Python، با اندازهگیری واقعی
- 28Agent Skills و SKILL.md: افشای تدریجی، با اندازهگیری
- 29ارزیابی LLM: از benchmarkهای عمومی تا مجموعه طلایی شما
- 30Prompt Injection و Lethal Trifecta: ایمنسازی یک agent واقعی