
 #01
Vídeos
A IA explicada en vídeos breves
Unha idea por vídeo, con linguaxe clara. Cada un enlaza co capítulo do noso curso gratuíto que a explica paso a paso.
Comeza aquí AI 101
- #01
 #02
Machine learning: how a computer draws its own dividing line
 #03
Neural networks: layers of tiny calculators passing signals on
 #04
How AI learns: guess, measure the error, nudge, repeat
 #05
Tokens: how AI chops your words into numbered pieces
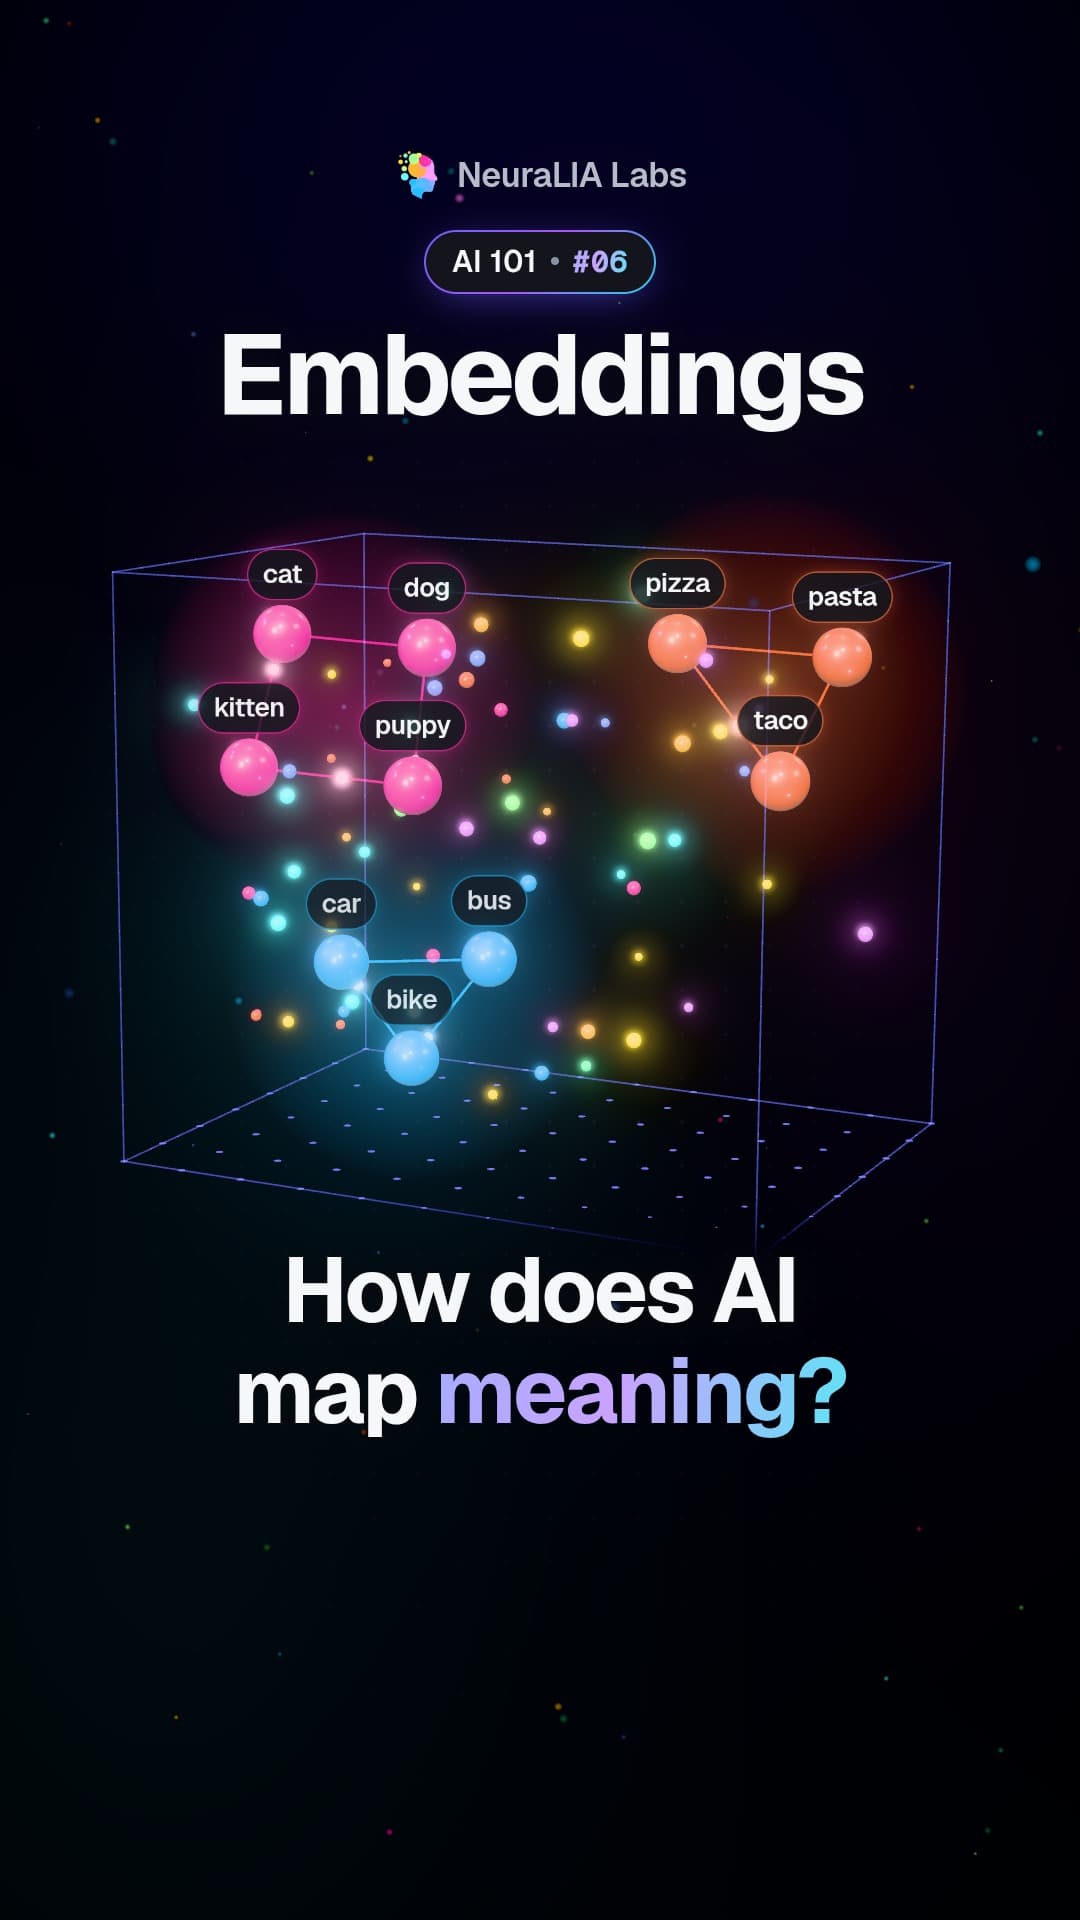 #06
Embeddings: why a puppy lands closer to a dog than to a pizza
Últimos
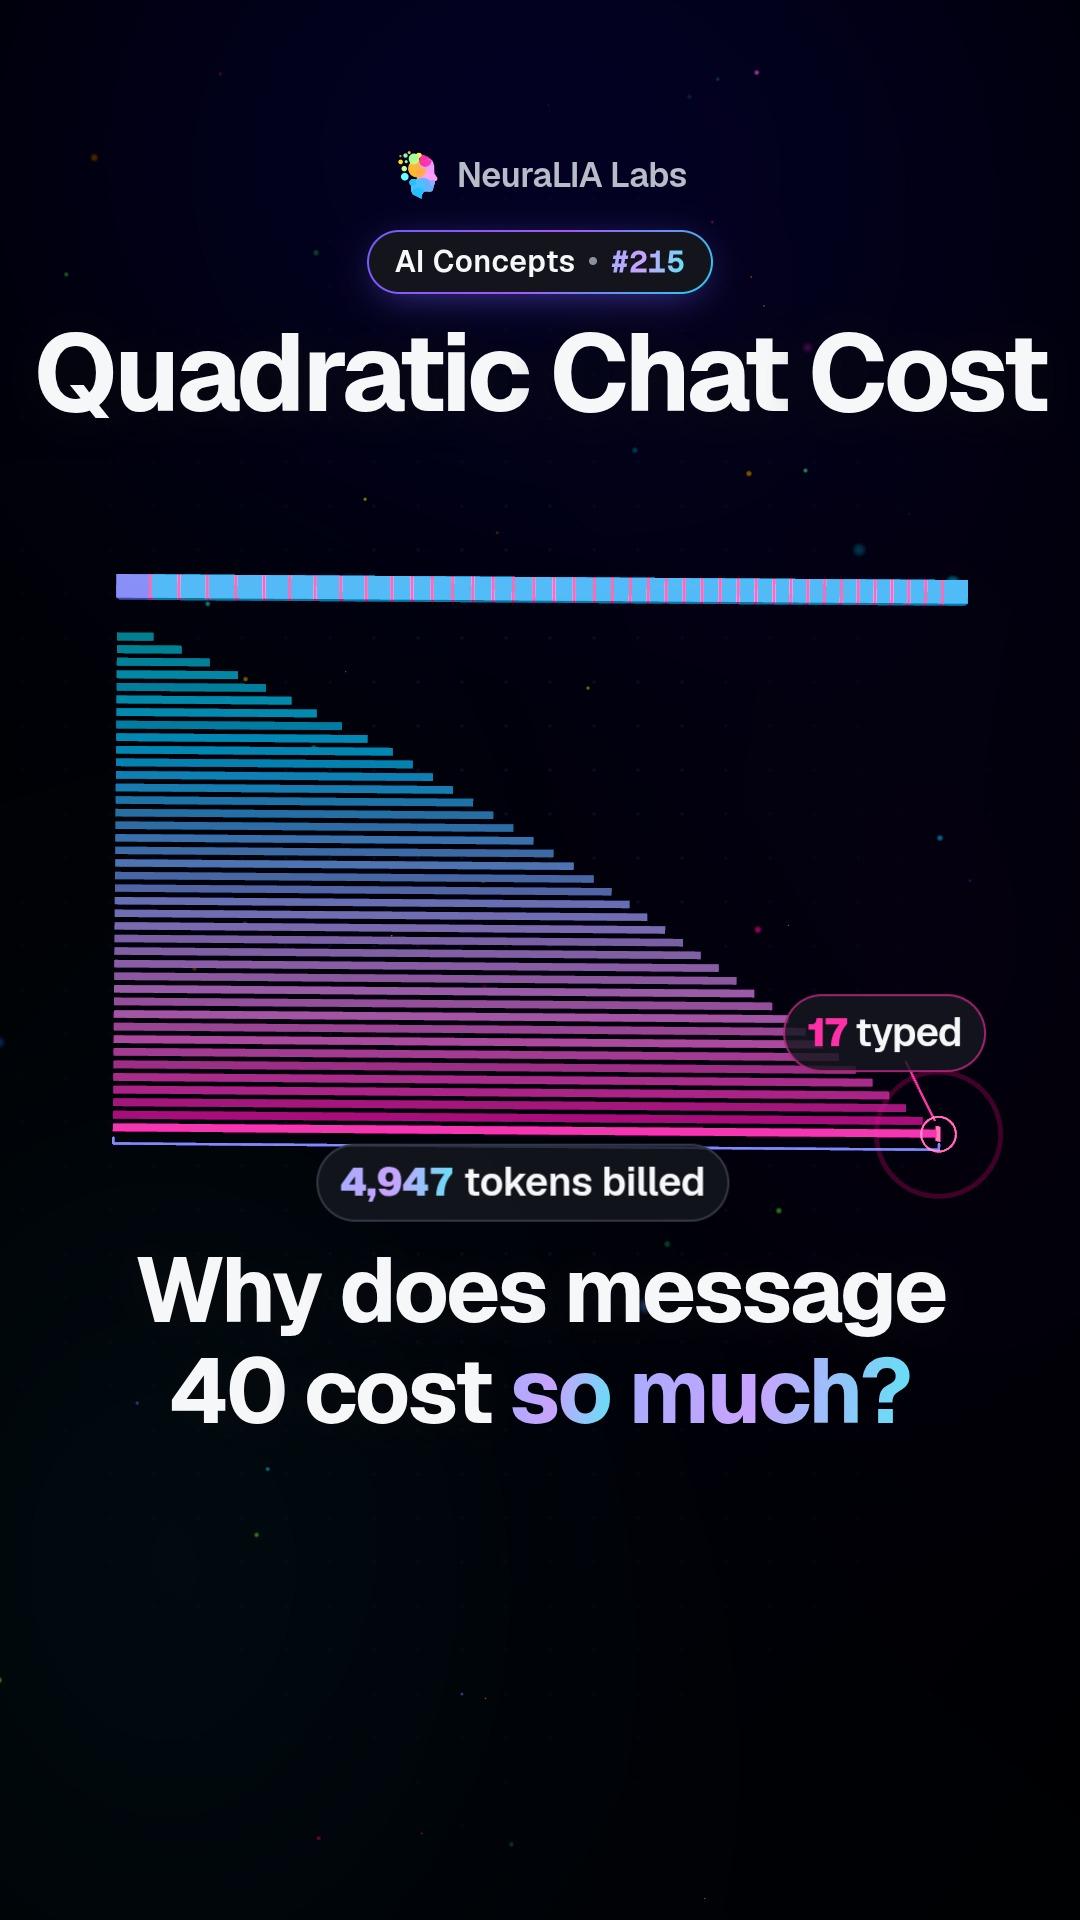 #215
Quadratic chat cost: why each new message costs more than the last
 #214
Stateless models: why your chatbot rereads the whole chat every time
 #213
Prompt versioning: treat your AI instructions like code, not a note
 #212
DSPy: describe the task and let a tool write the prompts
 #211
Auto prompt engineering: letting the AI search for its own wording
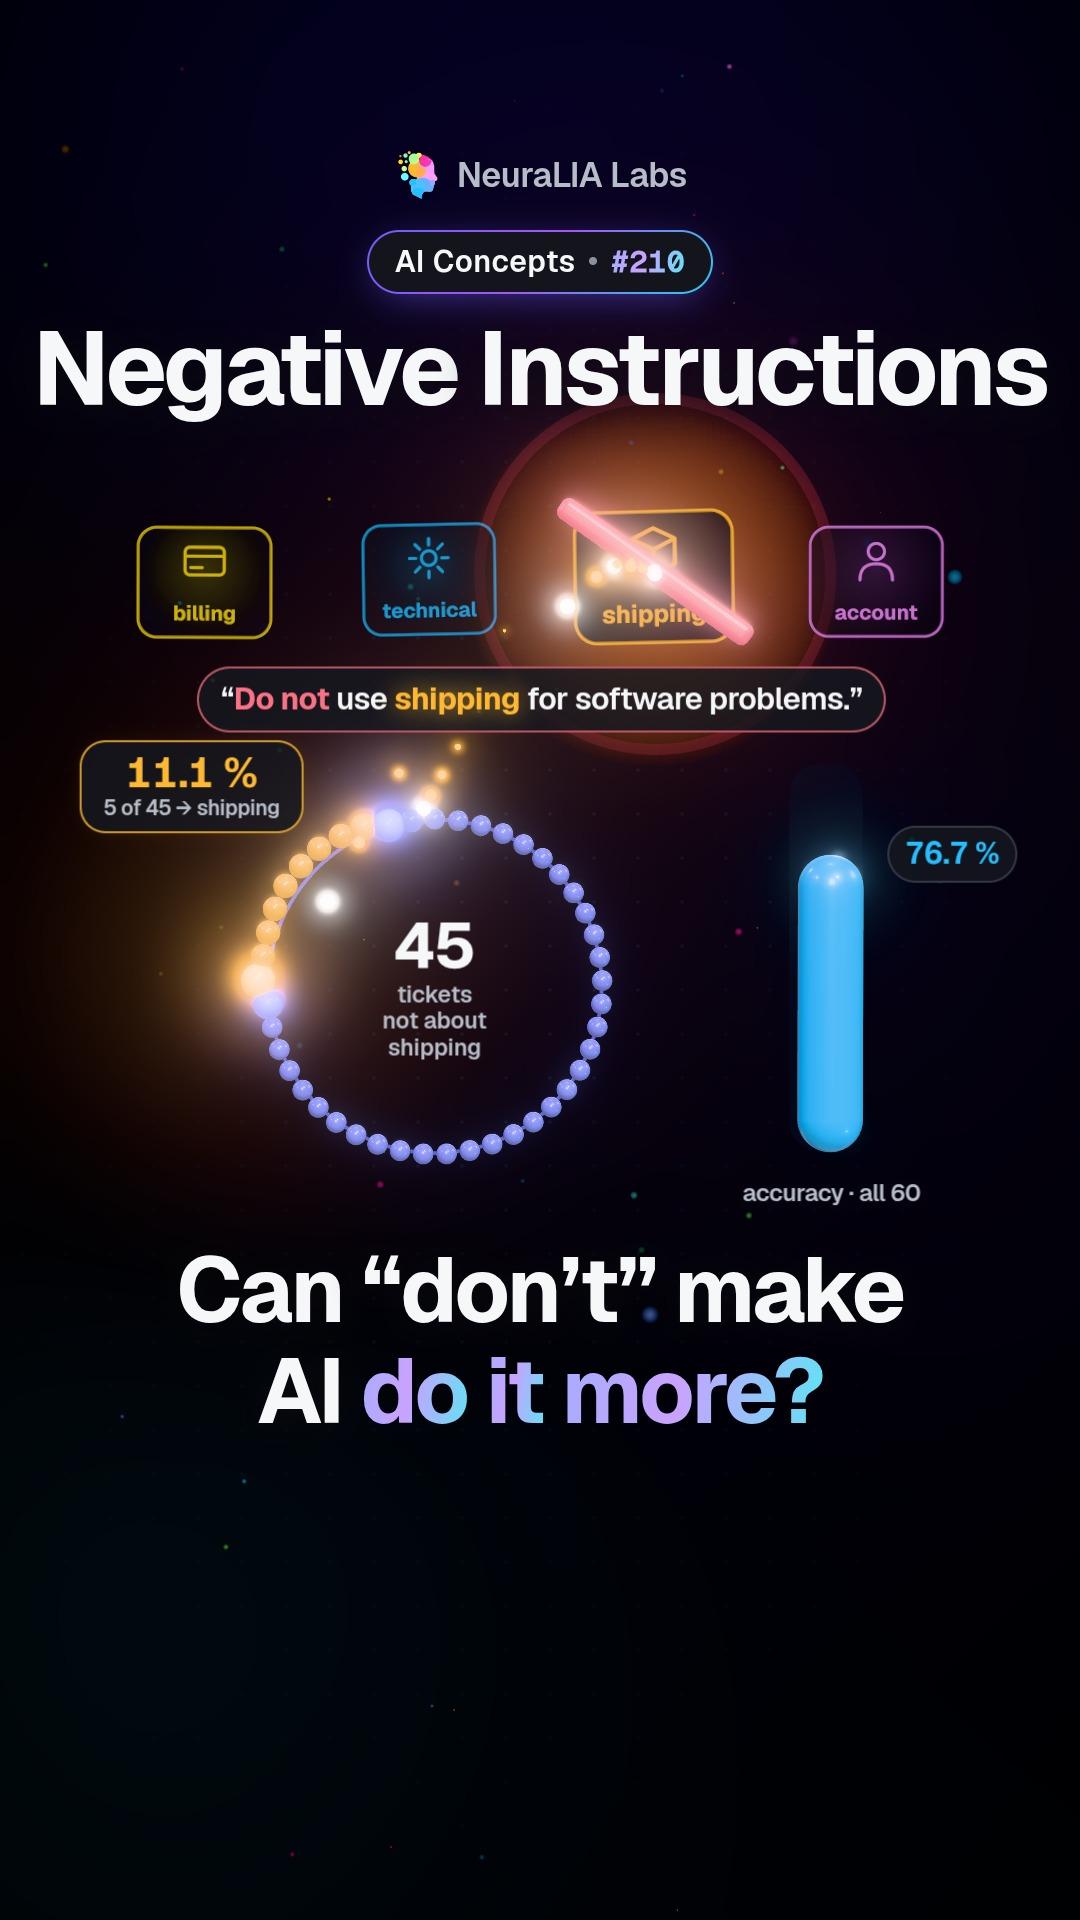 #210
Negative instructions: why telling an AI "don't" can backfire
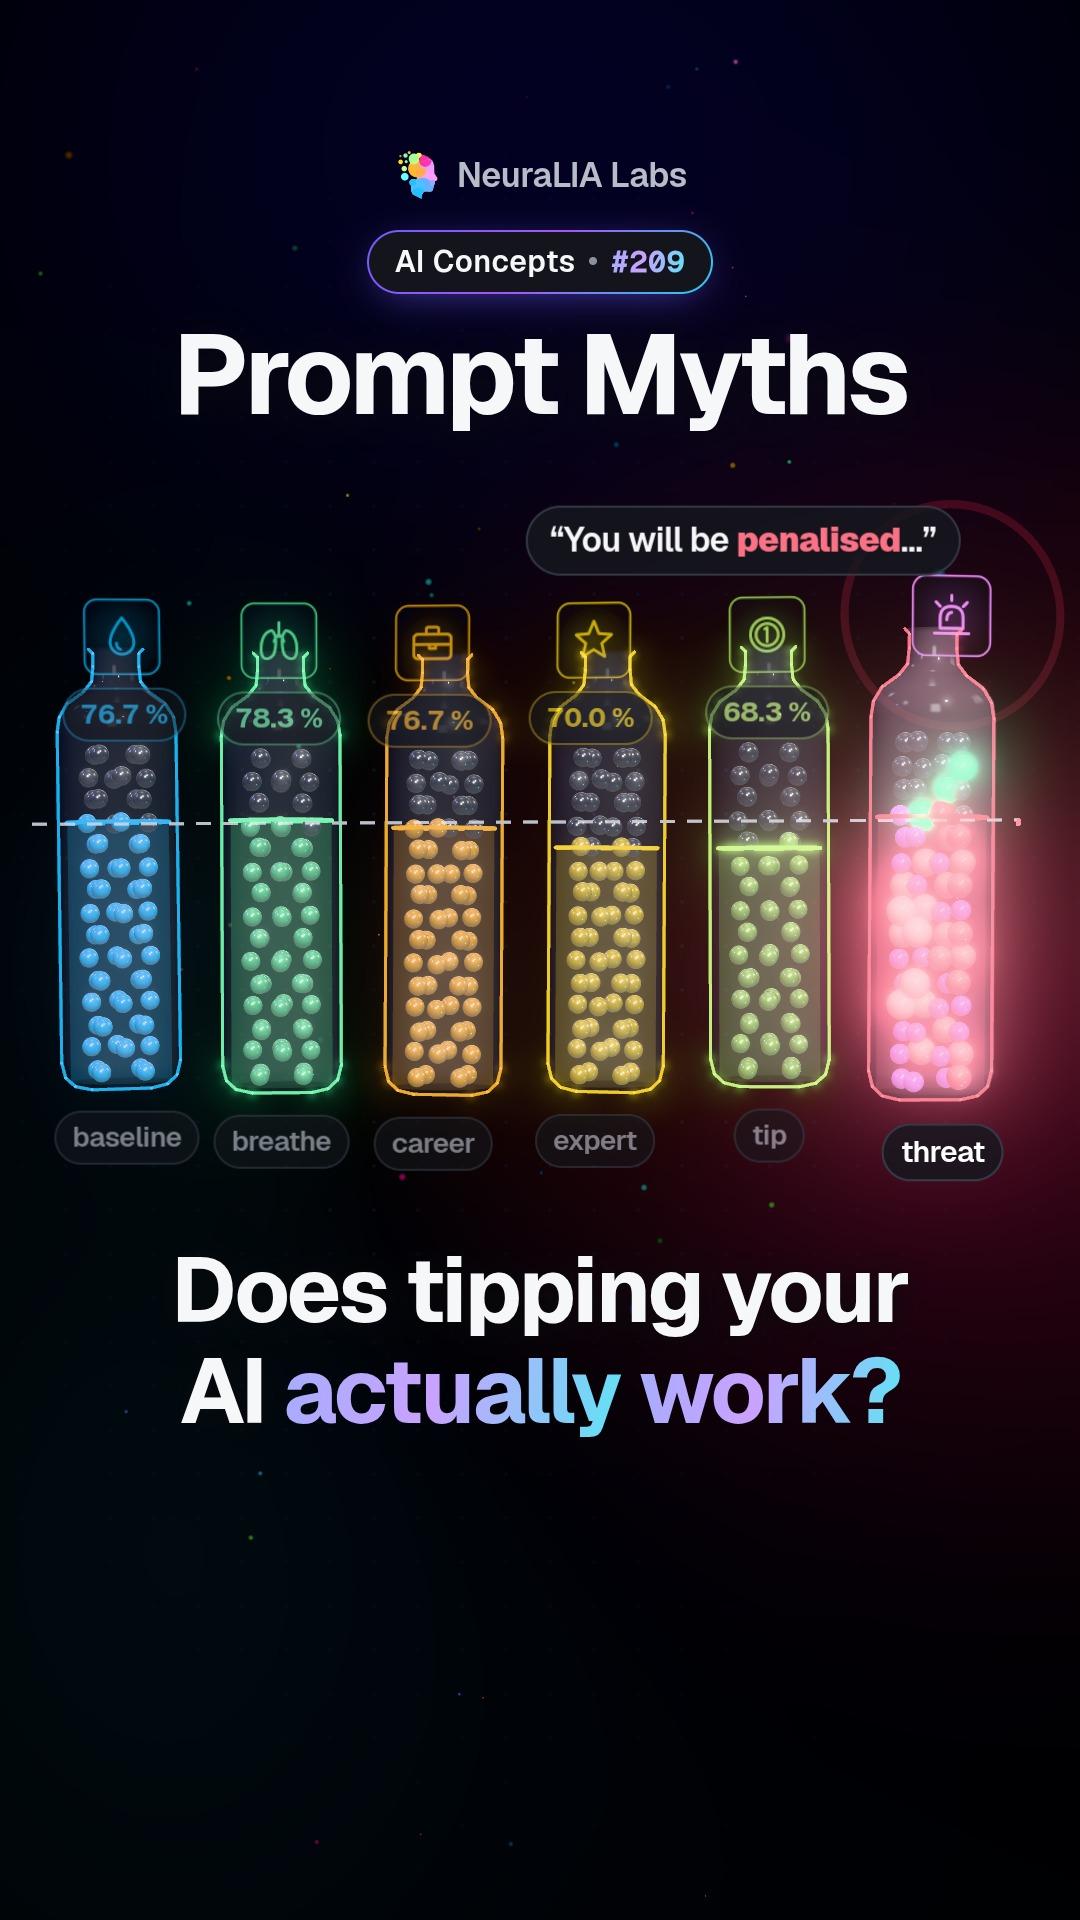 #209
Prompt myths: what tips, pep talks and threats did in a real test
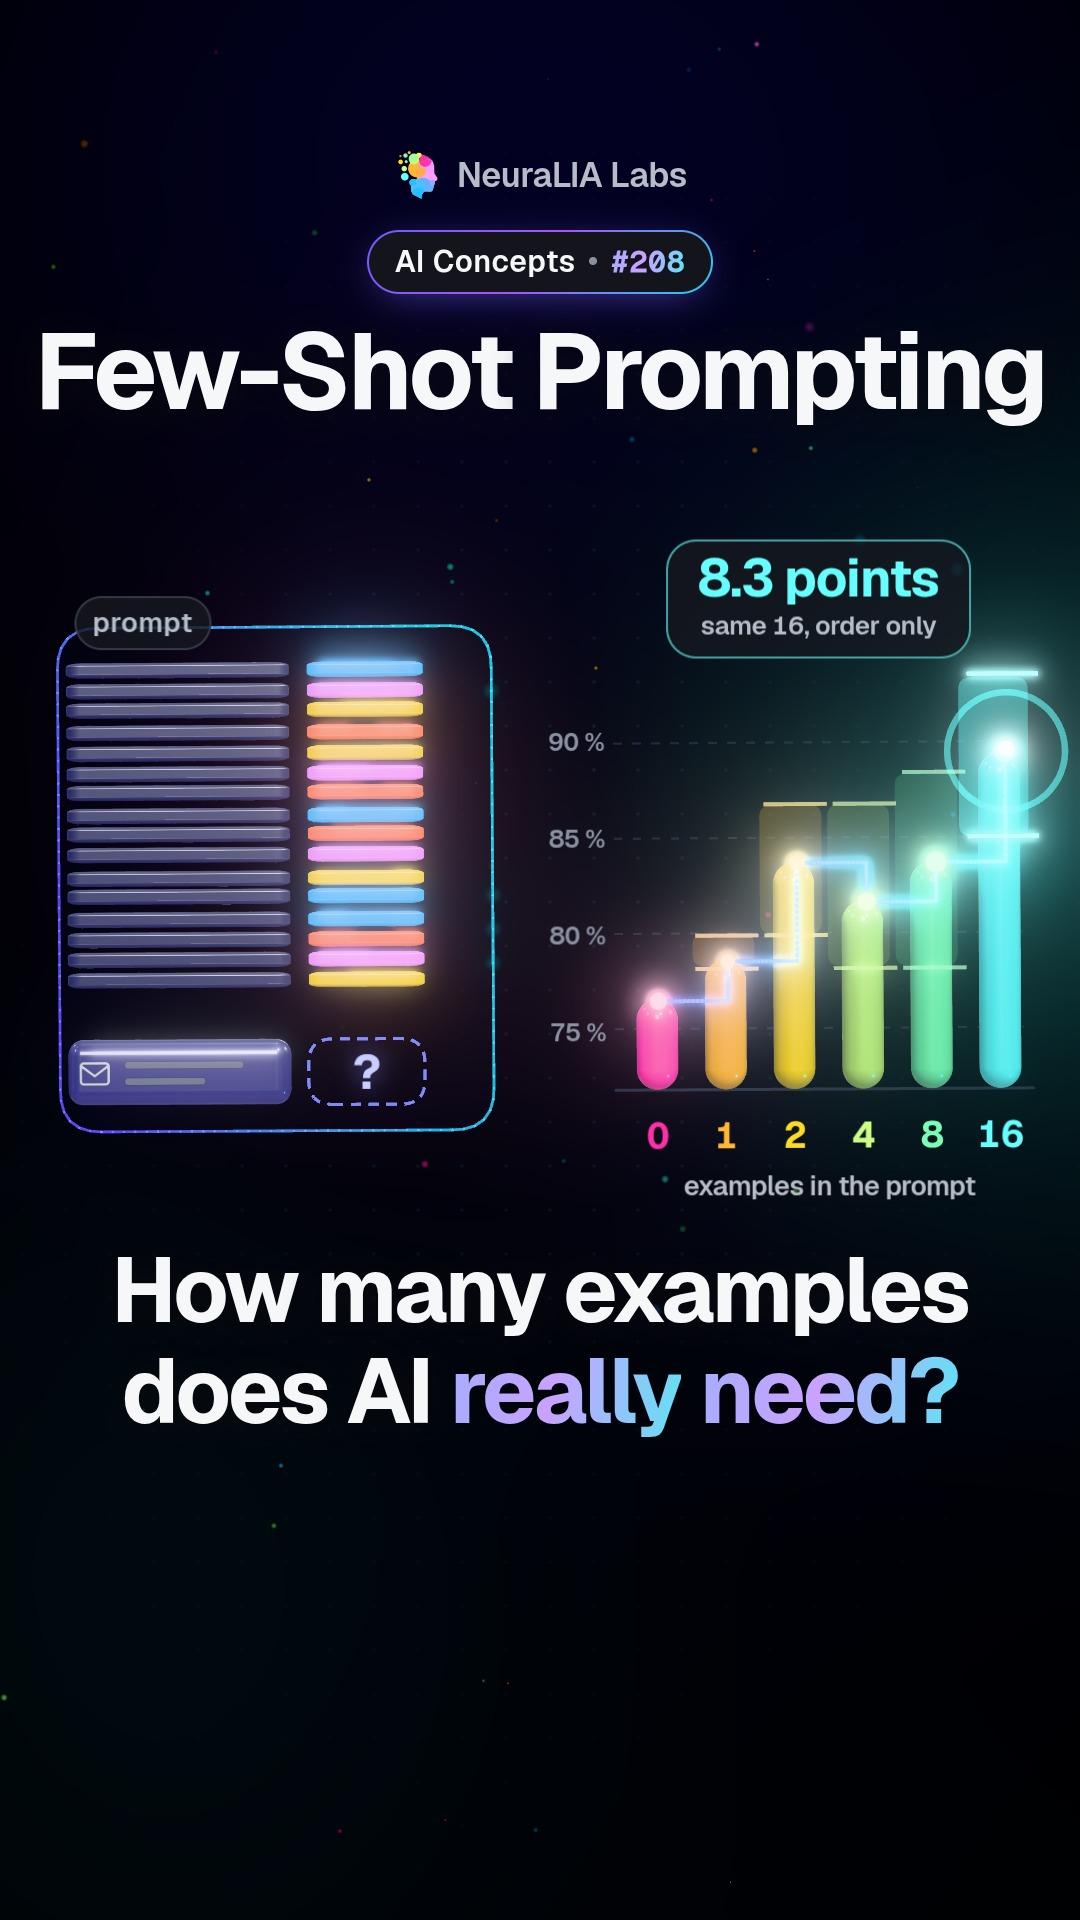 #208
Few-shot prompting: how many examples an AI prompt really needs
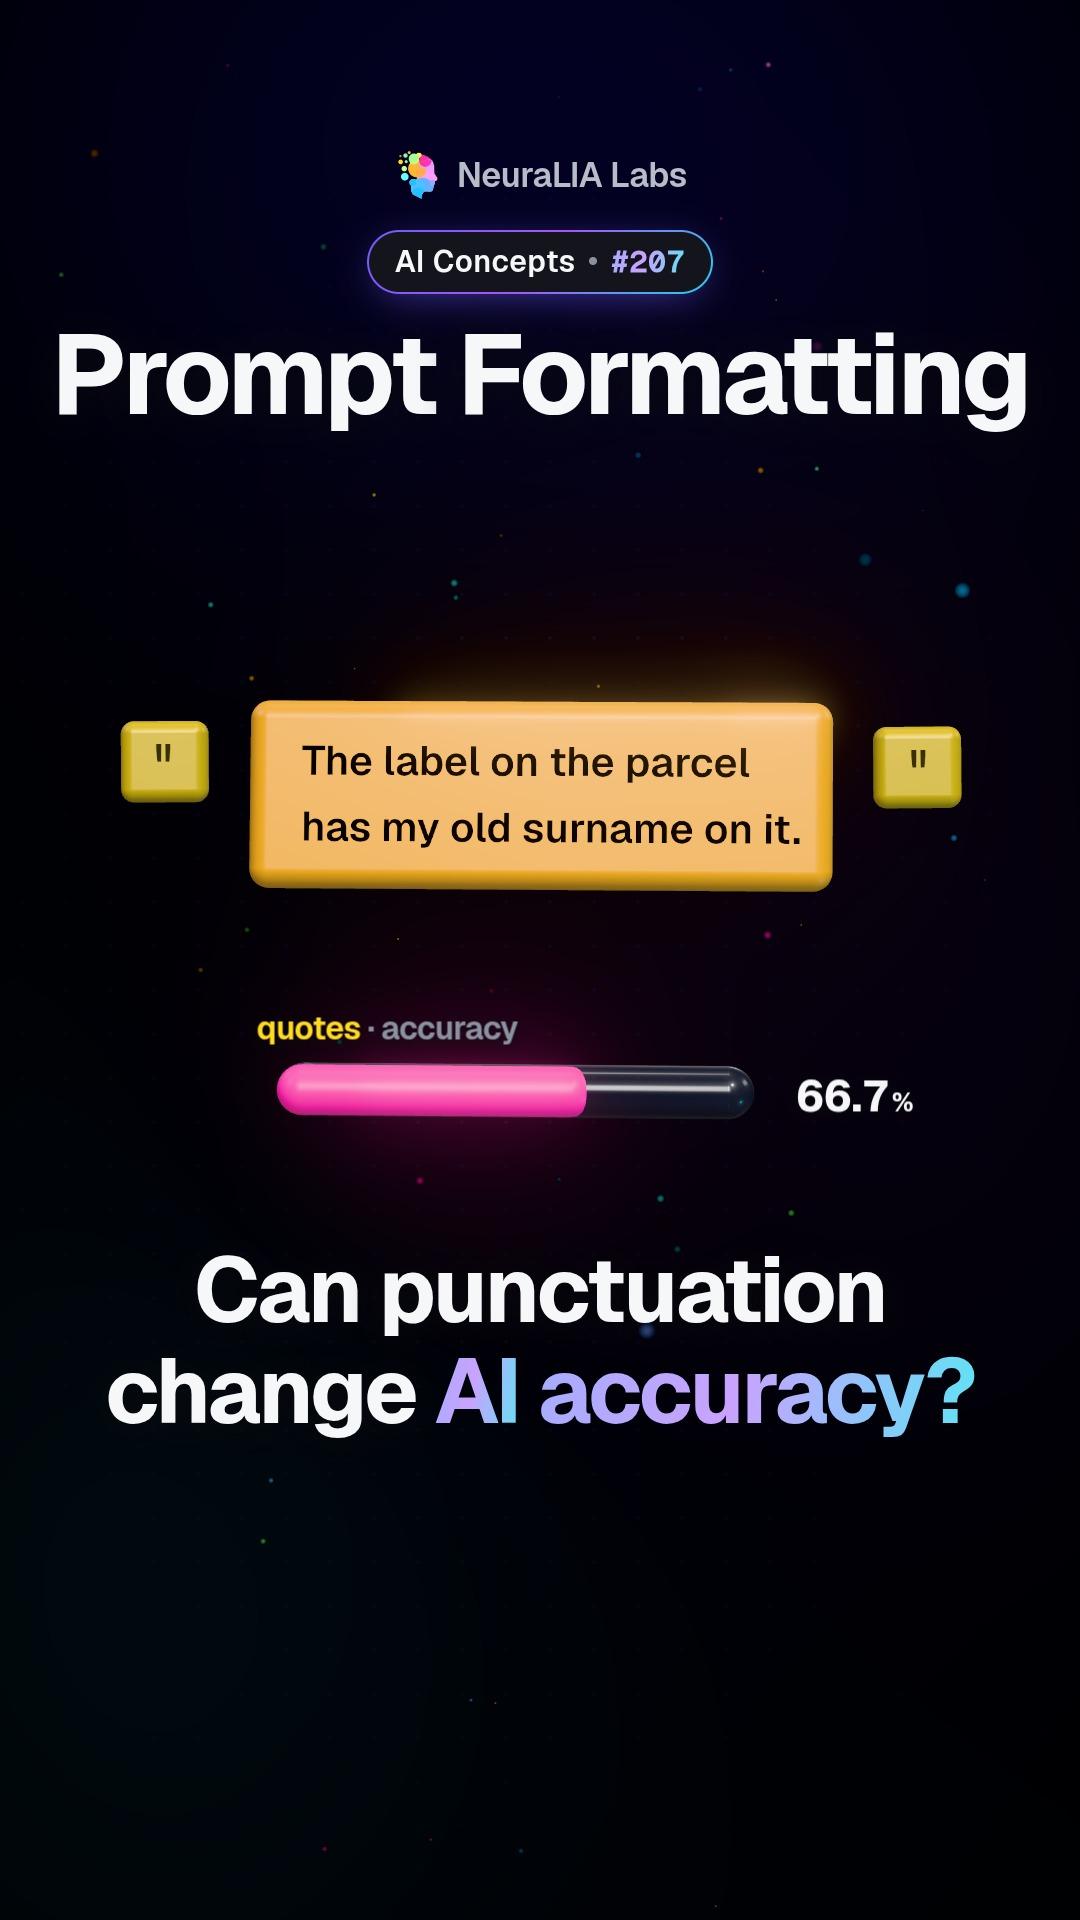 #207
Prompt formatting: how quotes and tags quietly shift AI accuracy
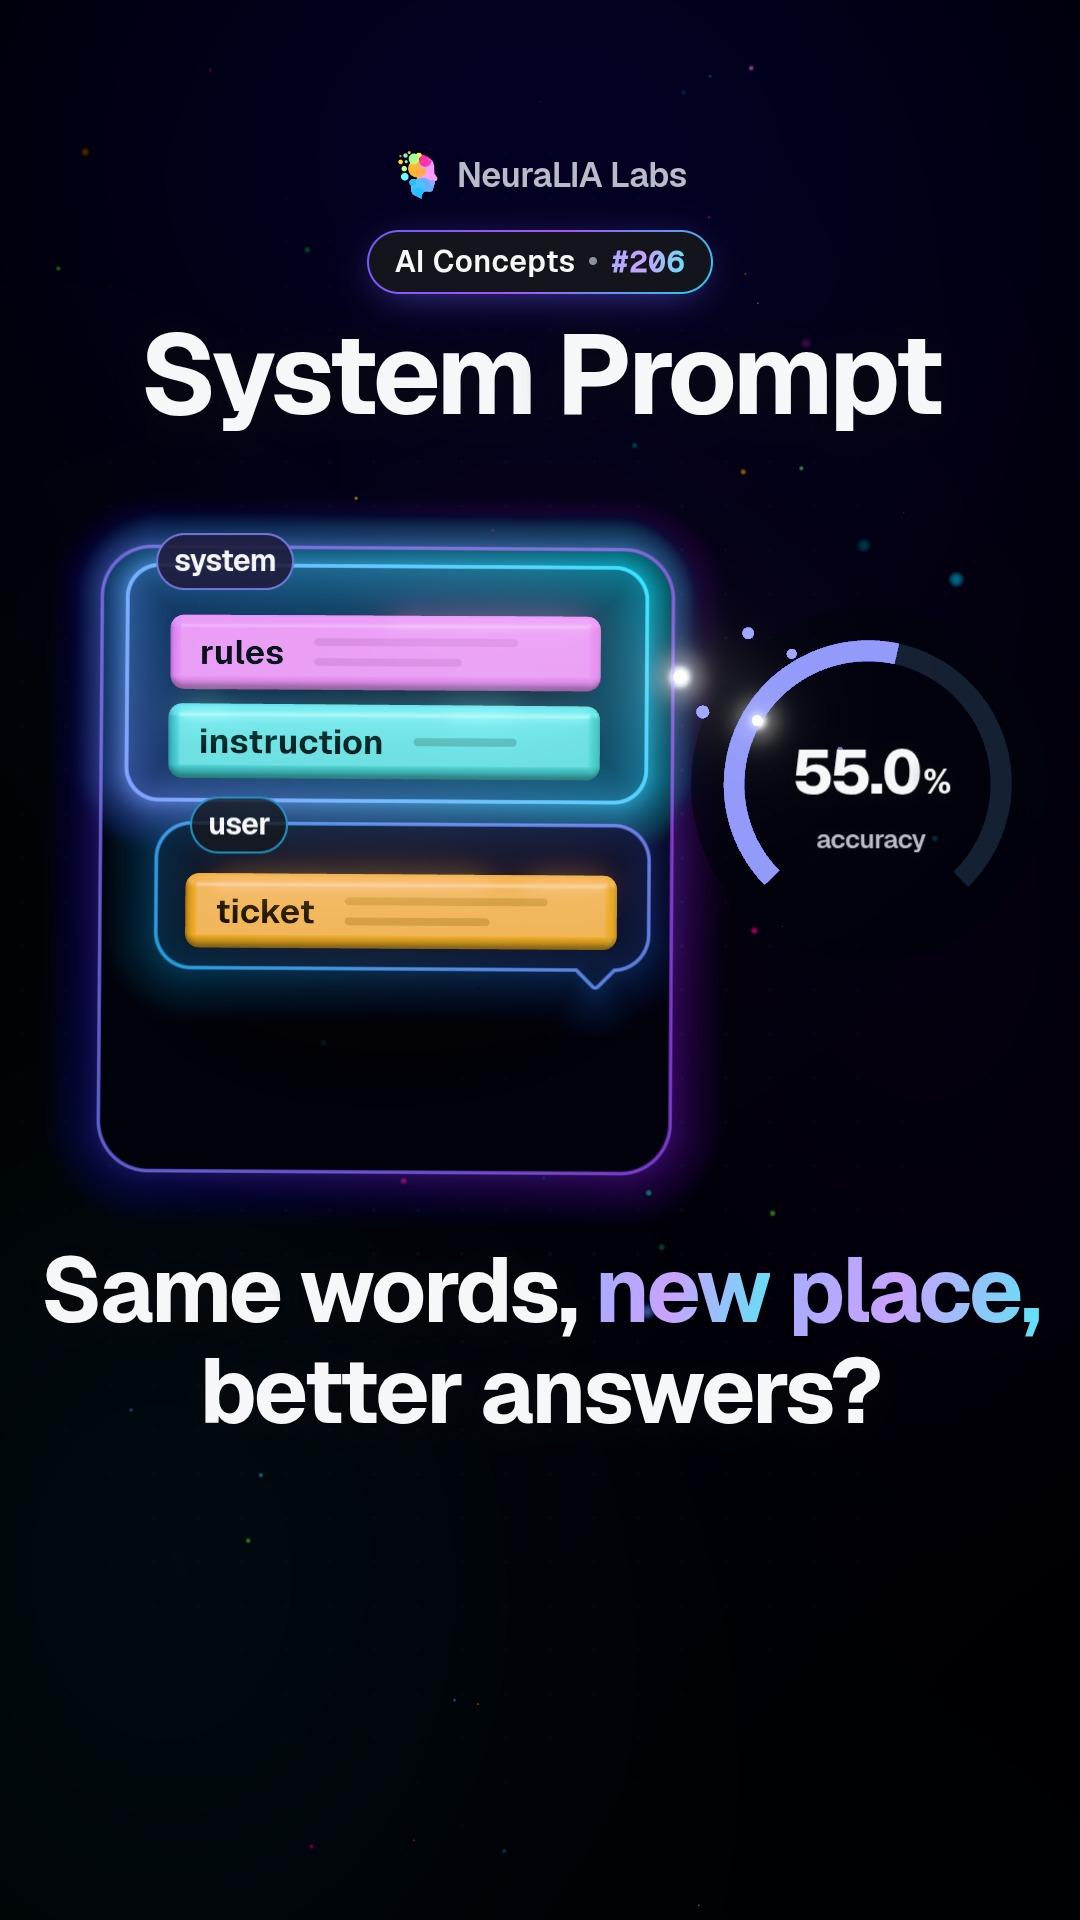 #206
System prompt: why where you put AI instructions changes results
 #205
Prompt order: the same words, rearranged, can double AI accuracy
 #204
Option order bias: when an AI picks a position, not an answer
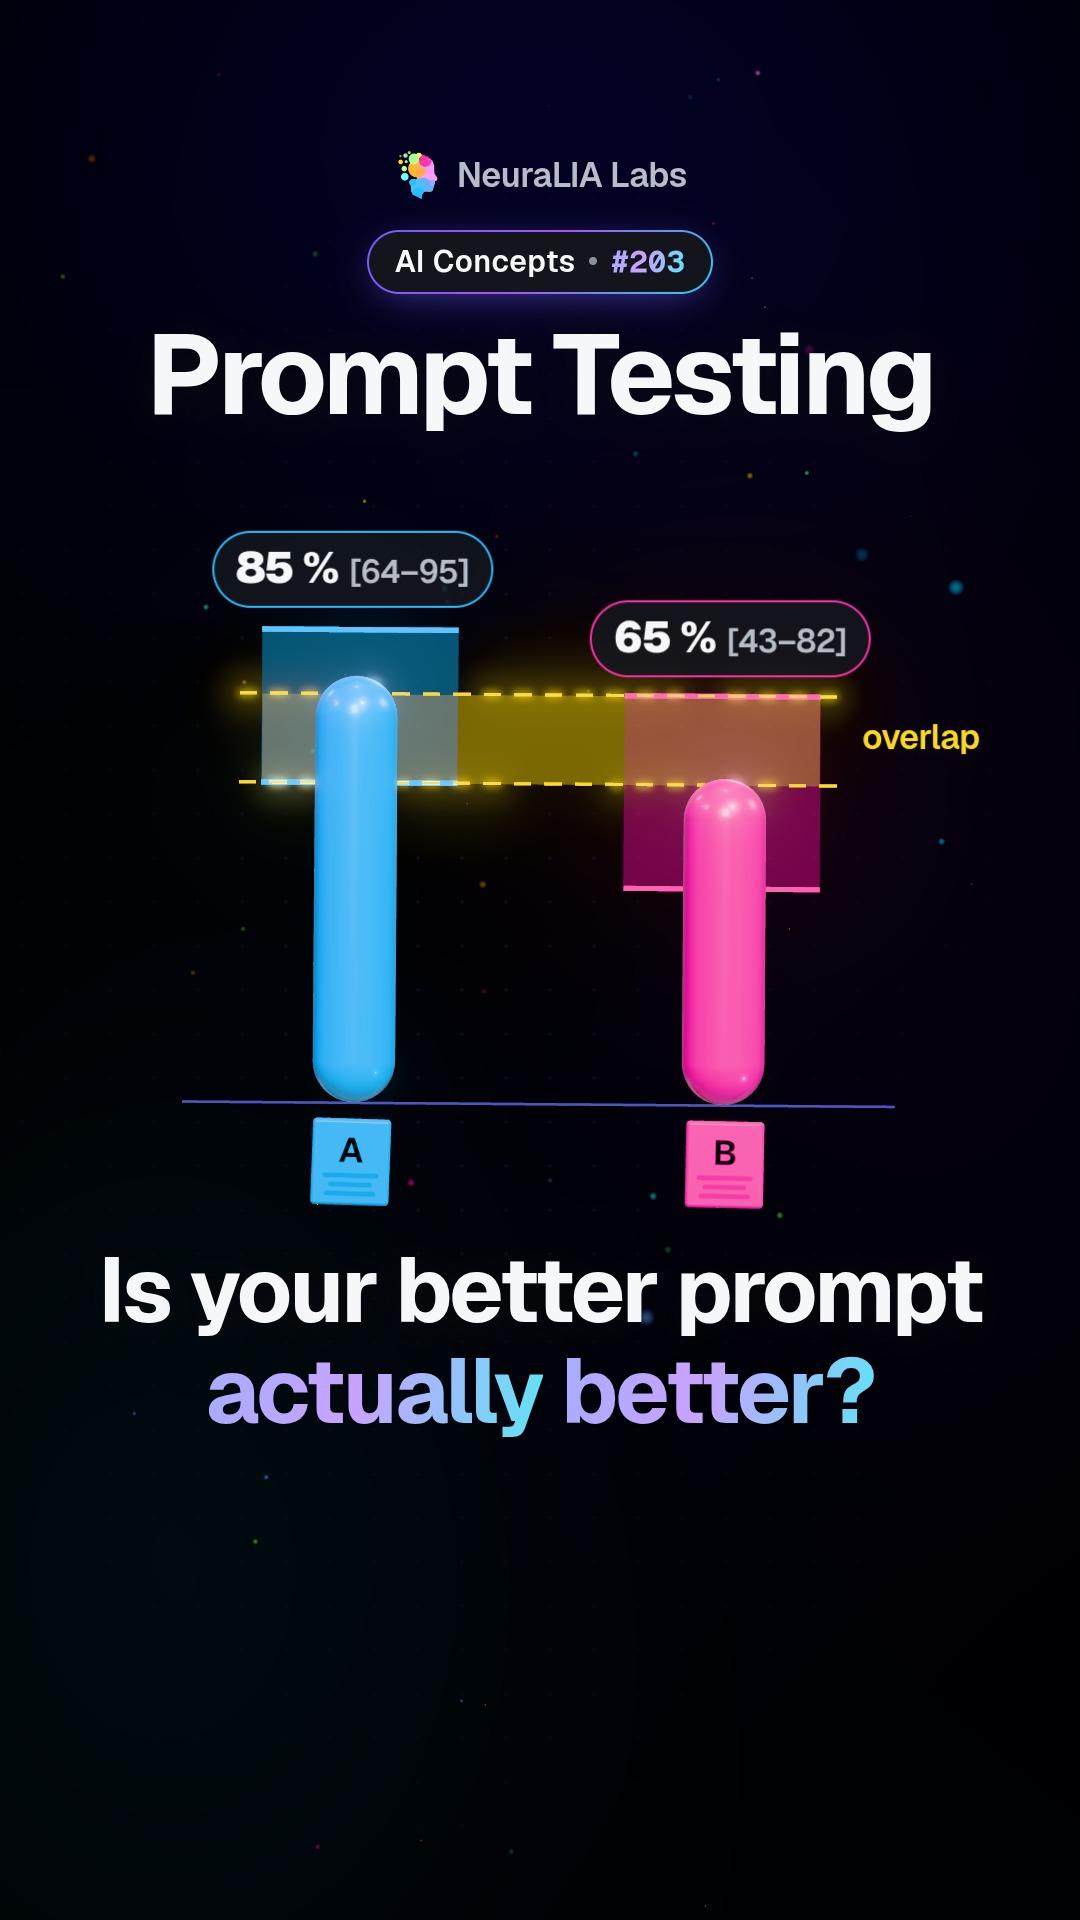 #203
Prompt testing: why twenty examples can't prove a prompt is better
 #202
Idempotency key: how to retry an AI request without paying twice
 #201
Idle timeout: how to tell a long AI answer from a frozen one
 #200
Timeouts: why every AI request needs a deadline you choose
 #199
Rate limits: when an AI service says wait, wait at least that long
 #198
Concurrency gate: letting fewer requests in made everything faster
 #197
Thundering herd: when retrying apps move in lockstep and jam a server
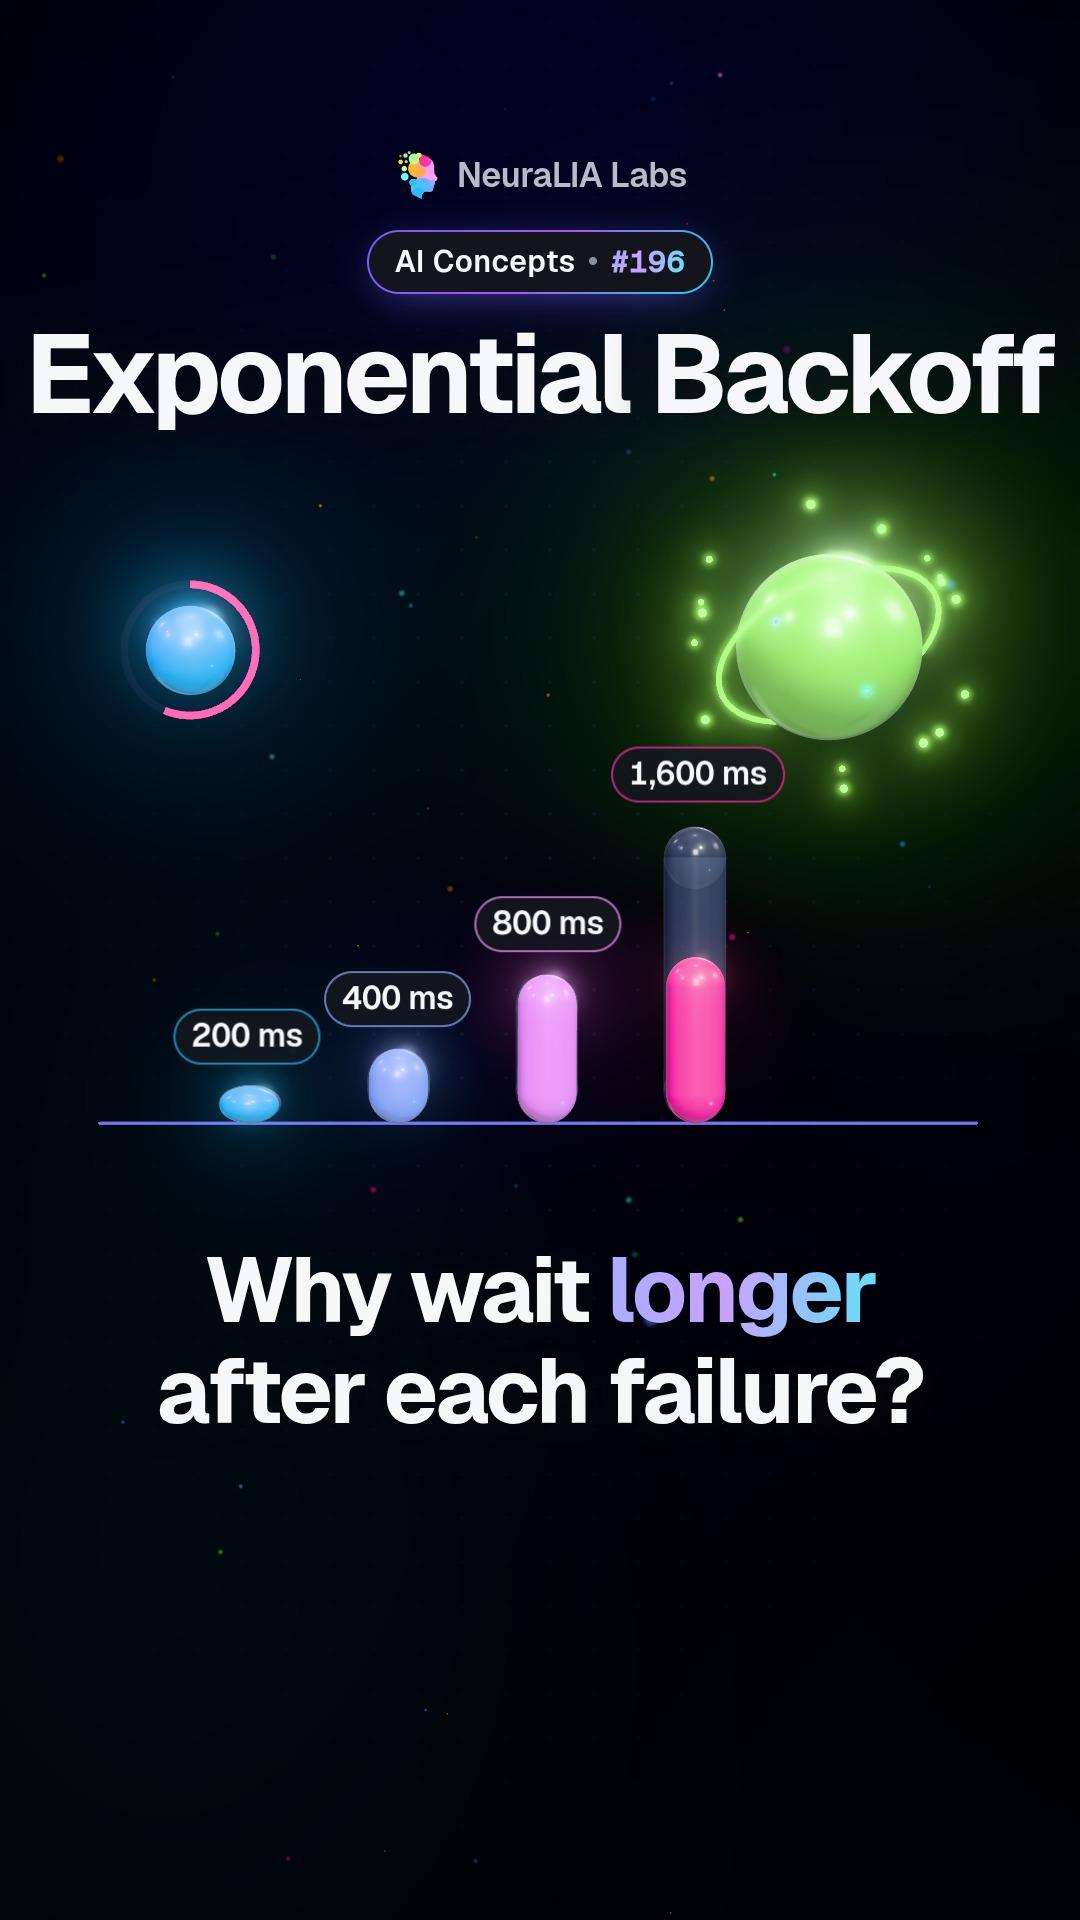 #196
Exponential backoff: why a retry should wait twice as long each time
 #195
Error triage: which AI errors deserve a retry and which never do
 #194
Finish reason: telling a finished AI answer from a cut-off one
 #193
Streaming: why AI answers arrive word by word, and what it really buys
 #192
API key safety: why your AI key must never reach the browser
Por capítulo do curso
- 1O perceptrón desde cero: que calcula unha neurona10 vídeos
- 2De onde vén unha función de perda: verosimilitude, non convención12 vídeos
- 3Costa abaixo: Gradient Descent e os dous pasos que todo o mundo salta13 vídeos
- 4Clasificación, entropía cruzada e como non enganarte a ti mesmo22 vídeos
- 5Backpropagation desde cero: primeiro o motor, despois a rede11 vídeos
- 6Facer que adestre e facer que xeneralice19 vídeos
- 7Constrúe un tokenizador BPE: por que o teu modelo non pode contar os R12 vídeos
- 8Predición do seguinte token: embeddings e que significa a perplexidade17 vídeos
- 9Attention e o bloque transformer, derivados dunha media17 vídeos
- 10Preadestrar un LLM: datos, cómputo, leis de escala e custo21 vídeos
- 11Do modelo base ao asistente: SFT, RLHF, DPO e GRPO16 vídeos
- 12Chain of Thought, RLVR e test-time compute, medidos9 vídeos
- 13Facer barata a inferencia: KV cache, batching e cuantización18 vídeos
- 14A túa primeira chamada LLM en produción: streaming, reintentos e timeouts11 vídeos
- 15Prompt engineering, medido: que cambia a saída11 vídeos
- 16A context window, os tokens e a factura, medidos2 vídeos
- 17Temperatura, top-p e o determinismo que non tes
- 18Tool Calling e saídas estruturadas: o contrato que aguanta
- 19RAG en produción: chunking, recuperación e citas honestas
- 20Fine-tuning, recuperación ou prompt? A decisión é económica
- 21Prezos multimodais: o que realmente facturan as imaxes, o audio e o vídeo
- 22Que é un AI agent: cinco tipos clásicos, dúas definicións rivais
- 23Constrúe un agent harness: o loop e as súas cinco saídas
- 24Context Engineering: por que o teu agent se volve máis parvo na quenda 40
- 25Orquestración multi-agent: cinco patróns e cando gaña un só
- 26MCP explicado fronte á especificación: que é realmente un servidor
- 27Publica un MCP server: TypeScript e Python, medidos
- 28Agent Skills e SKILL.md: divulgación progresiva, medida
- 29Avaliación de LLM: dos benchmarks públicos ao teu conxunto de ouro
- 30Prompt injection e a trifecta letal: protexer un agent real