
 #01
वीडियो
छोटे वीडियो में AI समझें
हर वीडियो में एक आइडिया, सरल भाषा में। हर वीडियो हमारे मुफ्त कोर्स के उस अध्याय से जुड़ा है जो उसे चरण-दर-चरण समझाता है।
यहाँ से शुरू करें AI 101
- #01
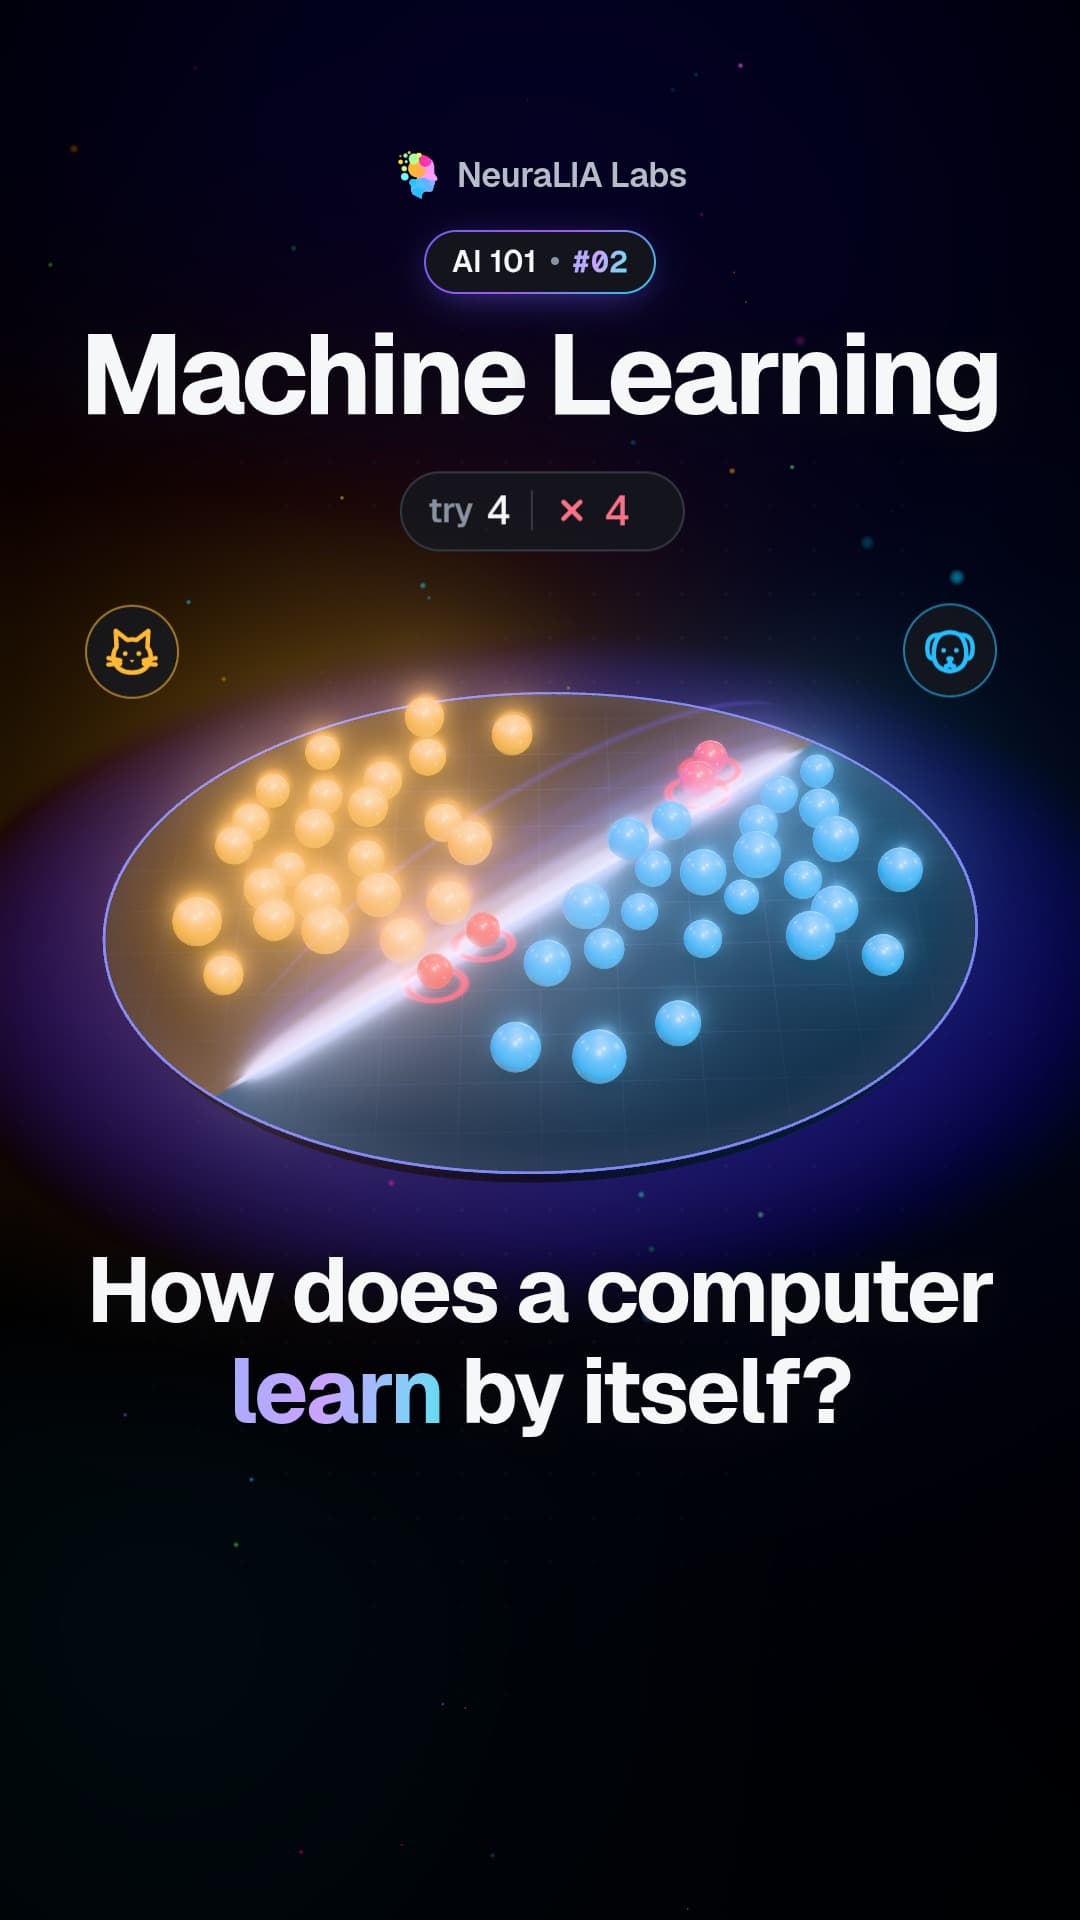 #02
Machine learning: how a computer draws its own dividing line
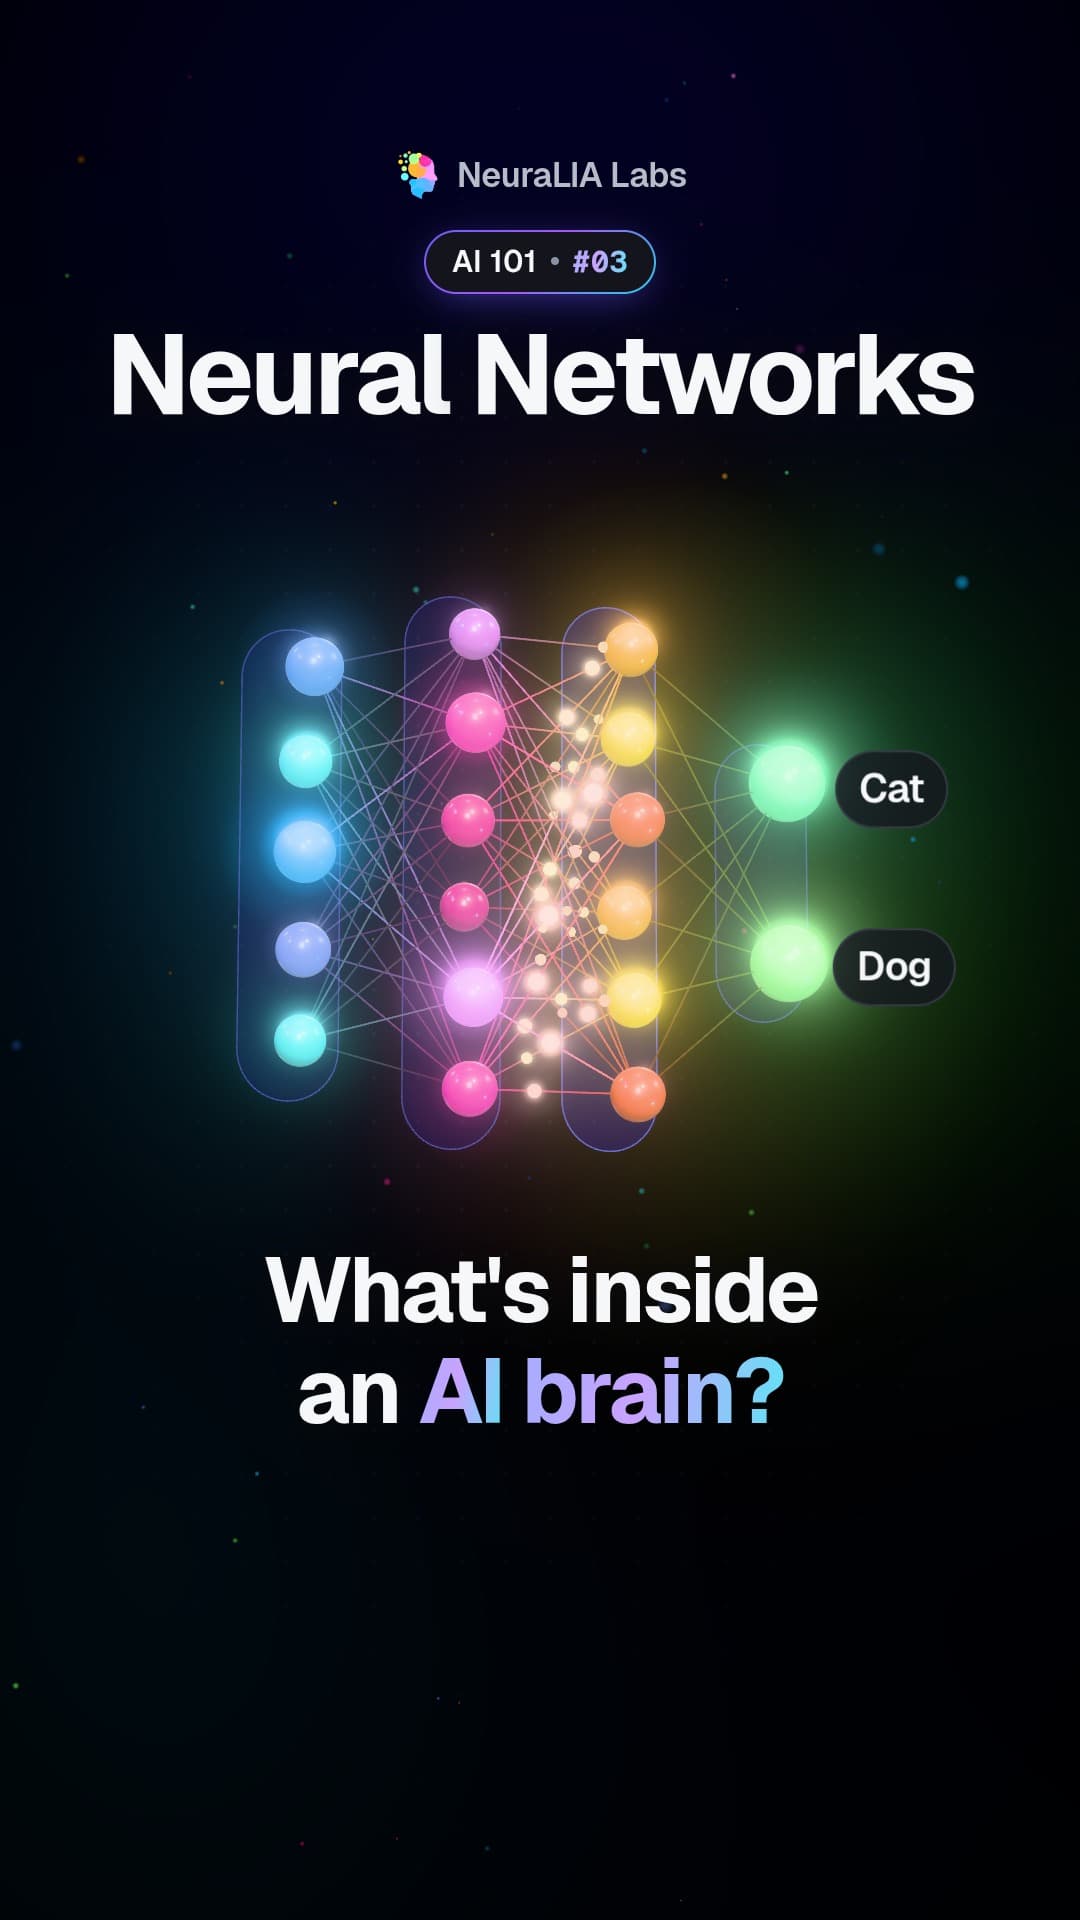 #03
Neural networks: layers of tiny calculators passing signals on
 #04
How AI learns: guess, measure the error, nudge, repeat
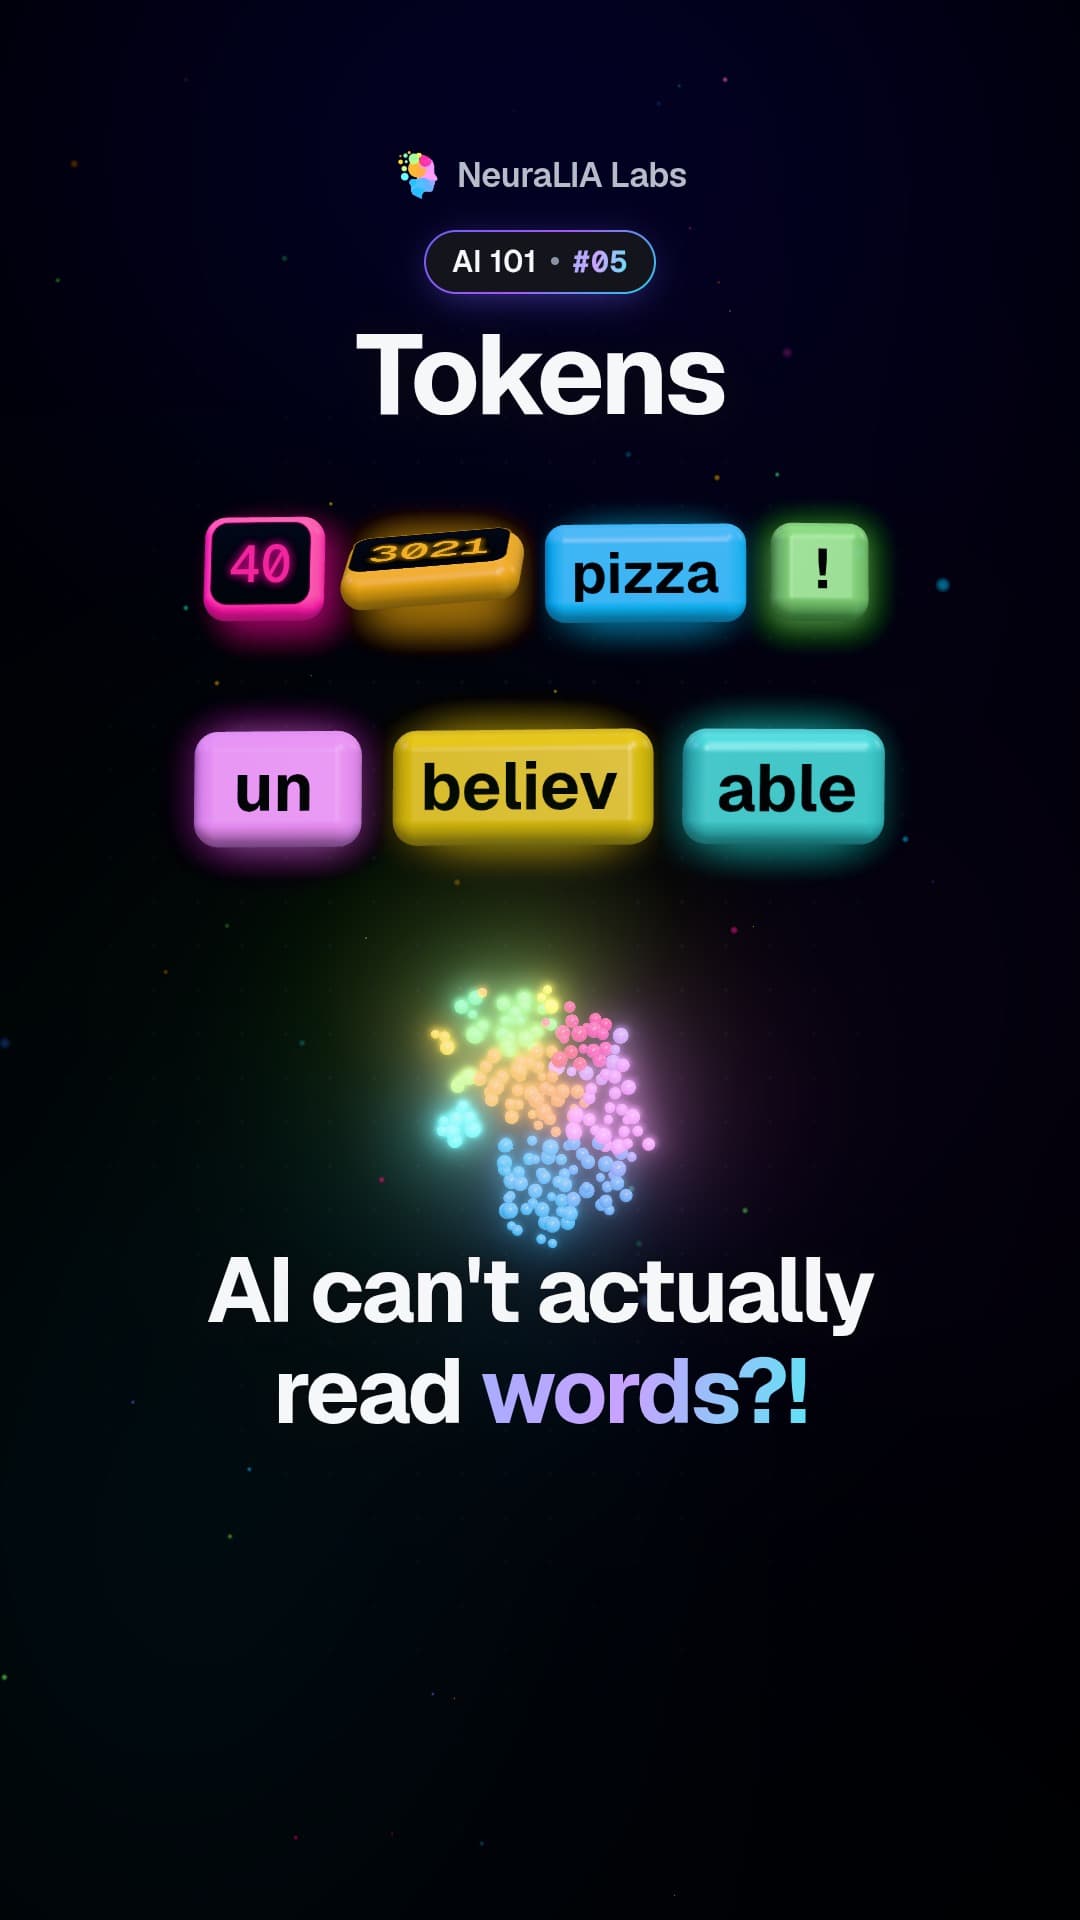 #05
Tokens: how AI chops your words into numbered pieces
 #06
Embeddings: why a puppy lands closer to a dog than to a pizza
नवीनतम
 #031
Momentum: how remembering past steps stops AI training zigzagging
 #030
Mini-batches: why AI learns faster from a random handful of data
 #029
Saddle points: where AI training looks stuck but has a way down
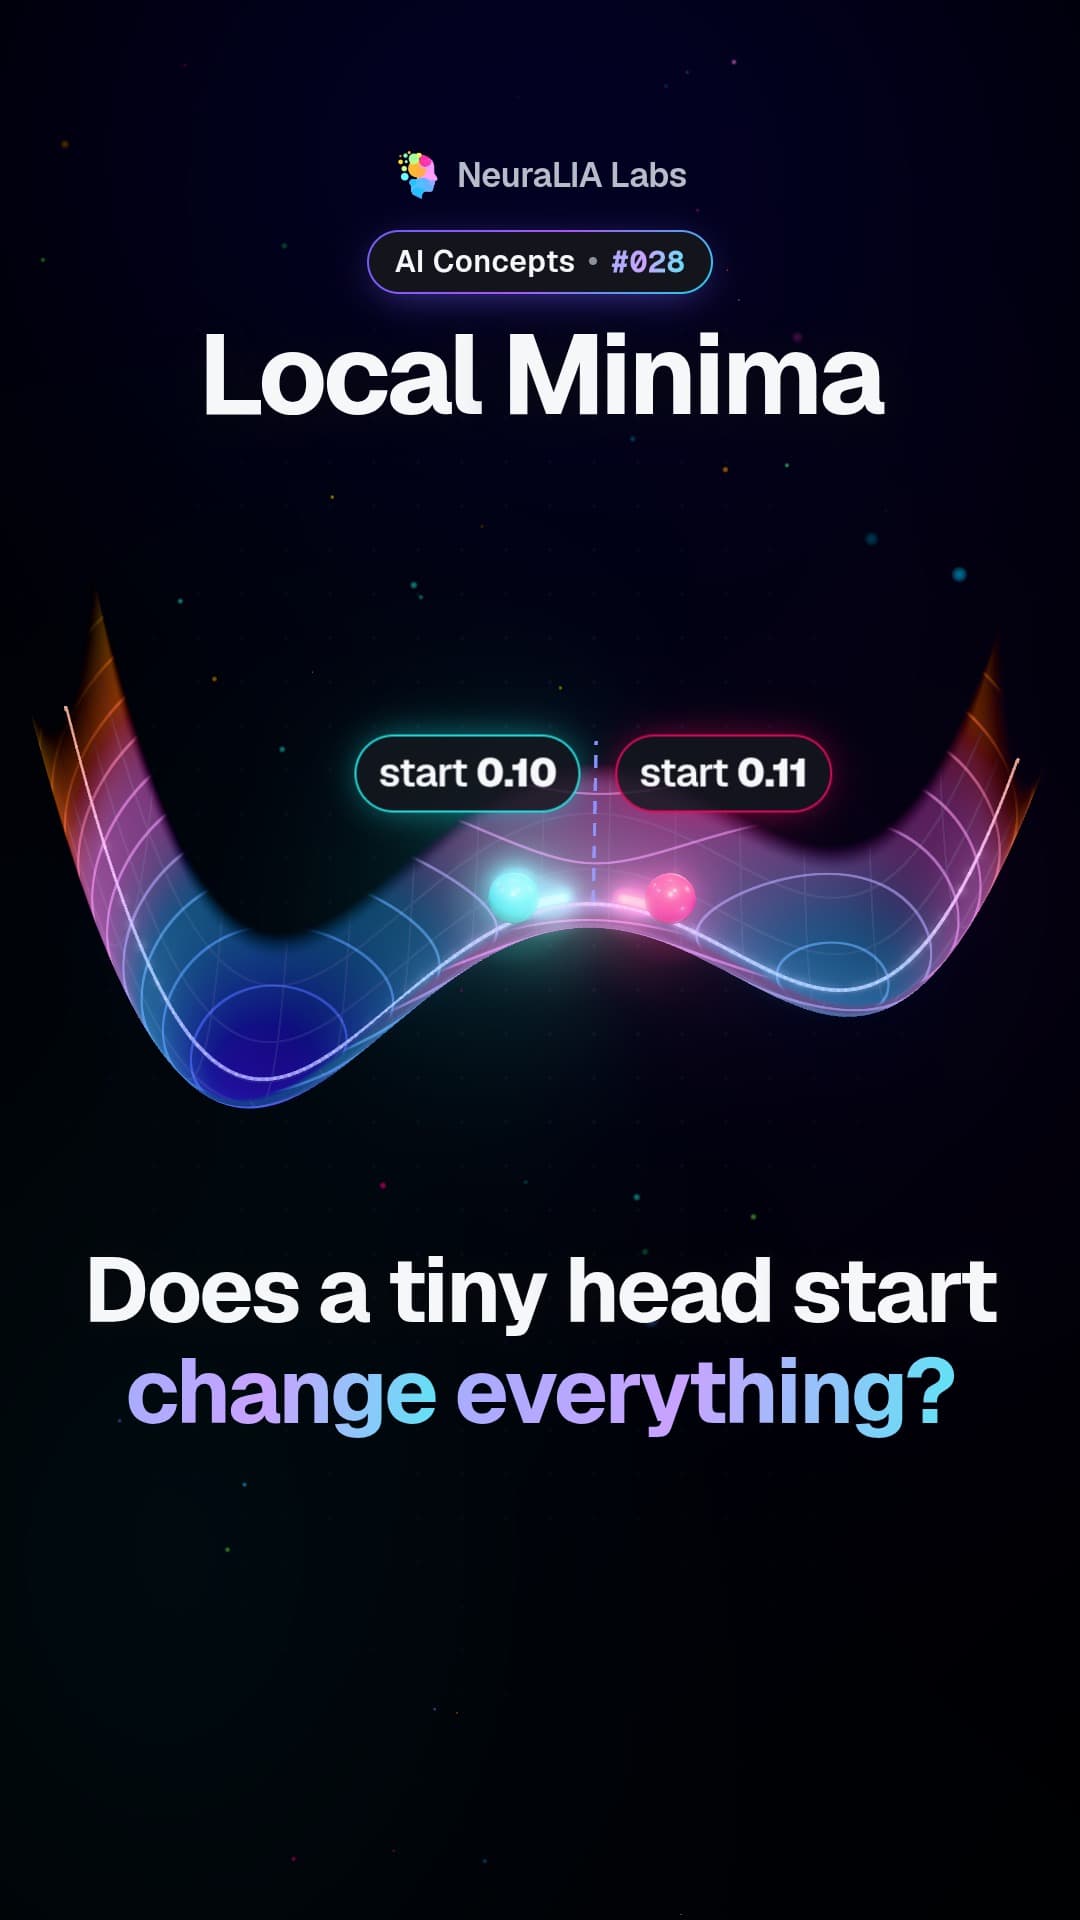 #028
Local minima: why AI training can settle for second best
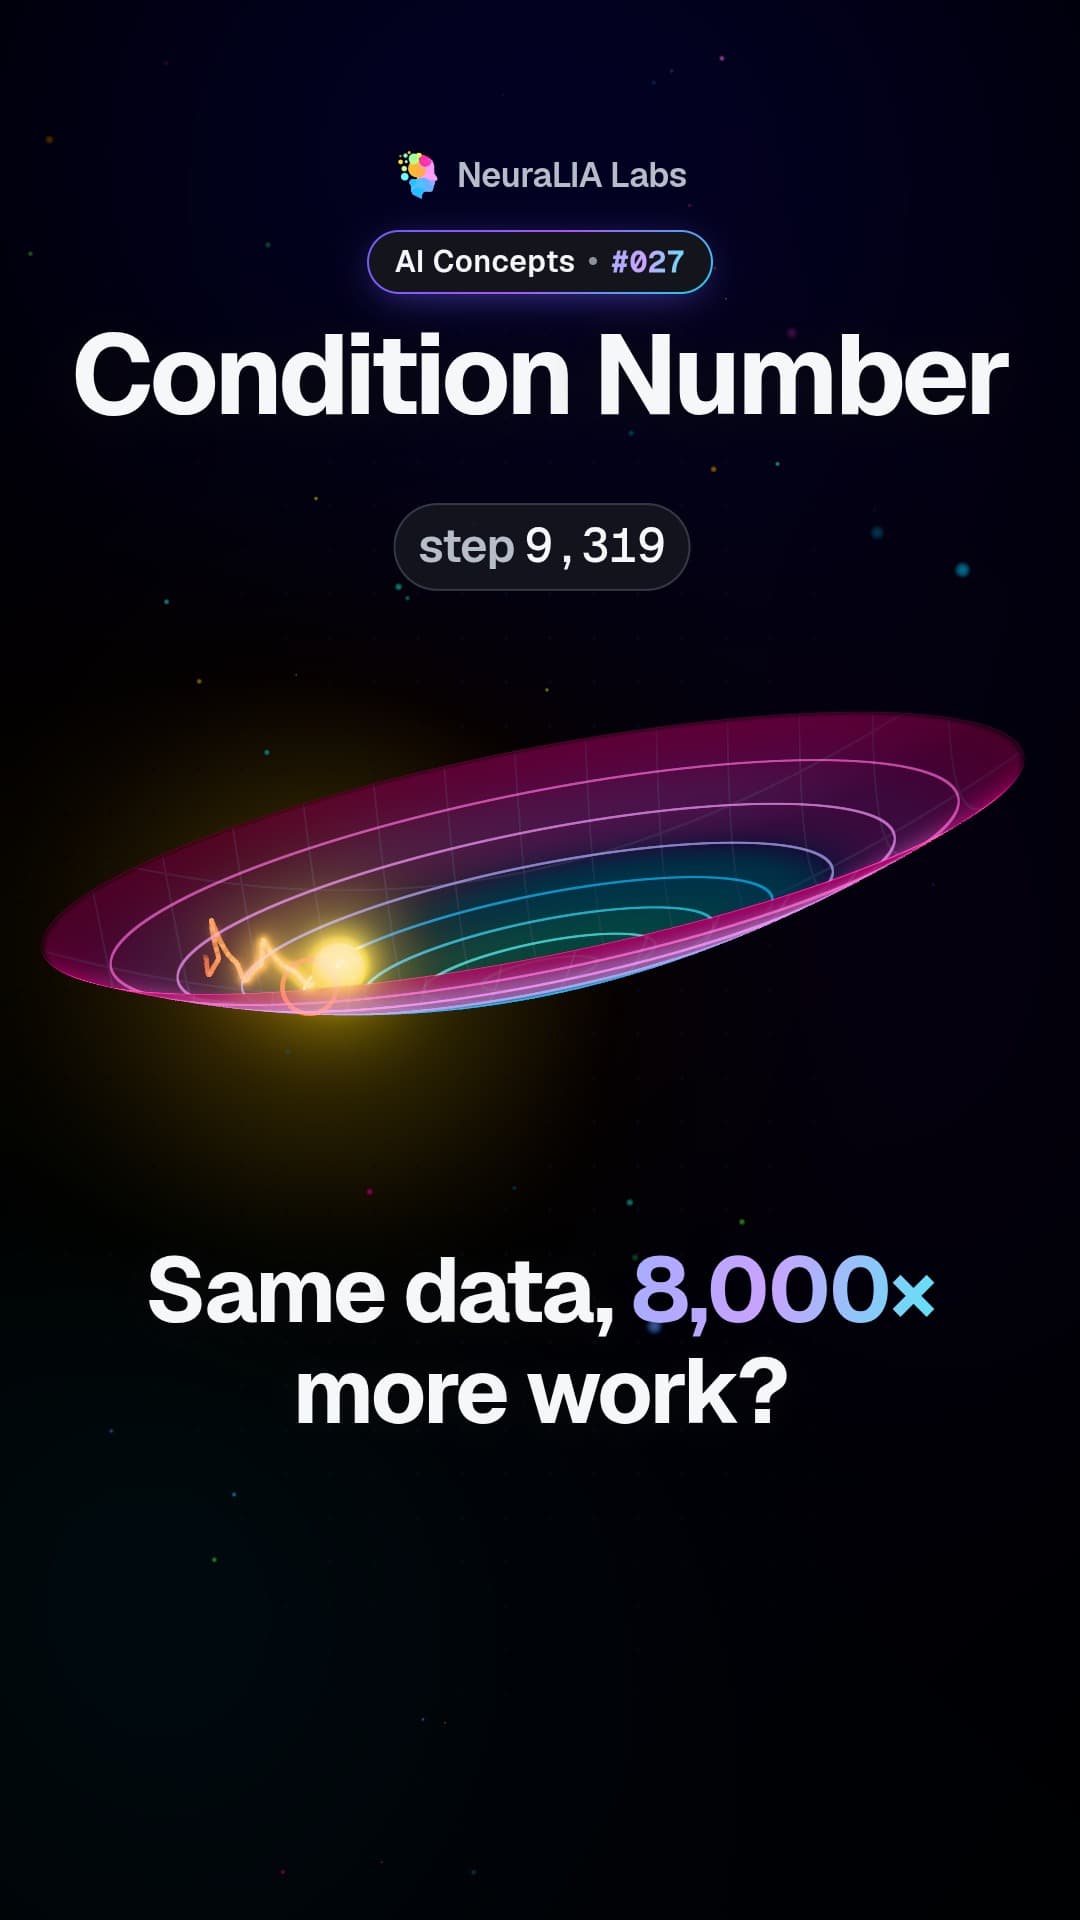 #027
Condition number: why a stretched valley makes AI training crawl
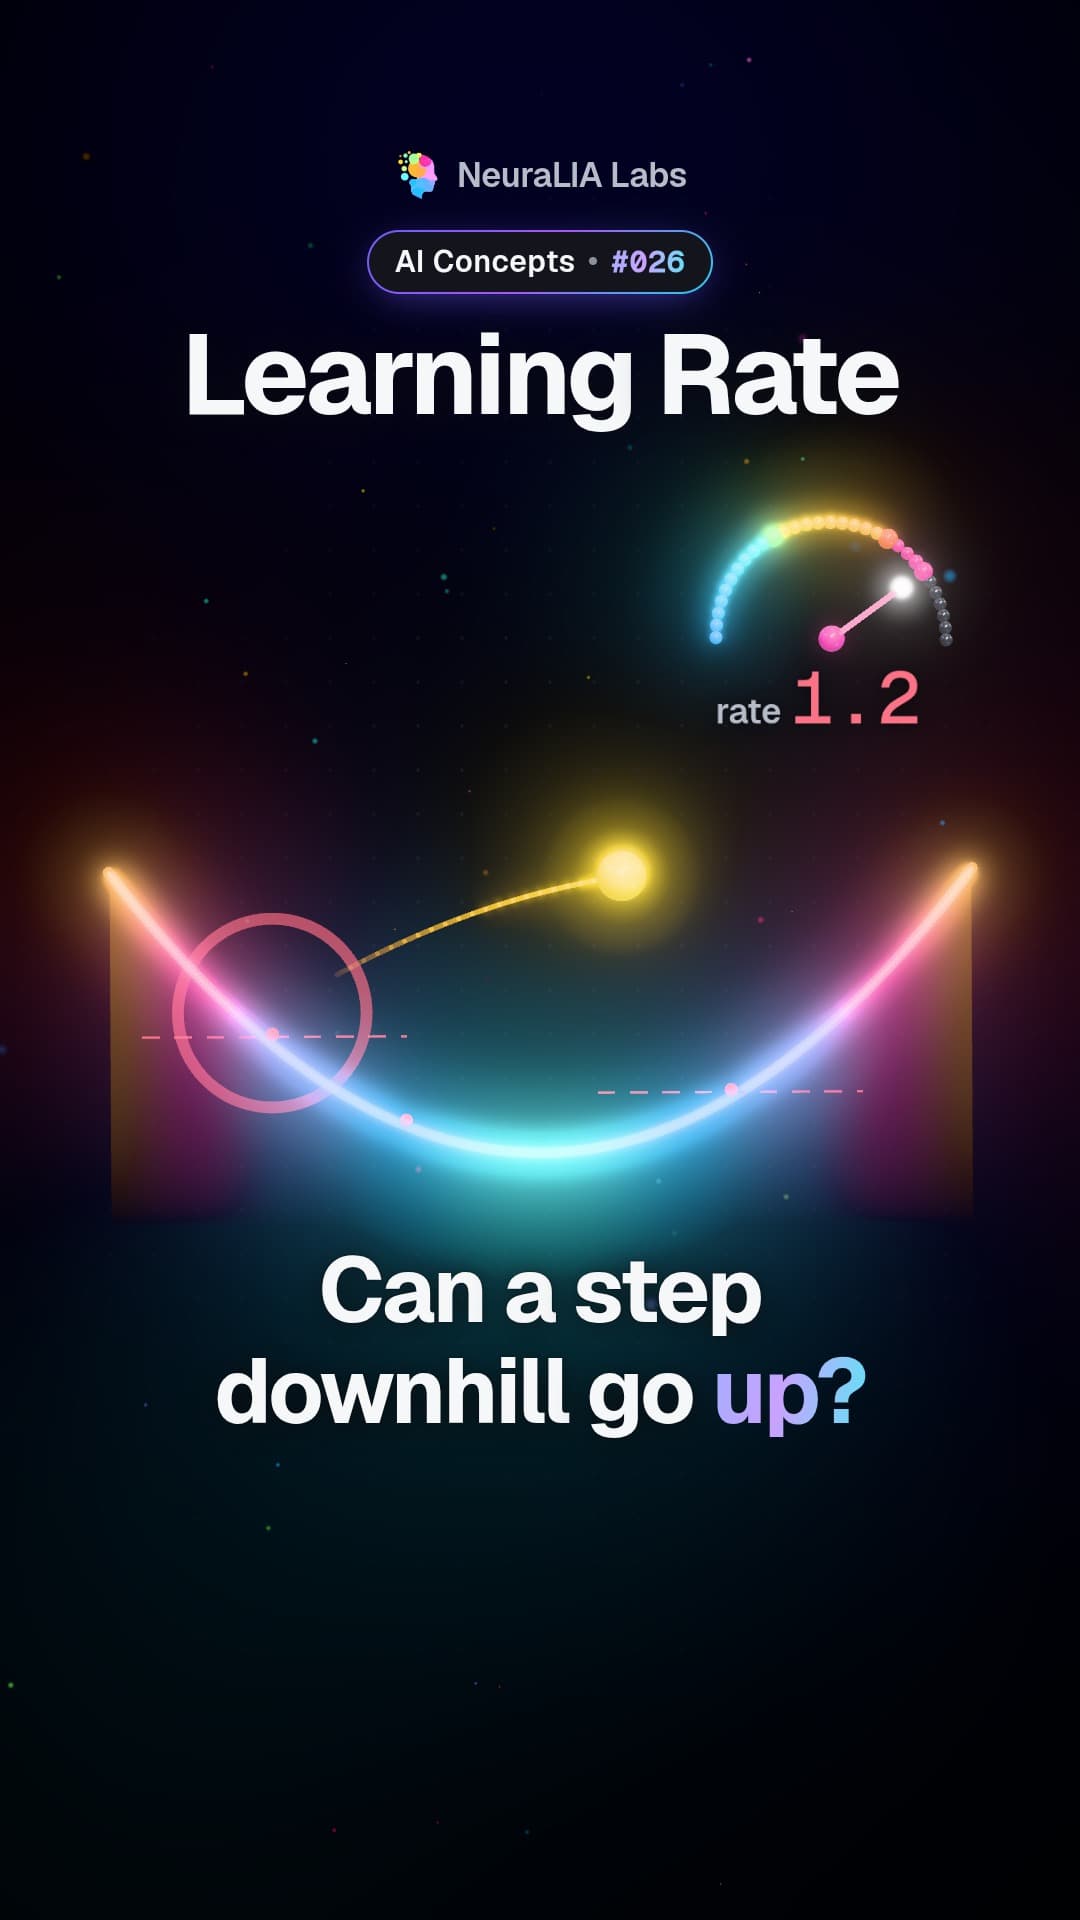 #026
Learning rate: the step size with a ceiling you can calculate
 #025
Gradient descent: how AI finds its way downhill in small steps
 #024
Gradient: the arrow that points uphill, and why AI walks the other way
 #023
Chain rule: how AI traces the effect of every layer
 #022
Derivative: how much the result moves when you nudge one input
 #021
Grid search: why you cannot train an AI by trying every setting
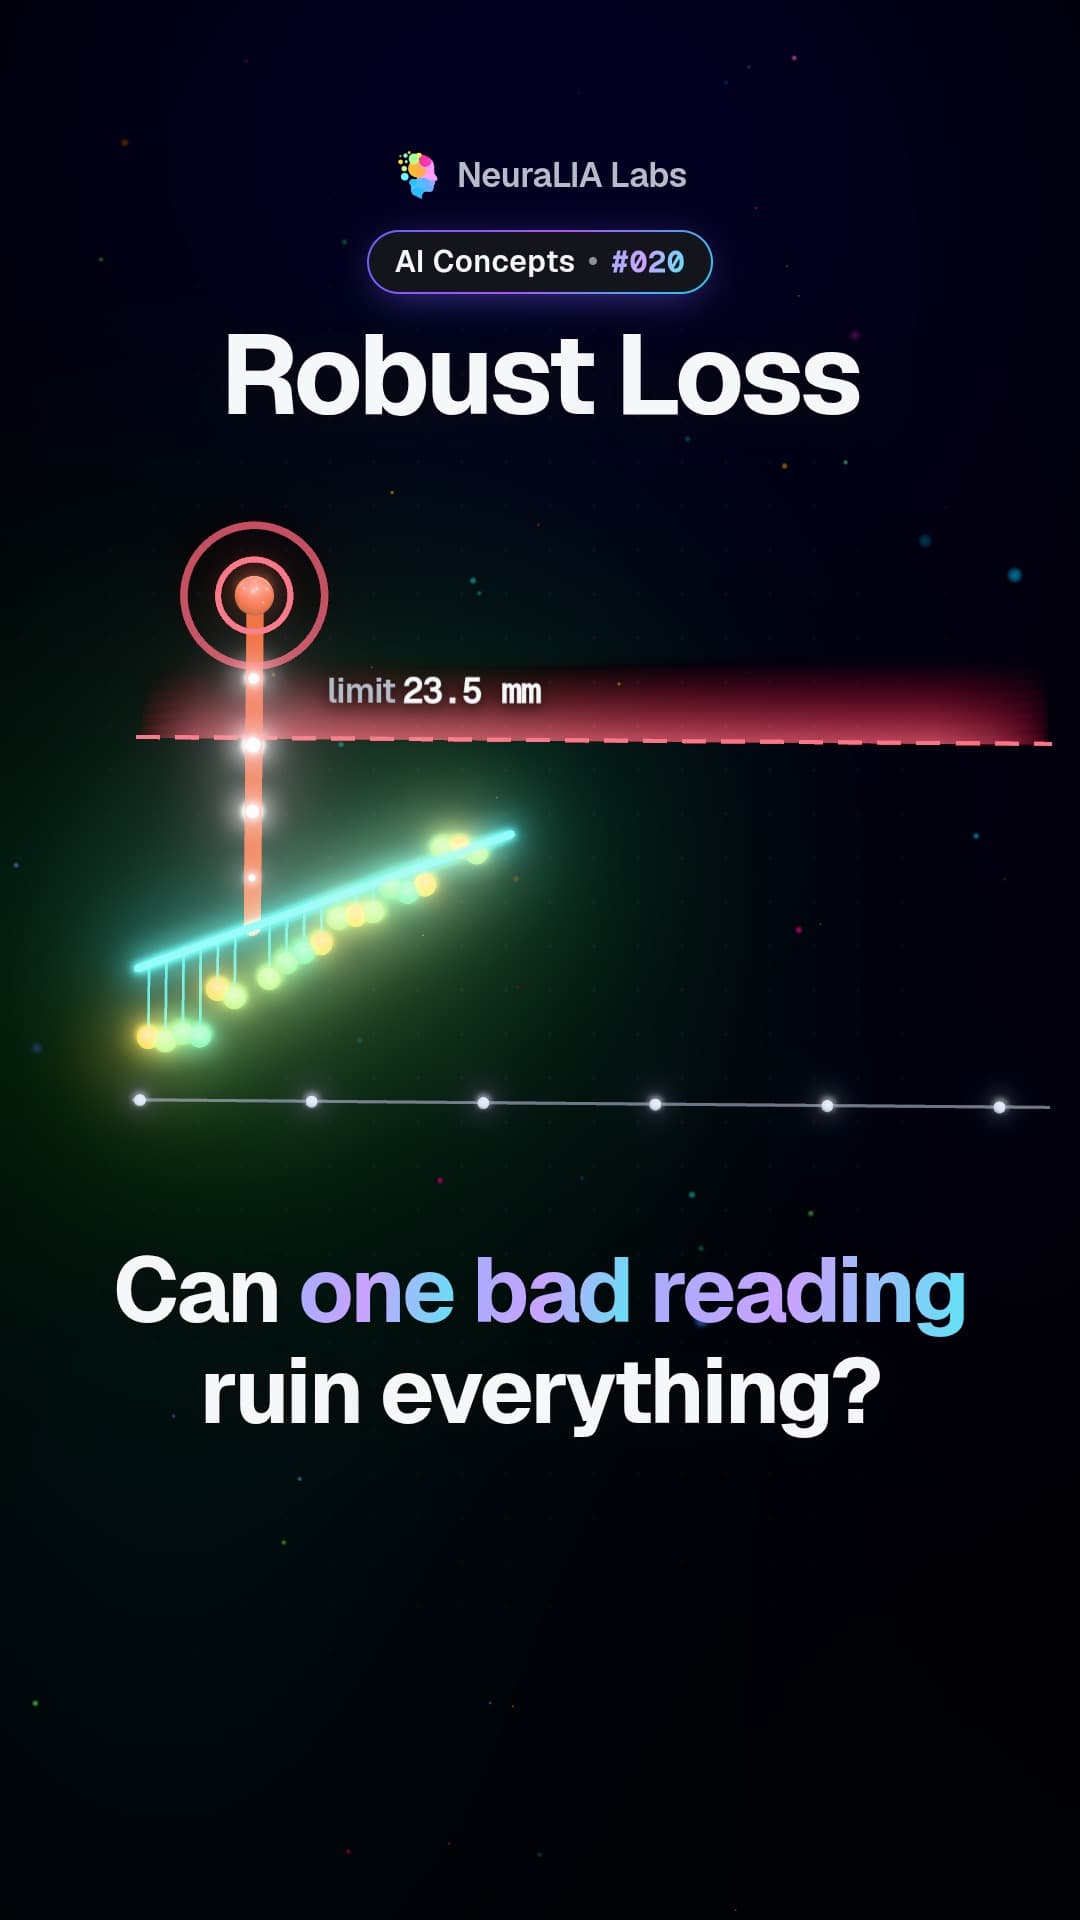 #020
Robust loss: stop one wild reading from wrecking your forecast
 #019
Heavy tails: when rare, huge errors break the usual average
 #018
Mean squared error: the hidden bet behind squaring your mistakes
 #017
The LogSumExp trick: one subtraction that stops AI math overflowing
 #016
Rounding error: why adding the same numbers can give two answers
 #015
Floating-point numbers: why your computer cannot hold every number
 #014
Negative log-likelihood: turning a fragile product into a calm sum
 #013
Maximum likelihood: the answer that makes your data least surprising
 #012
Bayes' rule: reasoning backwards from a clue to its most likely cause
 #011
Chain rule of probability: how AI scores a sentence word by word
 #010
Loss landscape: training an AI means finding the bottom of a valley
 #009
Loss function: the scoring rule that decides which answer wins
 #008
Feature engineering: the human choice that can beat the algorithm
कोर्स अध्याय के अनुसार
- 1Perceptron शुरुआत से: एक neuron क्या compute करता है10 वीडियो
- 2Loss Function कहाँ से आती है: Likelihood, Convention नहीं12 वीडियो
- 3ढलान की ओर: Gradient Descent और वे दो कदम जिन्हें सब छोड़ देते हैं12 वीडियो
- 4Classification, Cross-Entropy और खुद को धोखा देने से कैसे बचें
- 5Backpropagation शुरू से: पहले इंजन, फिर नेटवर्क1 वीडियो
- 6Train कराना, और Generalise कराना
- 7BPE Tokenizer बनाएं: आपका model R क्यों नहीं गिन पाता1 वीडियो
- 8Next-token prediction: embedding और perplexity का अर्थ1 वीडियो
- 9Average से निकला Attention और Transformer Block
- 10LLM की pretraining: डेटा, compute, scaling laws और लागत
- 11Base Model से Assistant तक: SFT, RLHF, DPO और GRPO
- 12Chain of Thought, RLVR और Test-Time Compute: माप के साथ
- 13Inference को सस्ता बनाना: KV cache, Batching और Quantization
- 14आपकी पहली Production LLM Call: Streaming, Retries, Timeouts
- 15Prompt Engineering, मापकर: आउटपुट को क्या बदलता है
- 16Context Window, Tokens और बिल: माप के साथ
- 17Temperature, top-p और वह determinism जो आपके पास नहीं है
- 18Tool Calling और Structured Outputs: वह अनुबंध जो टिकता है
- 19Production में RAG: chunking, retrieval और ईमानदार citations
- 20Fine-tune, retrieve या prompt? फैसला आर्थिक है
- 21Multimodal Pricing: Images, Audio और Video में असल बिल किसका आता है
- 22AI agent क्या है: पाँच क्लासिक प्रकार, दो प्रतिस्पर्धी परिभाषाएँ
- 23Agent Harness बनाएँ: Loop और उससे बाहर निकलने के पाँच रास्ते
- 24Context Engineering: आपका agent turn 40 पर धीमा क्यों पड़ जाता है
- 25Multi-Agent समन्वयन: पाँच पैटर्न, और कब एक ही जीतता है
- 26Spec के हिसाब से MCP: Server असल में क्या होता है
- 27MCP Server शिप करें: TypeScript और Python, माप के साथ
- 28Agent Skills और SKILL.md: प्रगतिशील खुलासा, मापा हुआ
- 29LLM मूल्यांकन: public benchmarks से अपने golden set तक
- 30Prompt Injection और घातक Trifecta: असली Agent को सुरक्षित करना