
 #01
Videoer
AI forklaret i korte videoer
Én idé pr. video, på klart sprog. Hver video linker til kapitlet i vores gratis kursus, der forklarer det trin for trin.
Start her AI 101
- #01
 #02
Machine learning: how a computer draws its own dividing line
 #03
Neural networks: layers of tiny calculators passing signals on
 #04
How AI learns: guess, measure the error, nudge, repeat
 #05
Tokens: how AI chops your words into numbered pieces
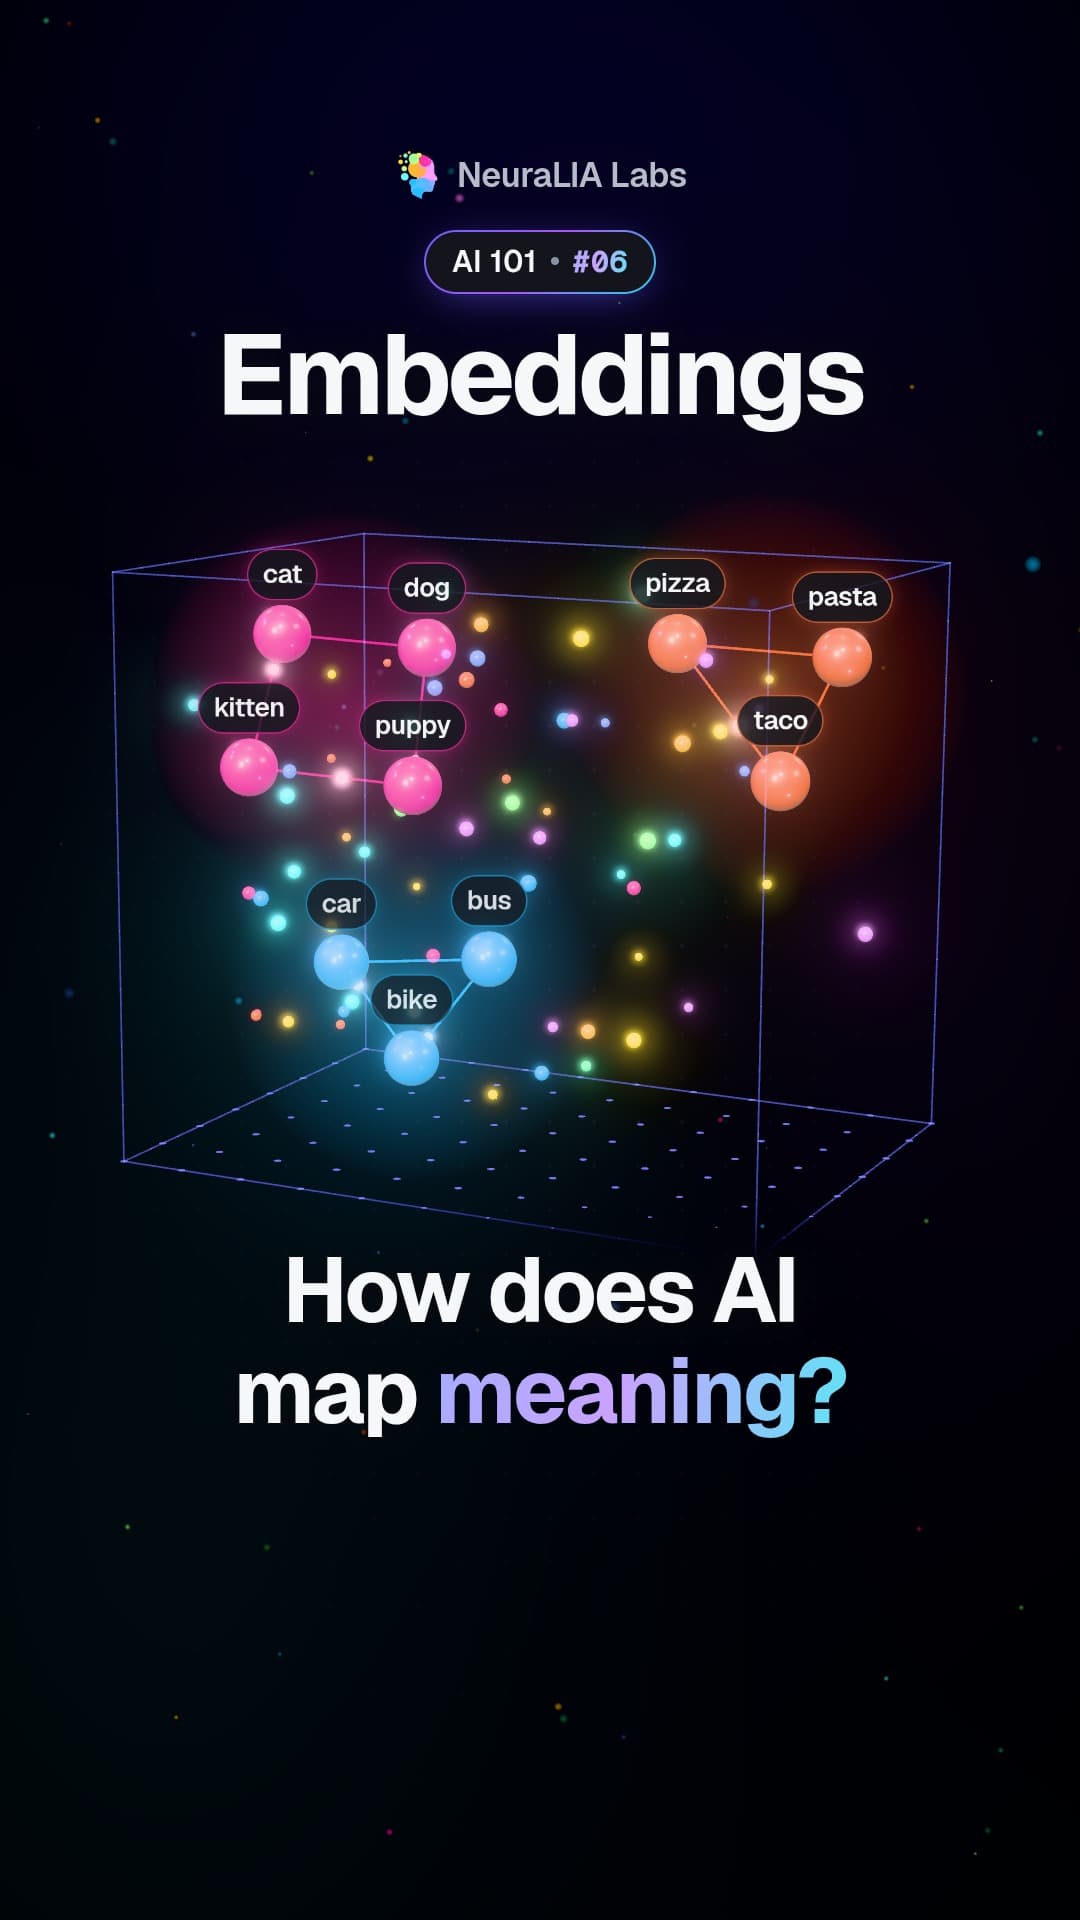 #06
Embeddings: why a puppy lands closer to a dog than to a pizza
Nyeste
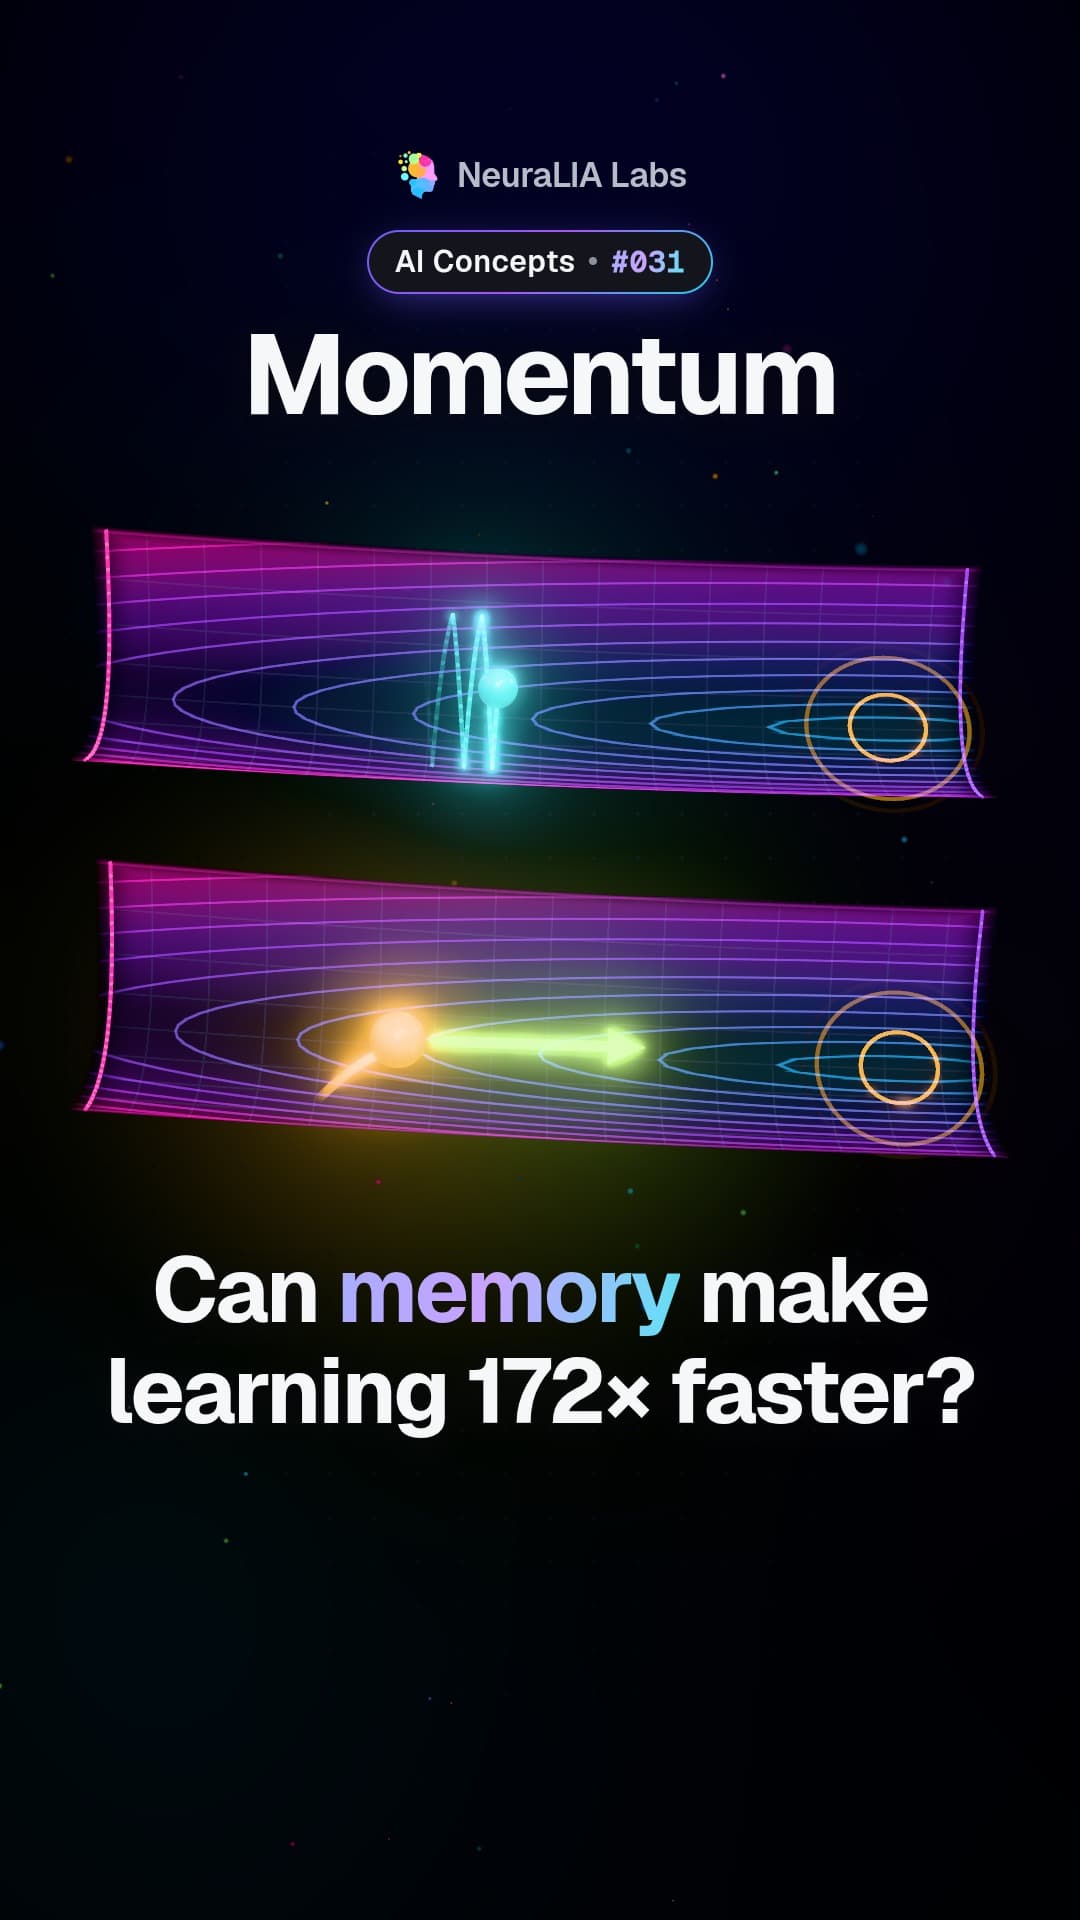 #031
Momentum: how remembering past steps stops AI training zigzagging
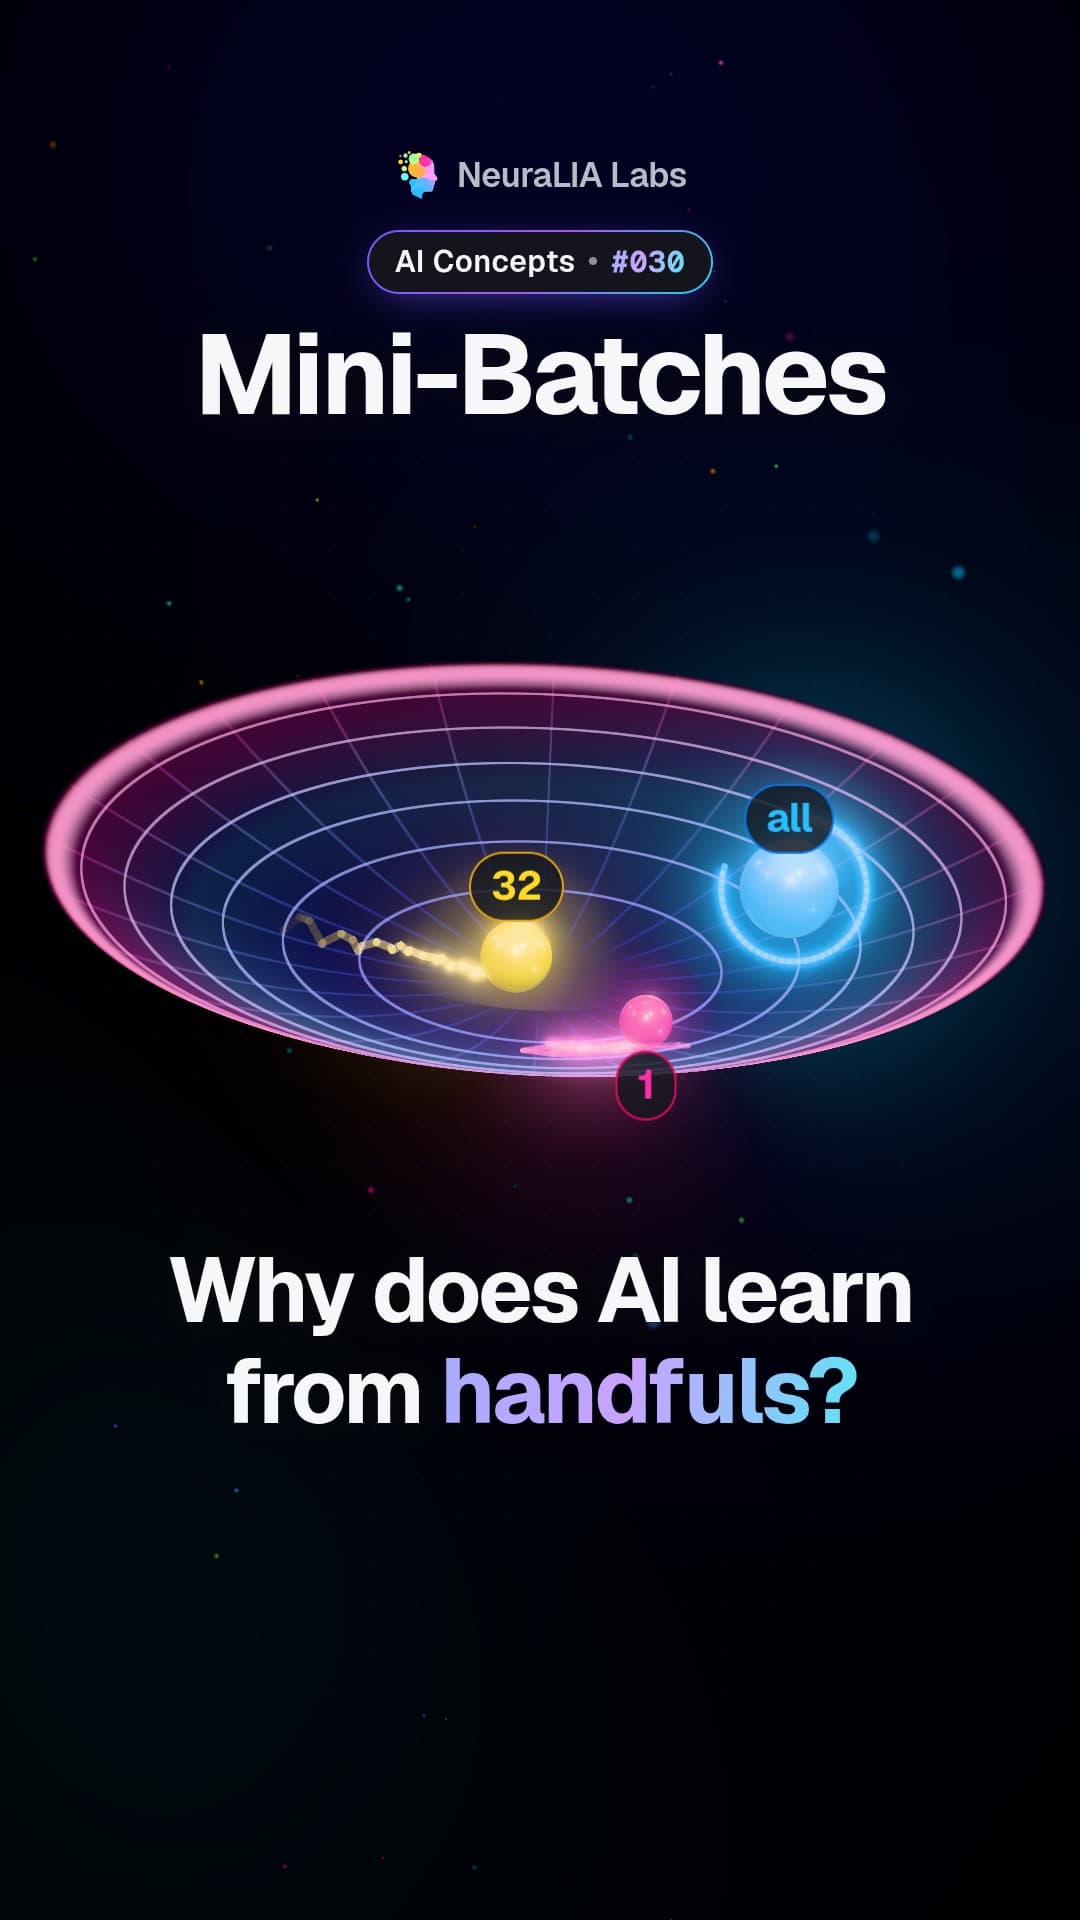 #030
Mini-batches: why AI learns faster from a random handful of data
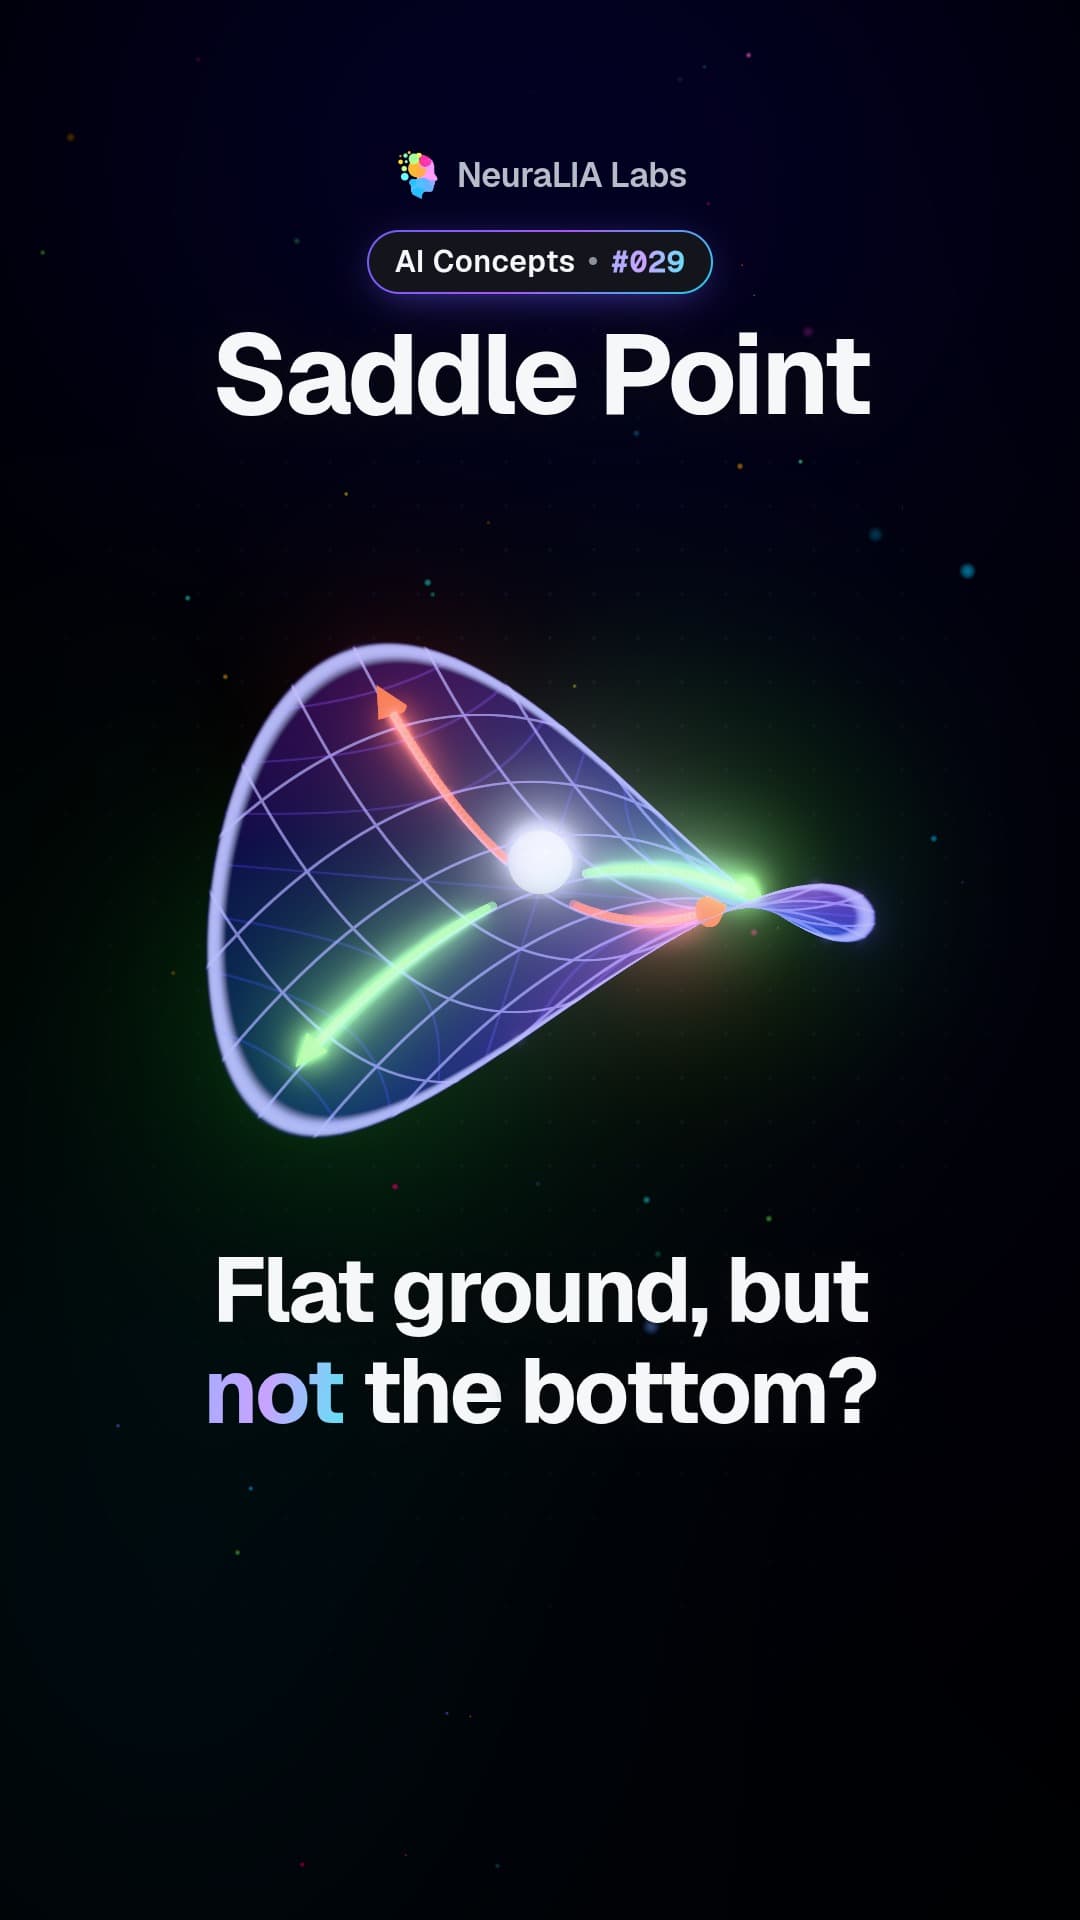 #029
Saddle points: where AI training looks stuck but has a way down
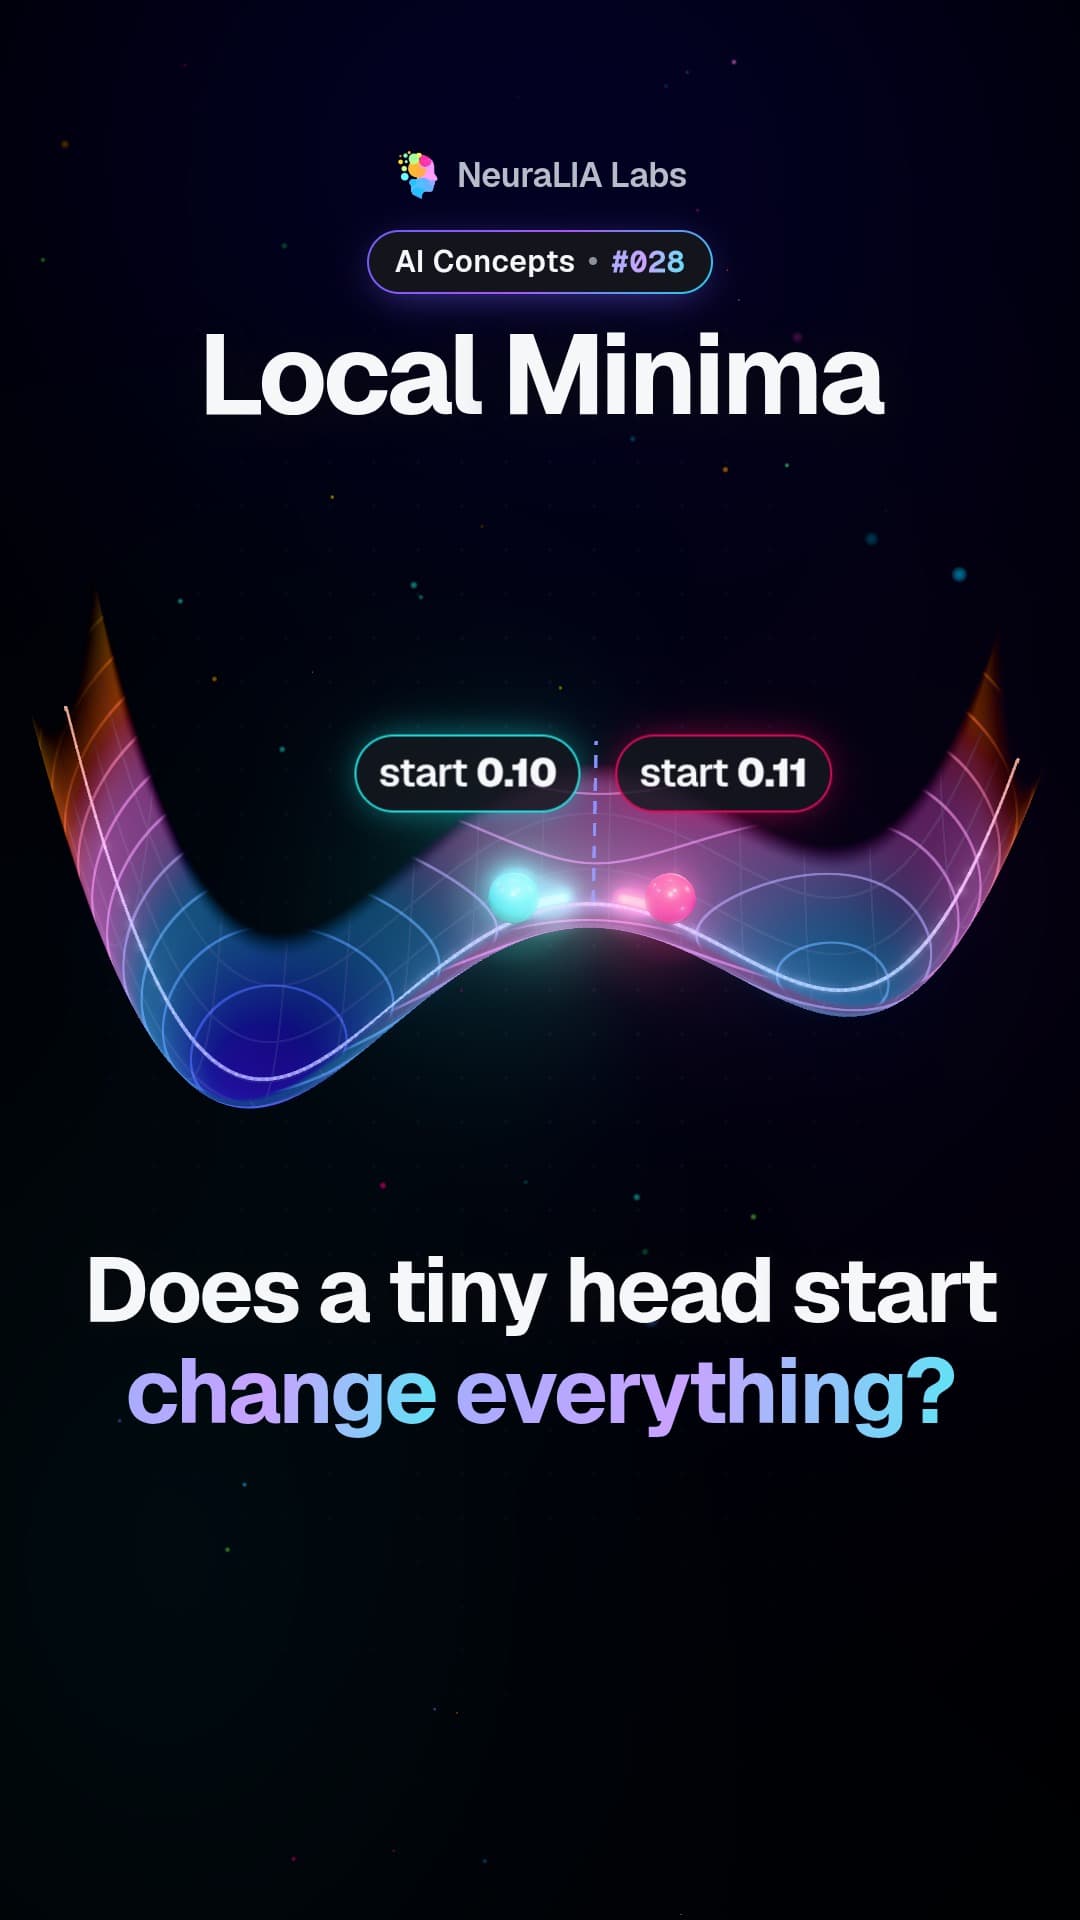 #028
Local minima: why AI training can settle for second best
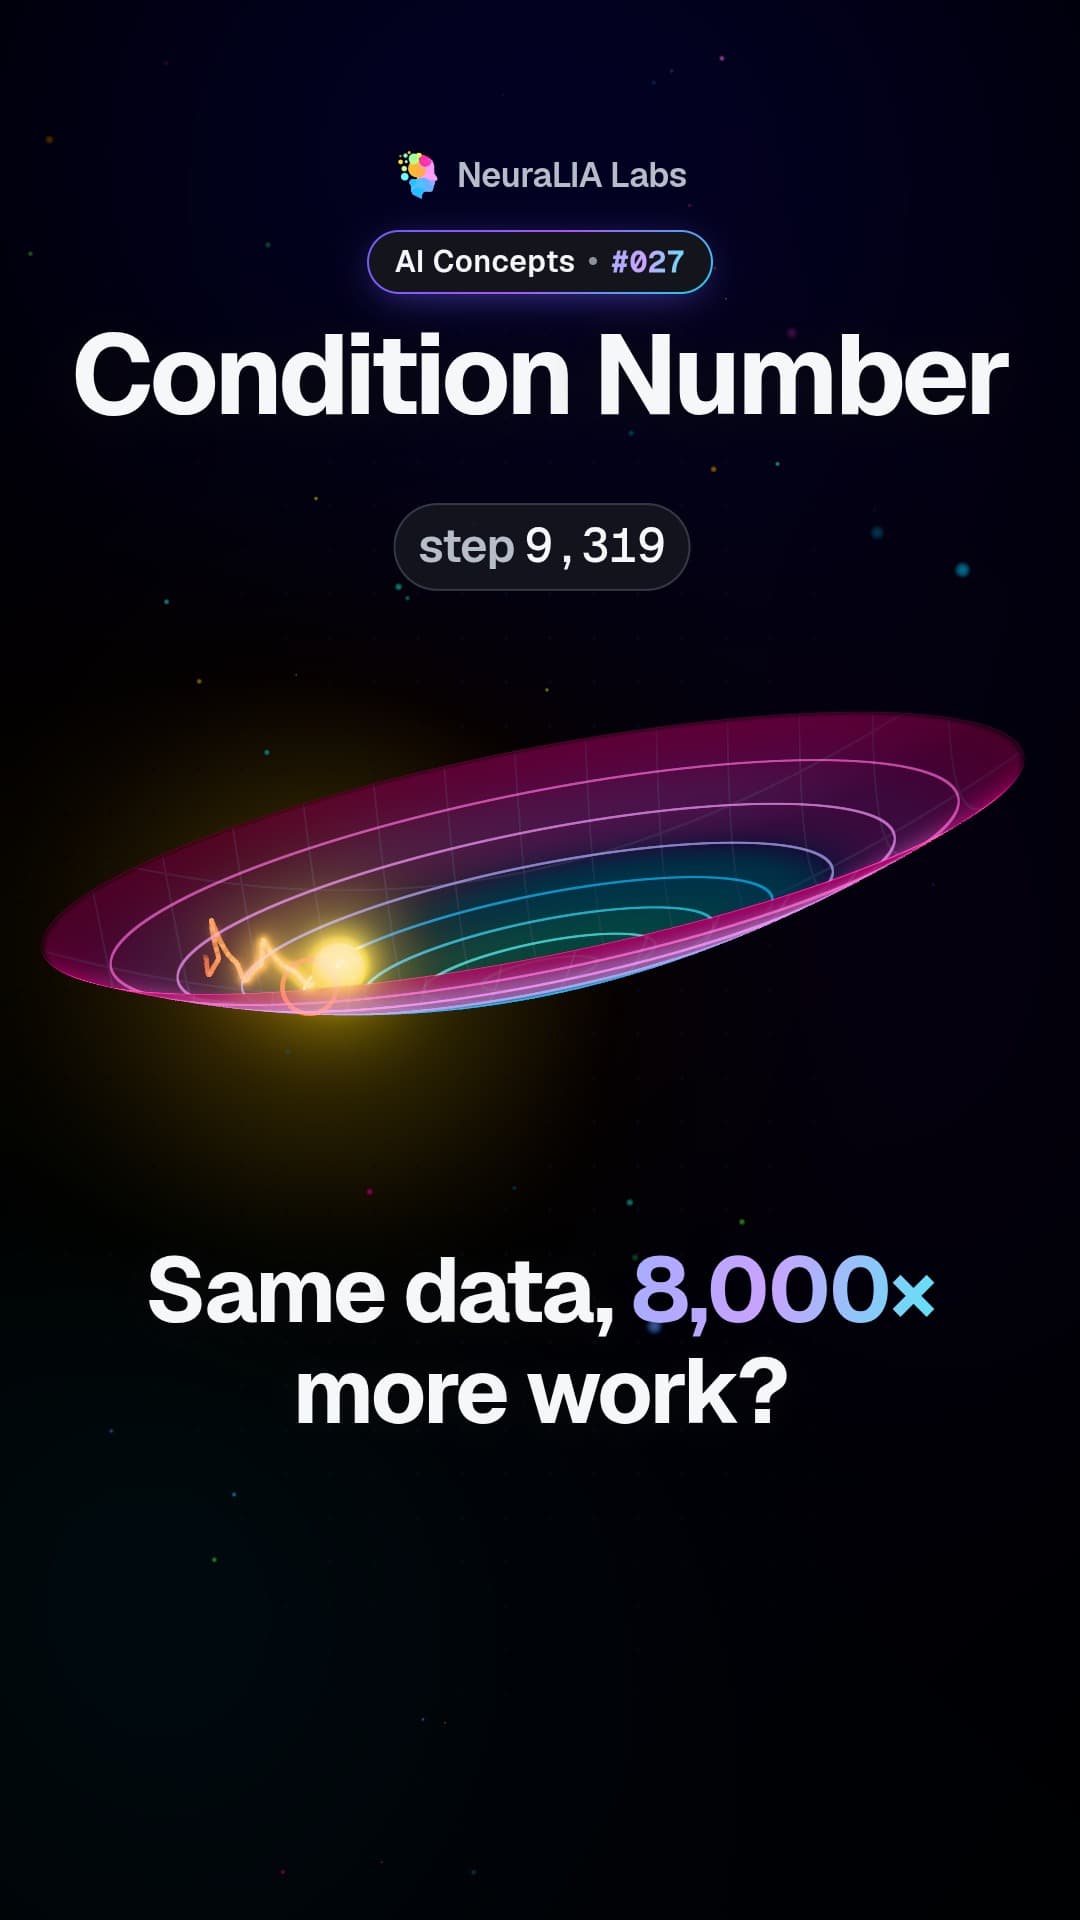 #027
Condition number: why a stretched valley makes AI training crawl
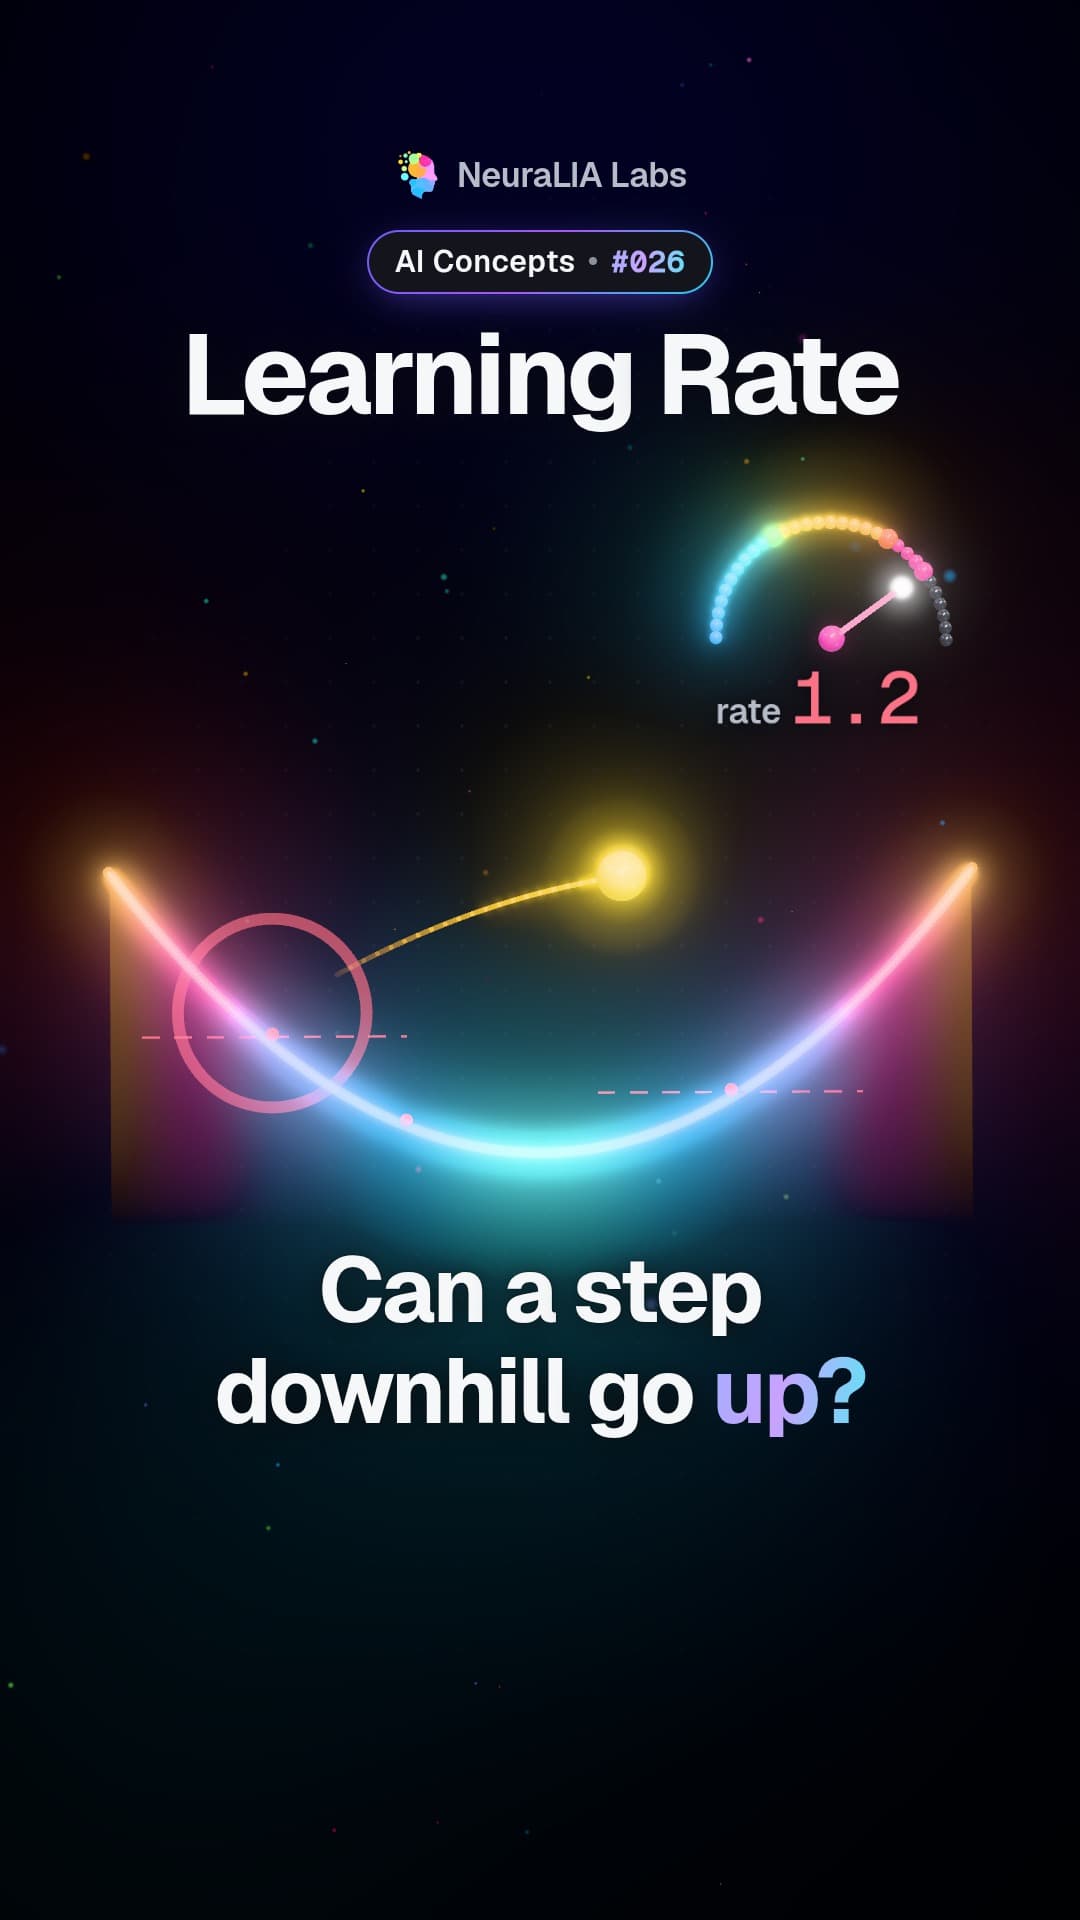 #026
Learning rate: the step size with a ceiling you can calculate
 #025
Gradient descent: how AI finds its way downhill in small steps
 #024
Gradient: the arrow that points uphill, and why AI walks the other way
 #023
Chain rule: how AI traces the effect of every layer
 #022
Derivative: how much the result moves when you nudge one input
 #021
Grid search: why you cannot train an AI by trying every setting
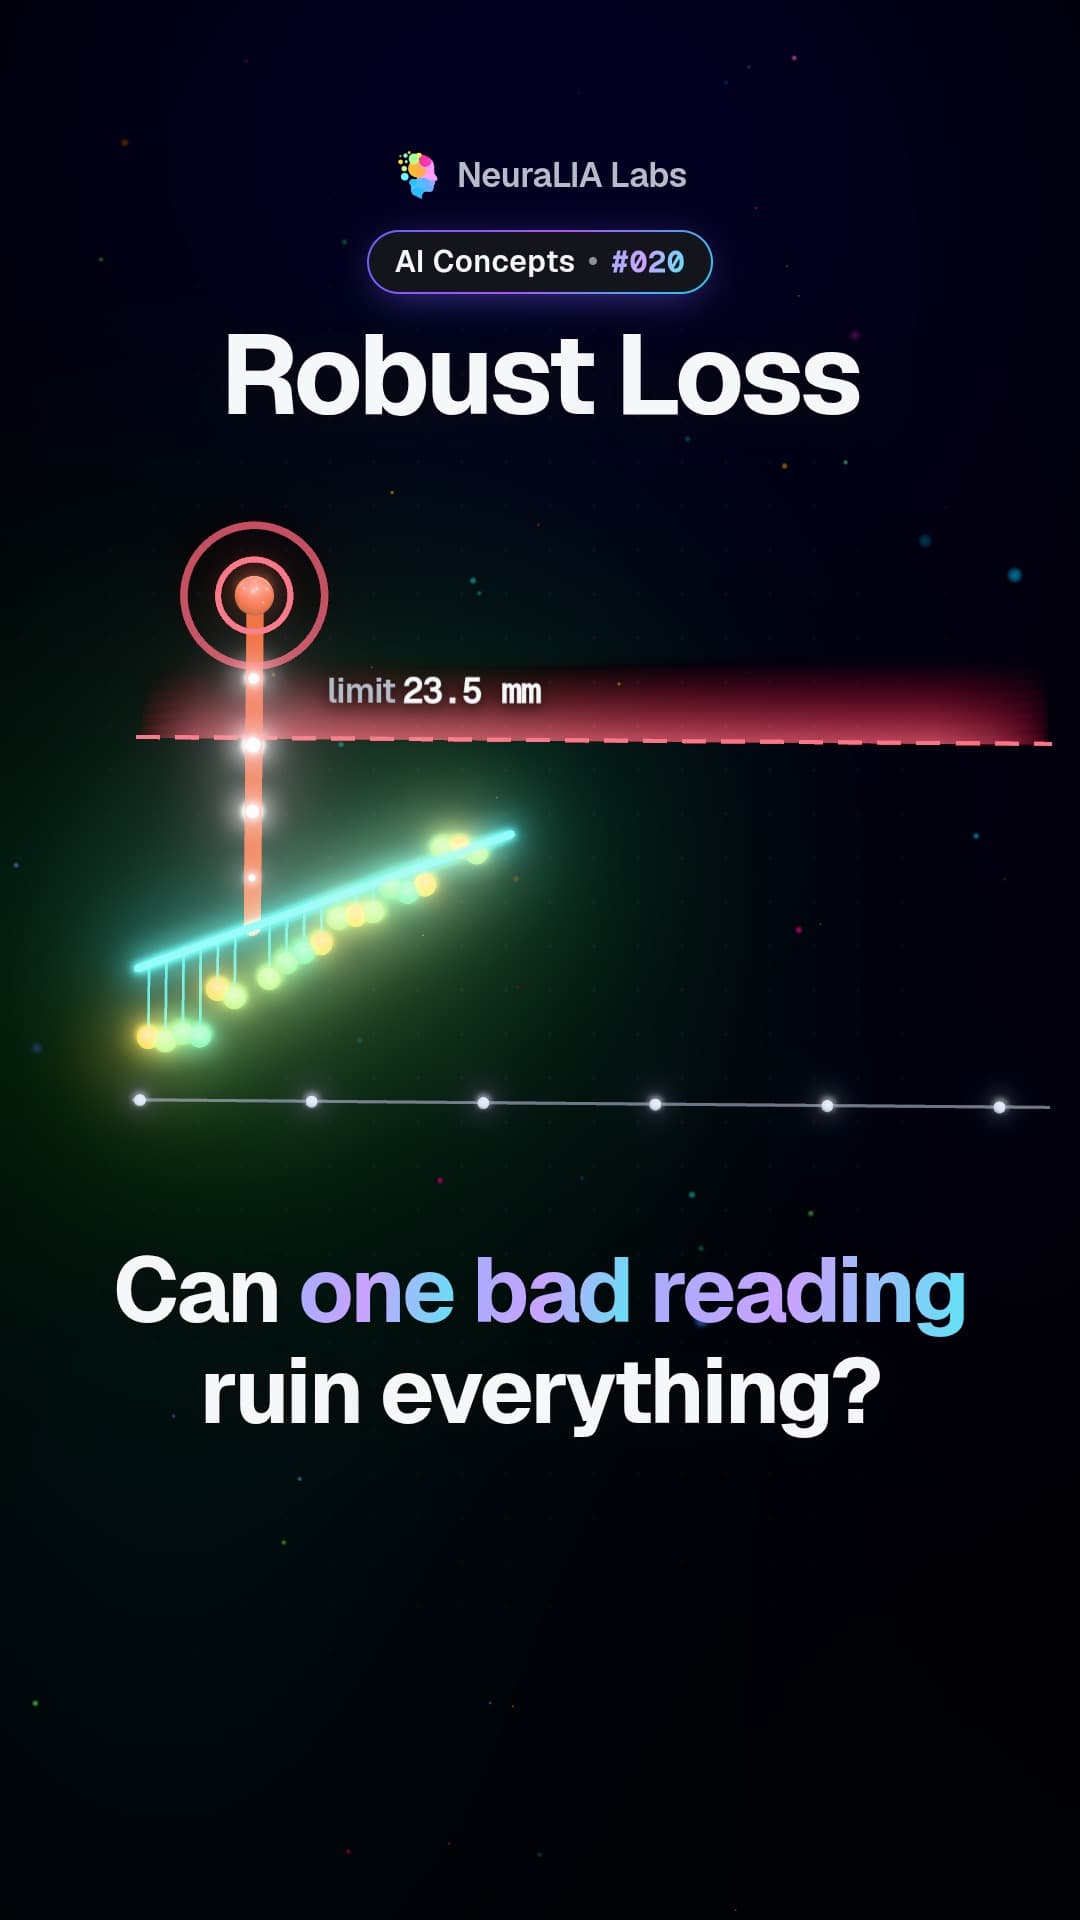 #020
Robust loss: stop one wild reading from wrecking your forecast
 #019
Heavy tails: when rare, huge errors break the usual average
 #018
Mean squared error: the hidden bet behind squaring your mistakes
 #017
The LogSumExp trick: one subtraction that stops AI math overflowing
 #016
Rounding error: why adding the same numbers can give two answers
 #015
Floating-point numbers: why your computer cannot hold every number
 #014
Negative log-likelihood: turning a fragile product into a calm sum
 #013
Maximum likelihood: the answer that makes your data least surprising
 #012
Bayes' rule: reasoning backwards from a clue to its most likely cause
 #011
Chain rule of probability: how AI scores a sentence word by word
 #010
Loss landscape: training an AI means finding the bottom of a valley
 #009
Loss function: the scoring rule that decides which answer wins
 #008
Feature engineering: the human choice that can beat the algorithm
Efter kursuskapitel
- 1Perceptronen fra bunden: Hvad en neuron beregner10 videoer
- 2Hvor en tabsfunktion kommer fra: likelihood, ikke konvention12 videoer
- 3Nedad: gradient descent og de to trin alle springer over12 videoer
- 4Klassifikation, krydsentropi og kunsten ikke at narre dig selv
- 5Backpropagation fra bunden: først motoren, så netværket1 video
- 6At få det til at træne — og til at generalisere
- 7Byg en BPE-tokenizer: Derfor kan din model ikke tælle r'erne1 video
- 8Next-token prediction: Embeddings, og hvad perplexity betyder1 video
- 9Attention og transformer-blokken, udledt fra et gennemsnit
- 10Pretraining af en LLM: data, compute, scaling laws og pris
- 11Fra base model til assistant: SFT, RLHF, DPO og GRPO
- 12Chain of Thought, RLVR og Test-Time Compute målt
- 13Gør inference billig: KV cache, batching og kvantisering
- 14Dit første produktionskald til en LLM: streaming, retries og timeouts
- 15Prompt engineering, målt: Hvad der ændrer outputtet
- 16Context window, tokens og regningen — målt
- 17Temperatur, top-p og den determinisme, du ikke har
- 18Tool Calling og strukturerede outputs: Kontrakten der holder
- 19RAG i produktion: Chunking, retrieval og ærlige kildehenvisninger
- 20Fine-tune, retrieve eller prompt? Beslutningen er økonomisk
- 21Multimodal prissætning: Hvad billeder, lyd og video egentlig fakturerer
- 22Hvad en AI-agent er: fem klassiske typer, to rivaliserende definitioner
- 23Byg et agent harness: loopet og dets fem veje ud
- 24Context Engineering: Derfor bliver din agent dummere ved tur 40
- 25Multi-Agent-orkestrering: Fem mønstre, og hvornår ét vinder
- 26MCP forklaret op mod specifikationen: hvad en server egentlig er
- 27Ship en MCP-server: TypeScript og Python, målt
- 28Agent Skills og SKILL.md: gradvis disclosure, målt
- 29LLM-evaluering: Fra offentlige benchmarks til dit golden set
- 30Prompt injection og den dødelige trifecta: sådan sikrer du en reel agent