
 #01
Video
L'AI spiegata in brevi video
Un'idea per video, spiegata in modo semplice. Ogni video rimanda al capitolo del nostro corso gratuito che la spiega passo dopo passo.
Inizia da qui AI 101
- #01
 #02
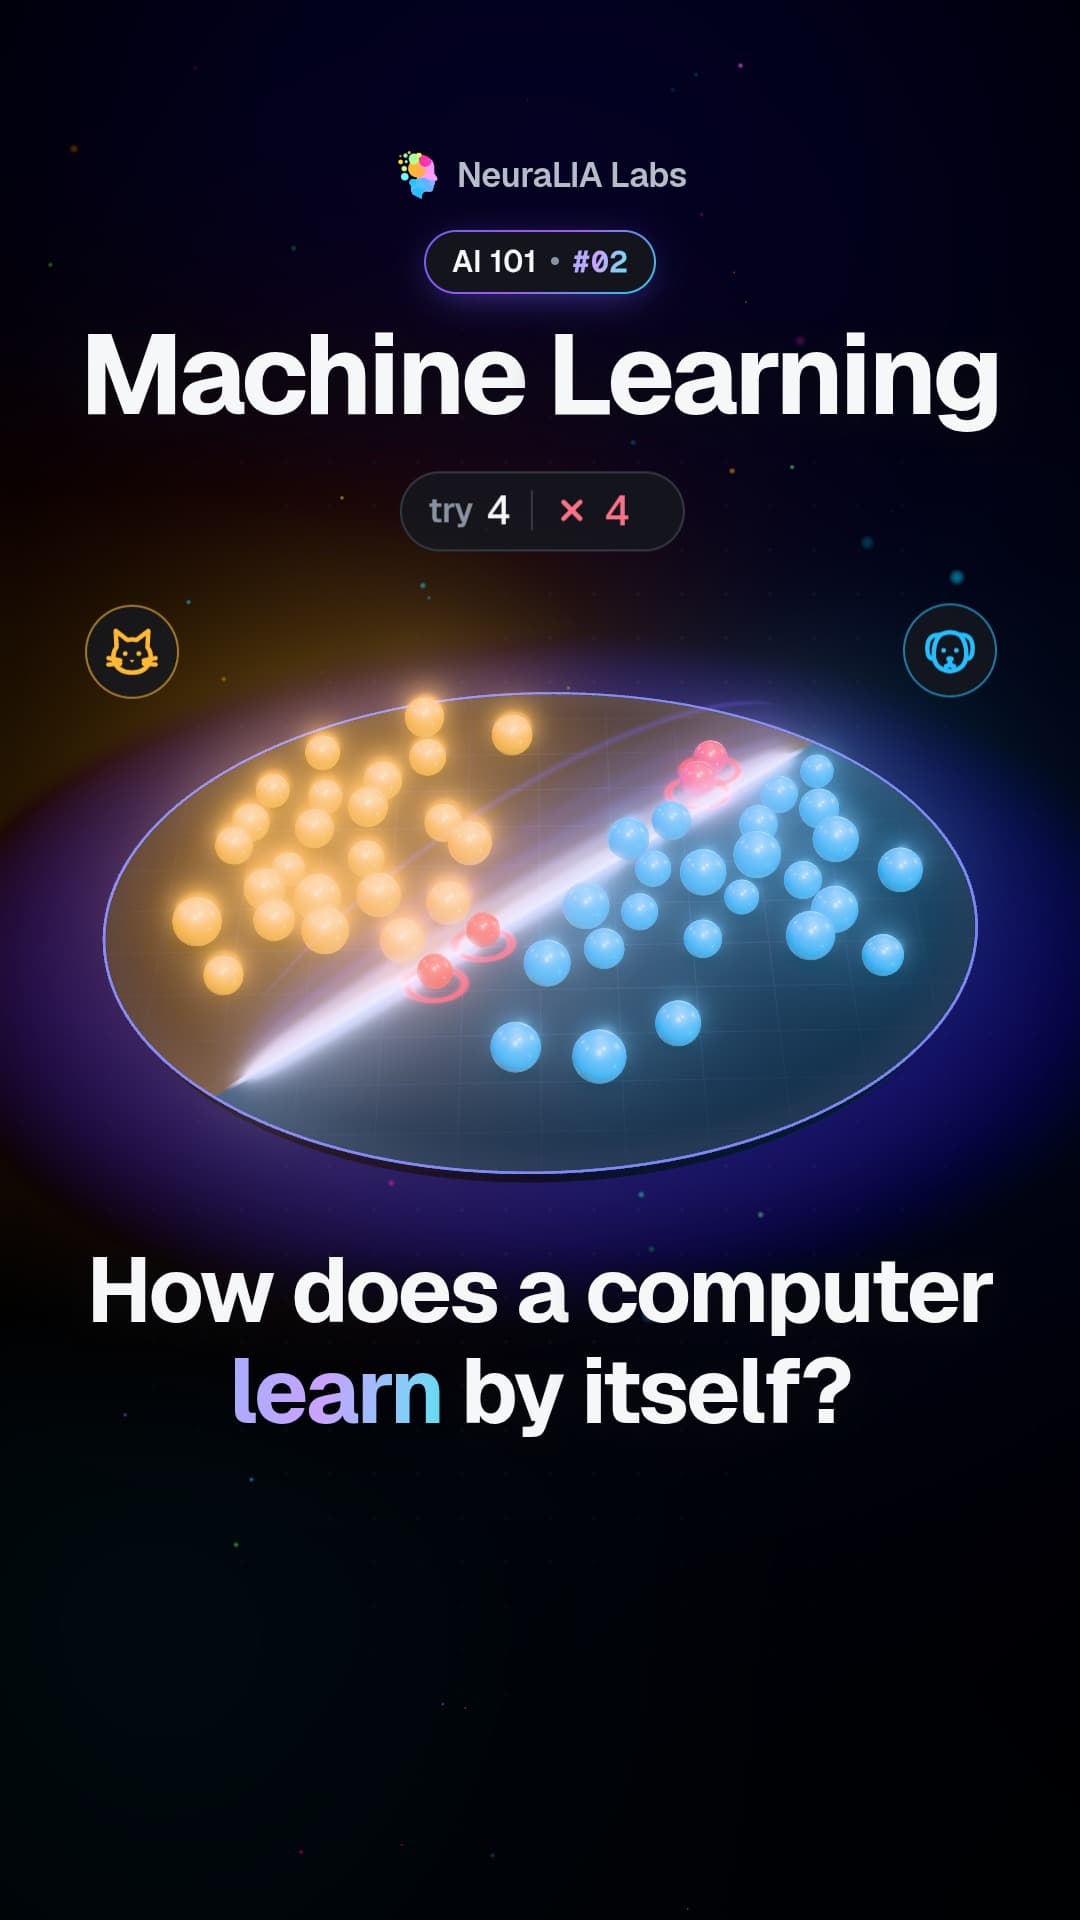
Machine learning: how a computer draws its own dividing line
 #03
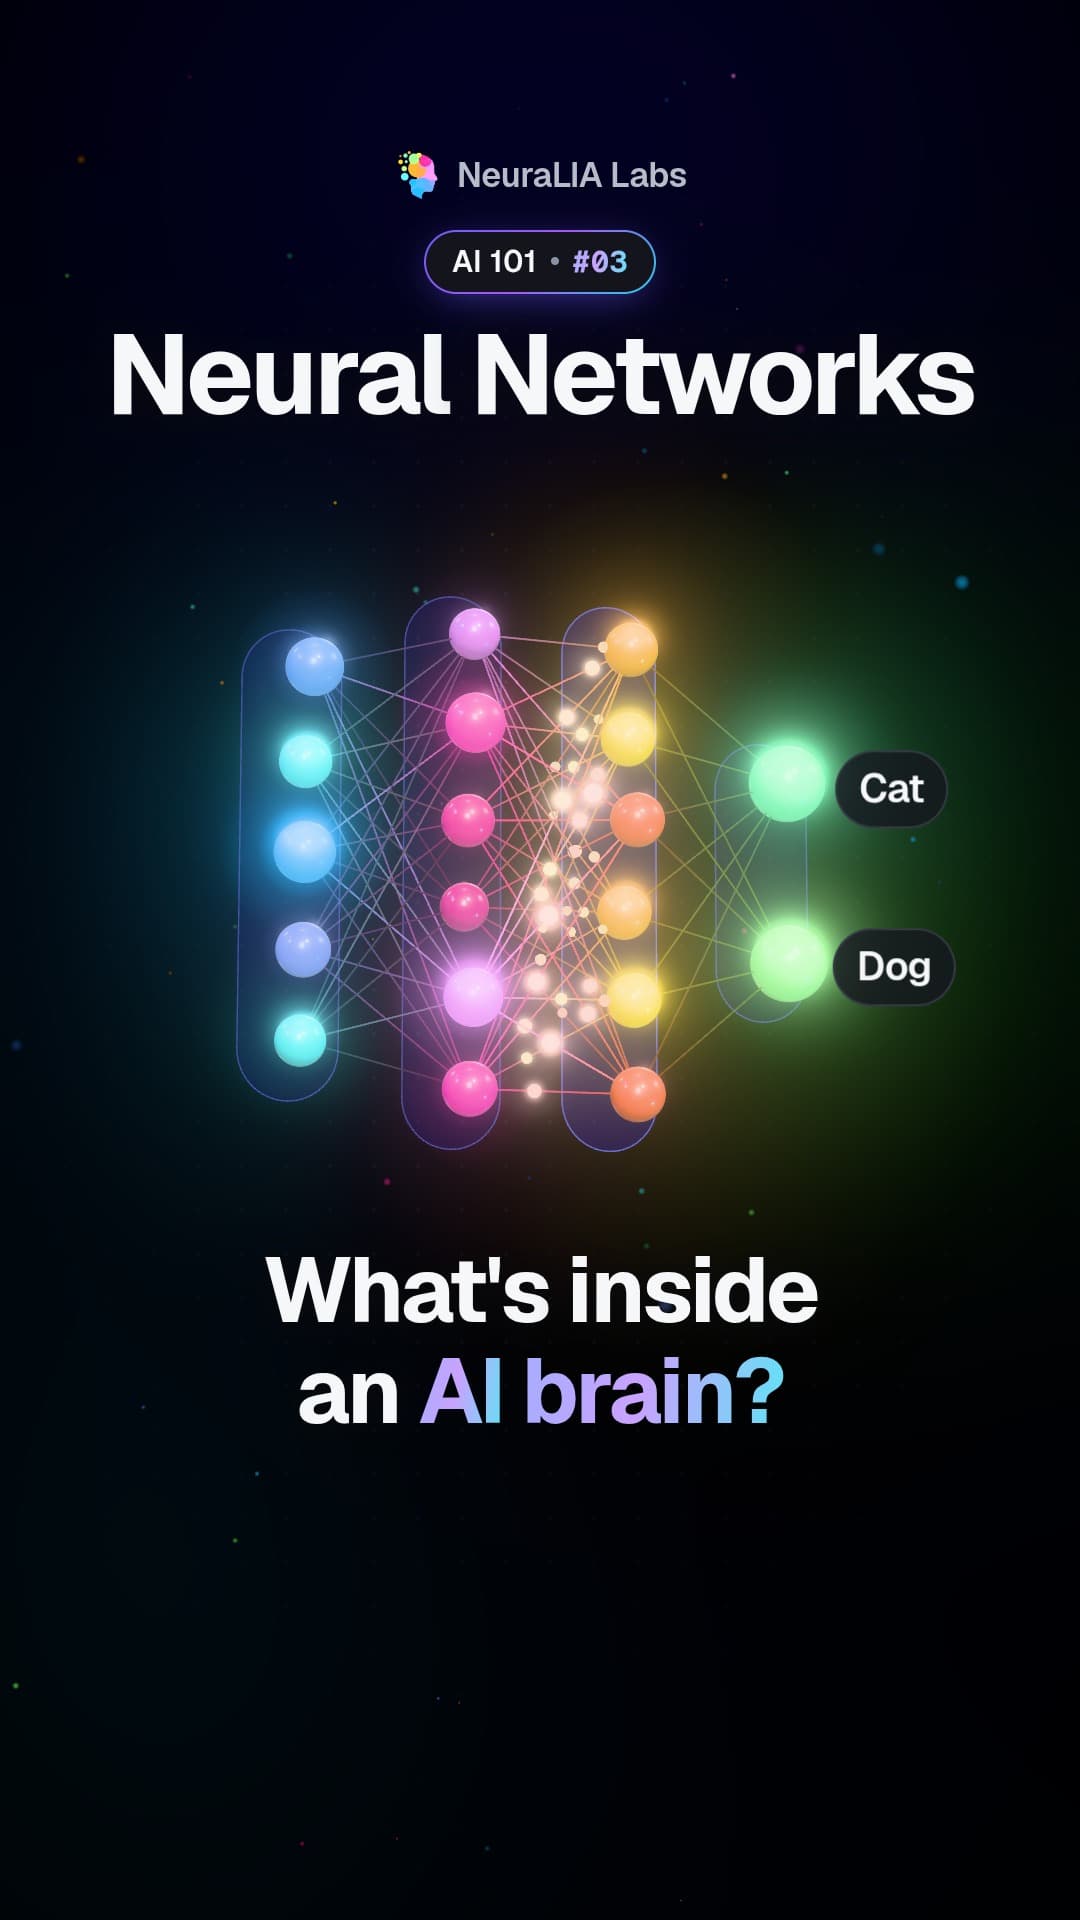
Neural networks: layers of tiny calculators passing signals on
 #04
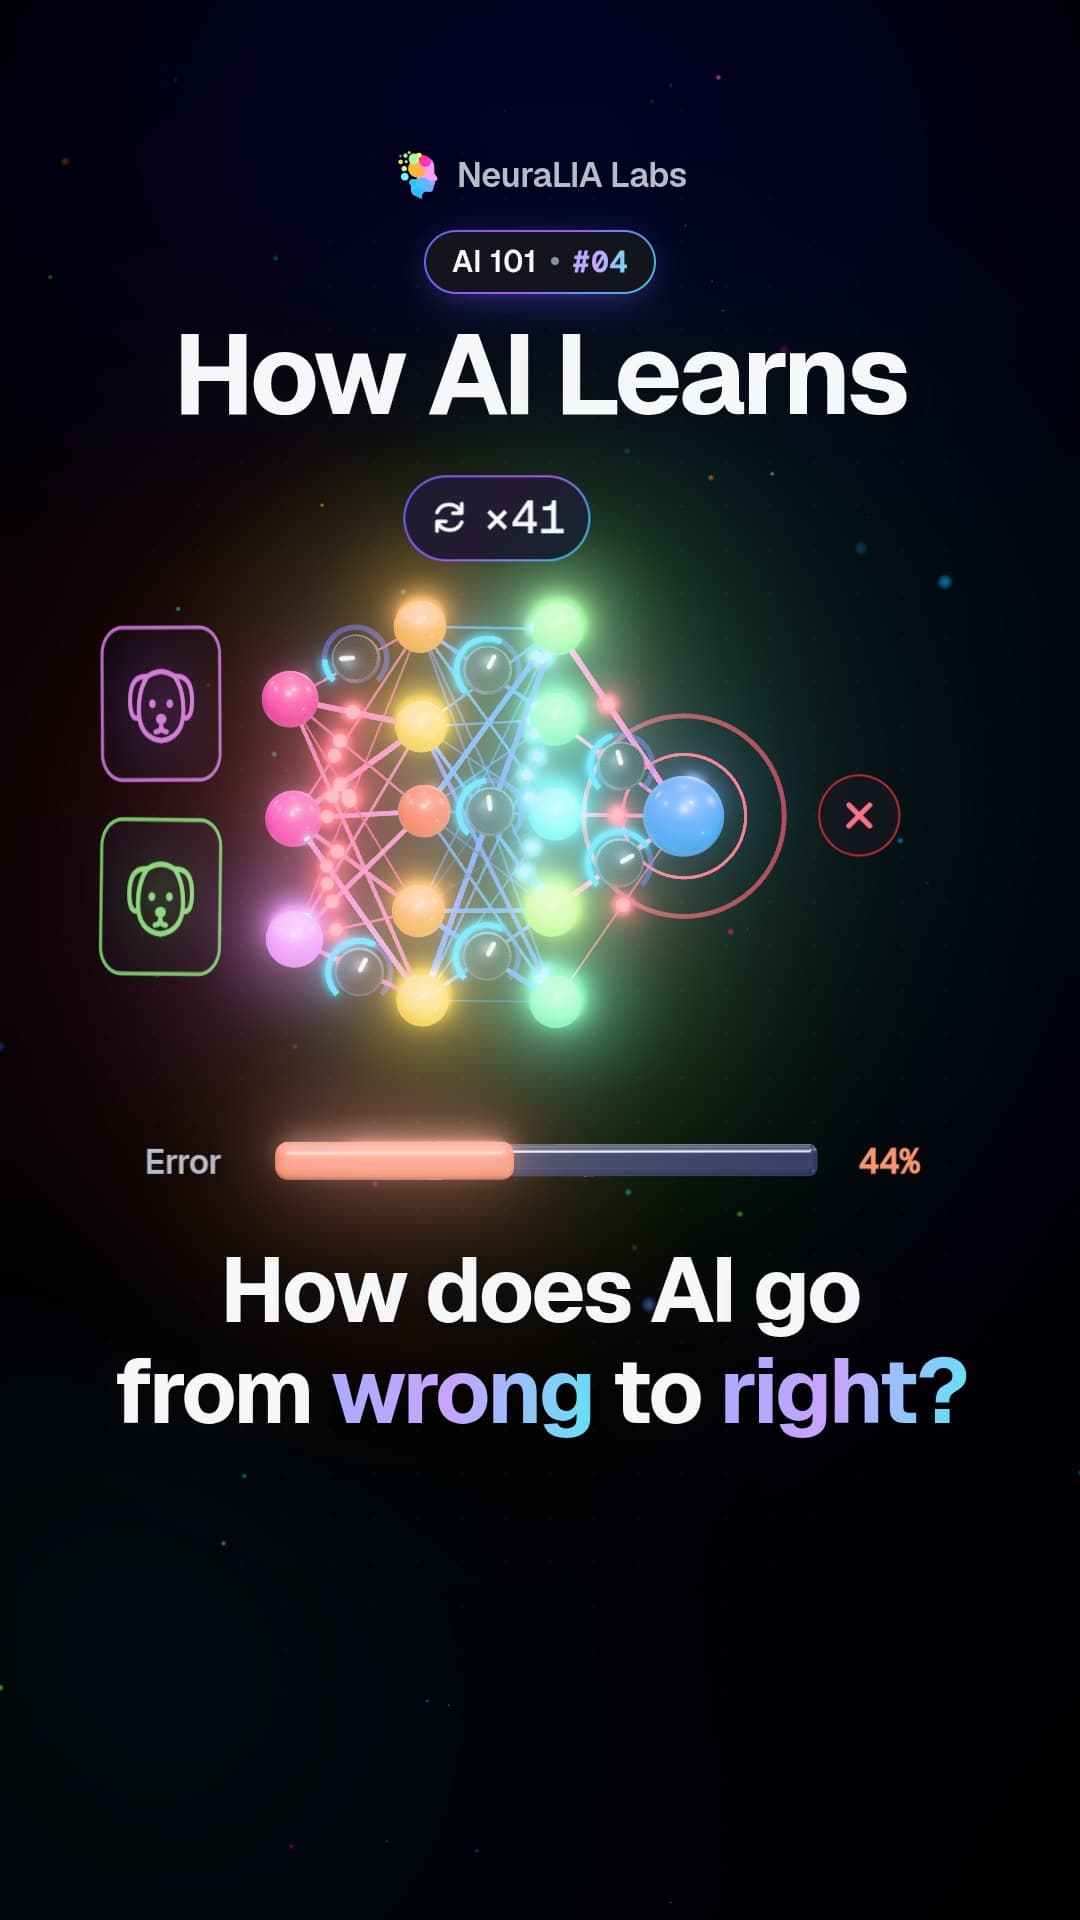
How AI learns: guess, measure the error, nudge, repeat
 #05
Tokens: how AI chops your words into numbered pieces
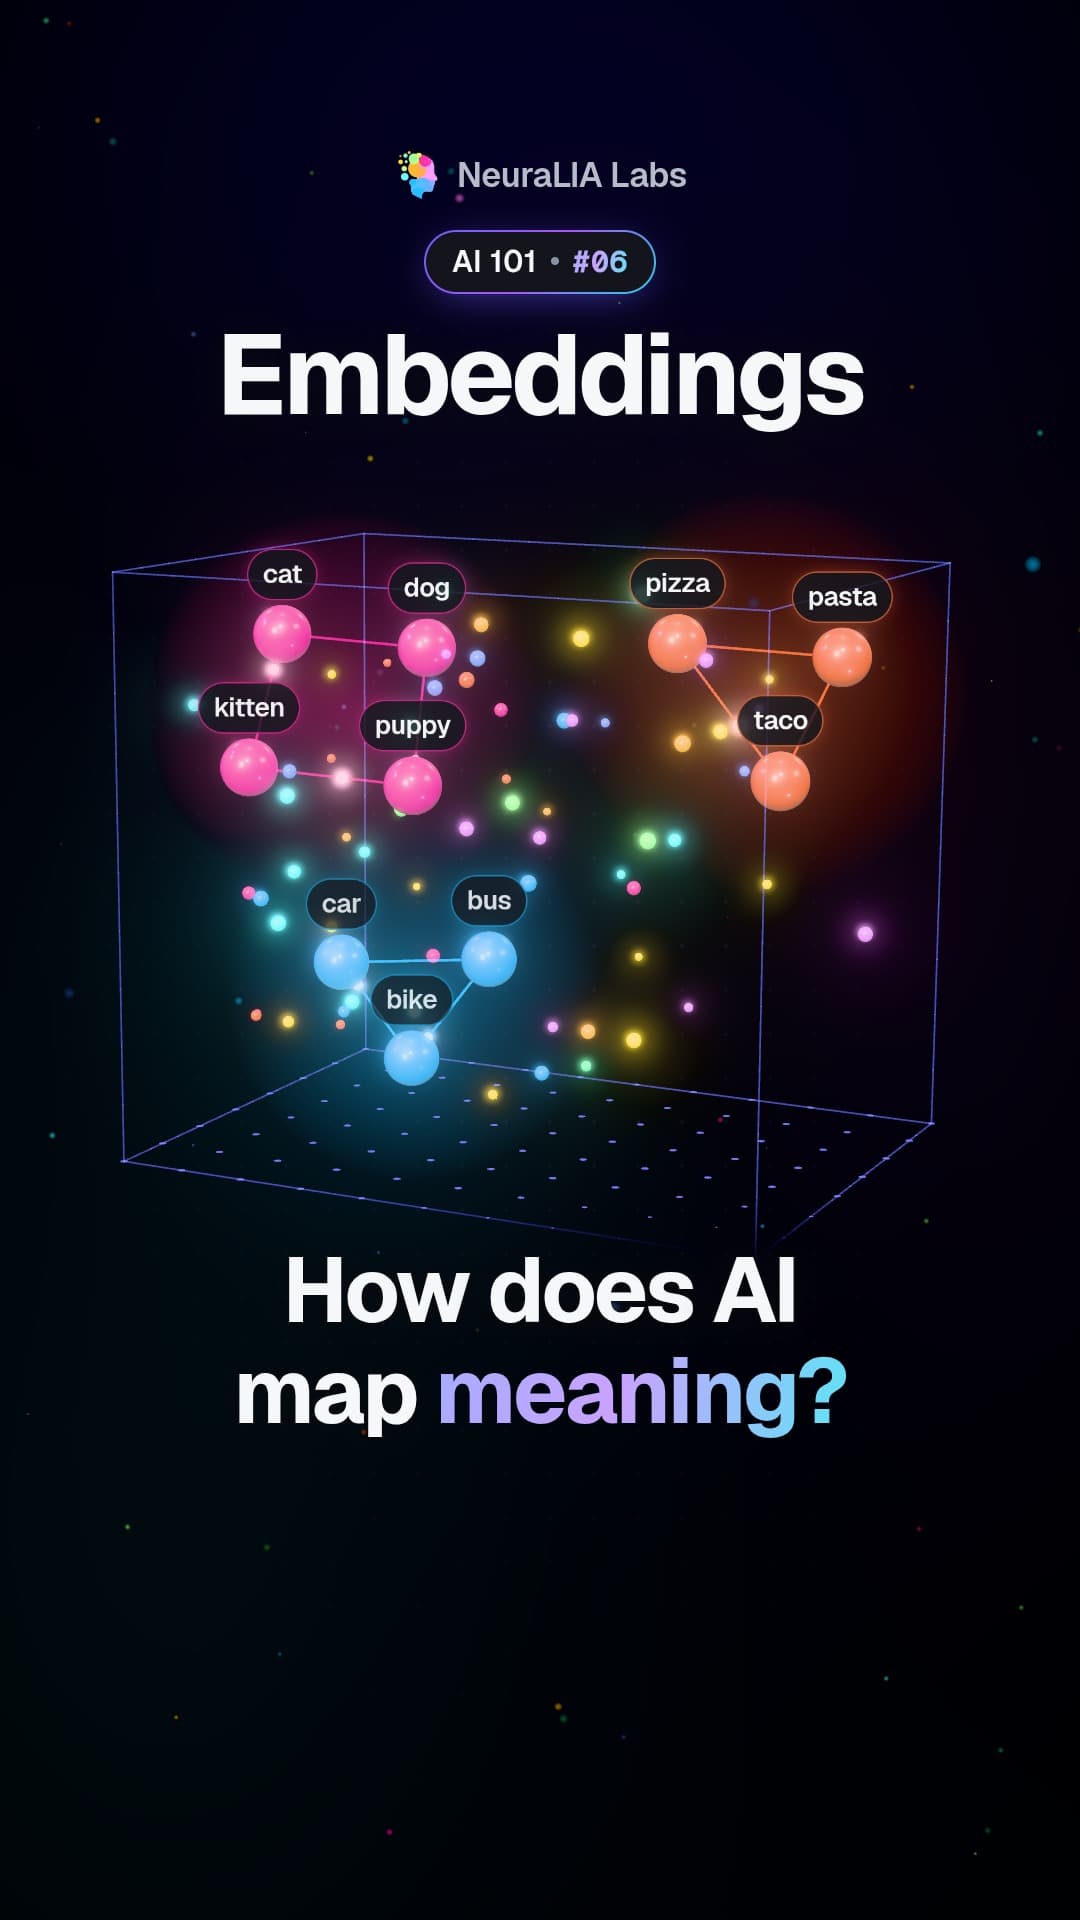 #06
Embeddings: why a puppy lands closer to a dog than to a pizza
Ultimi
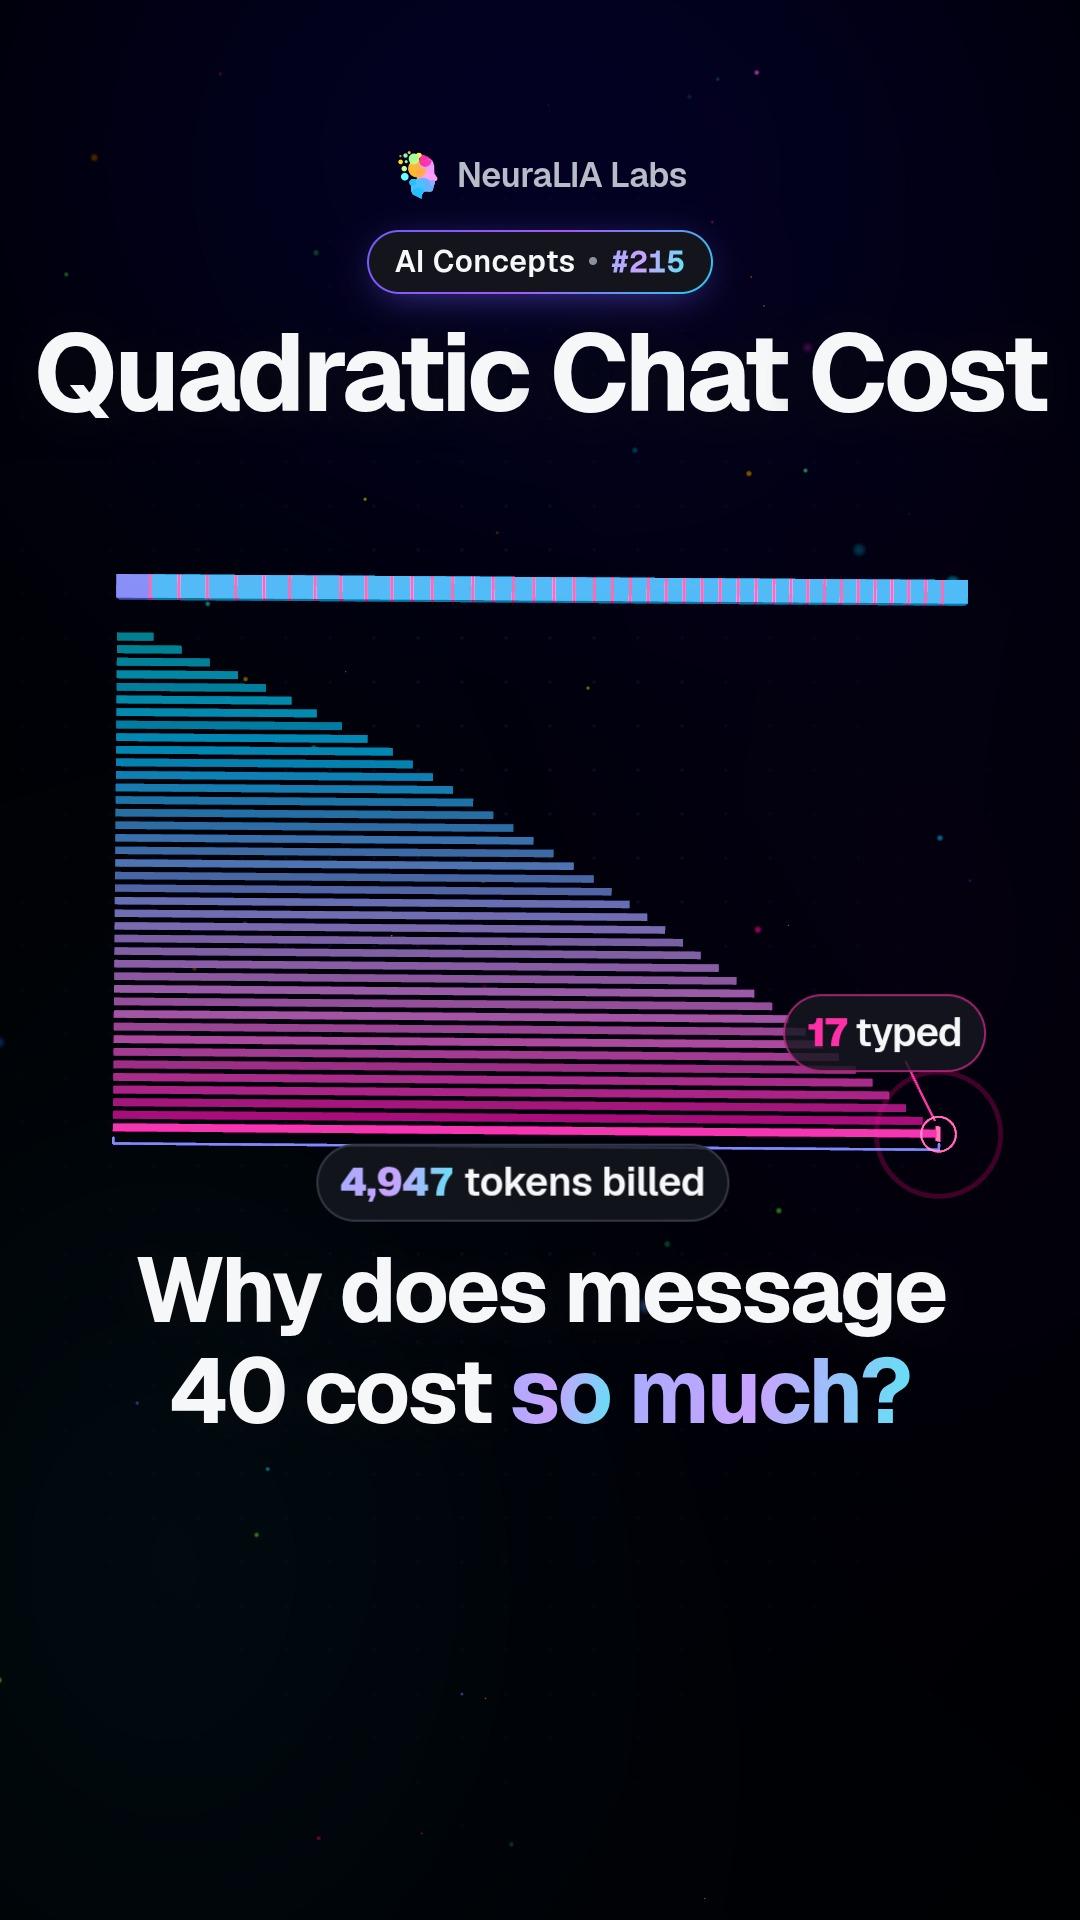 #215
Quadratic chat cost: why each new message costs more than the last
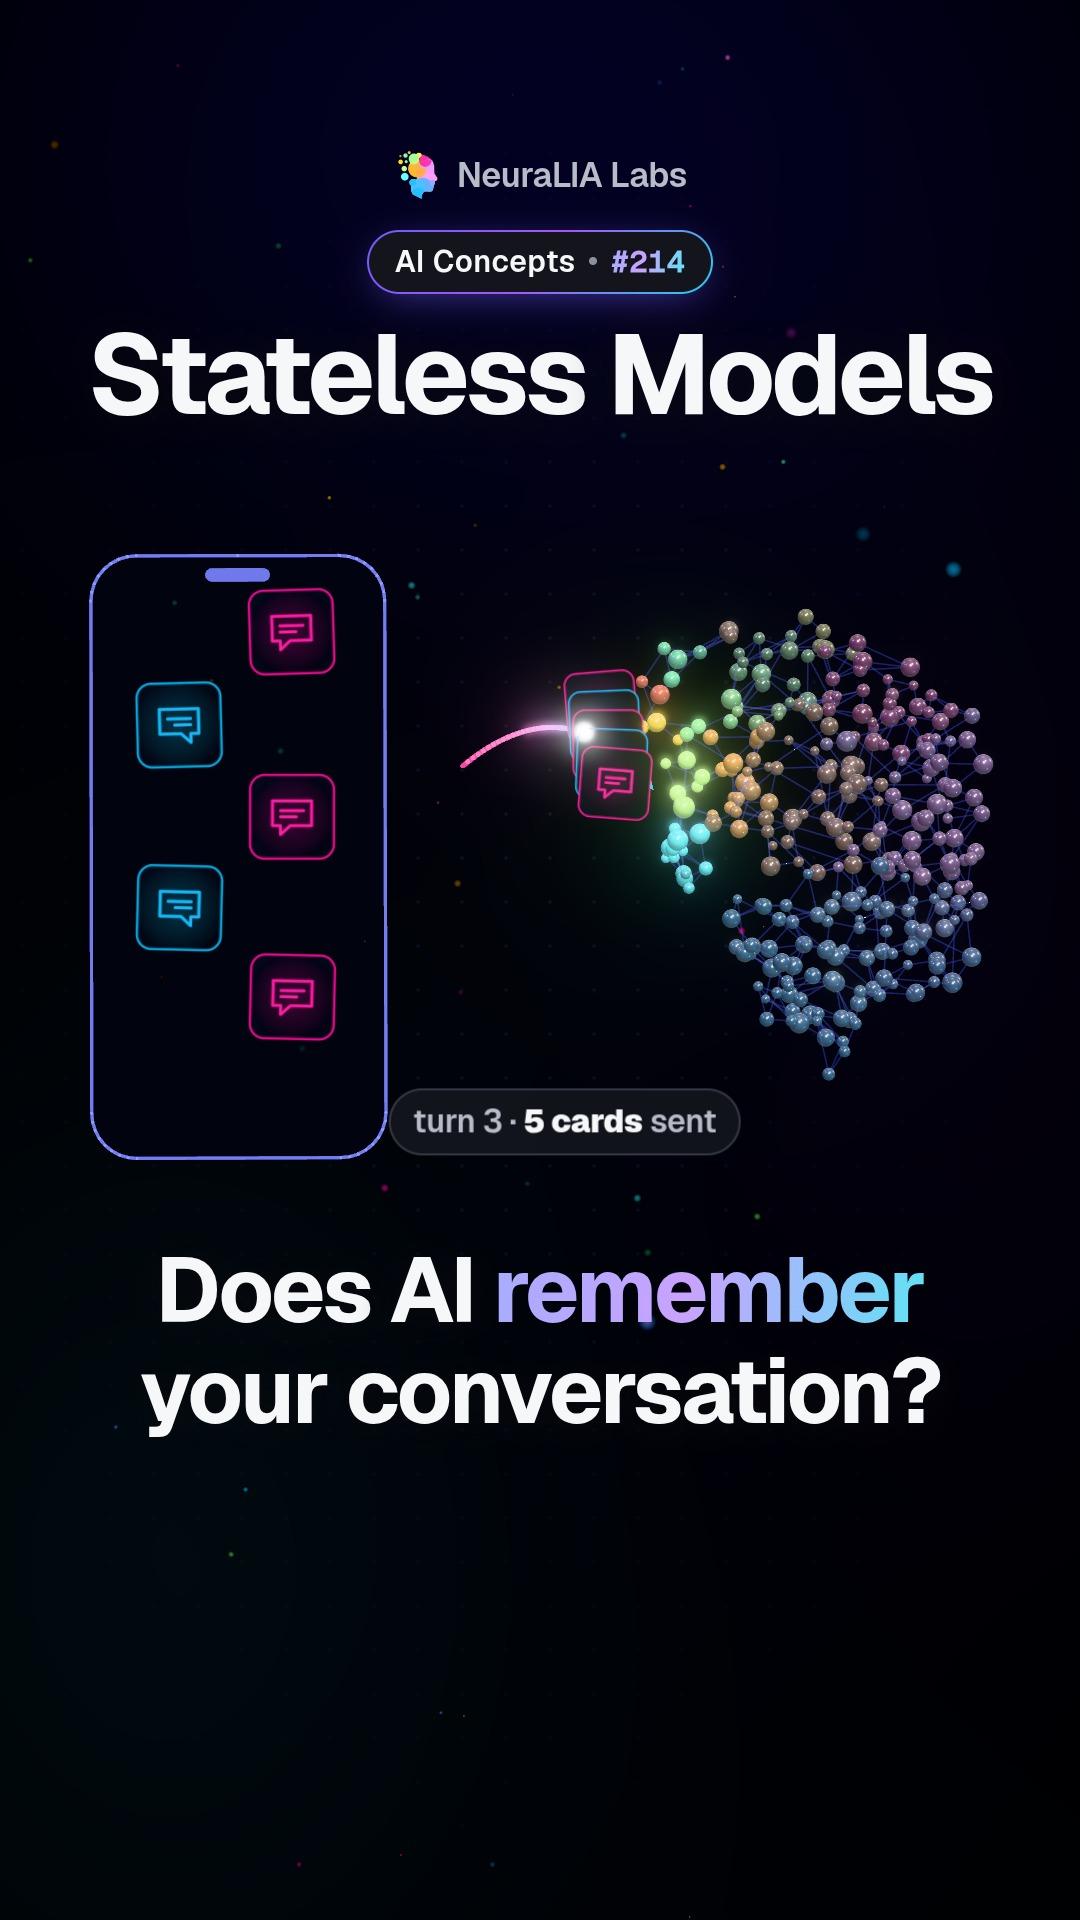 #214
Stateless models: why your chatbot rereads the whole chat every time
 #213
Prompt versioning: treat your AI instructions like code, not a note
 #212
DSPy: describe the task and let a tool write the prompts
 #211
Auto prompt engineering: letting the AI search for its own wording
 #210
Negative instructions: why telling an AI "don't" can backfire
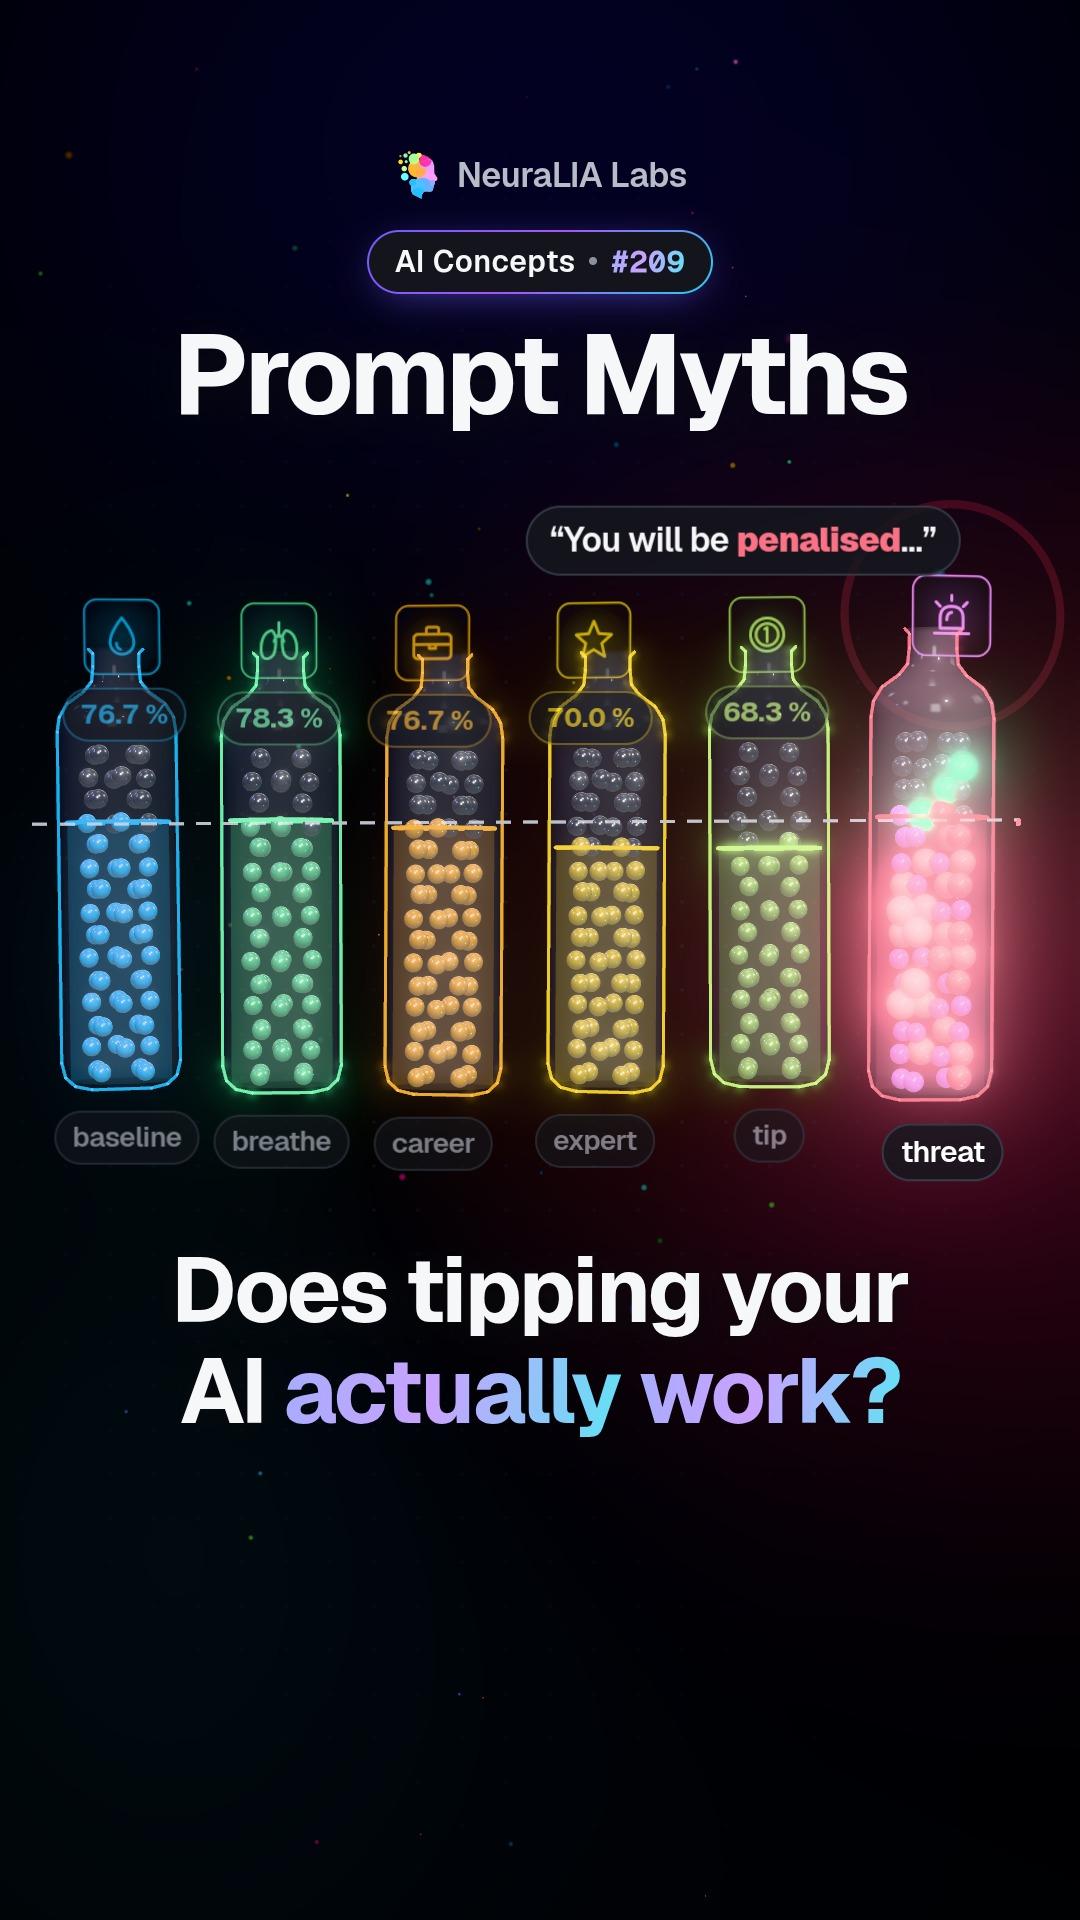 #209
Prompt myths: what tips, pep talks and threats did in a real test
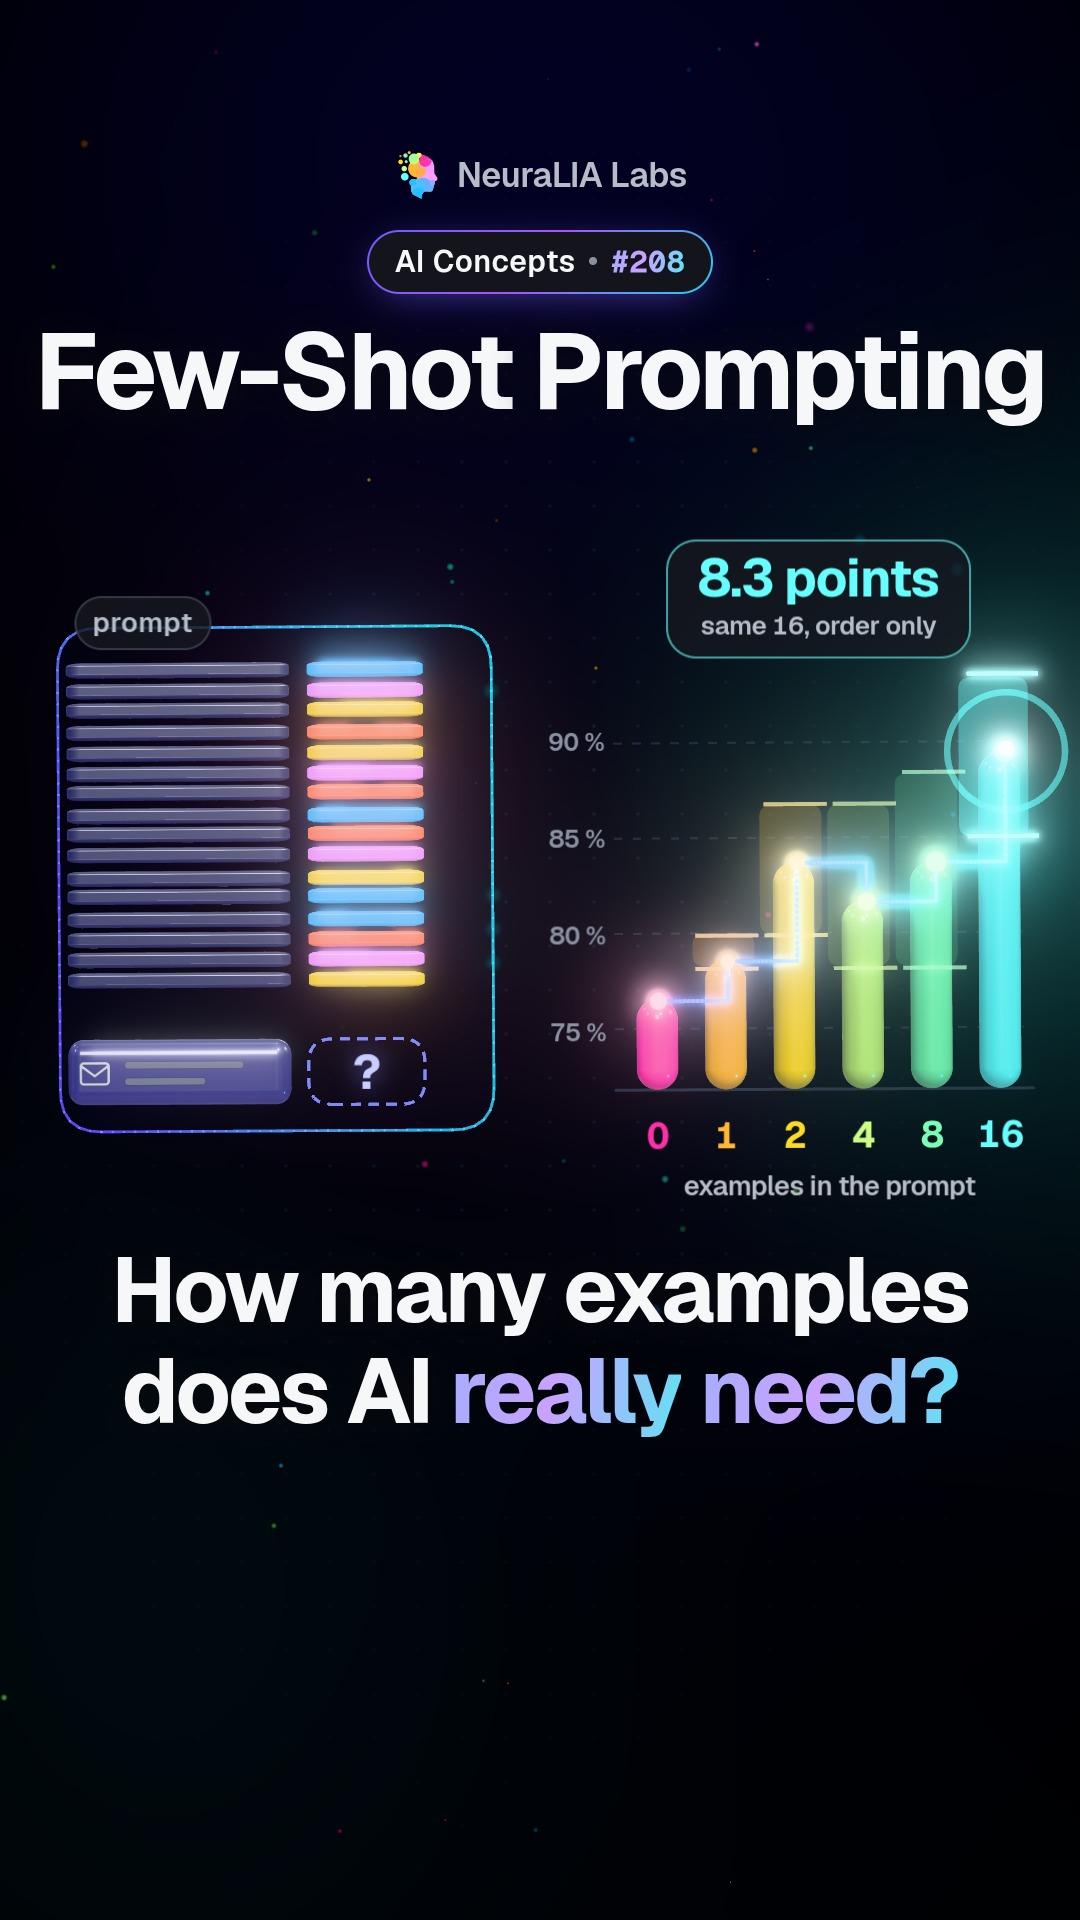 #208
Few-shot prompting: how many examples an AI prompt really needs
 #207
Prompt formatting: how quotes and tags quietly shift AI accuracy
 #206
System prompt: why where you put AI instructions changes results
 #205
Prompt order: the same words, rearranged, can double AI accuracy
 #204
Option order bias: when an AI picks a position, not an answer
 #203
Prompt testing: why twenty examples can't prove a prompt is better
 #202
Idempotency key: how to retry an AI request without paying twice
 #201
Idle timeout: how to tell a long AI answer from a frozen one
 #200
Timeouts: why every AI request needs a deadline you choose
 #199
Rate limits: when an AI service says wait, wait at least that long
 #198
Concurrency gate: letting fewer requests in made everything faster
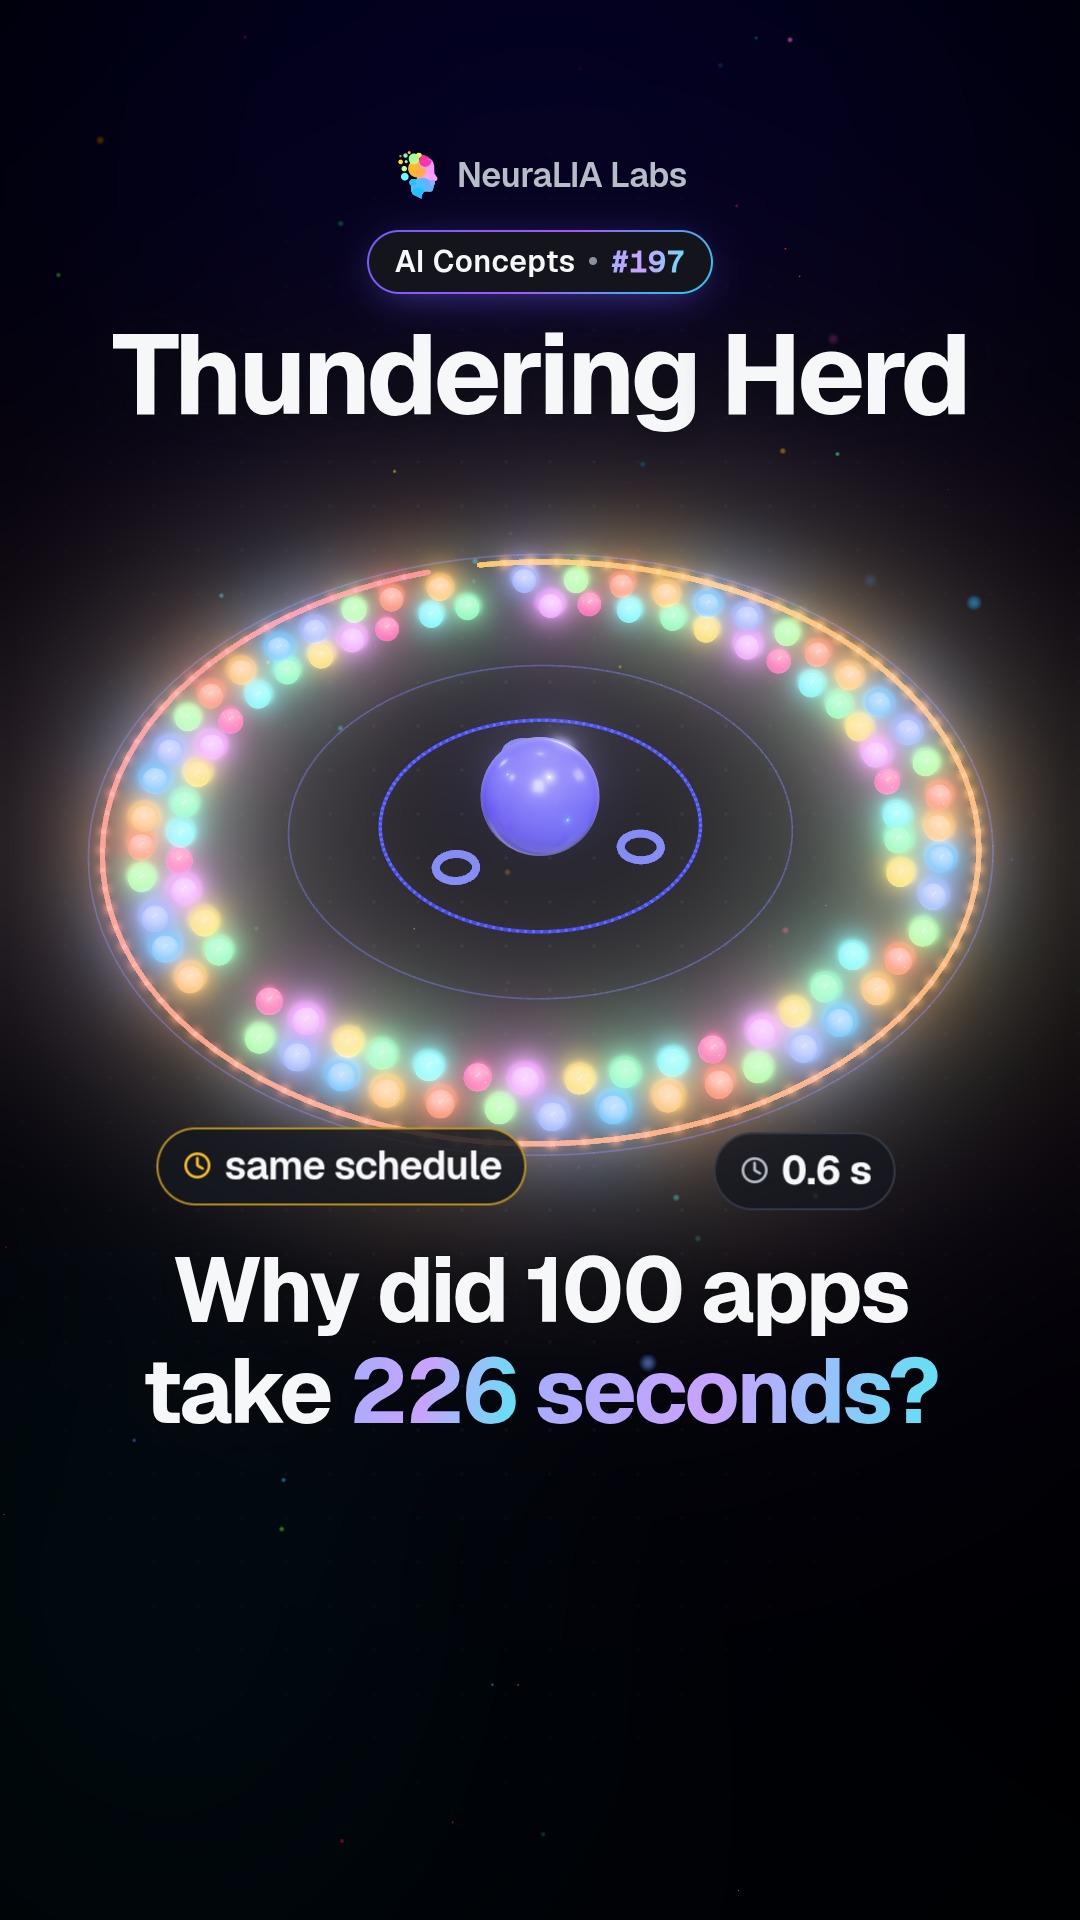 #197
Thundering herd: when retrying apps move in lockstep and jam a server
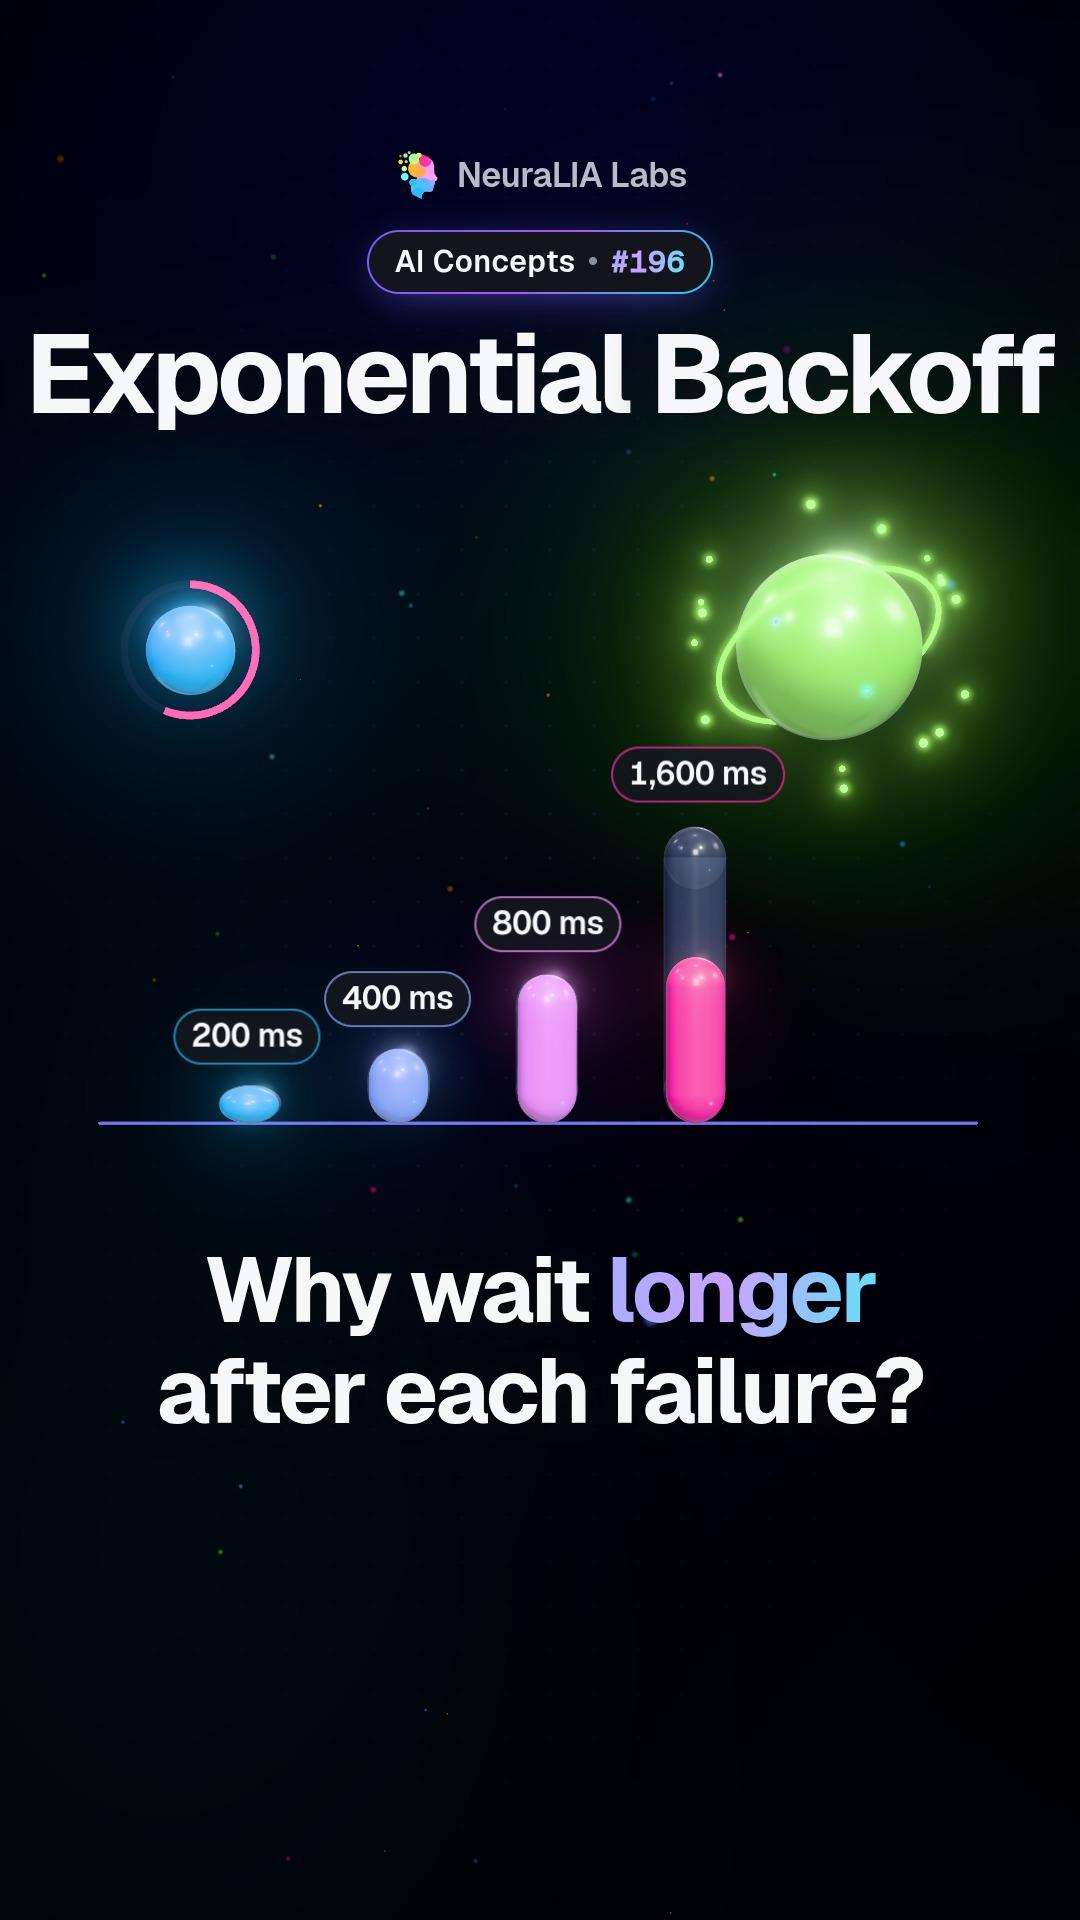 #196
Exponential backoff: why a retry should wait twice as long each time
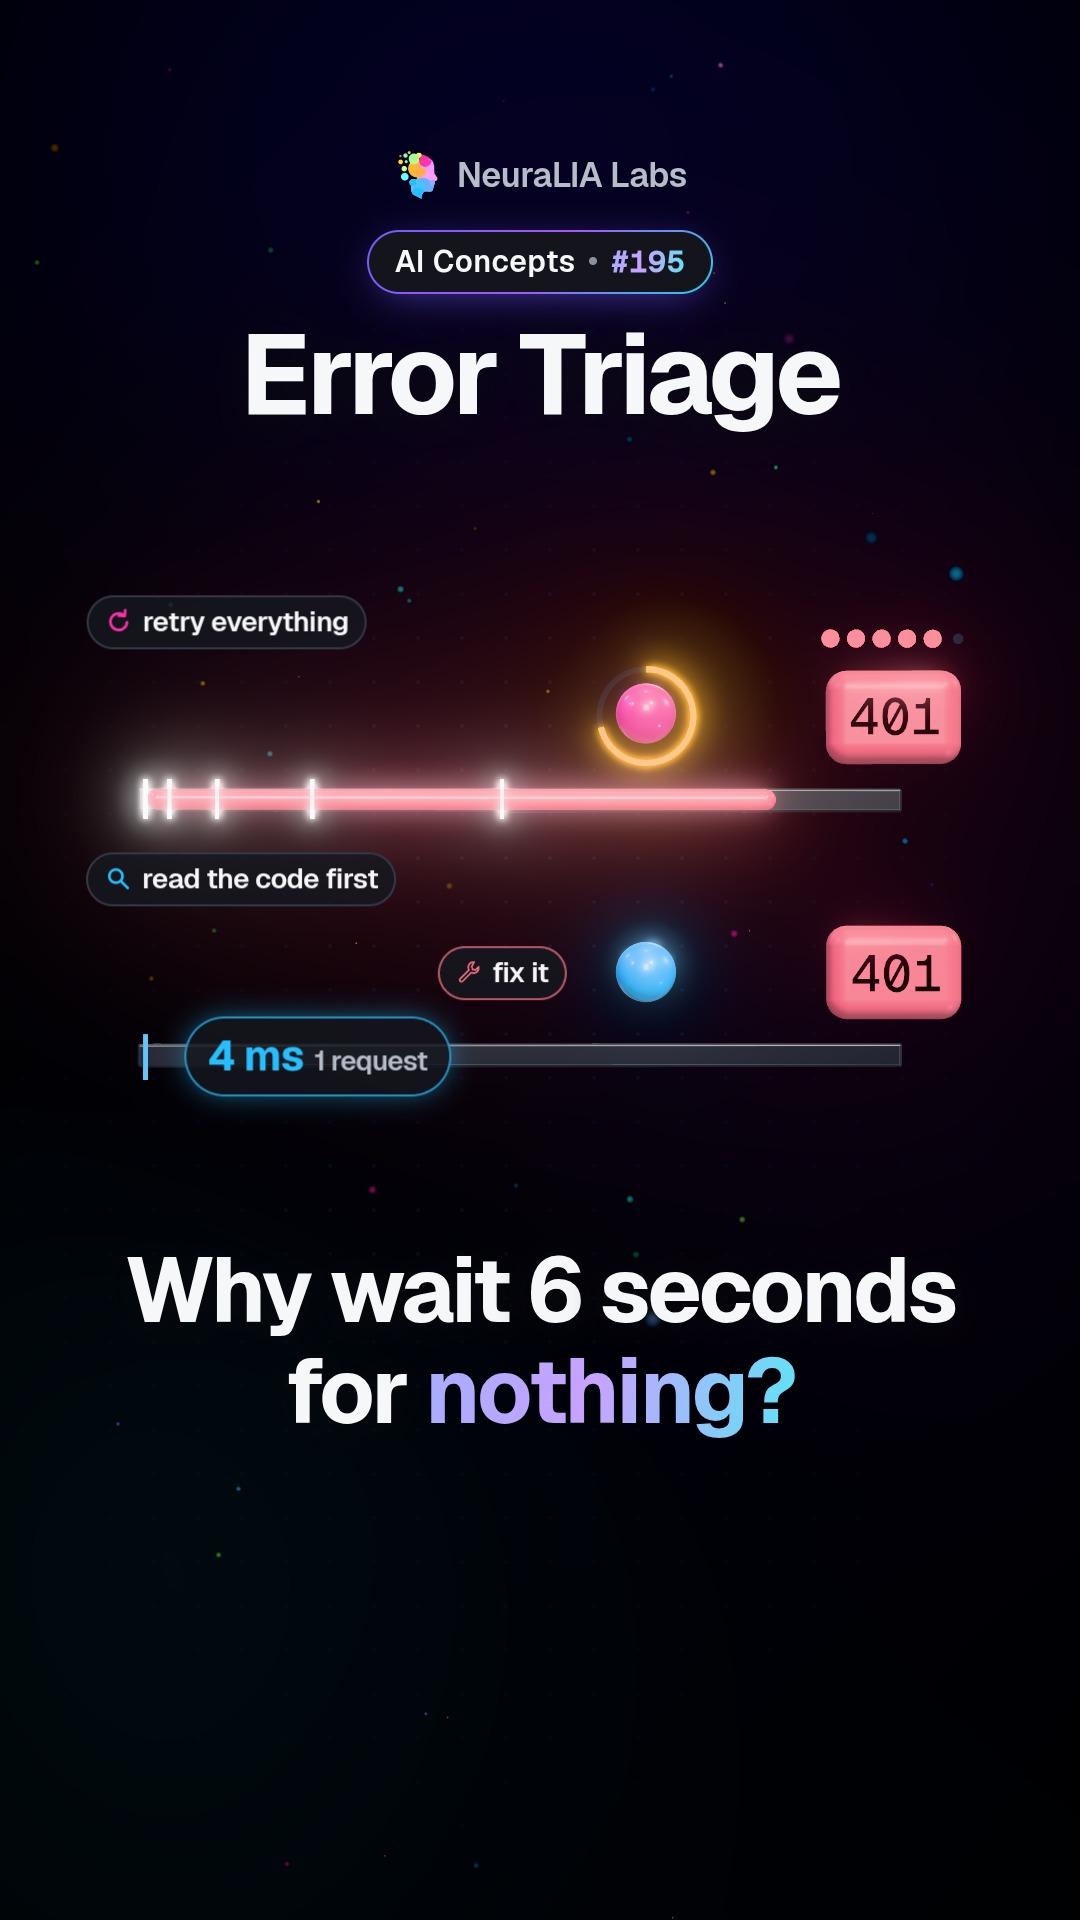 #195
Error triage: which AI errors deserve a retry and which never do
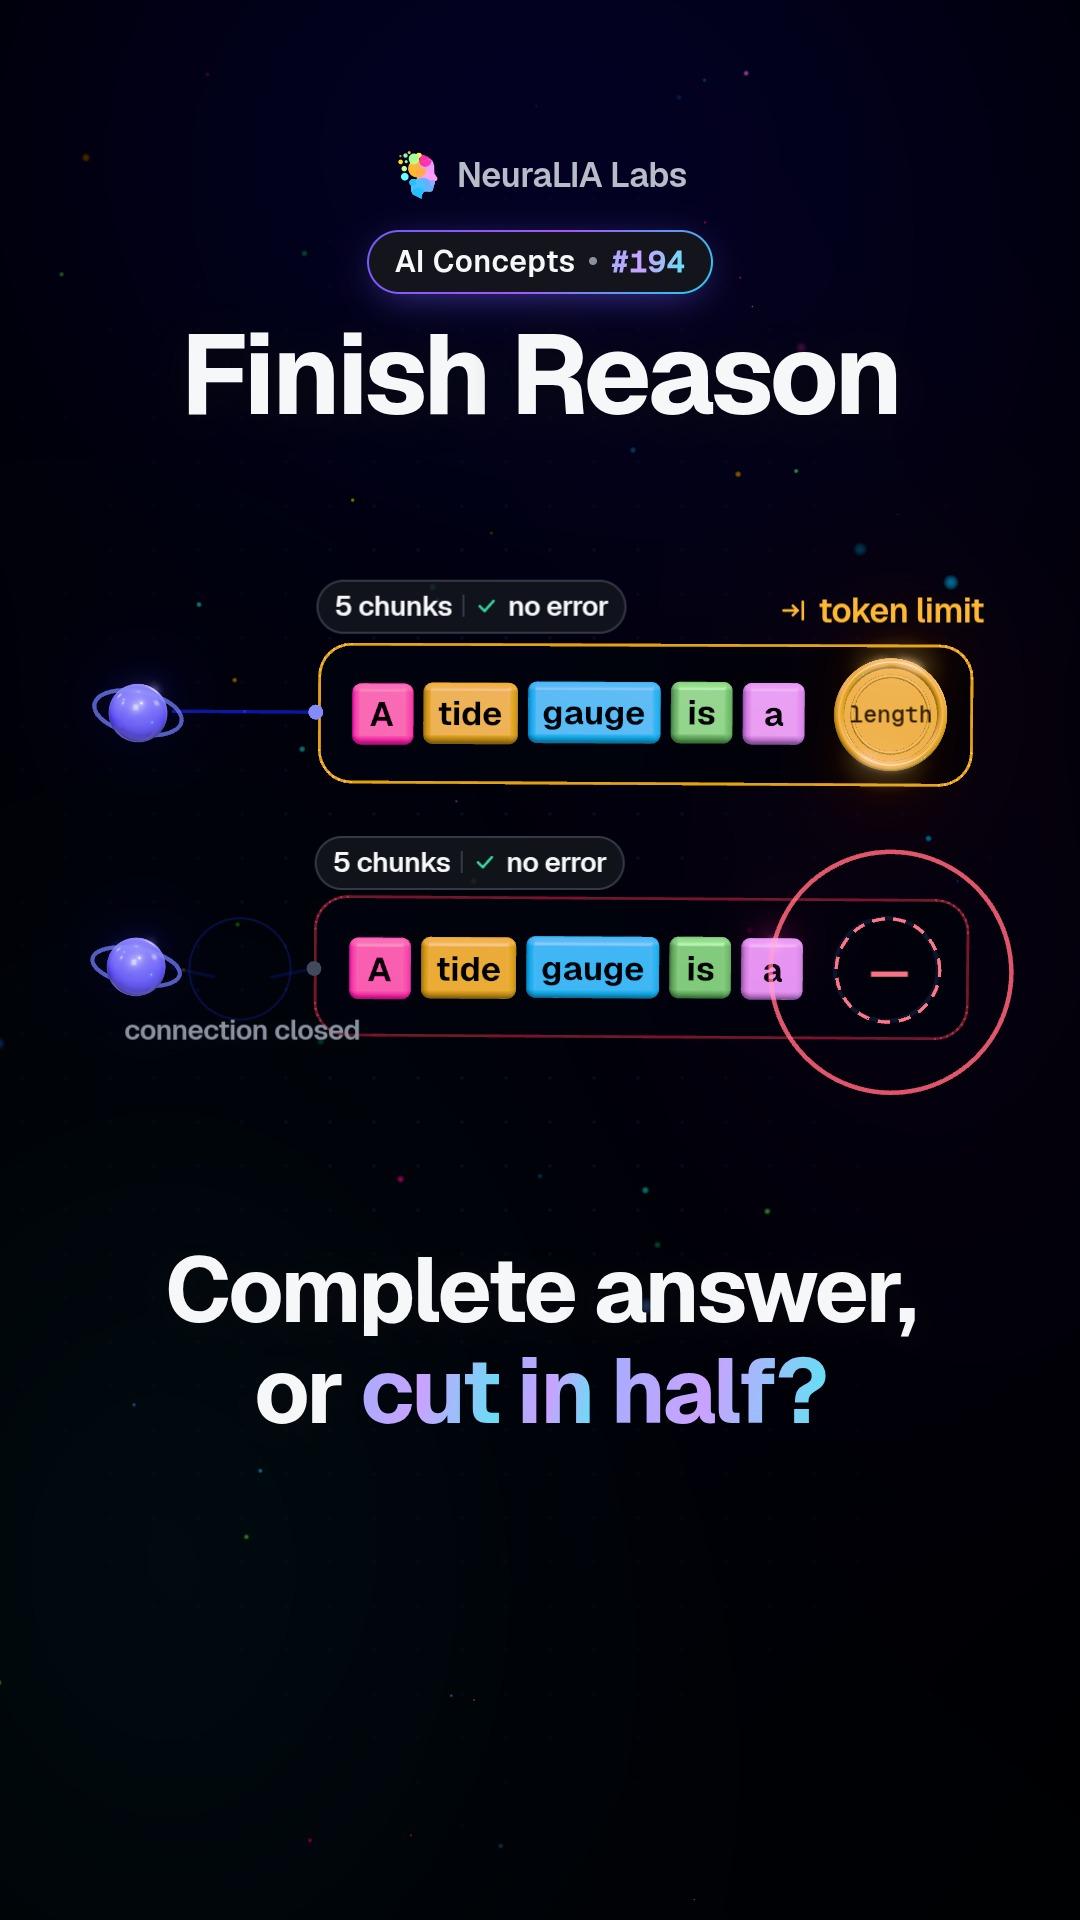 #194
Finish reason: telling a finished AI answer from a cut-off one
 #193
Streaming: why AI answers arrive word by word, and what it really buys
 #192
API key safety: why your AI key must never reach the browser
Per capitolo del corso
- 1Il perceptron da zero: che cosa calcola un neurone10 video
- 2Da dove nasce una funzione di loss: verosimiglianza, non convenzione12 video
- 3In discesa: Gradient Descent e i due passaggi che tutti saltano13 video
- 4Classificazione, cross-entropy e come non ingannarti da solo22 video
- 5Backpropagation da zero: prima il motore, poi la rete11 video
- 6Far sì che si alleni, e che generalizzi19 video
- 7Costruire un Tokenizer BPE: perché il tuo modello non conta le R12 video
- 8Predizione del next-token: embedding e cosa significa la perplexity17 video
- 9Attention e transformer block, derivati da una media17 video
- 10Pretraining di un LLM: dati, compute, scaling laws e costi21 video
- 11Dal modello di base all'assistente: SFT, RLHF, DPO e GRPO16 video
- 12Chain of Thought, RLVR e Test-Time Compute, misurati9 video
- 13Rendere l’inference economica: KV cache, batching e quantizzazione18 video
- 14La tua prima chiamata LLM in produzione: streaming, retry, timeout11 video
- 15Prompt Engineering misurato: cosa cambia l’output11 video
- 16Context window, token e conto: misurati2 video
- 17Temperature, Top-p e il determinismo che non hai
- 18Tool Calling e output strutturati: il contratto che regge
- 19RAG in produzione: chunking, retrieval e citazioni oneste
- 20Fine-Tune, retrieval o prompt? La decisione è economica
- 21Prezzi multimodali: cosa fatturano davvero immagini, audio e video
- 22Cos’è un AI agent: cinque tipi classici, due definizioni rivali
- 23Costruire un agent harness: il loop e le sue cinque vie d’uscita
- 24Context Engineering: perché il tuo agent diventa più stupido al turno 40
- 25Orchestrazione multi-agent: cinque pattern e quando ne vince uno
- 26MCP spiegato a partire dalla specifica: che cos’è davvero un server
- 27Pubblicare un server MCP: TypeScript e Python, misurati
- 28Agent Skills e SKILL.md: disclosure progressiva, misurata
- 29Valutazione degli LLM: dai benchmark pubblici al tuo golden set
- 30Prompt injection e trifecta letale: mettere in sicurezza un vero agent