
 #01
סרטונים
AI מוסבר בסרטונים קצרים
רעיון אחד בכל סרטון, בשפה פשוטה. כל סרטון מקשר לפרק בקורס החינמי שלנו שמסביר אותו שלב אחר שלב.
להתחיל כאן AI 101
- #01
 #02
Machine learning: how a computer draws its own dividing line
 #03
Neural networks: layers of tiny calculators passing signals on
 #04
How AI learns: guess, measure the error, nudge, repeat
 #05
Tokens: how AI chops your words into numbered pieces
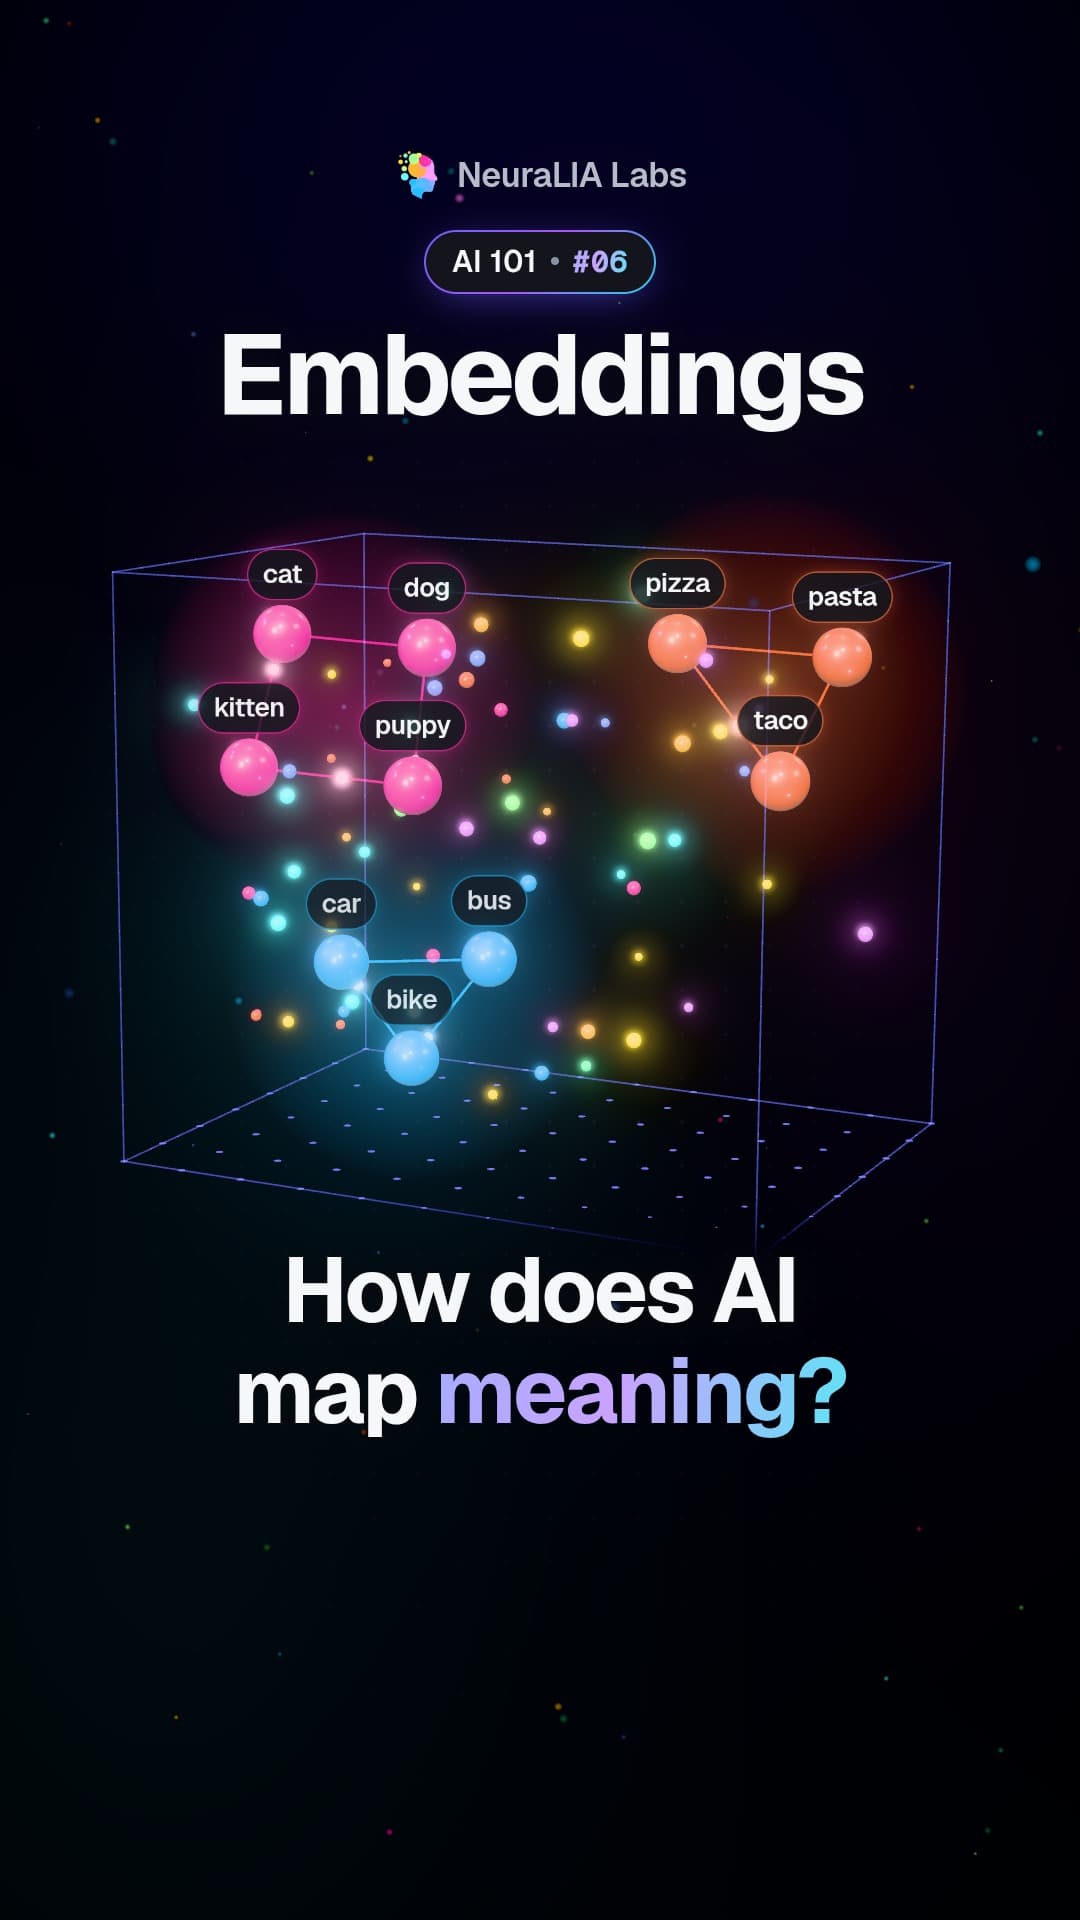 #06
Embeddings: why a puppy lands closer to a dog than to a pizza
אחרונים
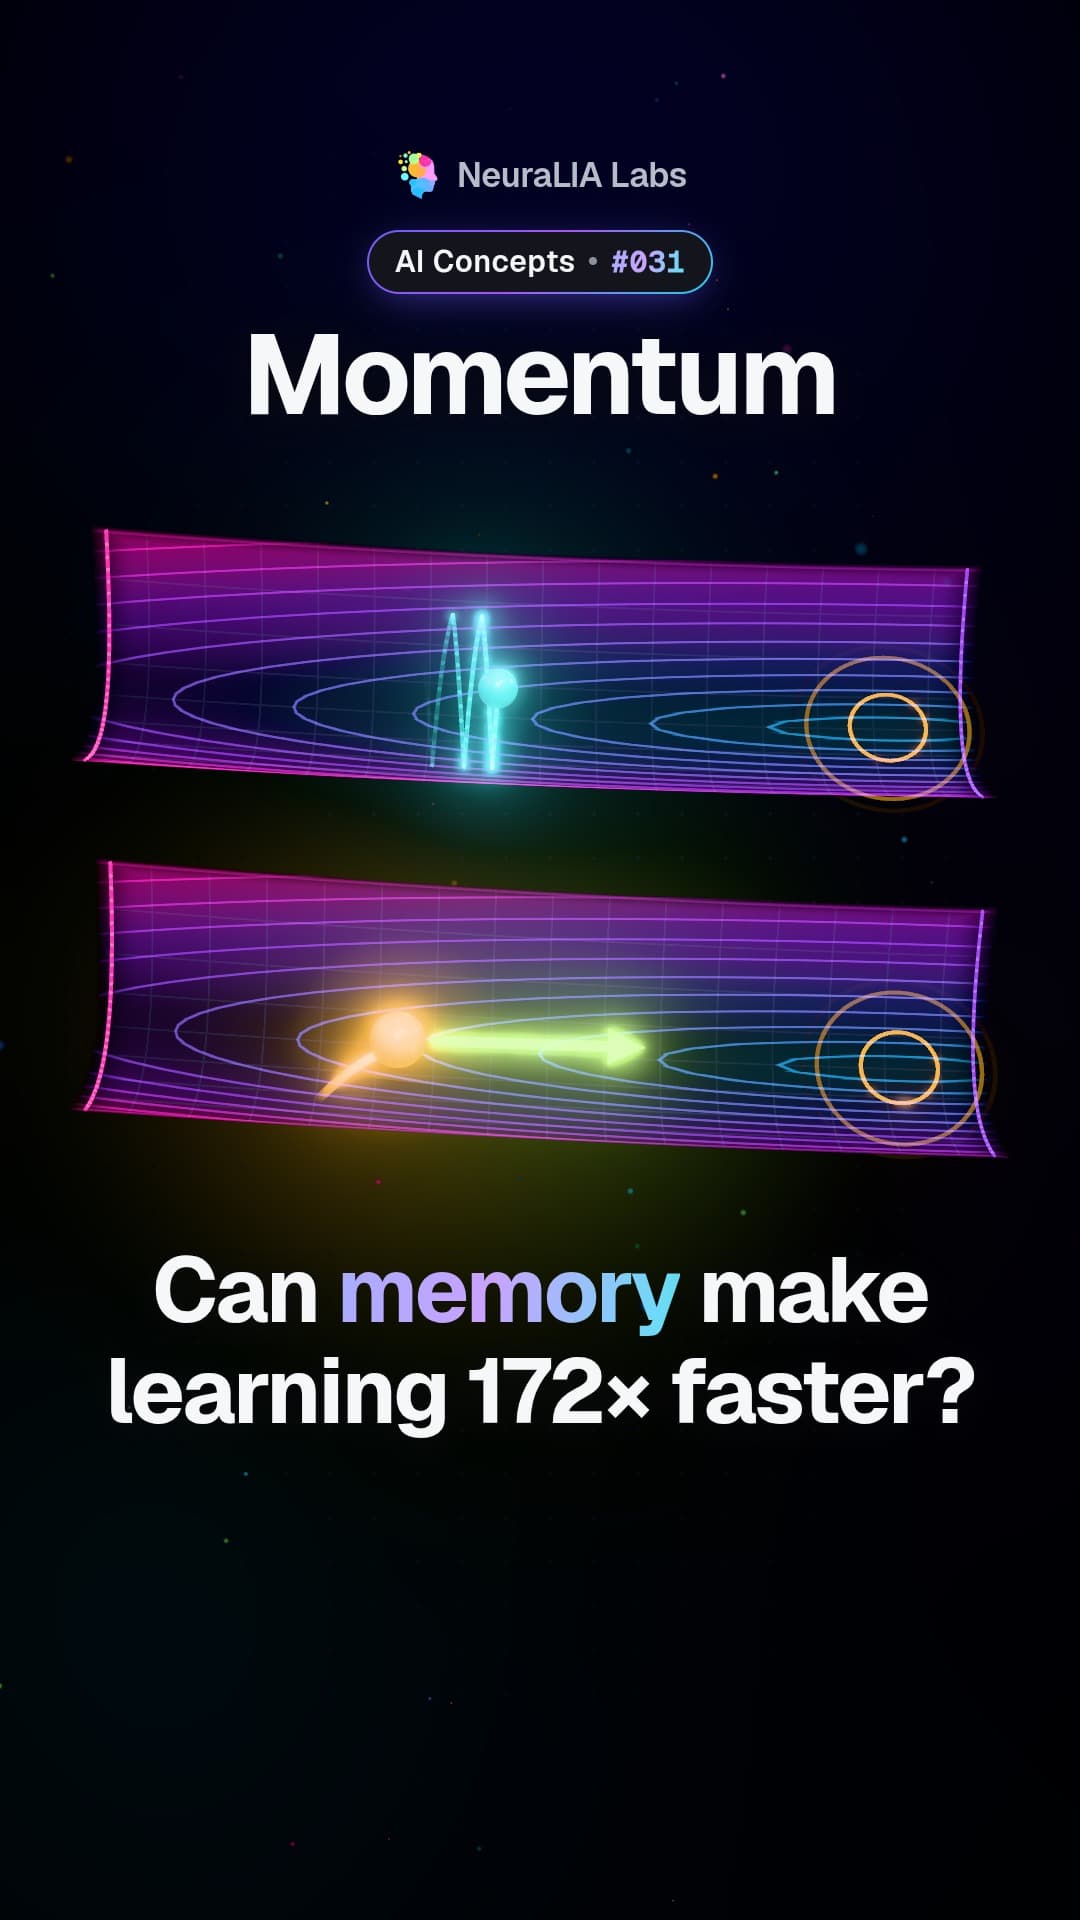 #031
Momentum: how remembering past steps stops AI training zigzagging
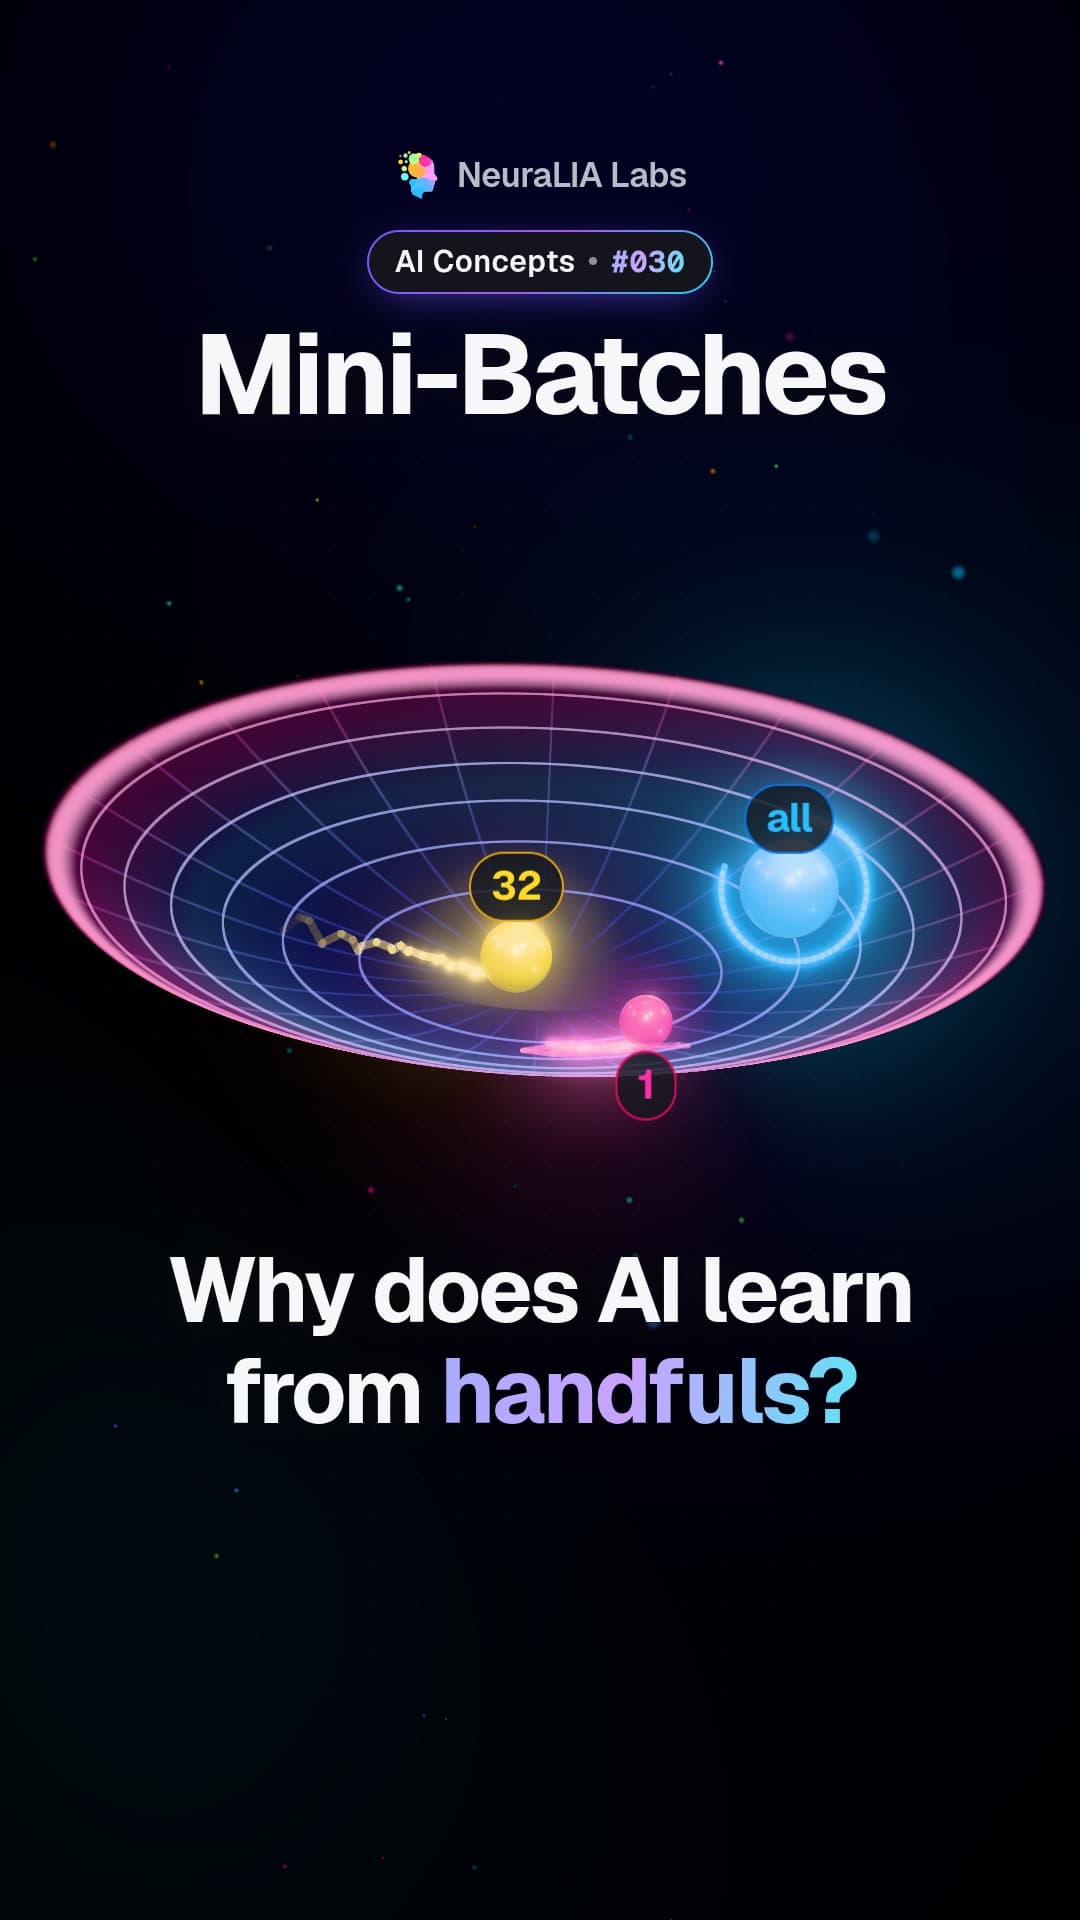 #030
Mini-batches: why AI learns faster from a random handful of data
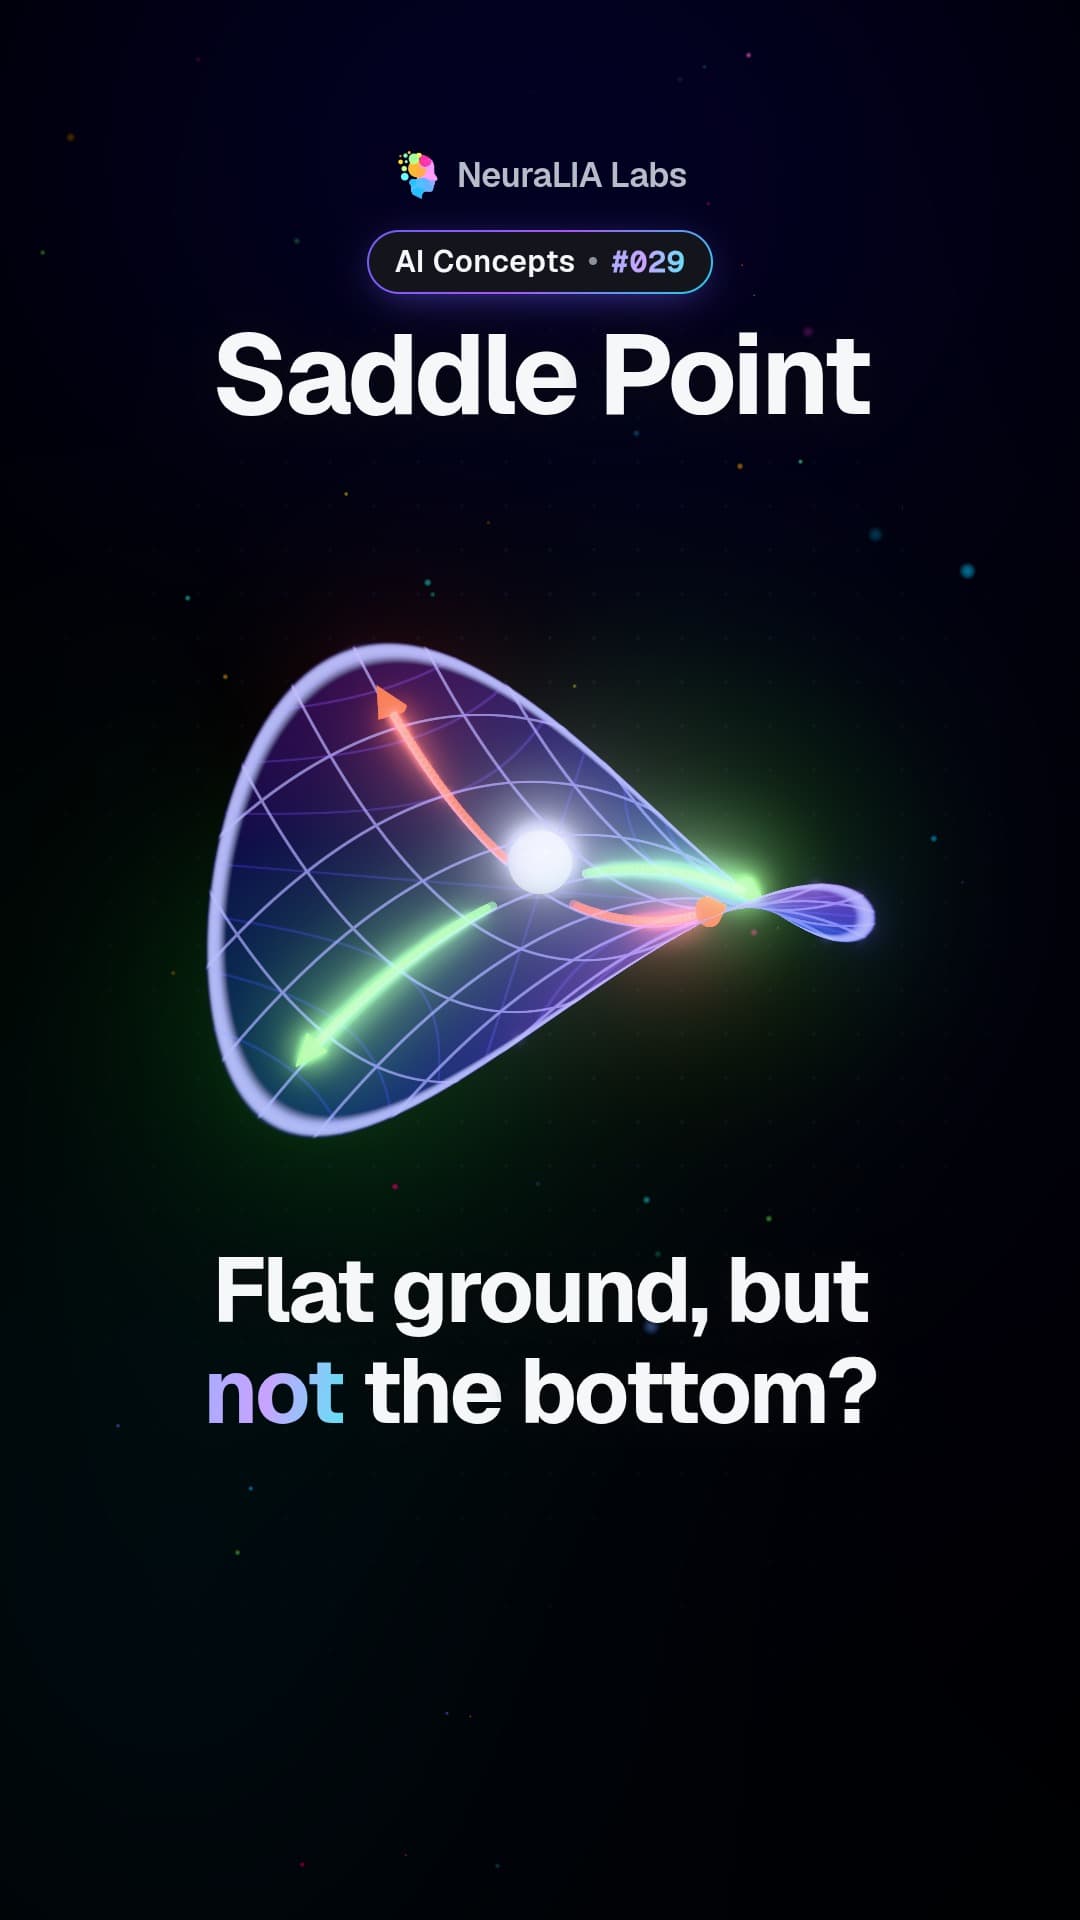 #029
Saddle points: where AI training looks stuck but has a way down
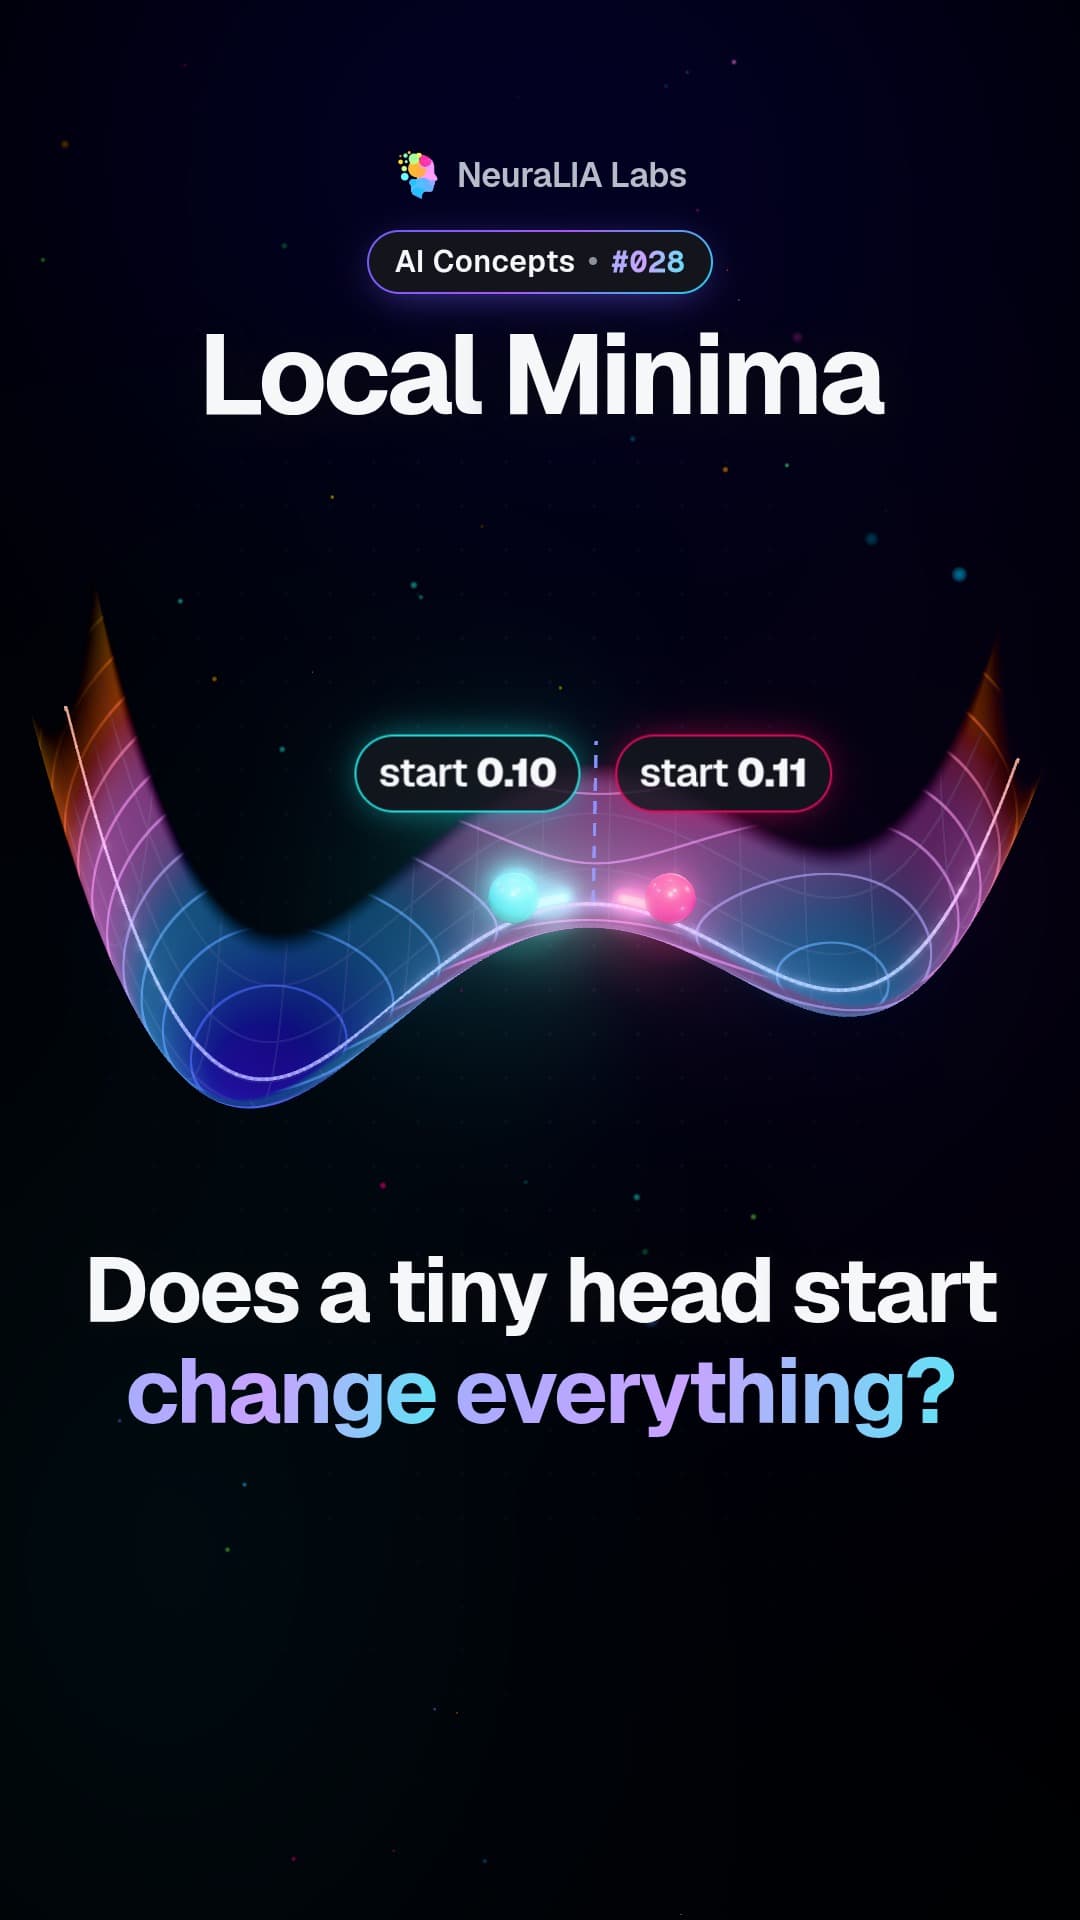 #028
Local minima: why AI training can settle for second best
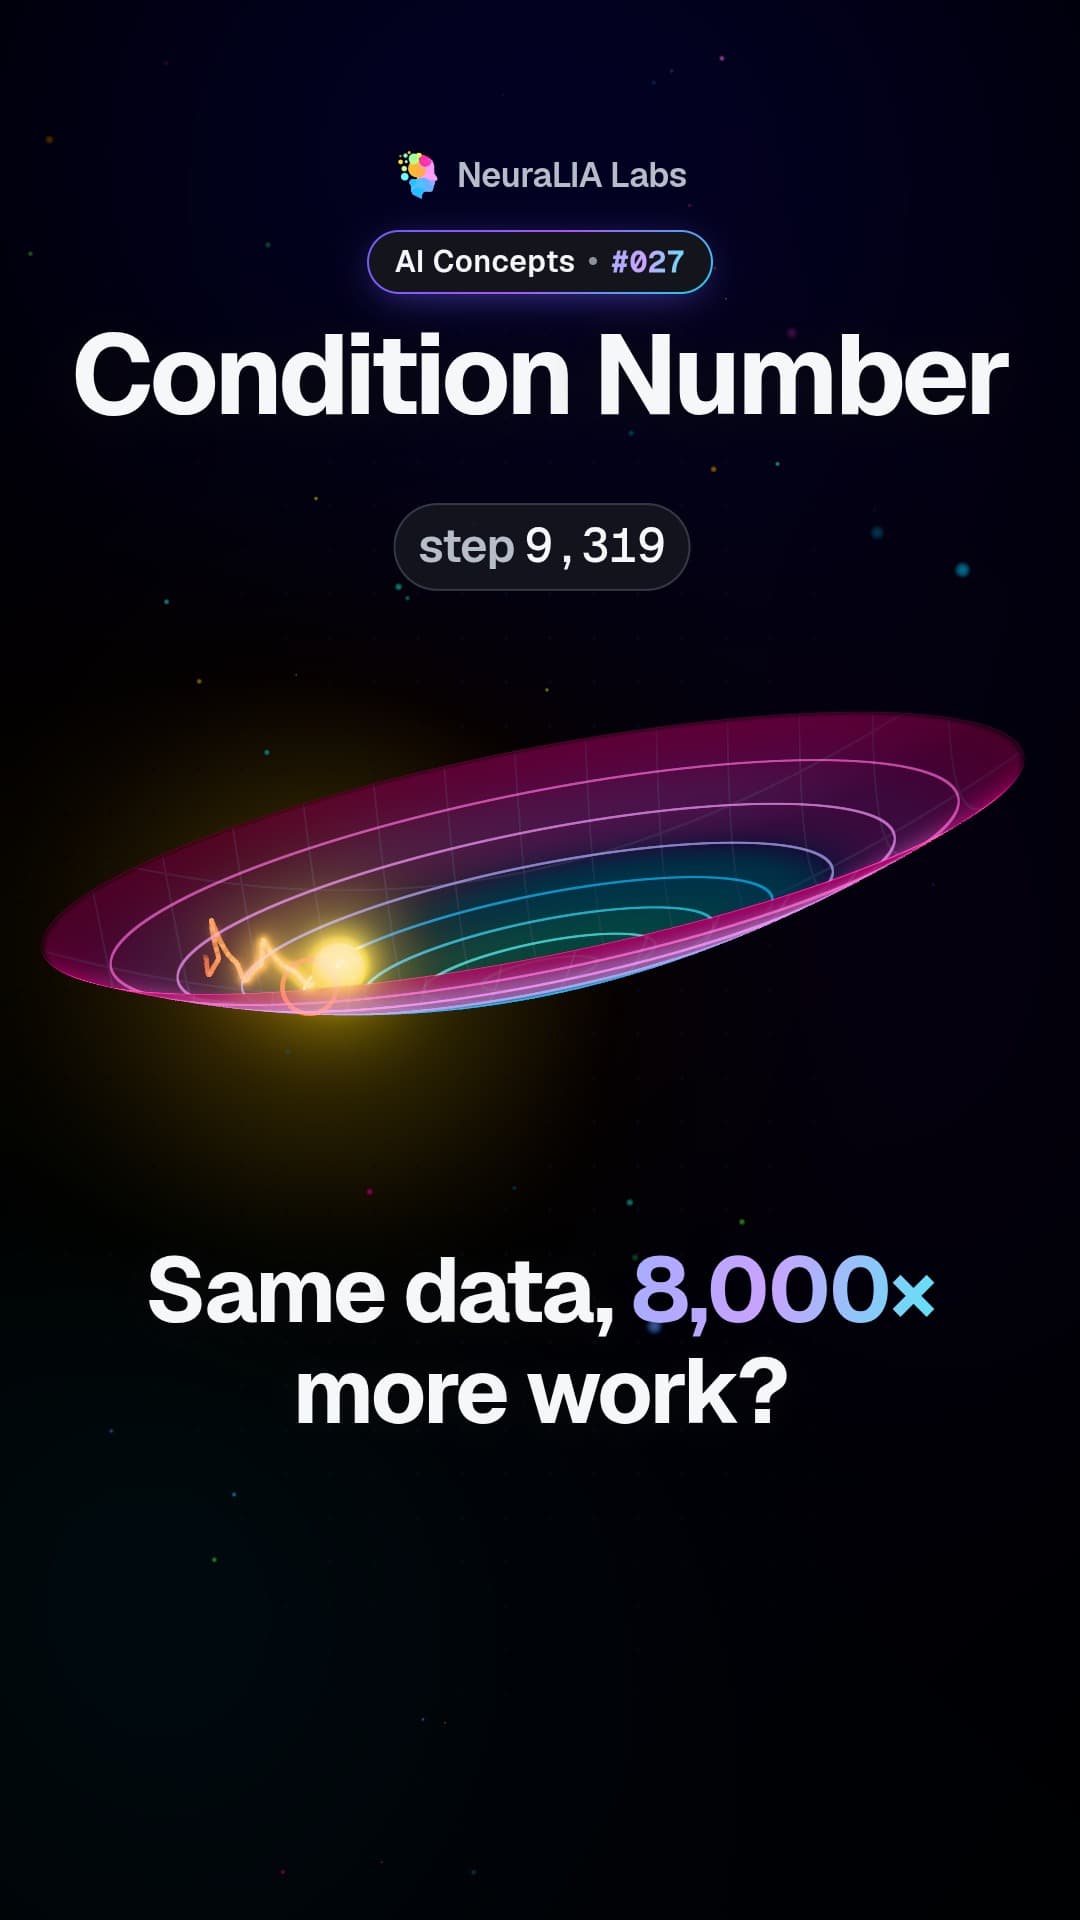 #027
Condition number: why a stretched valley makes AI training crawl
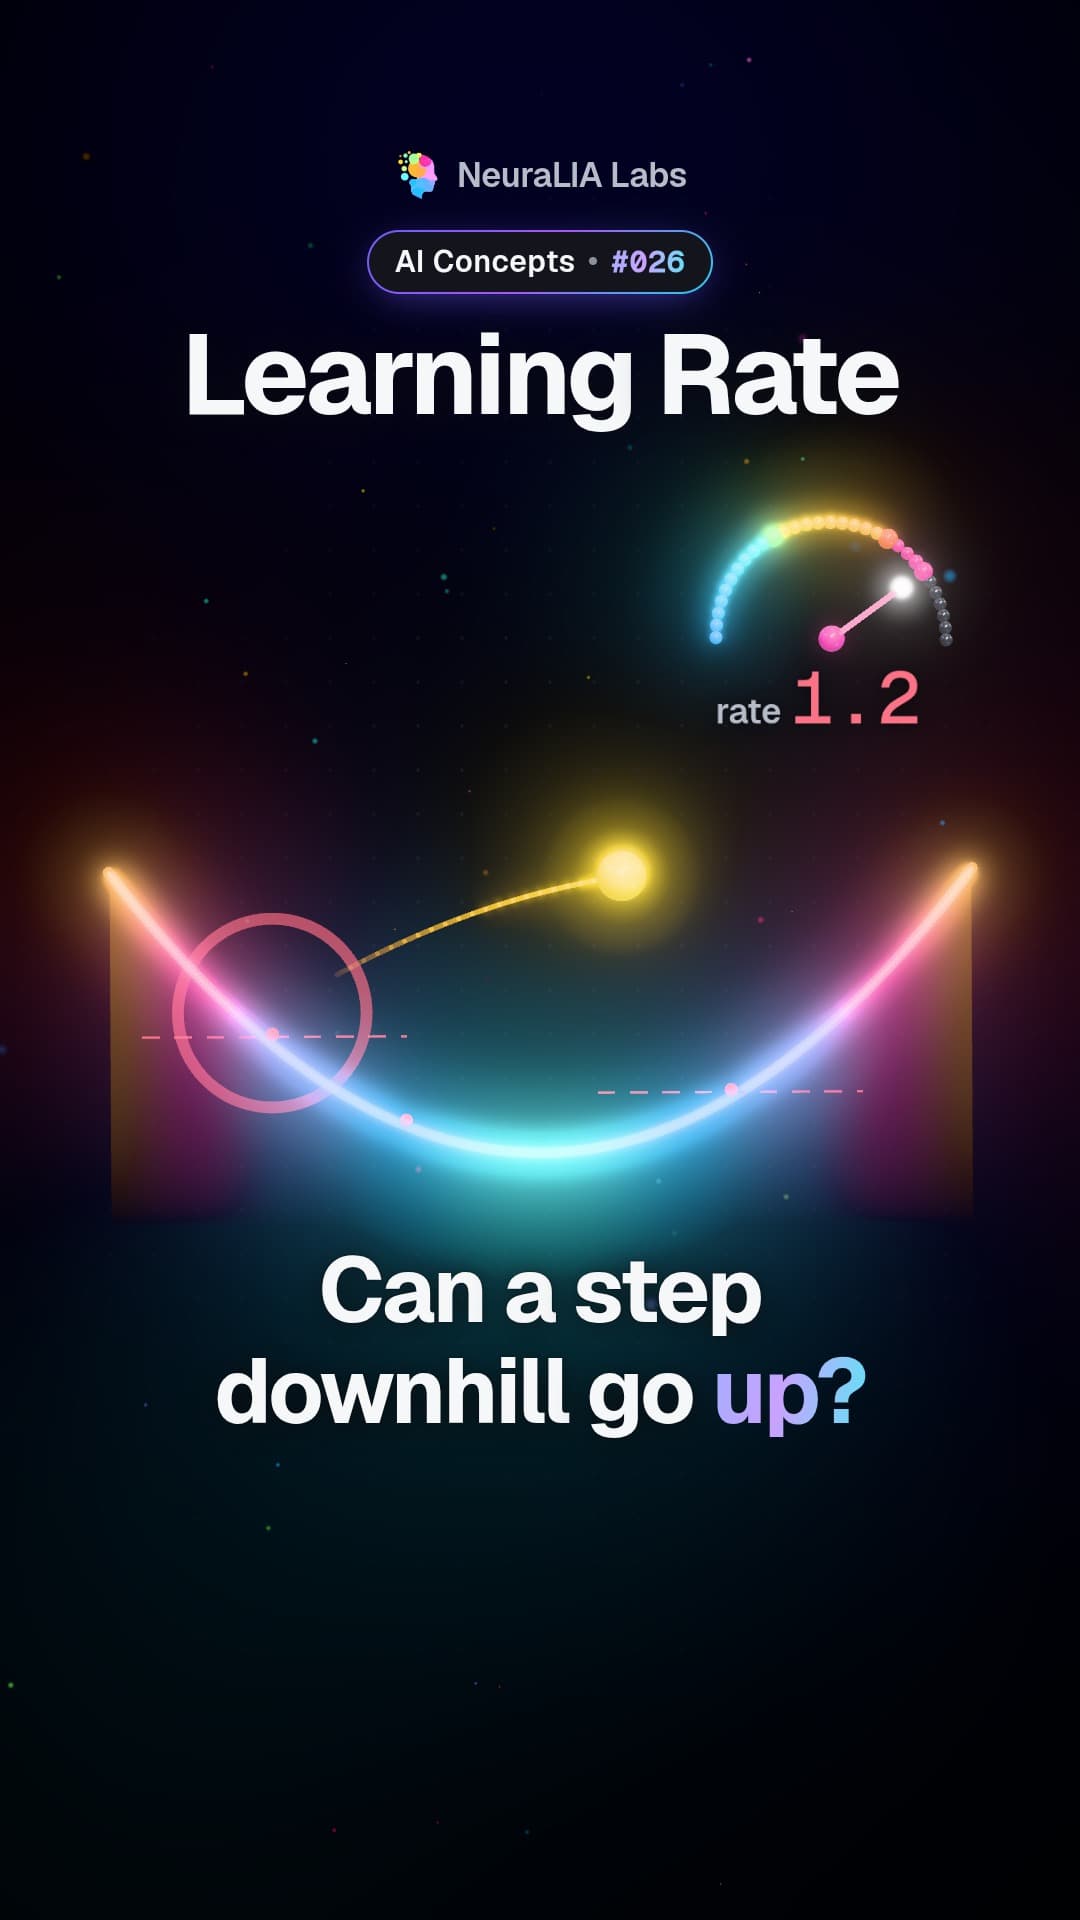 #026
Learning rate: the step size with a ceiling you can calculate
 #025
Gradient descent: how AI finds its way downhill in small steps
 #024
Gradient: the arrow that points uphill, and why AI walks the other way
 #023
Chain rule: how AI traces the effect of every layer
 #022
Derivative: how much the result moves when you nudge one input
 #021
Grid search: why you cannot train an AI by trying every setting
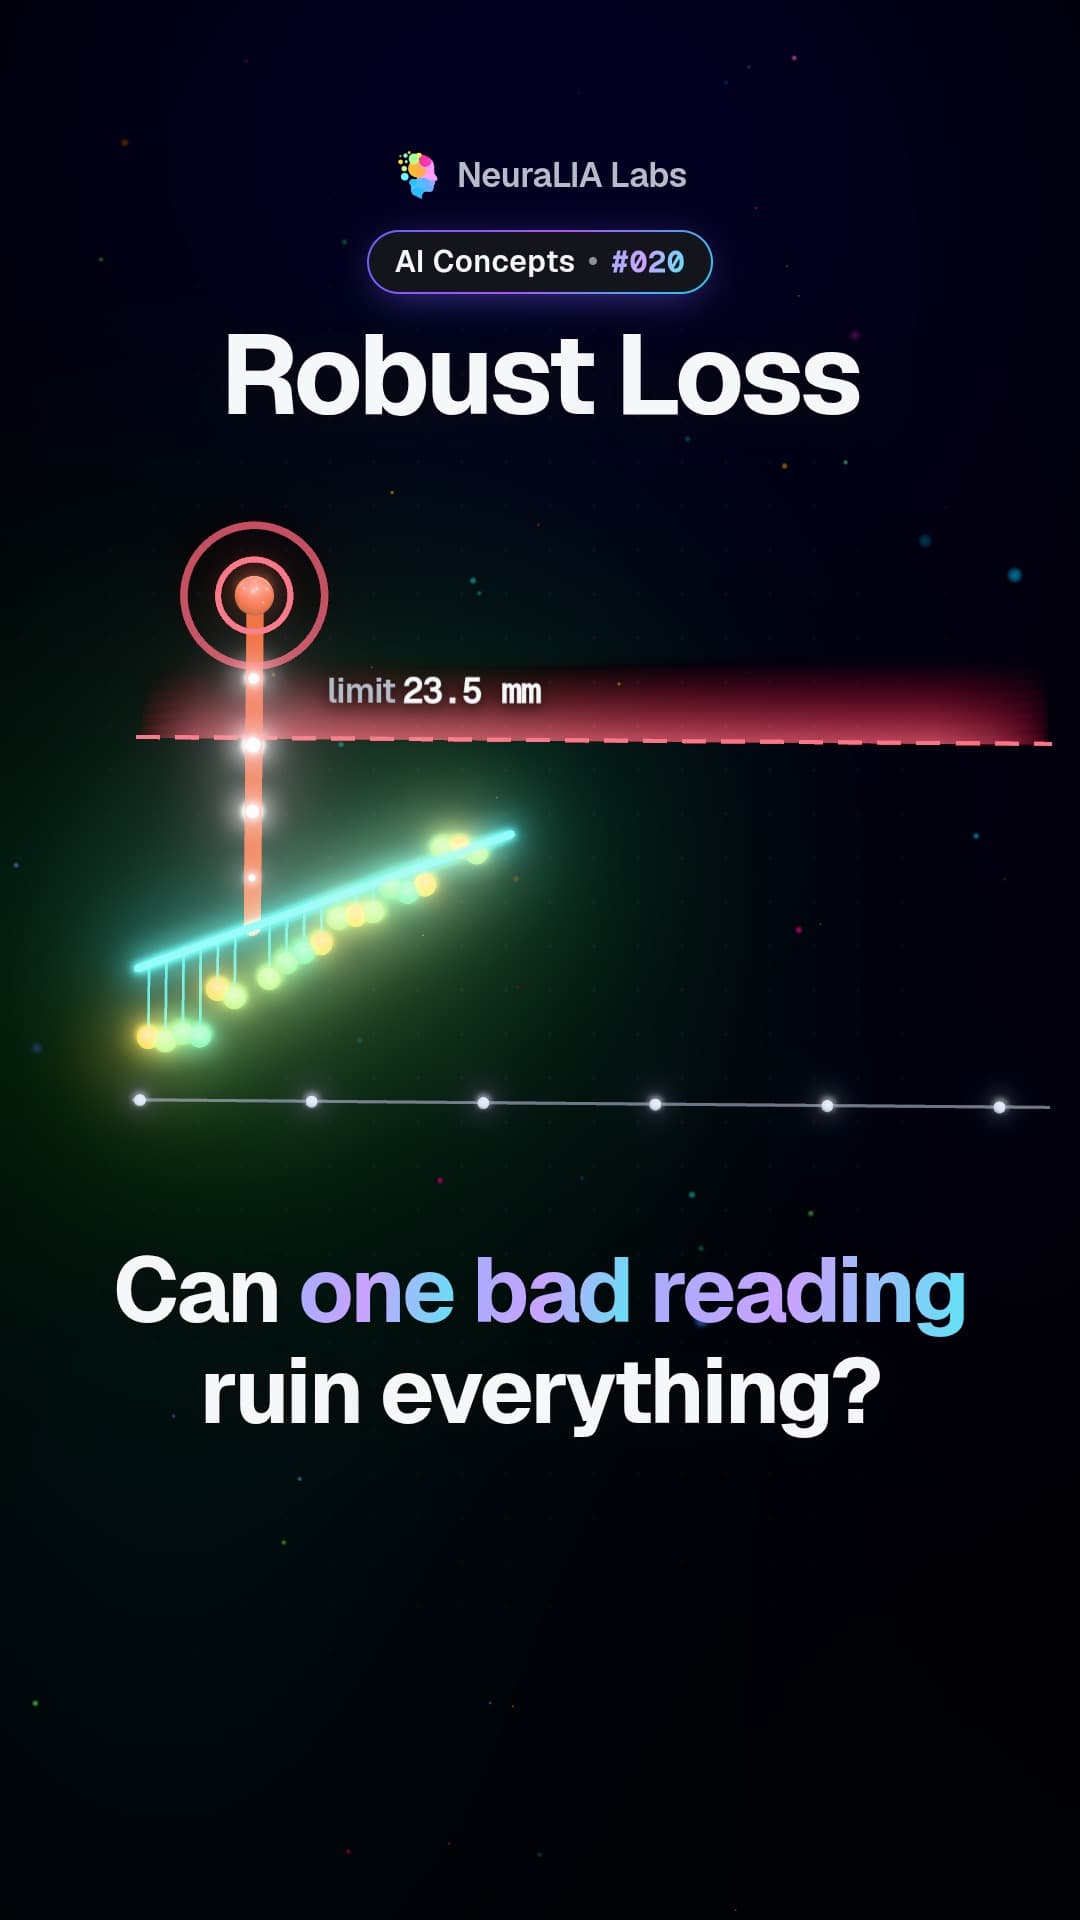 #020
Robust loss: stop one wild reading from wrecking your forecast
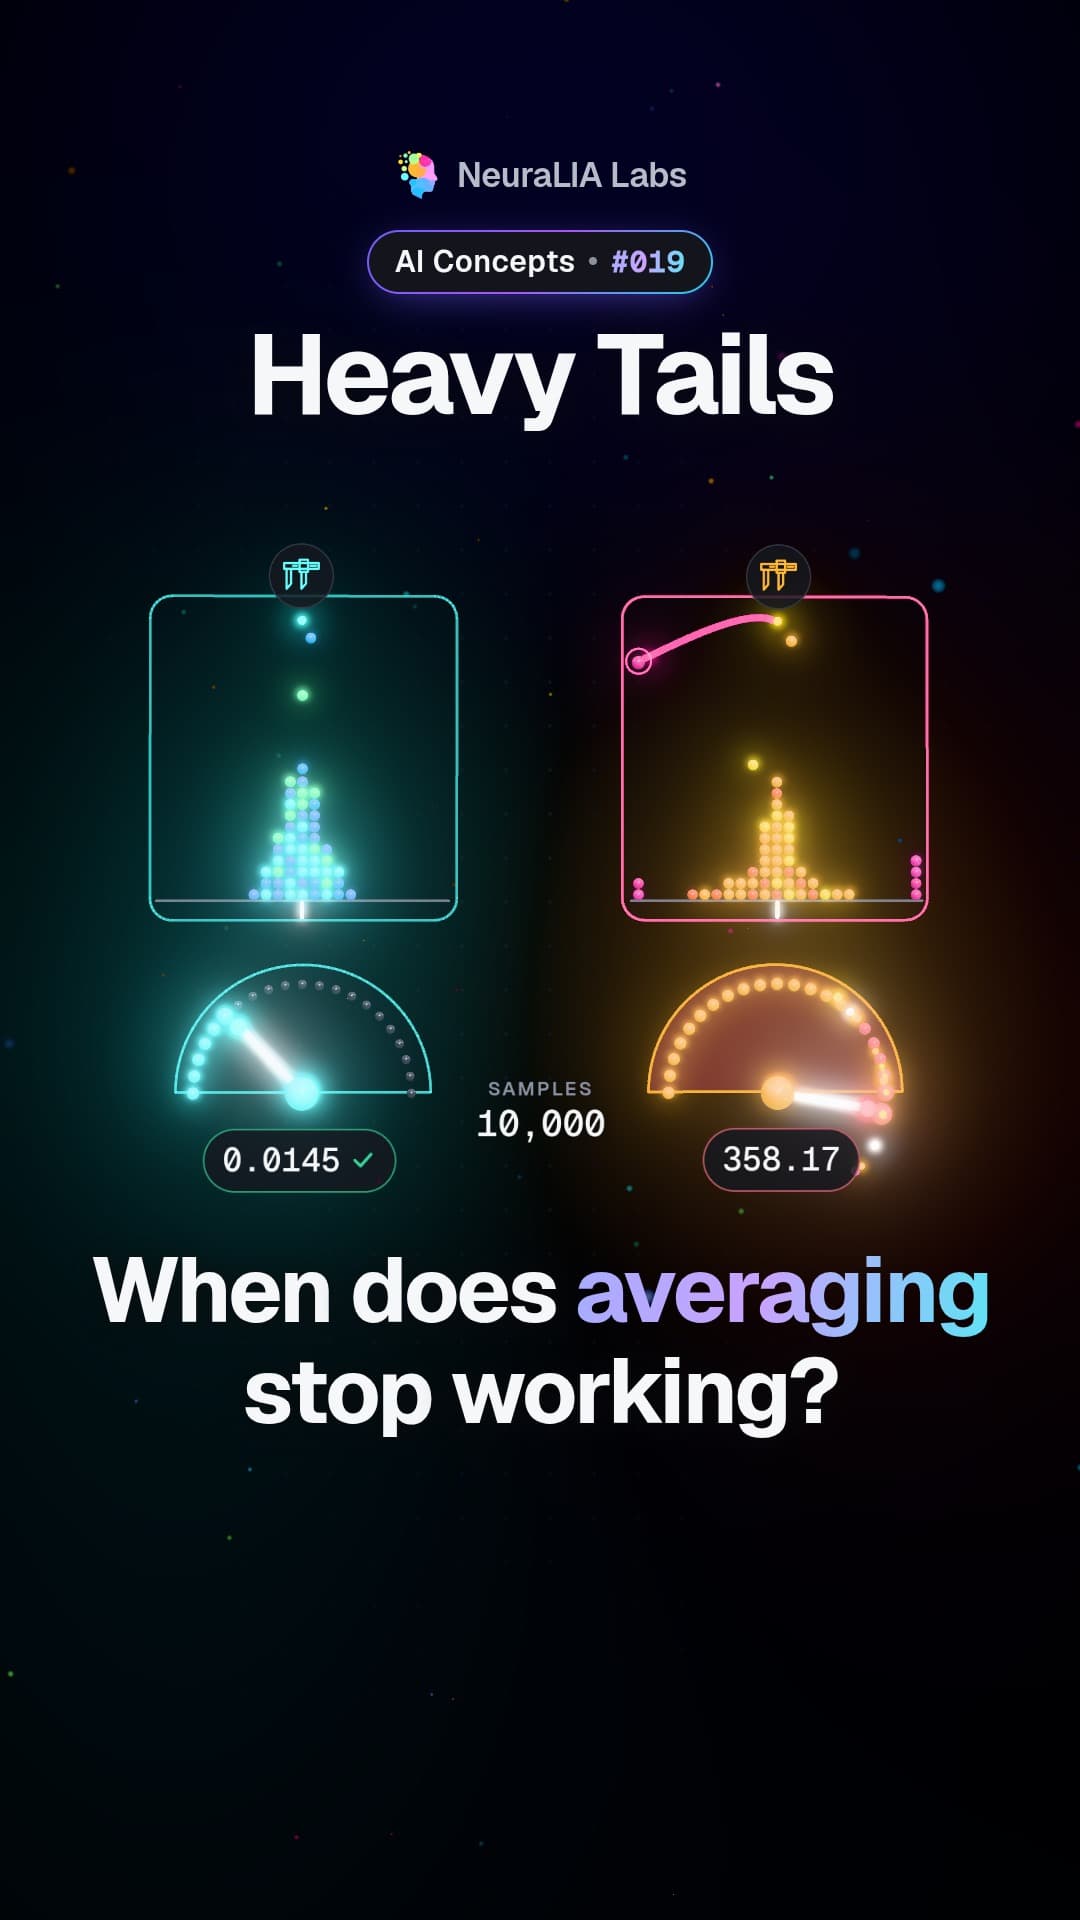 #019
Heavy tails: when rare, huge errors break the usual average
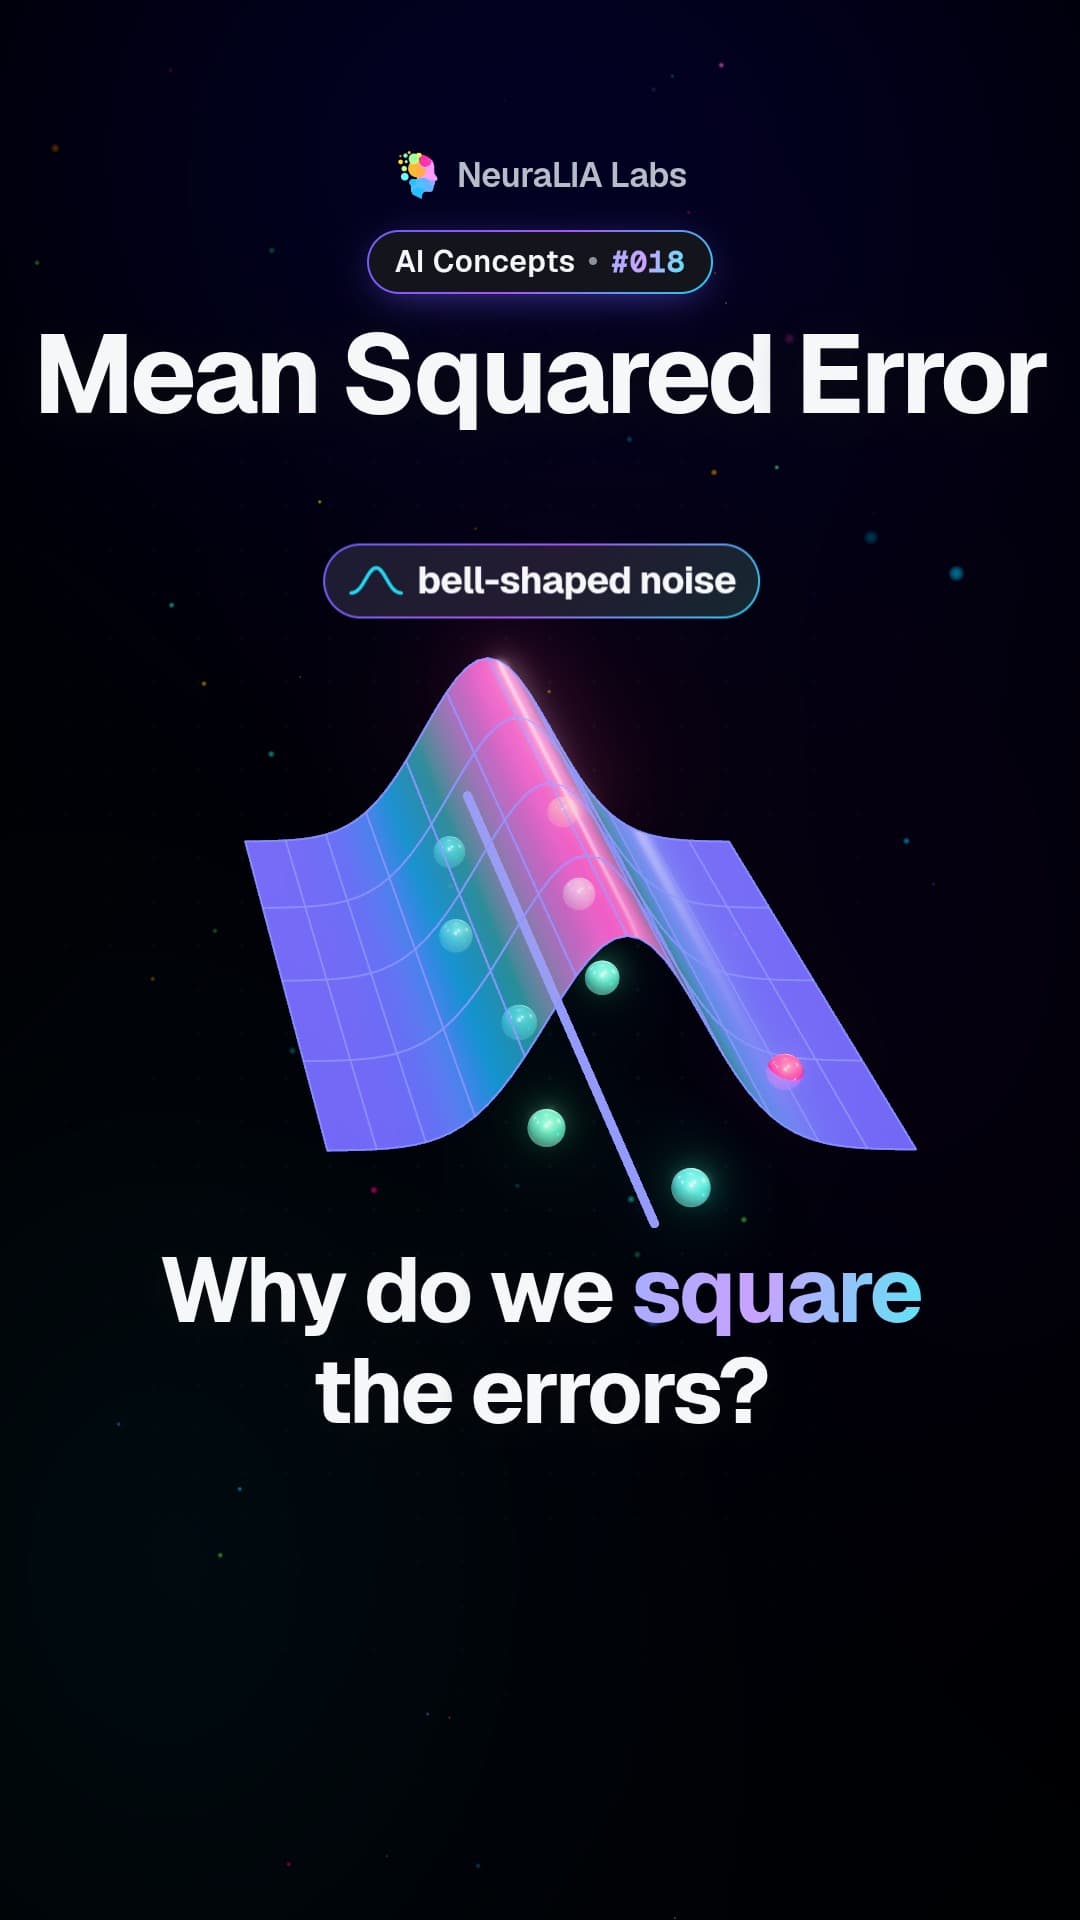 #018
Mean squared error: the hidden bet behind squaring your mistakes
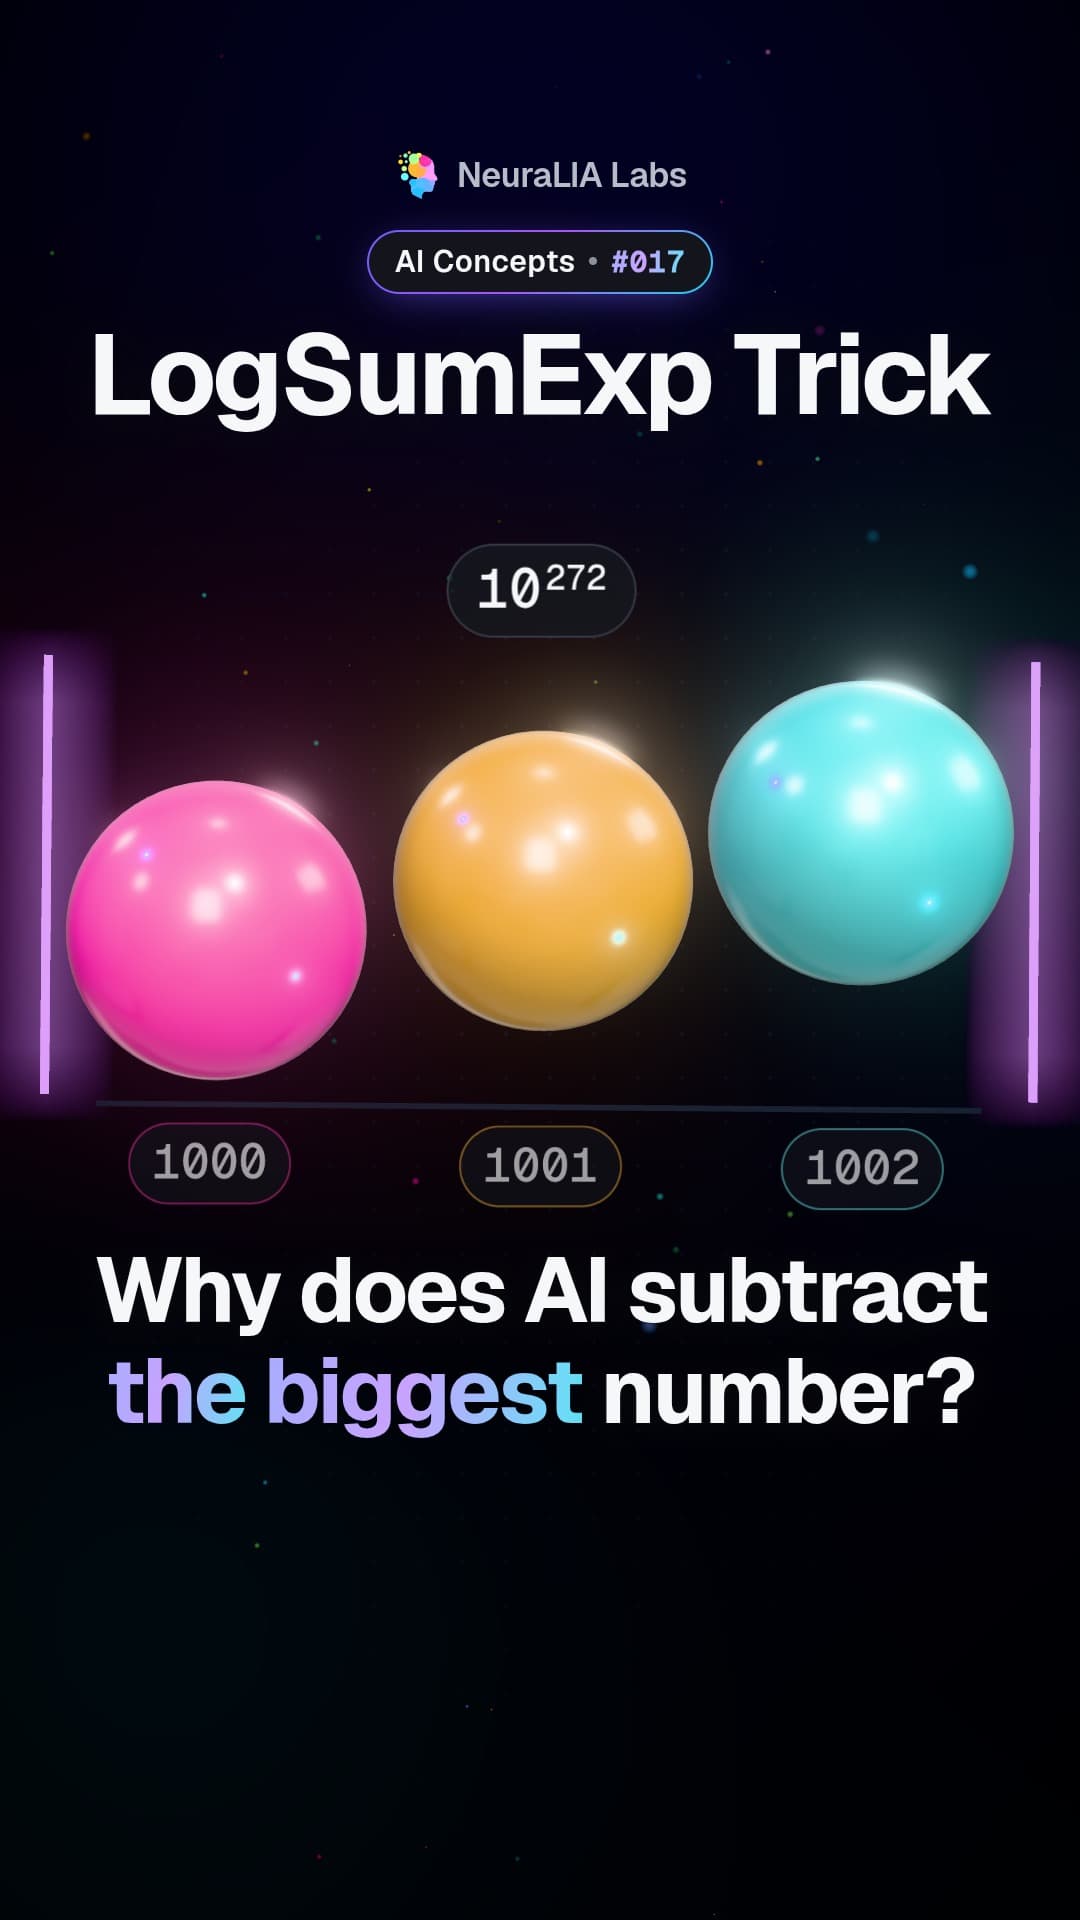 #017
The LogSumExp trick: one subtraction that stops AI math overflowing
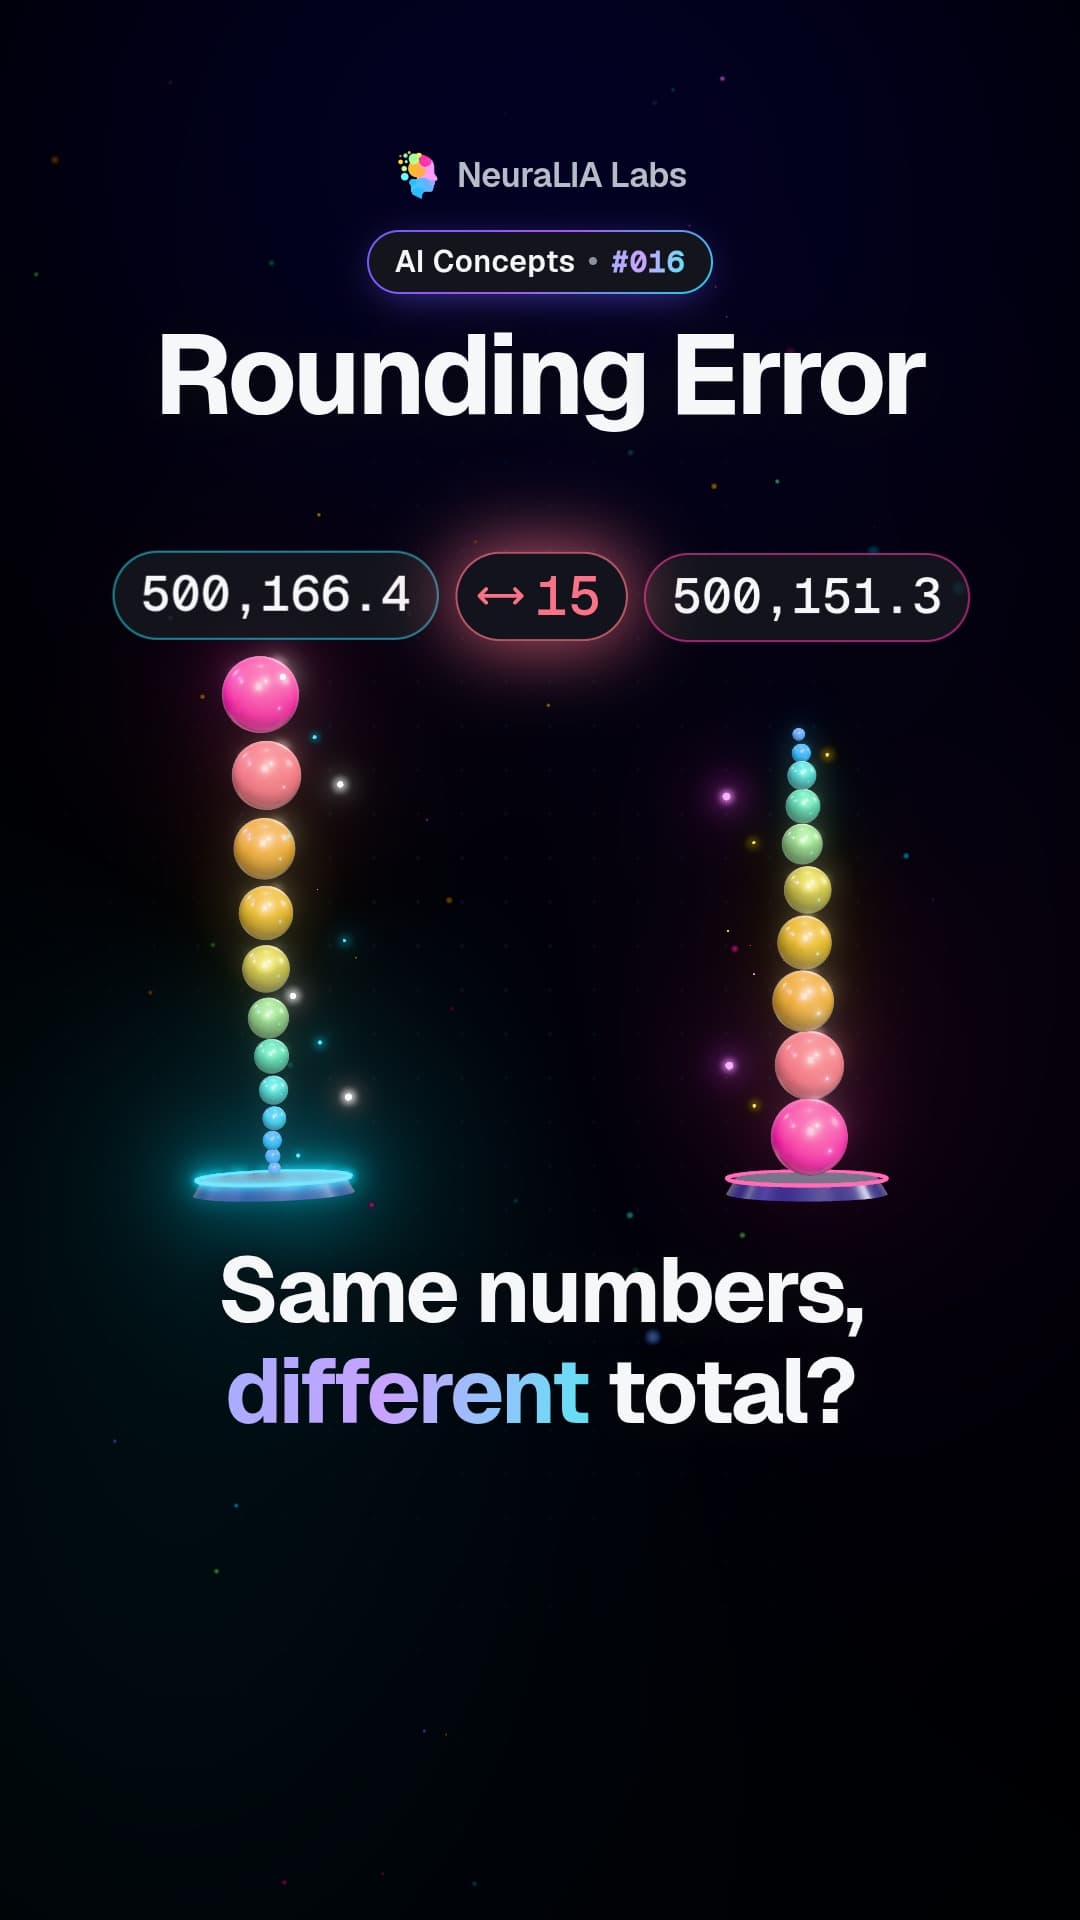 #016
Rounding error: why adding the same numbers can give two answers
 #015
Floating-point numbers: why your computer cannot hold every number
 #014
Negative log-likelihood: turning a fragile product into a calm sum
 #013
Maximum likelihood: the answer that makes your data least surprising
 #012
Bayes' rule: reasoning backwards from a clue to its most likely cause
 #011
Chain rule of probability: how AI scores a sentence word by word
 #010
Loss landscape: training an AI means finding the bottom of a valley
 #009
Loss function: the scoring rule that decides which answer wins
 #008
Feature engineering: the human choice that can beat the algorithm
לפי פרק בקורס
- 1הפרספטרון מאפס: מה נוירון מחשב10 סרטונים
- 2מאיפה מגיעה פונקציית loss: likelihood, לא מוסכמה12 סרטונים
- 3במורד: Gradient Descent, ושני הצעדים שכולם מדלגים עליהם12 סרטונים
- 4סיווג, אנטרופיה צולבת, ואיך לא לעבוד על עצמך
- 5Backpropagation מאפס: קודם המנוע, אחר כך הרשת1 סרטון
- 6לגרום לה להתאמן, ולגרום לה להכליל
- 7בונים BPE Tokenizer: למה המודל שלך לא מצליח לספור R1 סרטון
- 8חיזוי ה-token הבא: embedding, ומה באמת אומרת perplexity1 סרטון
- 9Attention ובלוק ה-Transformer, נגזרים מממוצע
- 10Pretraining ל-LLM: נתונים, חישוב, חוקי scaling ועלות
- 11ממודל בסיס לעוזר: SFT, RLHF, DPO ו-GRPO
- 12Chain of Thought, RLVR ו-Test-Time Compute — במדידה
- 13להוזיל Inference: KV cache, Batching ו-Quantization
- 14קריאת ה-LLM הראשונה שלך בייצור: streaming, ניסיונות חוזרים ו-timeouts
- 15Prompt engineering במדידה: מה באמת משנה את הפלט
- 16ה-context window, ה-tokens והחשבון — במדידה
- 17טמפרטורה, top-p והדטרמיניזם שאין לכם
- 18Tool Calling ופלטים מובנים: החוזה שמחזיק מעמד
- 19RAG בפרודקשן: chunking, אחזור וציטוטים אמינים
- 20Fine-Tuning, אחזור או Prompt? ההחלטה היא כלכלית
- 21תמחור רב־מודלי: על מה באמת משלמים בתמונות, אודיו ווידאו
- 22מהו AI agent: חמישה סוגים קלאסיים ושתי הגדרות יריבות
- 23בנו agent harness: הלולאה וחמש הדרכים לצאת ממנה
- 24Context Engineering: למה ה-agent שלך נעשה פחות חכם בתור 40
- 25תזמור Multi-Agent: חמישה דפוסים, ומתי אחד מנצח
- 26MCP מוסבר מול המפרט: מהו שרת באמת
- 27השקת שרת MCP: TypeScript ו-Python, במדידה
- 28Agent Skills ו-SKILL.md: חשיפה הדרגתית, במדידה
- 29הערכת LLM: מבנצ'מרקים ציבוריים לסט הזהב שלך
- 30Prompt injection והשילוש הקטלני: איך מאבטחים agent אמיתי