
 #01
الفيديوهات
شرح الذكاء الاصطناعي في فيديوهات قصيرة
فكرة واحدة في كل فيديو، بلغة بسيطة. يرتبط كل فيديو بفصل من دورتنا المجانية يشرحها خطوة بخطوة.
ابدأ هنا AI 101
- #01
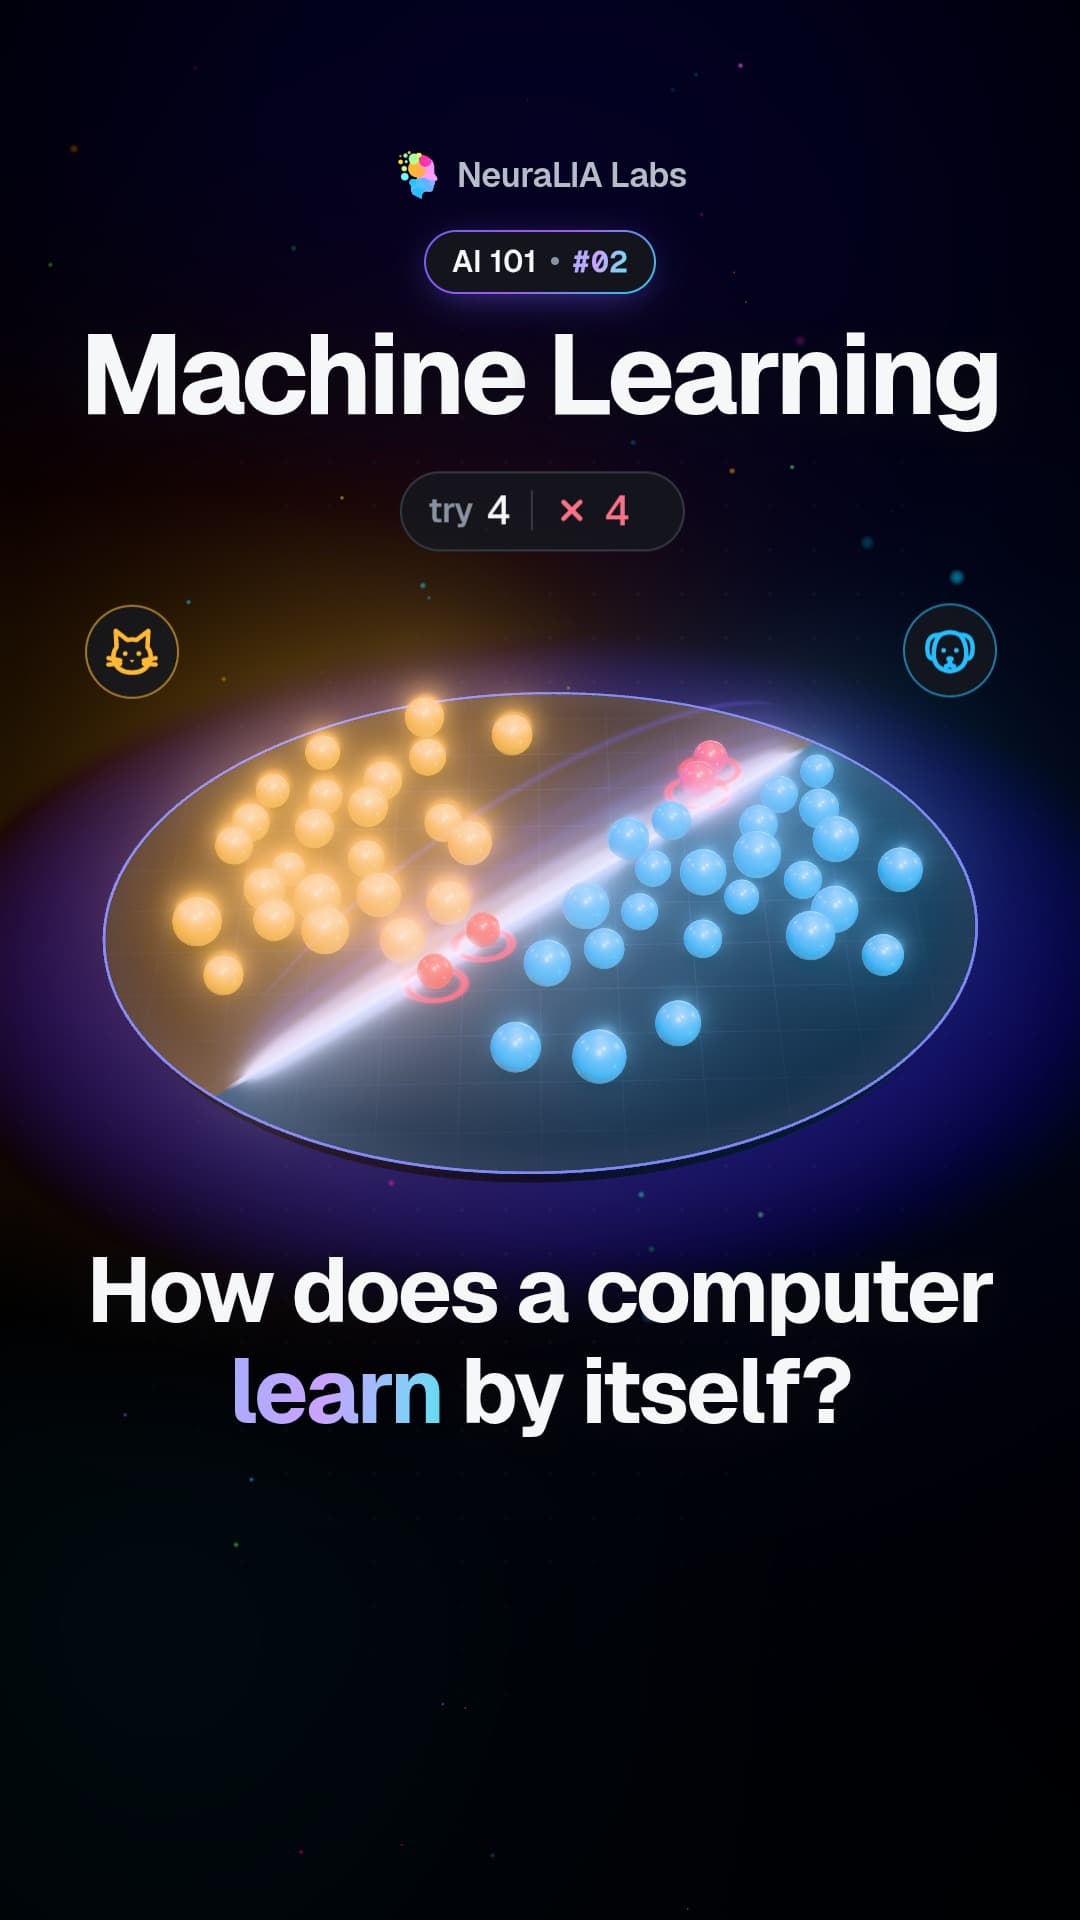 #02
Machine learning: how a computer draws its own dividing line
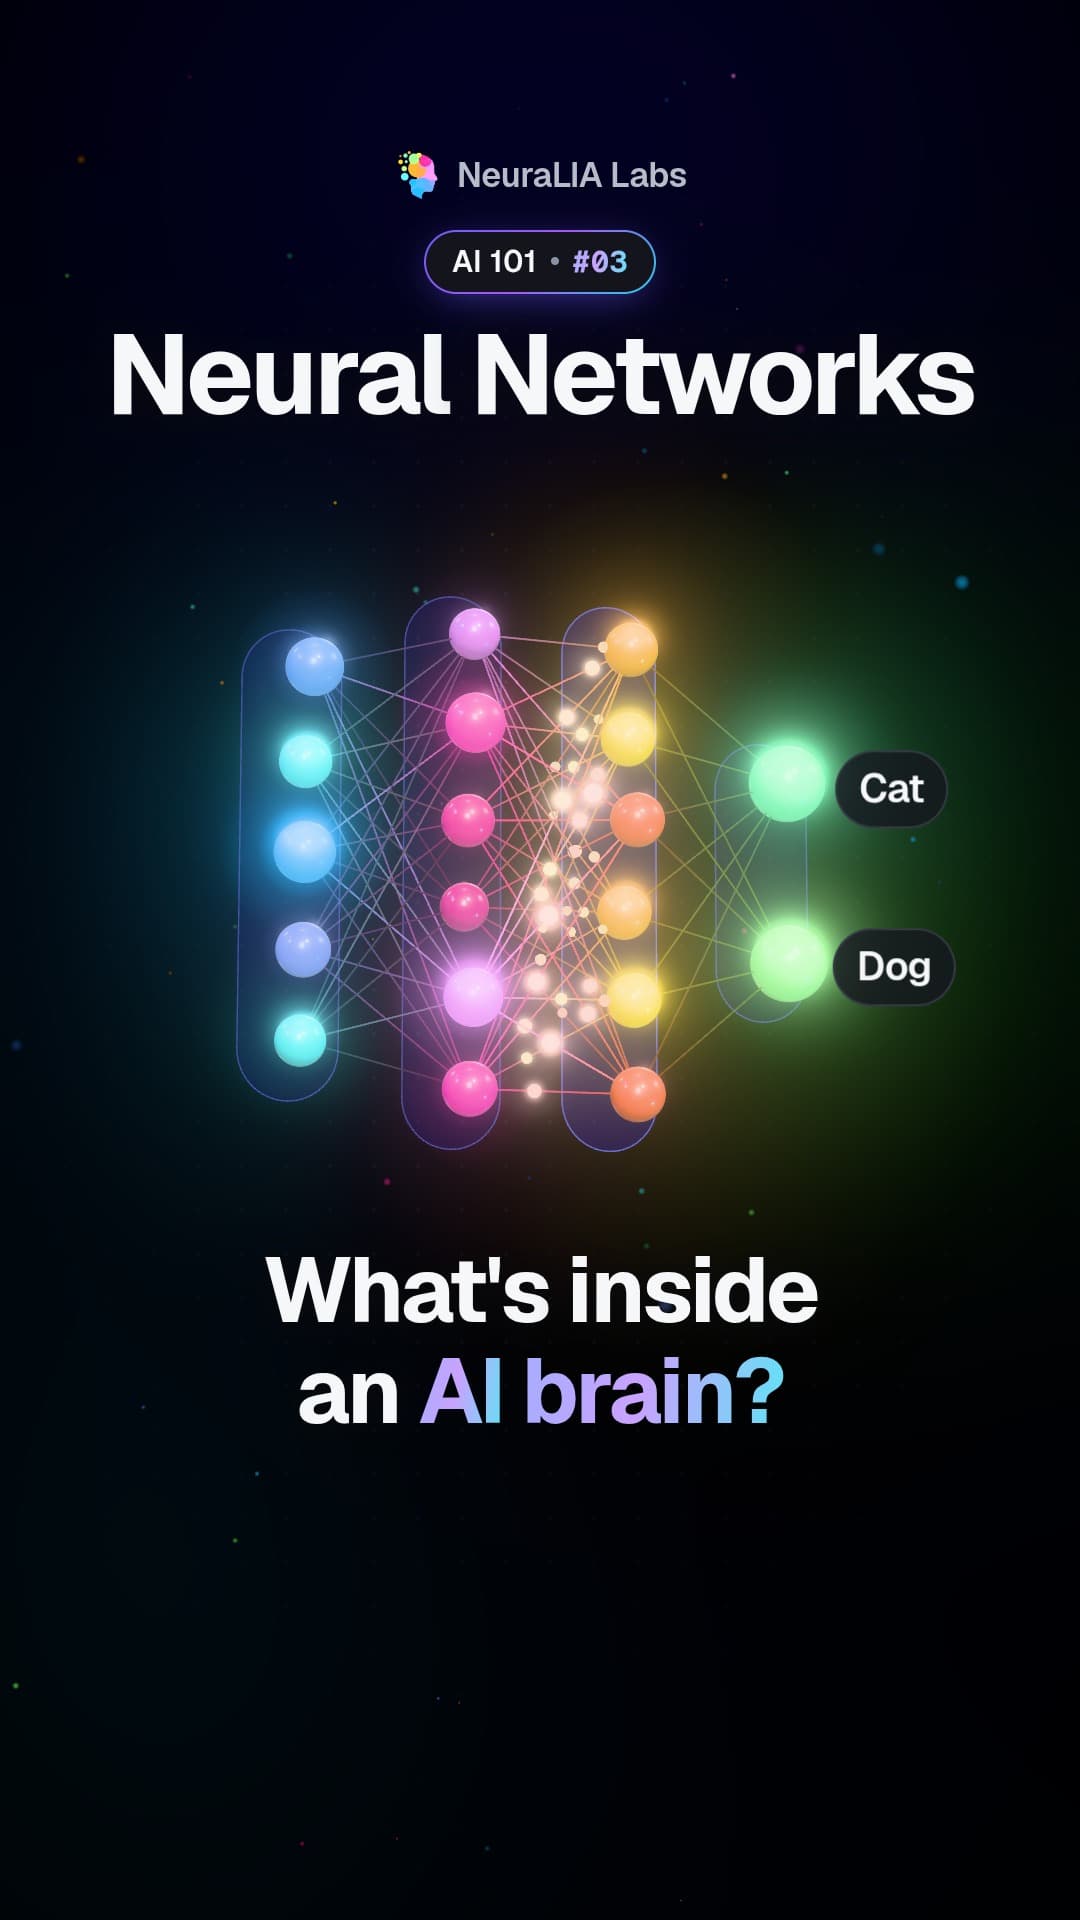 #03
Neural networks: layers of tiny calculators passing signals on
 #04
How AI learns: guess, measure the error, nudge, repeat
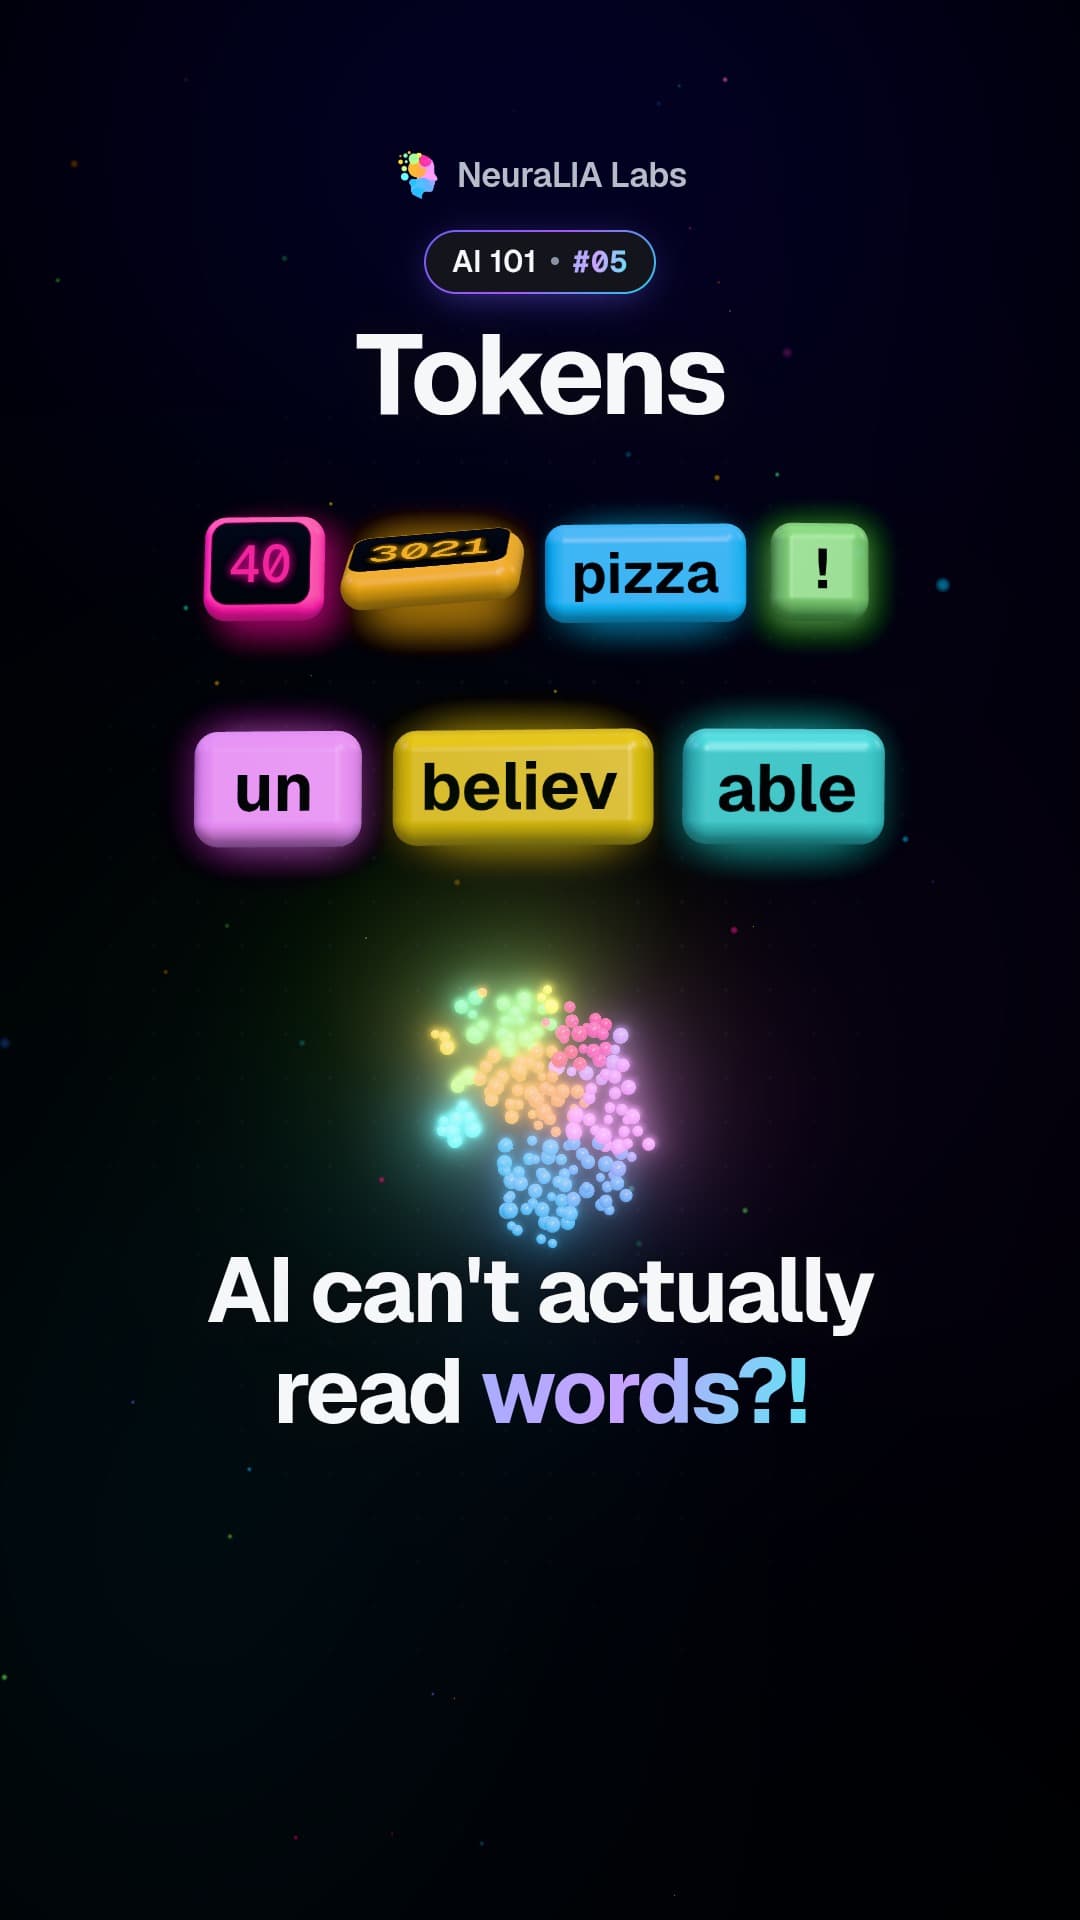 #05
Tokens: how AI chops your words into numbered pieces
 #06
Embeddings: why a puppy lands closer to a dog than to a pizza
الأحدث
 #031
Momentum: how remembering past steps stops AI training zigzagging
 #030
Mini-batches: why AI learns faster from a random handful of data
 #029
Saddle points: where AI training looks stuck but has a way down
 #028
Local minima: why AI training can settle for second best
 #027
Condition number: why a stretched valley makes AI training crawl
 #026
Learning rate: the step size with a ceiling you can calculate
 #025
Gradient descent: how AI finds its way downhill in small steps
 #024
Gradient: the arrow that points uphill, and why AI walks the other way
 #023
Chain rule: how AI traces the effect of every layer
 #022
Derivative: how much the result moves when you nudge one input
 #021
Grid search: why you cannot train an AI by trying every setting
 #020
Robust loss: stop one wild reading from wrecking your forecast
 #019
Heavy tails: when rare, huge errors break the usual average
 #018
Mean squared error: the hidden bet behind squaring your mistakes
 #017
The LogSumExp trick: one subtraction that stops AI math overflowing
 #016
Rounding error: why adding the same numbers can give two answers
 #015
Floating-point numbers: why your computer cannot hold every number
 #014
Negative log-likelihood: turning a fragile product into a calm sum
 #013
Maximum likelihood: the answer that makes your data least surprising
 #012
Bayes' rule: reasoning backwards from a clue to its most likely cause
 #011
Chain rule of probability: how AI scores a sentence word by word
 #010
Loss landscape: training an AI means finding the bottom of a valley
 #009
Loss function: the scoring rule that decides which answer wins
 #008
Feature engineering: the human choice that can beat the algorithm
حسب فصل الدورة
- 1الـ Perceptron من الصفر: ما الذي يحسبه العصبون؟10 مقاطع فيديو
- 2من أين تأتي دالة الخسارة: من الأرجحية، لا من العرف12 مقطع فيديو
- 3إلى أسفل الوادي: Gradient Descent والخطوتان اللتان يتخطاهما الجميع12 مقطع فيديو
- 4التصنيف، الإنتروبيا المتقاطعة، وكيف لا تخدع نفسك
- 5Backpropagation من الصفر: المحرك أولًا، ثم الشبكة1 مقطع فيديو
- 6جعله يتدرّب، وجعله يعمّم
- 7ابنِ BPE Tokenizer: لماذا لا يستطيع نموذجك عدّ حروف R؟1 مقطع فيديو
- 8التنبؤ بالـ token التالي: Embeddings، وما تعنيه Perplexity1 مقطع فيديو
- 9Attention وكتلة Transformer، مشتقان من المتوسط
- 10التدريب المسبق لـ LLM: البيانات والحوسبة وقوانين التوسع والتكلفة
- 11من Base Model إلى Assistant: SFT وRLHF وDPO وGRPO
- 12Chain of Thought وRLVR وTest-Time Compute، بالأرقام
- 13جعل inference رخيصًا: KV cache وbatching والتكميم
- 14أول استدعاء LLM في الإنتاج: البث، إعادة المحاولة، المهل الزمنية
- 15Prompt Engineering بالأرقام: ما الذي يغيّر المخرجات
- 16Context Window وtokens والفاتورة، بالأرقام
- 17Temperature وTop-p والحتمية التي لا تملكها
- 18Tool Calling والمخرجات المنظَّمة: العقد الذي يصمد
- 19RAG في الإنتاج: Chunking والاسترجاع والاستشهادات الصادقة
- 20Fine-Tune أم استرجاع أم Prompt؟ القرار اقتصادي
- 21تسعير Multimodal: ما الذي تُحاسَب عليه الصور والصوت والفيديو فعلاً
- 22ما هو AI Agent: خمسة أنواع كلاسيكية وتعريفان متنافسان
- 23ابنِ Agent Harness: الحلقة وخمس طرق للخروج منها
- 24Context Engineering: لماذا يصبح agent لديك أغبى عند الدور 40
- 25تنسيق multi-agent: خمسة أنماط، ومتى يفوز أحدها
- 26شرح MCP وفق المواصفة: ما هو الخادم حقًا
- 27إطلاق خادم MCP: TypeScript وPython بالأرقام
- 28Agent Skills و SKILL.md: الإفصاح التدريجي، بالأرقام
- 29تقييم LLM: من benchmarks العامة إلى مجموعتك الذهبية
- 30حقن prompt والثلاثية القاتلة: تأمين agent حقيقي