
 #174
Este vídeo y su texto están en inglés.
AWQ: giving an AI's most important numbers VIP treatment
AWQ shrinks an AI model while protecting the few numbers that matter most. Learn how it finds them by watching real inputs, with a photo-shrinking example.
En detalle
What AWQ is
AWQ, short for activation-aware weight quantization, is a way to shrink a large AI model so it needs less memory. Shrinking here means rounding the model's learned numbers, its weights, to fewer digits. Rounding always loses a little detail. AWQ starts from a simple observation: not every weight matters equally. A small share of them matter far more than the rest, so AWQ makes sure those lose as little detail as possible.
The word "activation-aware" is the key. Activations are the signals that flow through the model while it is working on real text. AWQ looks at those signals to decide which weights deserve extra care, instead of judging the weights on their own.
What the video shows
The video shows the idea in two steps. First, the method watches the model handle real inputs to spot the small group of numbers that matter most. Then it protects those numbers before rounding everything down, so they keep more of their detail than the rest.
An everyday example
Imagine shrinking a group photo so it sends quickly over a slow connection. You would happily let the sky and the wall behind everyone turn a bit blocky, as long as the faces stay sharp. The faces are a small part of the picture, but they are what people look at.
AWQ treats a model the same way. Most of its numbers can take some rough rounding. A few are the faces: they carry much of what the model does. And just like with the photo, you find the faces by looking at what actually matters when the thing is used, not by staring at the pixels one by one.
How it works
- Watch real inputs. AWQ passes a small sample of real text through the model, called a calibration set, and records how strong the signals are.
- Find the important channels. A channel is a group of weights tied to one of those signals. Where the incoming signal is strong, those weights have a bigger say in the result, so their rounding errors hurt more.
- Enlarge them before rounding. Those channels are scaled up before the rounding happens, so they land on finer levels and lose less detail.
- No retraining. It needs the calibration sample but no gradients, the learning signals used when a model is trained.
Why does enlarging help? Imagine a ruler marked only in whole centimetres. A tiny screw measured with it comes out as either 0 or 1 cm. Photocopy the screw at four times its size, measure the copy, divide by four, and your reading is four times finer. Scaling up the important weights before rounding plays the same trick.
Why it matters
Shrinking is what lets a large model run on smaller, cheaper hardware, and the weights AWQ produces are built for graphics cards (GPUs). The cost of shrinking is lost detail. AWQ's lesson is that the loss does not have to be spread evenly. If you know which few numbers carry the most, you can spend your precision there. Its sibling GPTQ fixes errors as it goes; AWQ decides up front who gets the VIP treatment.
Learn it step by step in Chapter 13 of our free course AI From Scratch: Making Inference Cheap: KV Cache, Batching and Quantization.
También en
Más de este capítulo
- #174
 #175
Prefill vs decode: why a chatbot pauses first, then streams smoothly
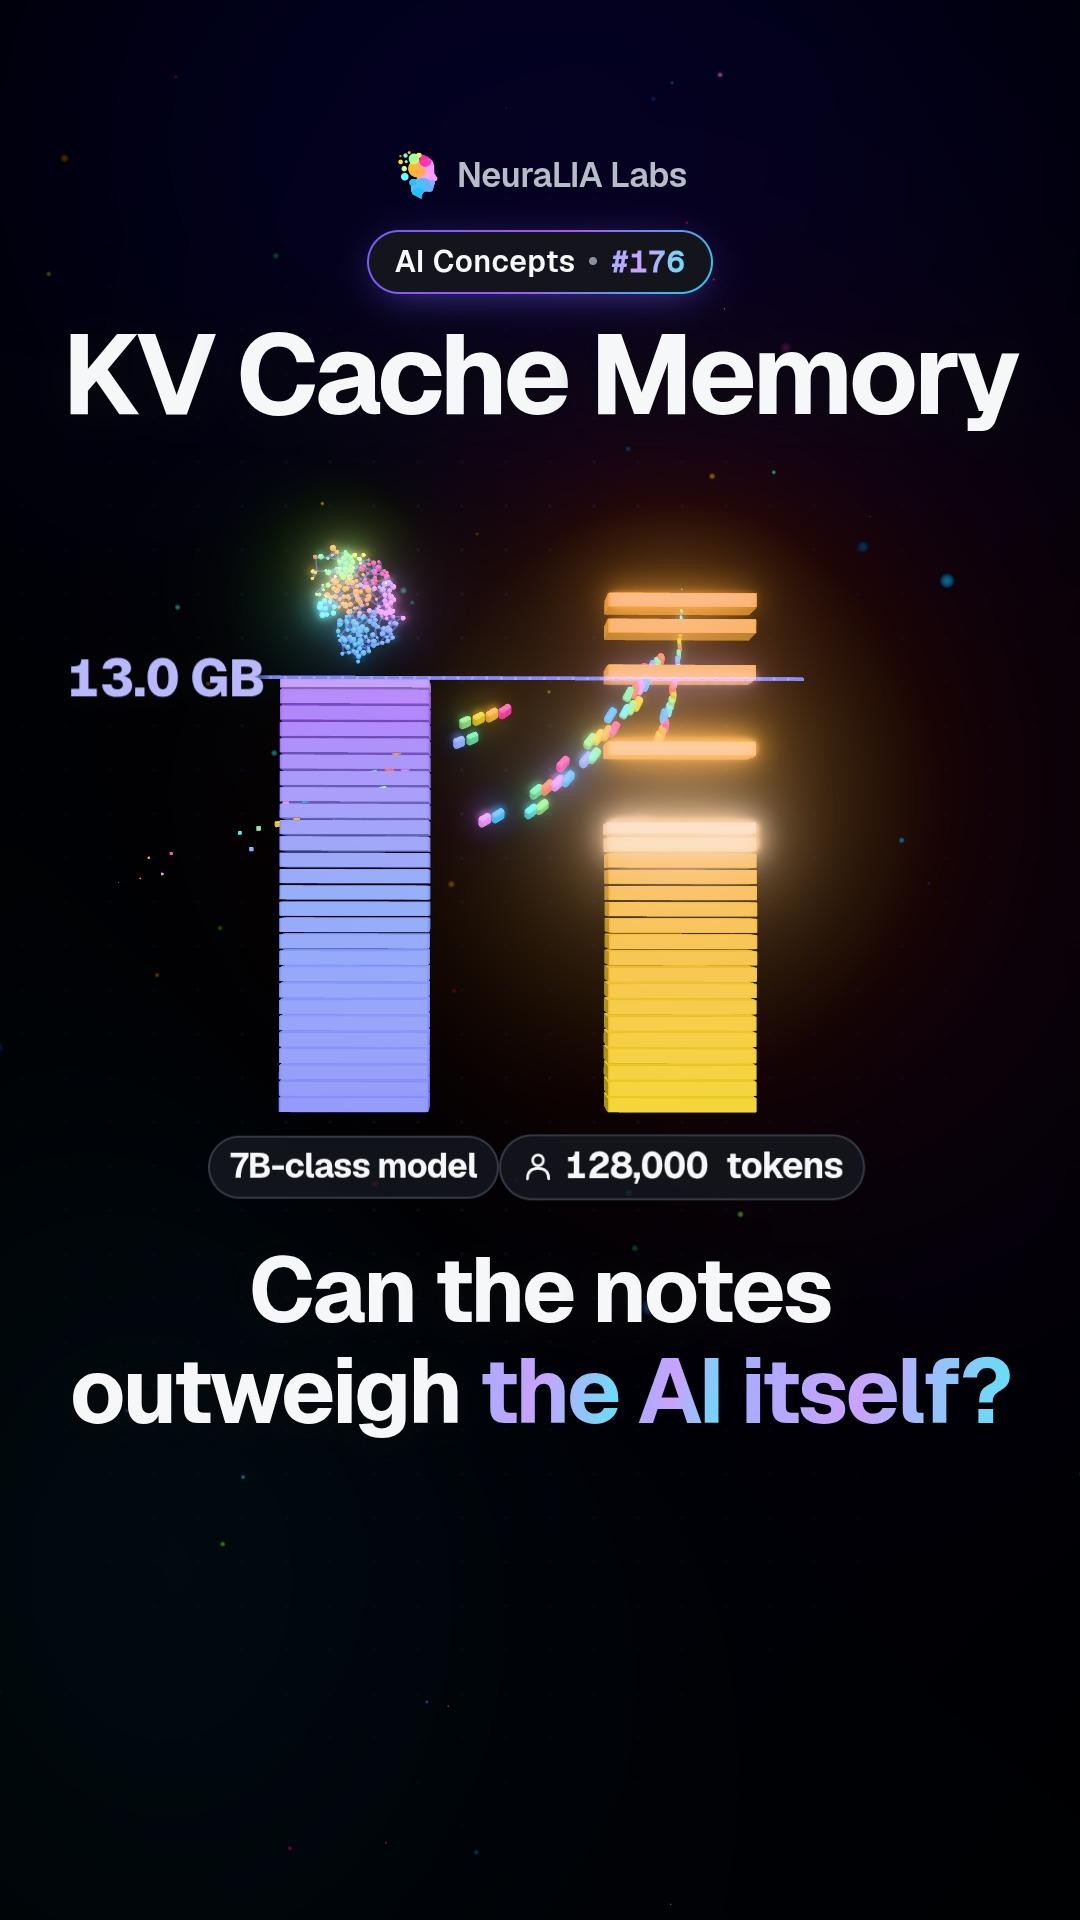 #176
KV cache memory: when a chatbot's notes outgrow the model itself
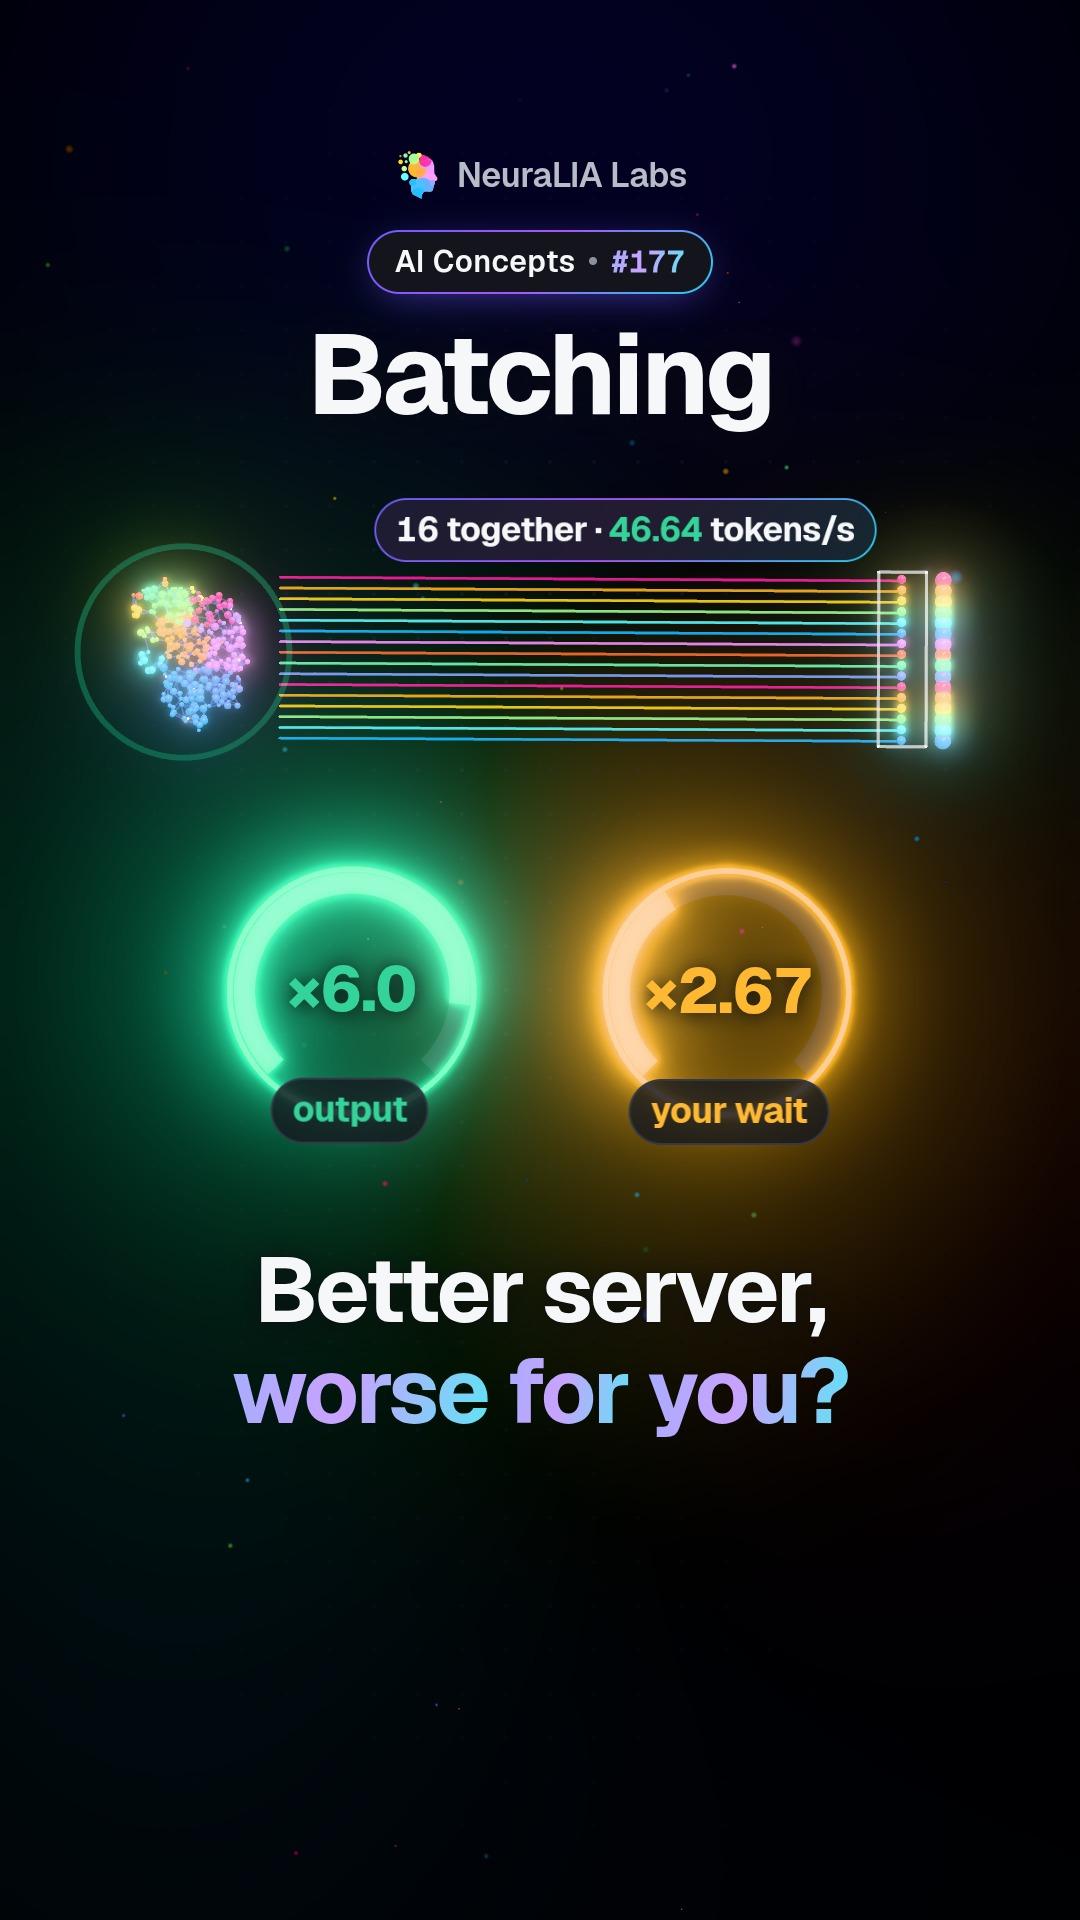 #177
Batching: more output per second, but a longer wait for each user
 #178
Continuous batching: no more waiting for the slowest reply
 #179
PagedAttention: the parking-lot trick behind busy AI servers
Texto escrito con ayuda de IA a partir del capítulo 13 de nuestro curso gratis.