
 #174
Este vídeo y su texto están en inglés.
Batching: more output per second, but a longer wait for each user
Serving many requests together multiplies what an AI server produces, but every user waits longer. Learn the trade-off and where extra grouping stops paying.
En detalle
What batching is
Batching means an AI server works on several people's requests in the same step, instead of one at a time. It pays off because of how a model writes. For every new token (a word or a piece of a word), the server has to pull all of the model's weights, the numbers it learned in training, out of memory. That trip is the slow part. The actual calculation for one token is small. So if the weights have to travel anyway, the server might as well use that trip for many requests at once.
What the video shows
In the course's test, the server went from handling 1 request at a time to 16 at once. Its total output rose six times. But each step took 2.67 times longer, so every individual person waited longer for each new word. And past a certain point, adding more requests to the group stopped helping.
An everyday example
Think of a taxi versus a bus. A taxi takes one passenger straight to where they want to go. A bus carries forty people on one trip, which is far cheaper per passenger, but each rider waits while others get on and off. The city moves more people; each person travels a bit slower. Batching turns an AI server from a taxi into a bus.
How it works: two numbers pulling apart
Batching trades between two measures:
- Latency: how long one person waits for their reply. This is what users feel.
- Throughput: how many tokens the server produces per second, counting everyone. This is what the bill gets divided by.
Here is what the course measured, with each request decoding one token per step:
| Requests at once | Tokens per second | Wait per step compared with 1 request | |---|---|---| | 1 | 7.8 | 1.00x | | 16 | 46.6 | 2.67x | | 32 | 50.8 | 4.90x |
The course is blunt about it: no setting improves both numbers. A bigger group means a cheaper server and slower replies.
Where it stops paying
Going from 16 to 32 requests raised output by only about 9%, while the wait per step nearly doubled. At that point the server is no longer held back by moving weights around. It is held back by the calculation itself, so a bigger group buys almost nothing. The course calls this turning point the knee. Every deployment has one, but where it sits has to be measured on your own hardware.
A common misconception
It is tempting to treat the extra wait as a bug that better tuning will remove. According to the course, it is not. The slower reply is the price of the higher output, and every batch size simply picks a different point on that trade.
Why it matters
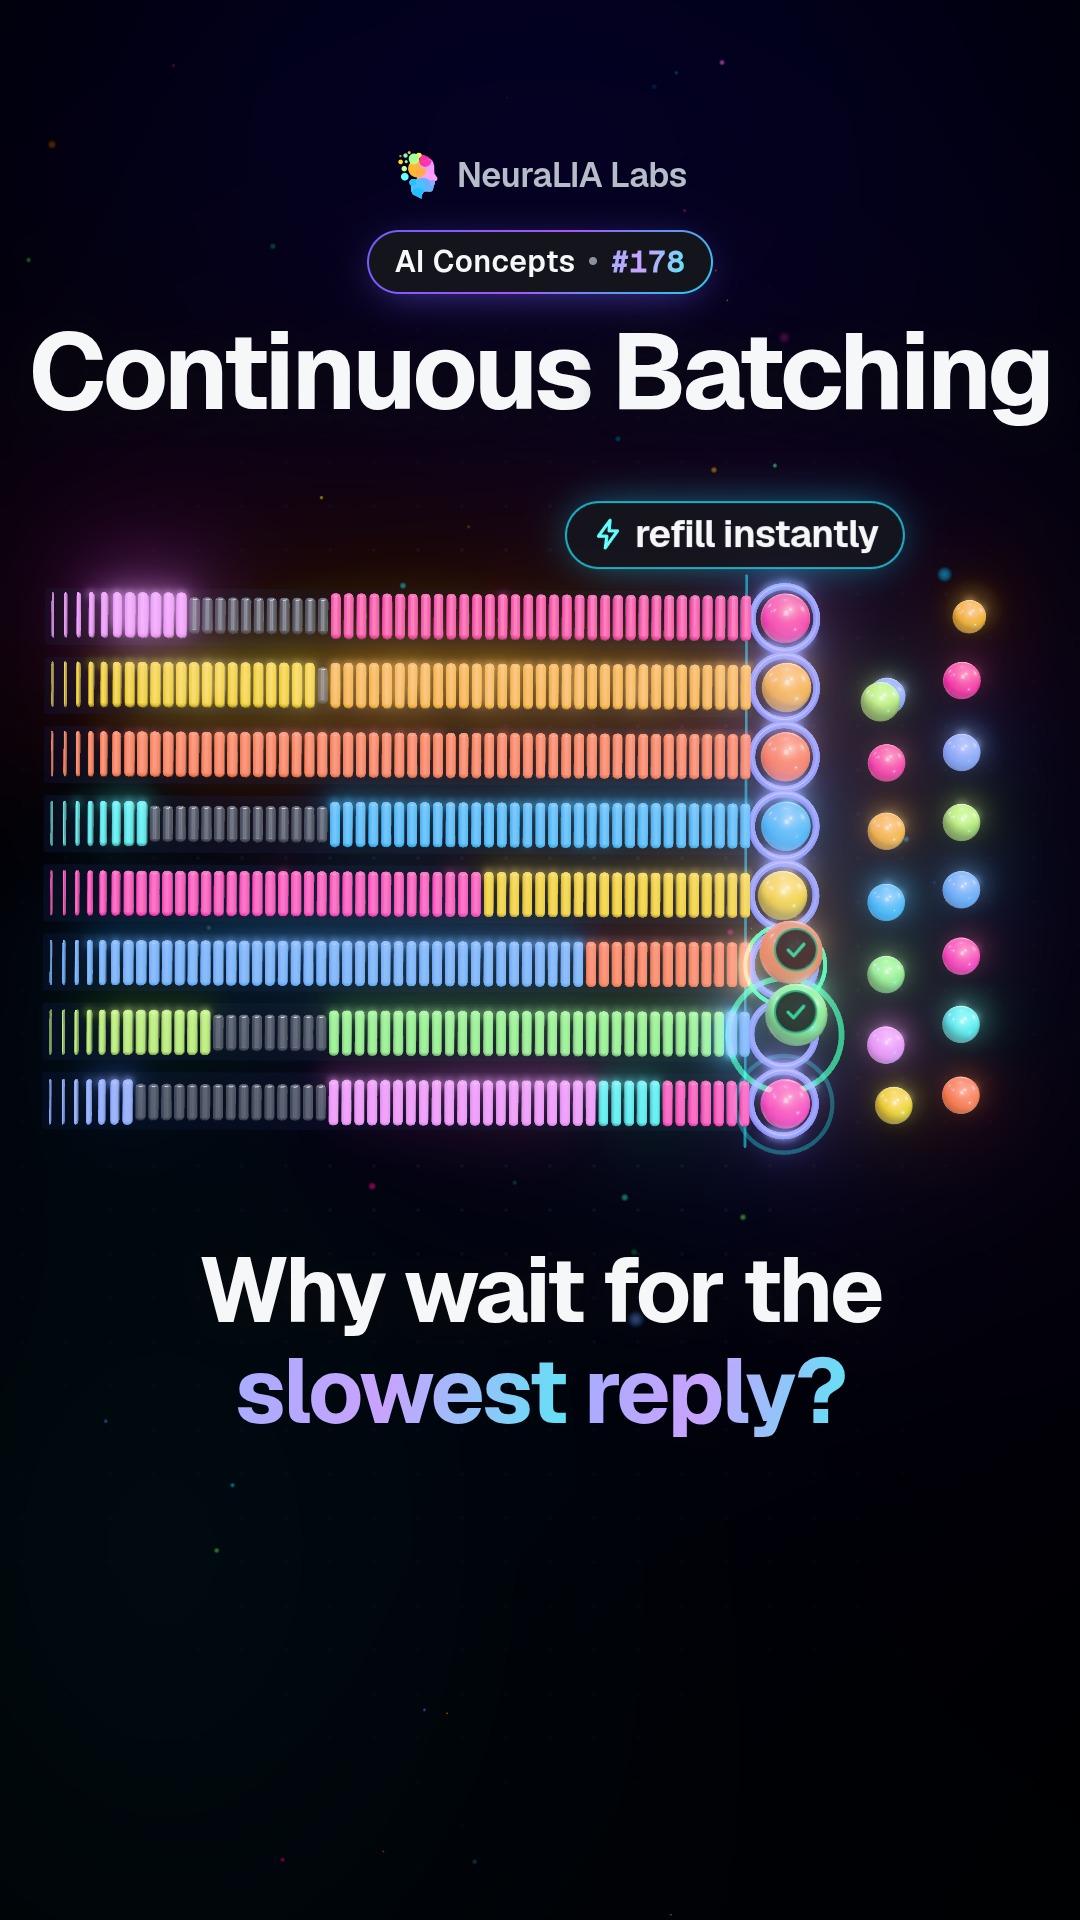
Batching is how a server spreads its cost across many users. It also explains why the right batch size is a business decision, not just a technical one: you choose where to sit between cheap and fast. The next idea in this chapter, continuous batching, makes the grouping itself much smarter.
Learn it step by step in Chapter 13 of our free course AI From Scratch: Making Inference Cheap: KV Cache, Batching and Quantization.
También en
Más de este capítulo
Texto escrito con ayuda de IA a partir del capítulo 13 de nuestro curso gratis.