
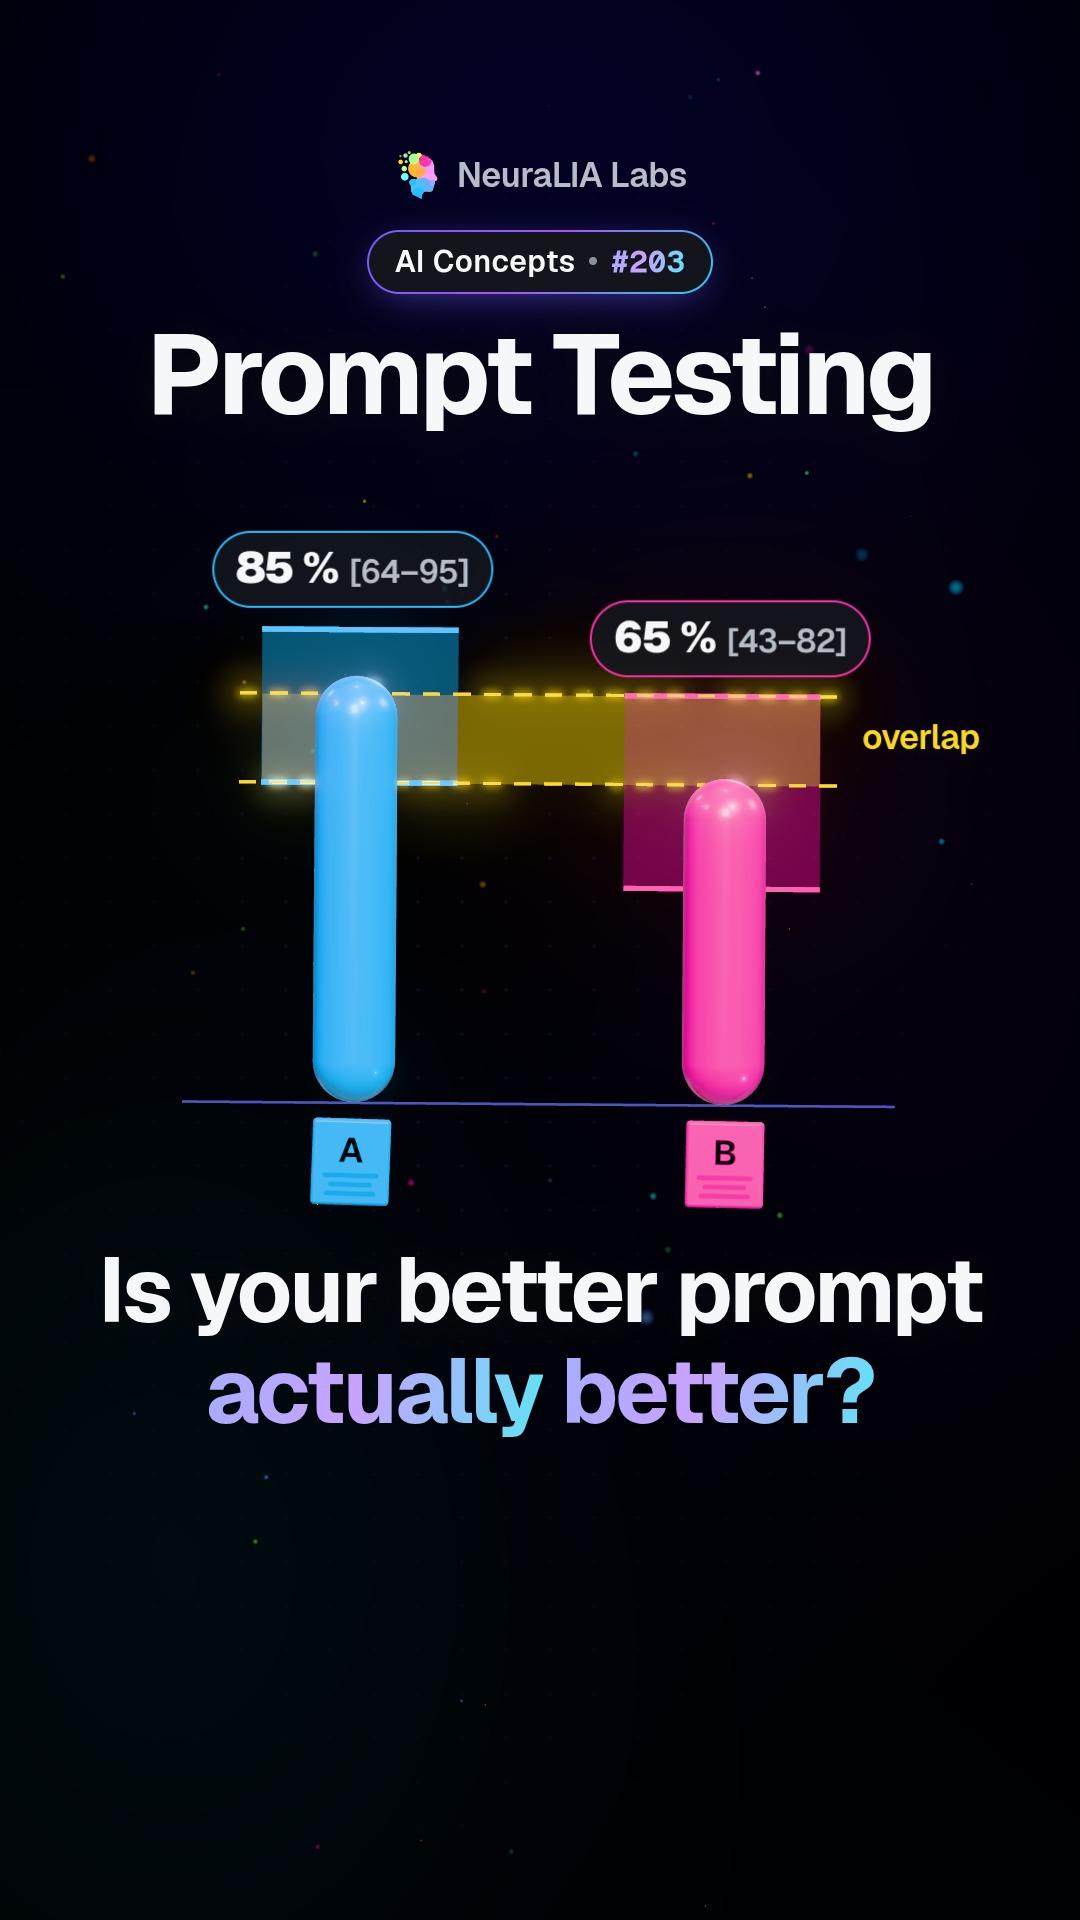
 #203
Toto video a jeho text jsou v angličtině.
Prompt myths: what tips, pep talks and threats did in a real test
Offering an AI a $200 tip or calling it an expert did nothing measurable in a 60-case test, while a threat cut accuracy by 35 points. What it means for you.
Podrobně
What prompt myths are
The internet is full of one-line tricks that supposedly make a chatbot smarter. Tell it to take a deep breath. Say your career depends on the answer. Call it a world-class expert. Promise it a tip. These are prompt myths: sentences that spread because they sound plausible and are easy to share, not because anyone measured them. A prompt is simply the text you send to an AI model, and adding one more sentence costs nothing, so people pile them on "just in case".
What the video shows
The video asks whether tipping your AI actually works, and answers with the course's own test. Offering a tip, asking the AI to breathe or calling it an expert made no measurable difference. Threatening it with a penalty did make a difference, in the wrong direction: accuracy fell by 35 percentage points, from about 77% of answers right to about 42%.
How the test worked
The course used one small AI model and one job: reading customer support tickets and sending each one to the right queue. There were 60 tickets with known correct answers. Each trick was added as a single sentence to the model's standing instructions (the system prompt, the part that sets the rules for the whole conversation). Everything else stayed identical.
| Sentence added | Correct out of 60 | |---|---| | Nothing (the starting point) | 46 | | Take a deep breath | 47 | | This is very important to my career | 46 | | Calling it a world-class support expert | 42 | | A $200 tip for a correct answer | 41 | | A penalty for every ticket in the wrong queue | 25 |
The expert and the tip look slightly worse. But the course compared each version with the original ticket by ticket, and those small drops are too small to separate from luck. The threat is different: 24 tickets that had been right went wrong, and only 3 went the other way.
The result that looks like nothing
The "career" sentence kept exactly the same score, 46 out of 60. Yet 10 of the 60 answers changed: five went from wrong to right and five from right to wrong. One number said "no effect" while a sixth of the answers had shifted. If you judge a prompt change by a single average on a small test, it can look free when it is not.
An everyday example
Imagine a cold remedy that everyone in your office swears by. Some people took it and felt better, so the story spreads. The only way to know if it works is to compare people who took it with people who did not, on the same kind of cold. Prompt tricks are the same: a sentence that "worked for me once" is a story, not a result.
A fair caveat
These sentences were tested on one small model and one task, so this is not a verdict on every AI. "Take a deep breath" first came from an automated search for high-scoring instructions, which is a narrower claim than the viral version. What does carry over is the method, not the list.
Why it matters
- Four of the five tricks tested did nothing measurable, so in this test they were only clutter.
- Emotional wording is not neutral. It can push the model's answers, sometimes hard, and you cannot tell which way by reading the sentence.
- The habit that works: test any new sentence on your own cases before you keep it.
Learn it step by step in Chapter 15 of our free course AI From Scratch: Prompt Engineering, Measured: What Changes the Output.
Také na
Další z této kapitoly
- #203
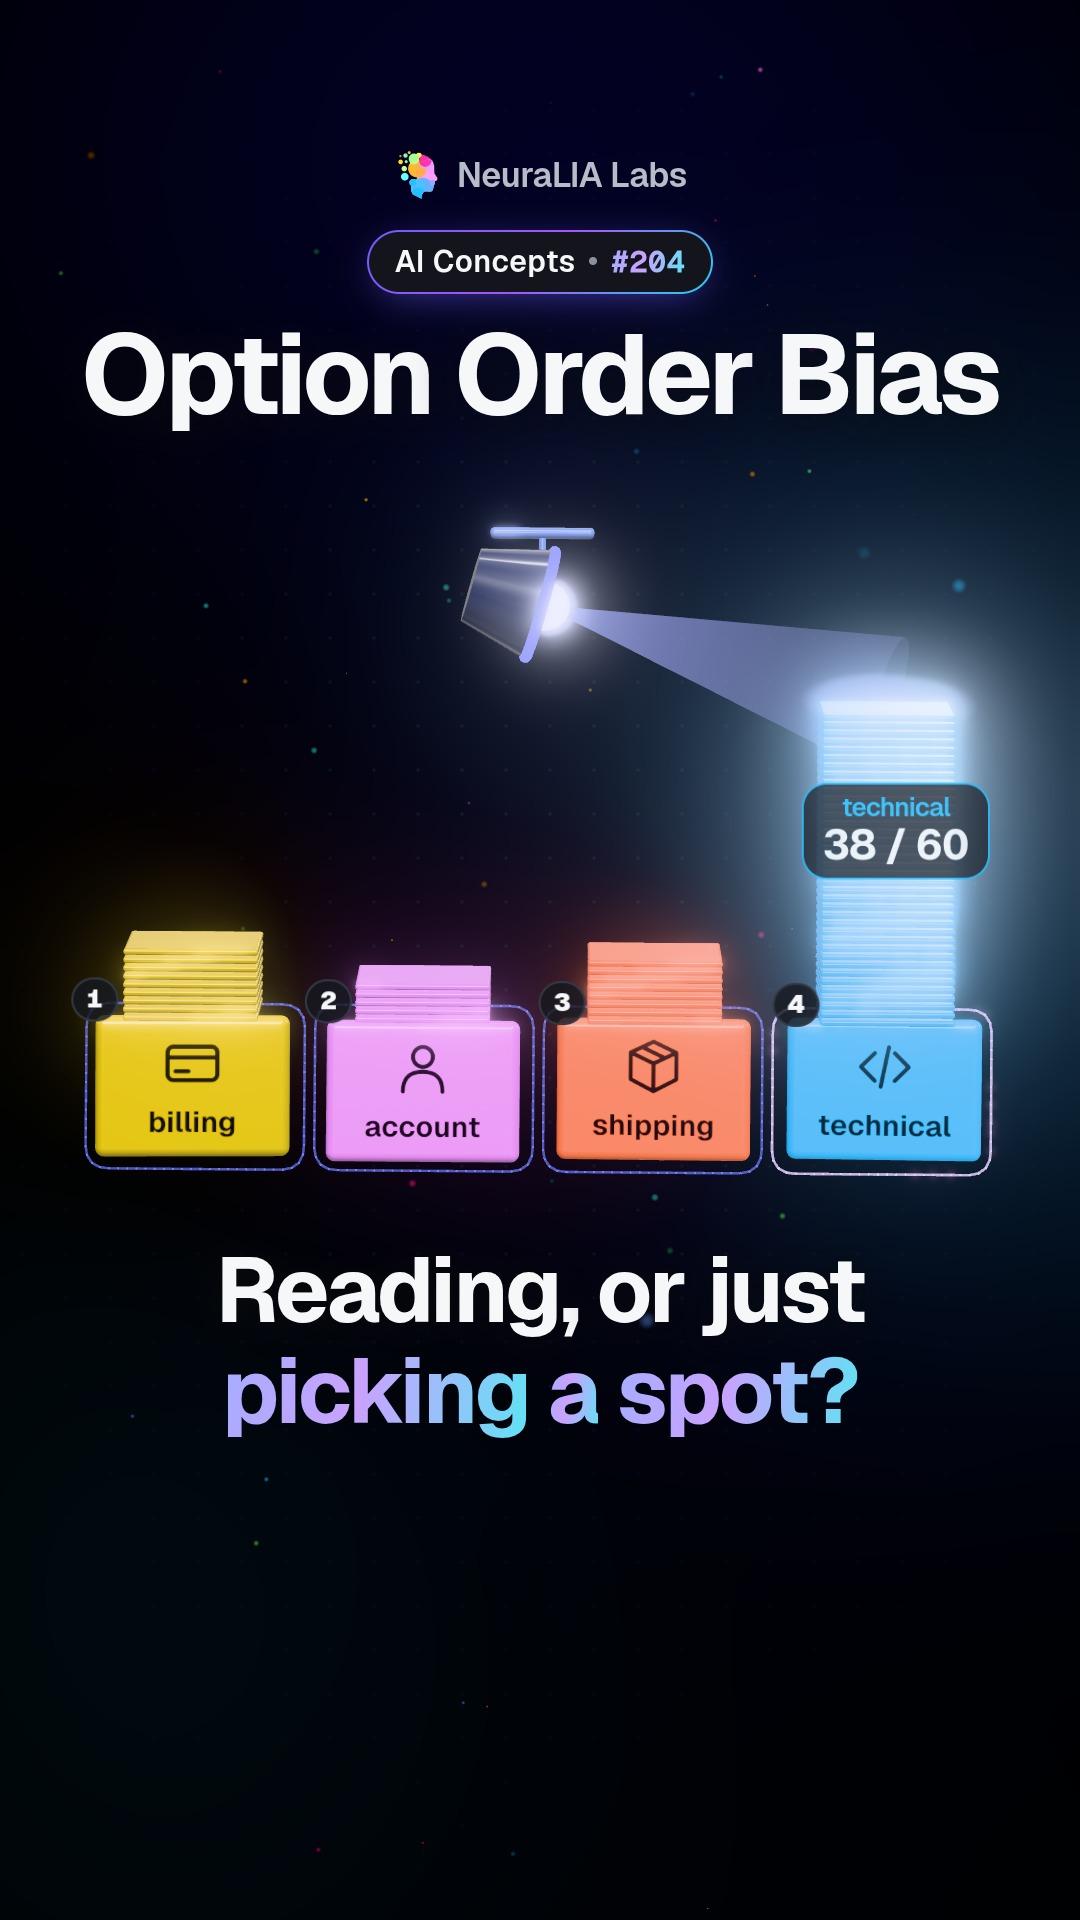 #204
Option order bias: when an AI picks a position, not an answer
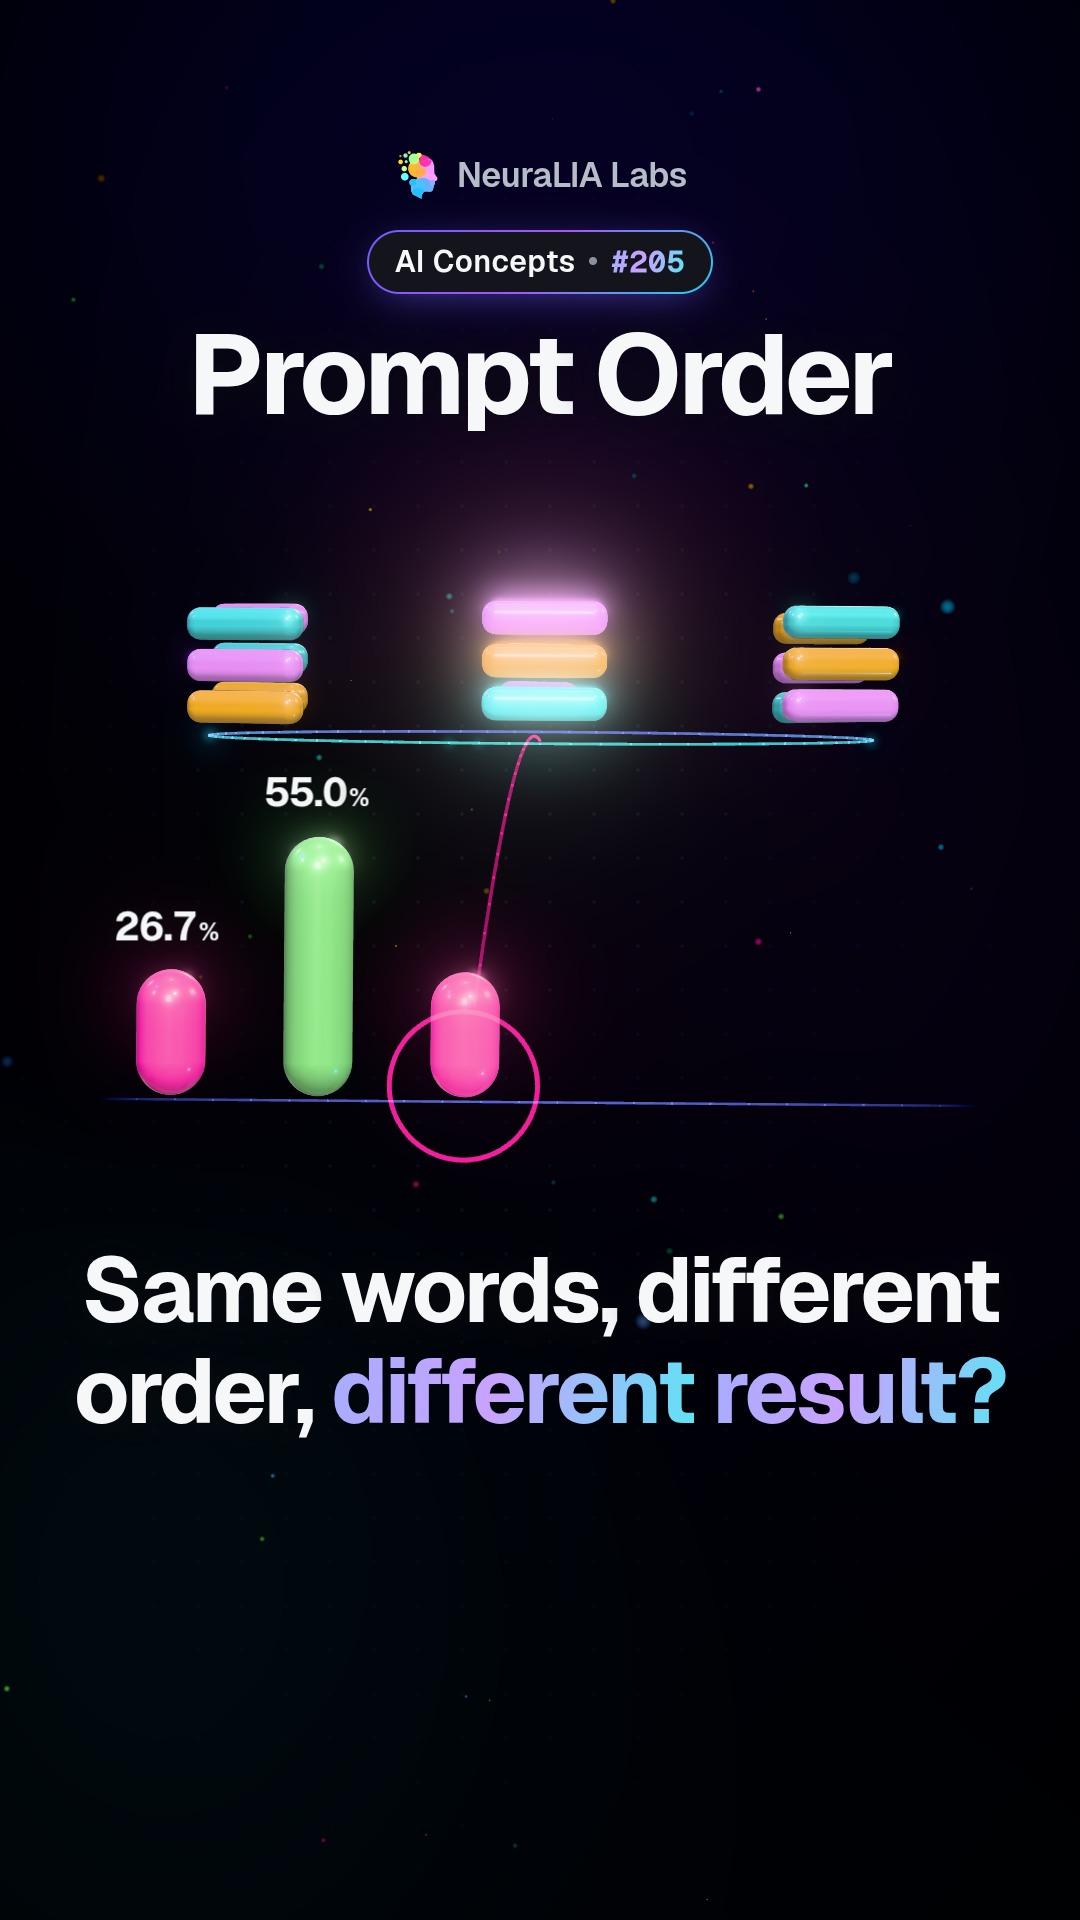 #205
Prompt order: the same words, rearranged, can double AI accuracy
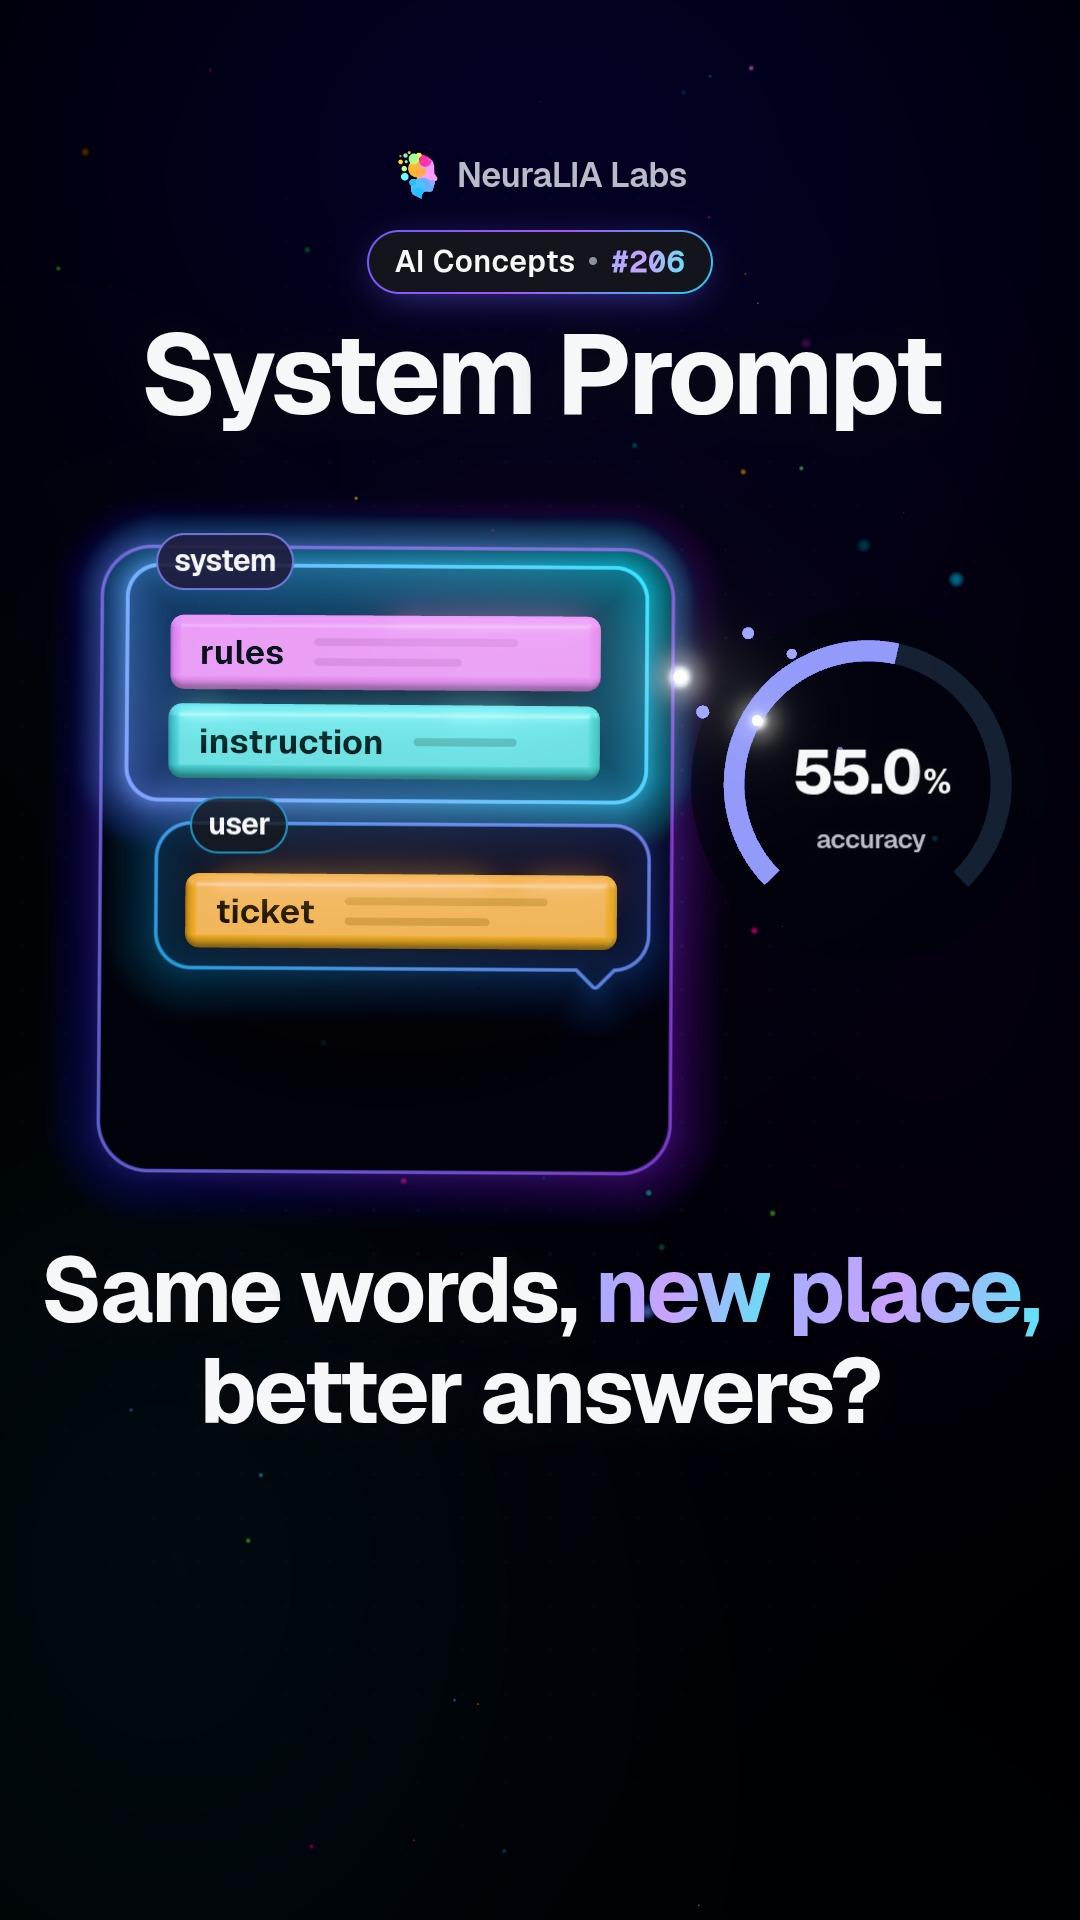 #206
System prompt: why where you put AI instructions changes results
 #207
Prompt formatting: how quotes and tags quietly shift AI accuracy
 #208
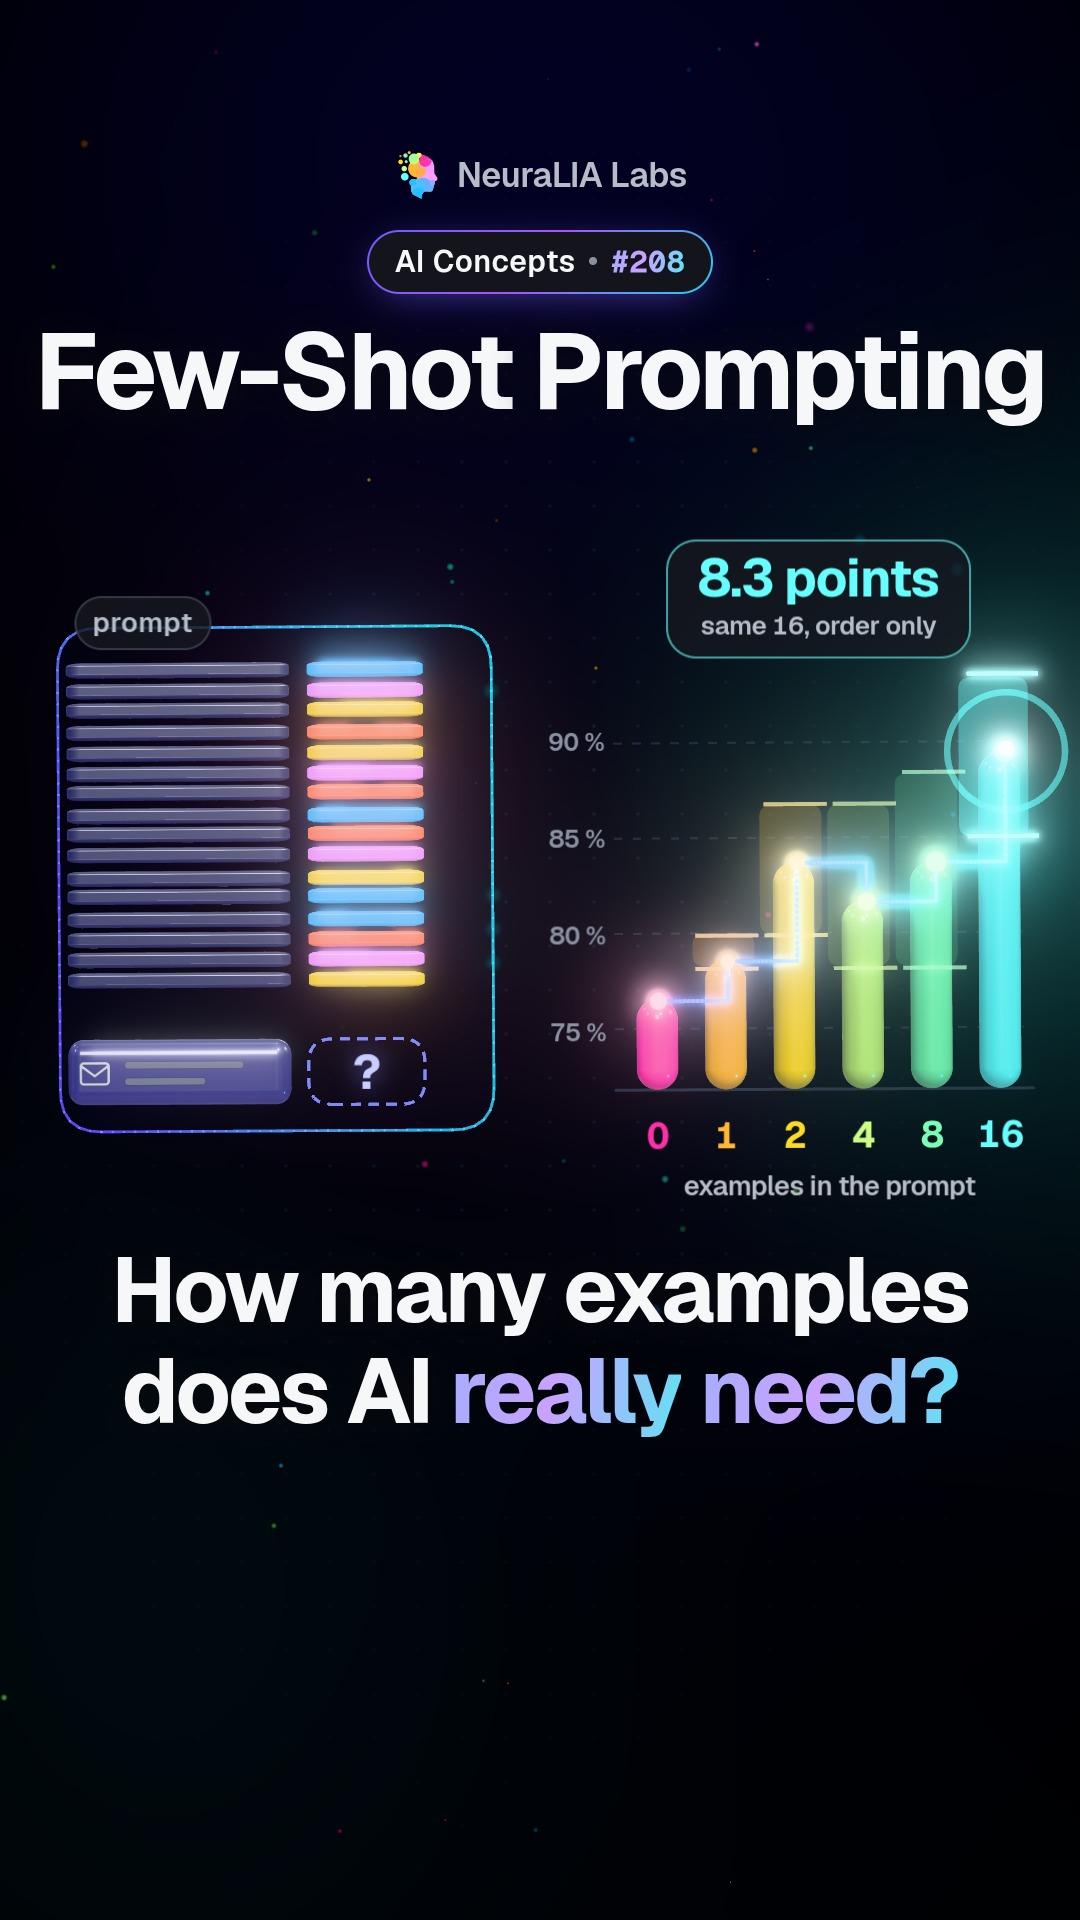
Few-shot prompting: how many examples an AI prompt really needs
Text napsaný s pomocí AI podle kapitoly 15 našeho bezplatného kurzu.