
 #111
Toto video a jeho text jsou v angličtině.
Mixture of experts: why a giant AI model can cost like a small one
A mixture of experts sends each word to just one or two experts out of many. How a huge model stays cheap per word, and why its size can mislead you.
Podrobně
What a mixture of experts is
Every building block of the AI models behind chatbots contains a small neural network that works on each word separately, the feed-forward layer. It holds about two thirds of each block's parameters, the adjustable numbers a model learns. A mixture of experts takes that part and keeps many copies of it, called experts. For each word, a small router picks only the top one or two experts to do the work. The rest sit out for that word.
What the video shows
The video shows a big part of the AI split into many small experts, with each word sent to only two of them. The result is a model that is huge in total, yet cheap for every word it processes.
One precision: in the course's version, nothing is cut into pieces. The feed-forward network is copied many times. Each expert is small next to the whole model, but as big as the network it copies, which is exactly why the total size grows. Two experts per word is a common choice; some designs use just one.
An everyday example
Imagine a hospital with 64 specialists on staff. A triage nurse glances at each patient and sends them to the two doctors who look most useful. The hospital as a whole holds an enormous amount of expertise, but each visit only costs two consultations, not sixty-four.
That is the economy the course describes: 64 experts with 2 working on each word gives roughly 32 times the parameters, for roughly the same cost per word.
How it works
- Score. The router is a tiny scoring layer. For the current word, it gives every expert a score.
- Pick. Only the top one or two experts run. The others are skipped.
- Blend. Their outputs are combined, each weighted by the score the router gave it.
This happens separately for every word, and again in every block of the model.
A common misconception
The hospital picture breaks down in one important way. There is no "French expert" and no "coding expert". Nobody hands out topics. The routing is learned during training, the choice is made for each word at each layer, so the same word can visit different experts in different blocks. Whatever specialties emerge are mostly impossible for people to interpret.
Two sizes, not one
With a mixture of experts, a model's headline size stops telling you what it costs to run. The course gives the example of a model with 400 billion parameters that may use only 17 billion of them for each word. Both numbers matter, for different reasons:
- The total decides whether the model fits in the memory of the graphics cards that run it.
- The active count decides how much work each word costs.
A side effect: same question, different answer
Servers process many people's requests together, in groups called batches. Each expert has a limit on how many words it can take within a batch, so which expert handles your word can depend on whose requests happened to be grouped with yours. And because the router makes an either-or choice, a tiny change in a score can send a word to a different expert. This is one of the reasons a model does not always give exactly the same output for exactly the same input, a topic covered in Chapter 17 of the course.
Why it matters
Next time you read a model's parameter count, ask which number it is: everything it contains, or what it actually uses per word. Mixture of experts is how a model can be enormous on paper and still cost per word like a much smaller one.
Learn it step by step in Chapter 9 of our free course AI From Scratch: Attention and the Transformer Block, Derived From an Average.
Také na
Další z této kapitoly
- #111
 #112
Residual connections: why modern AI adds instead of overwriting
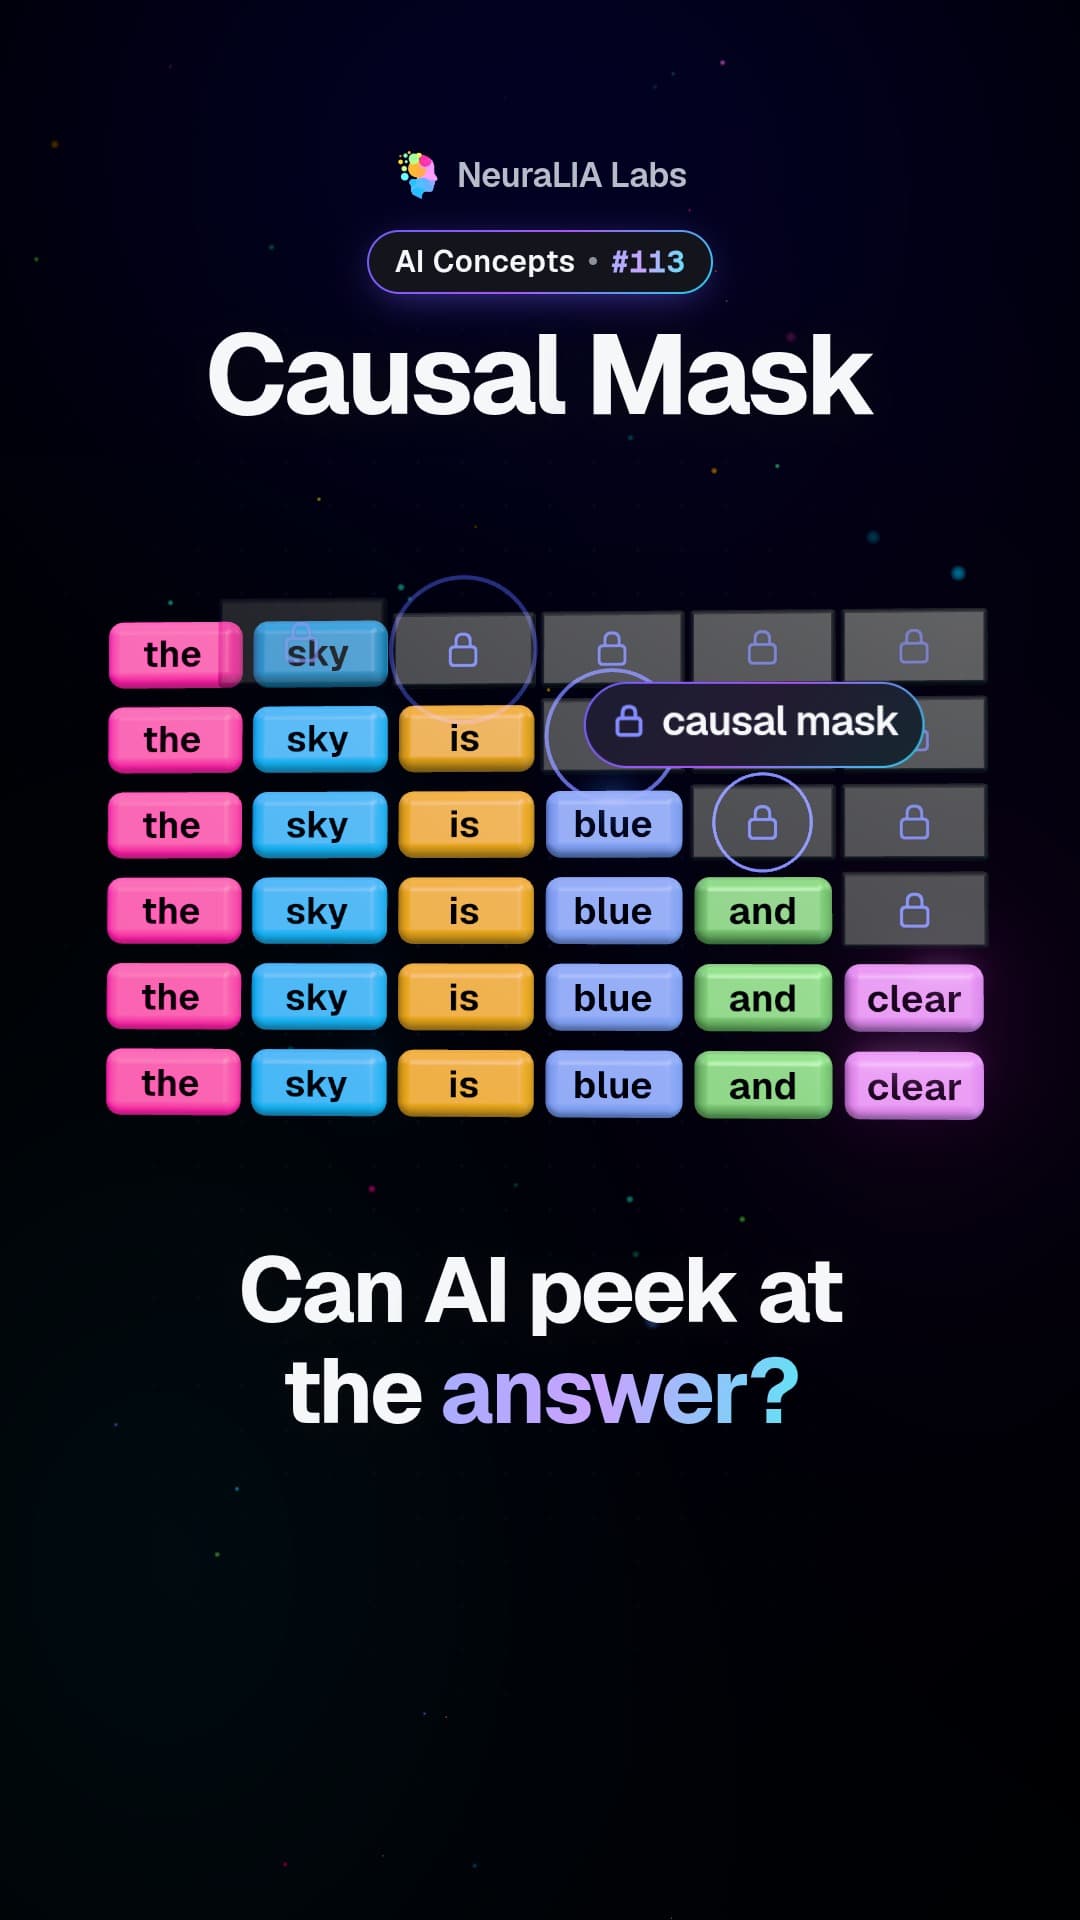 #113
Causal mask: the triangle that keeps a language model from cheating
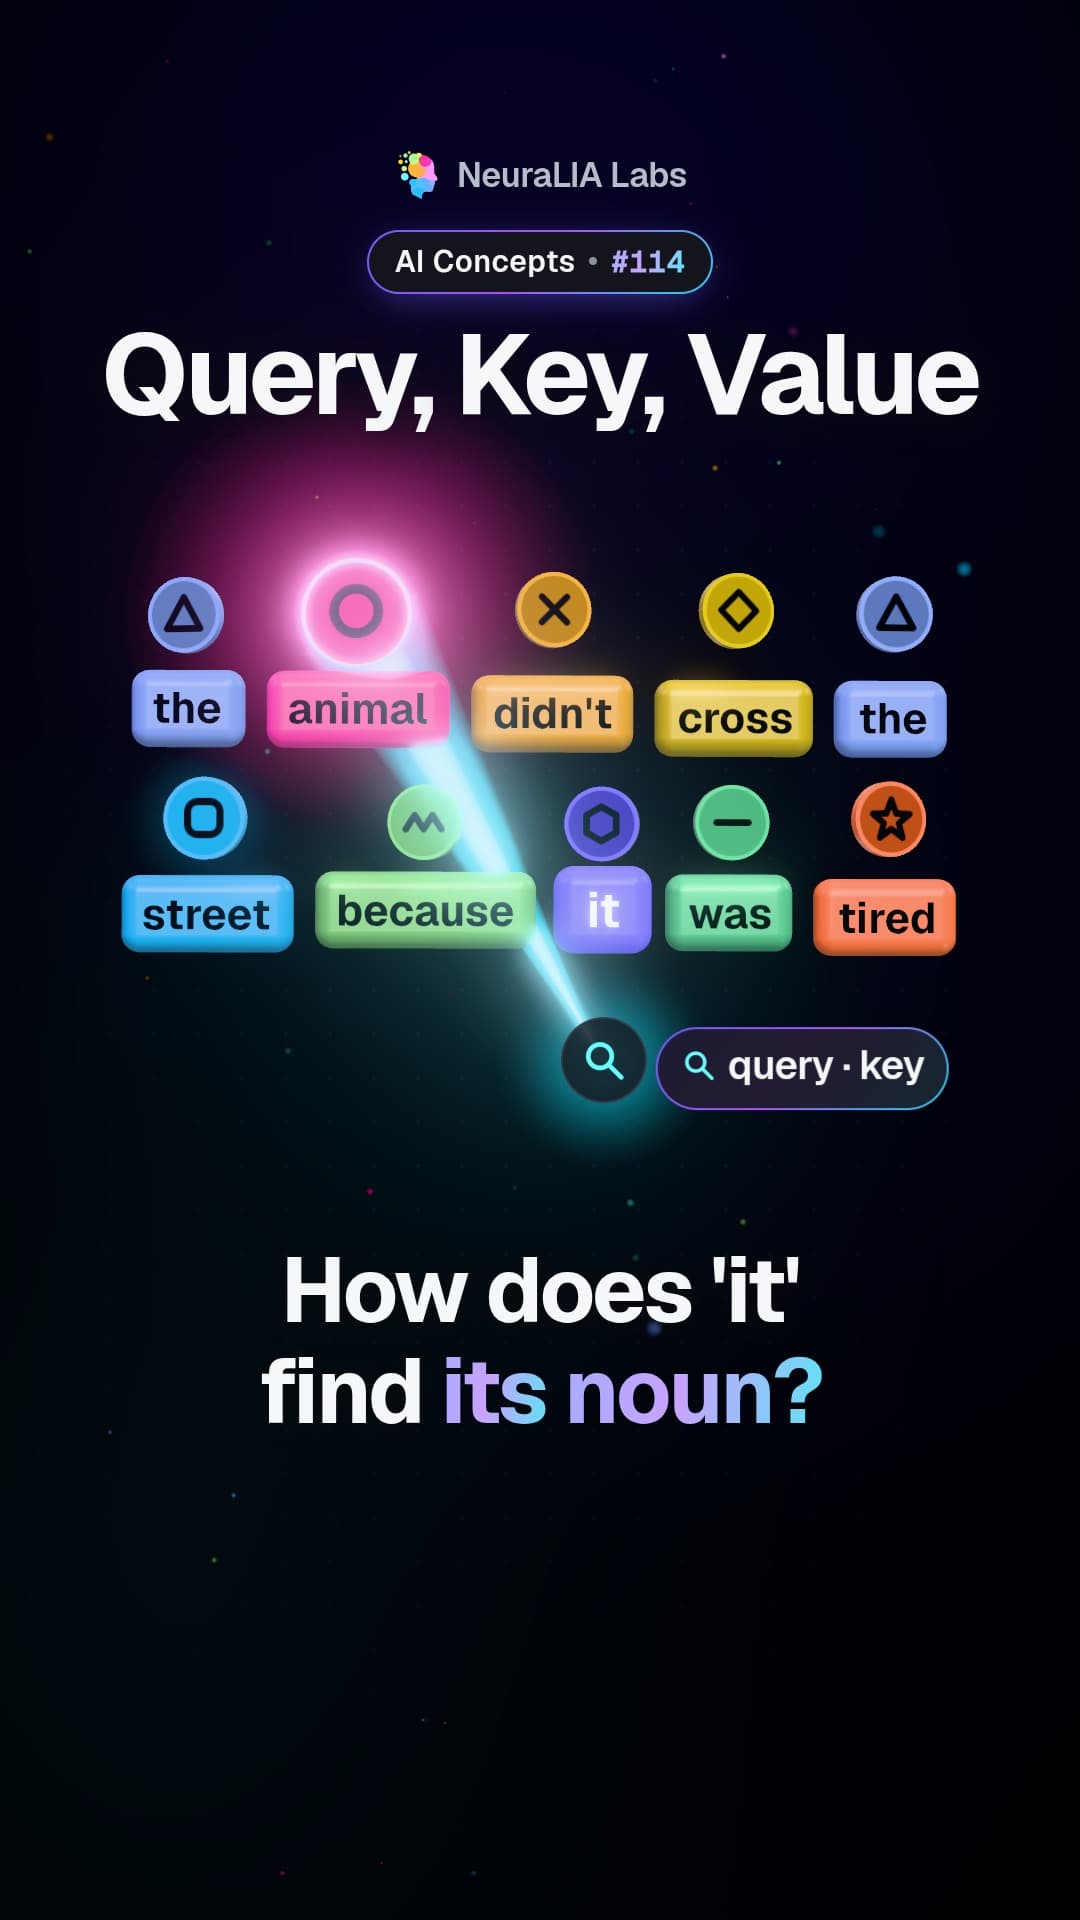 #114
Query, key, value: the three jobs every word does inside attention
 #115
Scaled attention: the small division that keeps big models learning
 #116
Multi-head attention: why AI reads with several spotlights at once
Text napsaný s pomocí AI podle kapitoly 9 našeho bezplatného kurzu.