
 #03
Este vídeo e seu texto estão em inglês.
Saturation: when a flat curve stops a neural network from learning
S-shaped curves go flat at their ends, and a learning signal that lands there almost vanishes. See how a flat spot made it 9,945 times weaker, and why that matters.
Em detalhes
What saturation is
A classic building block inside neural networks is an S-shaped curve called tanh. It squeezes any number into the range between -1 and 1. Around the middle the curve is steep, so a small change in the input makes a big change in the output. Far out at either end it is almost flat: push the input higher and the output hardly moves.
Landing on that flat stretch is called saturation. It matters because of how networks learn. Training sends a correction signal backwards through the network, and every time the signal crosses one of these curves it gets multiplied by how steep the curve is at that point. On the flat part, that multiplier is close to zero, so the correction almost disappears.
What the video shows
The video makes the point with one number. S-shaped curves go flat at their ends, and when the signal lands there, almost nothing makes it back to the earlier layers. In the course's example, the signal crossing a single flat curve shrank 9,945 times compared with the same calculation on the curve's steep part.
An everyday example
Imagine a test where every score above 90 counts as an A. A student sitting at 98 can study twice as hard or half as hard, and the grade will not budge. The grade has stopped carrying any information about whether the extra effort helped. A student sitting right at the border between a B and an A is different: a little extra work can change the grade, so the effort shows.
A saturated neuron is the student at 98. It may be in a perfectly reasonable place, but it can no longer tell the network which way to adjust.
How it happens, in numbers
The course runs the same small calculation twice, changing only the starting values.
- First run: the number going into tanh is about 1.33, on the steep part of the curve. The correction signal at that point is about 0.24.
- Second run: the number going into tanh is 6, far out on the flat part. The signal drops to about 0.000025.
That is the 9,945-fold drop. The calculation has three routes leading back to its input. In the first run all three carry signal. In the second, the two routes that pass through tanh fall silent, and only the direct route that skips the curve still delivers anything.
Why it matters
One flat curve already starves every route that passes through it. A deep network stacks many of them, and the multipliers compound. Put forty saturated layers in a row and you are multiplying forty tiny numbers together: the earliest layers end up with practically no signal and stop learning. This is the famous vanishing gradient problem (gradient is the course's word for that correction signal).
The miniature example also hints at a fix. The only route that survived was the one that went around the curve instead of through it. That is the thinking behind skip connections: shortcuts that let the signal jump past a layer rather than squeeze through it.
Learn it step by step in Chapter 5 of our free course AI From Scratch: Backpropagation From Scratch: The Engine, Then the Network.
Também em
Mais deste capítulo
- #03
 #055
Activation functions: the small bend that makes deep networks work
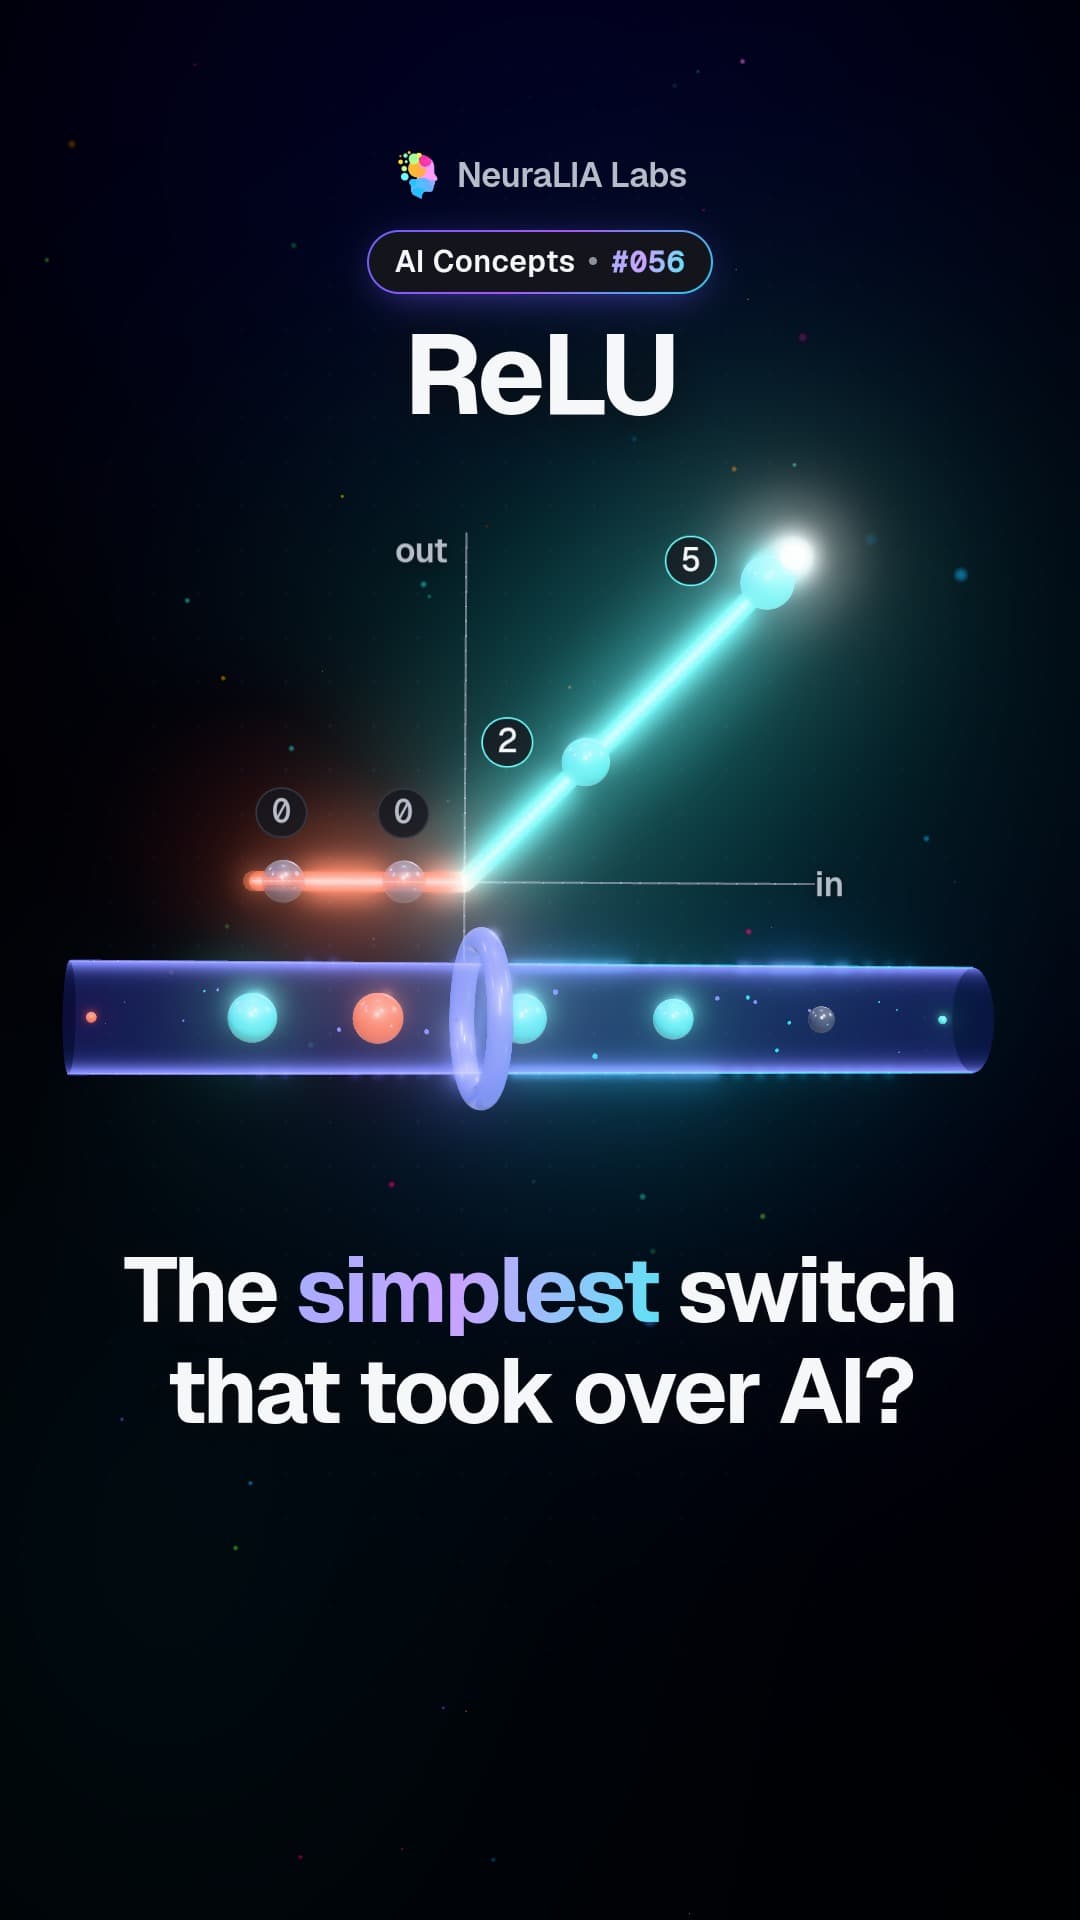 #056
ReLU: the simple on-off rule inside modern neural networks
 #057
Dying ReLU: when parts of a neural network quietly switch off
 #058
Computational graphs: how AI tracks where every number came from
 #059
Backpropagation: one backwards pass that trains a whole network
Texto escrito com assistência de IA a partir do capítulo 5 do nosso curso gratuito.