
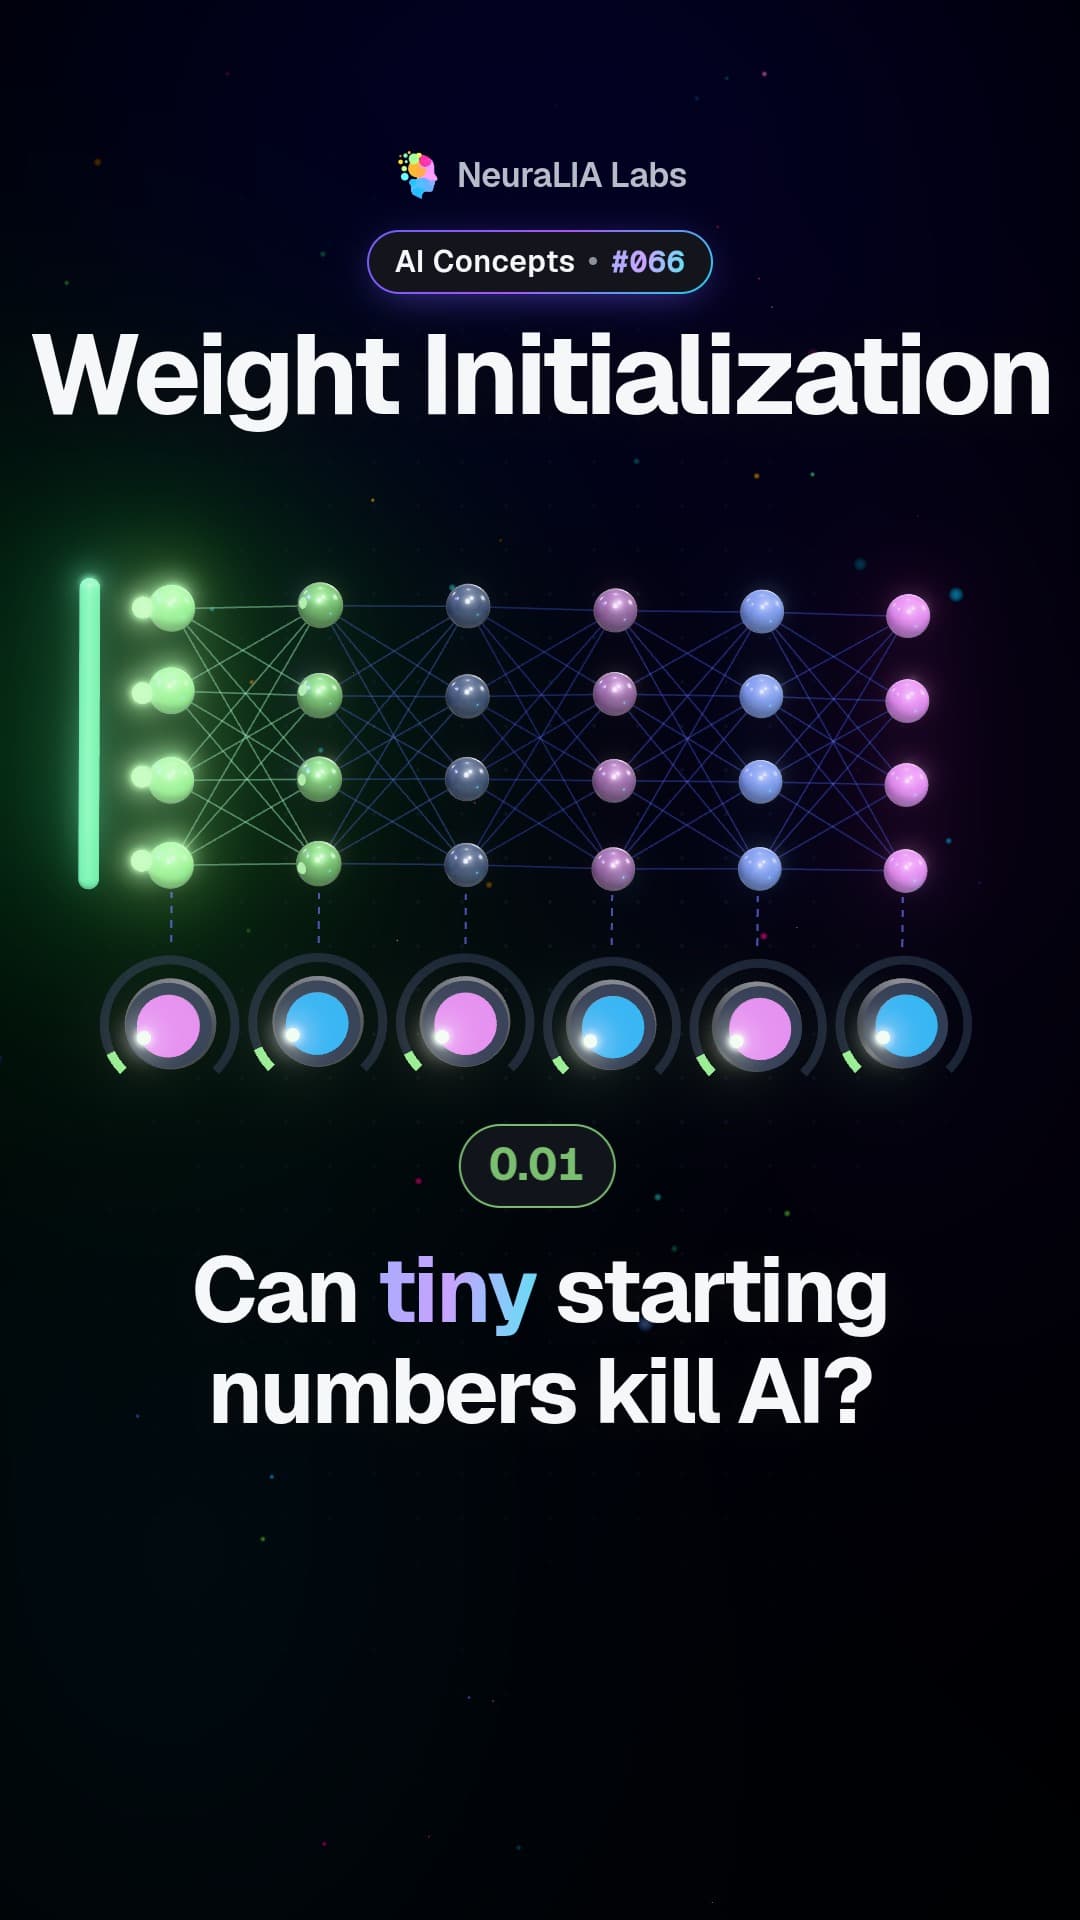
 #066
Den här videon och dess text är på engelska.
Exploding gradients: why AI training can suddenly blow up
A network learns by passing corrections back through its layers. If each layer enlarges them, training breaks. Here is why it happens and how to stop it.
I detalj
What exploding gradients are
A neural network learns in rounds. It makes a guess, measures how wrong it was, and then sends a correction backwards through its layers, from the output end towards the input end. Those corrections are called gradients: numbers that tell each of the network's internal settings (its weights) which way to move, and by how much.
Gradients explode when each layer makes the correction bigger as it hands it back. Several layers in a row that each enlarge it compound, like interest on a debt nobody is paying off. The corrections become enormous, the settings jump wildly, and training breaks. Often the error score stops being a number at all, and the computer prints NaN, short for "not a number".
What the video shows
The short makes one point. AI learns by sending corrections backwards through its layers. If every layer enlarges them, they grow out of control and training breaks. The remedy it points to: good starting values for the network.
An everyday example
Imagine six loudspeakers in a row, where each one listens to the one before it and plays the sound back three times louder. A whisper at one end arrives as a roar at the other. No single speaker is broken. The problem is the chain: small amplifications, repeated, multiply.
A deep network is that row of speakers played in reverse. The correction enters at the last layer and gets amplified at every step on its way to the first.
What it looks like in real numbers
In our free course, a six-layer network is started with random weights whose typical size is 1. (Typical size means the standard deviation: how spread out the numbers are.) Each layer takes 128 inputs, so with weights that large, the weights alone multiply the correction by roughly 11 (the square root of 128) on every step backwards. Measured layer by layer, the correction is about 7 at the last layer and about 1,940 at the first.
The strange part is that the forward direction looks fine. The signals flowing from input to output sit around 0.96, which seems healthy. They are not. Each unit (a tiny calculator inside a layer) squeezes its output into the range between -1 and 1, and these units are jammed against that limit, a state called saturation. Jammed units pass back only a fraction of the correction, but the weights enlarge it by more, so it still grows, roughly threefold per layer on average. The network looks calm going forward while the corrections blow up coming back.
With well-chosen starting weights, the same network keeps its corrections at a similar size in every layer, roughly between 0.4 and 2.3. Nothing dies and nothing explodes.
How to spot it and stop it
- The error turns into NaN within the first few steps. In real training runs, that is the classic sign, though not the only possible cause.
- Look before you guess. Print the size of the gradients at each layer. If they grow steadily from the last layer to the first, they are exploding.
- Fix the starting values. Sizing the initial weights to match the number of inputs is its own topic: weight initialization.
- Add a guard. Gradient clipping caps how large any single correction is allowed to be. It takes one line of code.
Why it matters
The more layers a network has, the more times the correction gets multiplied on its way back, so the danger grows with depth. Knowing this turns a mysterious crash into a predictable effect: a NaN at step three is not bad luck, it is a sign that something is amplifying the corrections.
Learn it step by step in Chapter 6 of our free course AI From Scratch: Getting It to Train, and Getting It to Generalise.
Finns även på
Mer från det här kapitlet
- #066
 #067
Batch normalization: the AI layer that grades on a curve
 #068
Layer normalization: why chatbots steady each input on its own
 #069
Ablation: change one thing at a time to find what really works
 #070
Loss curves: what the shape of a training line tells you
 #071
Adam: the optimizer that gives every direction its own stride
Text skriven med AI-hjälp från kapitel 6 i vår gratiskurs.