
 #203
Это видео и текст к нему на английском.
Prompt formatting: how quotes and tags quietly shift AI accuracy
Wrapping the same text in quotes, tags or headings moved a small AI's accuracy by 18 points. Learn why formatting is a setting to test, not a rule to copy.
Подробнее
What prompt formatting is
Prompt formatting is the punctuation and layout around the content of a prompt: whether a piece of text is wrapped in quotes, marked with a label like "Ticket:", boxed off with symbols or given a heading. None of it changes the meaning. People treat it as cosmetic. Language models do not.
What the video shows
The video wraps the same text in quotes, tags or headings and shows a small AI's accuracy moving by 18 points. Its lesson: formatting is a setting you should test, and some celebrated gains are not actually proven.
In the course experiment, a small model sorts customer support tickets into queues. Only one thing changes between runs: what surrounds the ticket text. Here is how each version scored on the same 60 tickets:
| How the ticket is marked | Correct | |---|---| | XML-style tags (a pair of labels in angle brackets) | 85.0% | | nothing at all | 80.0% | | a heading line (Markdown style) | 78.3% | | a "Ticket:" label | 76.7% | | lines of hash symbols | 75.0% | | triple backticks (the symbols programmers use to box off code) | 73.3% | | double quotes | 66.7% |
An everyday example
Imagine comparing two pairs of running shoes. If different runners test each pair on different days, weather and fitness swamp any real difference. Now have the same runners cover the same routes in both pairs and compare route by route. A hilly route or a tired runner slows both pairs alike, so that noise cancels out and the shoes are what is left. That second kind of test is called paired, and it is the key to reading the table above.
How to read a result like this
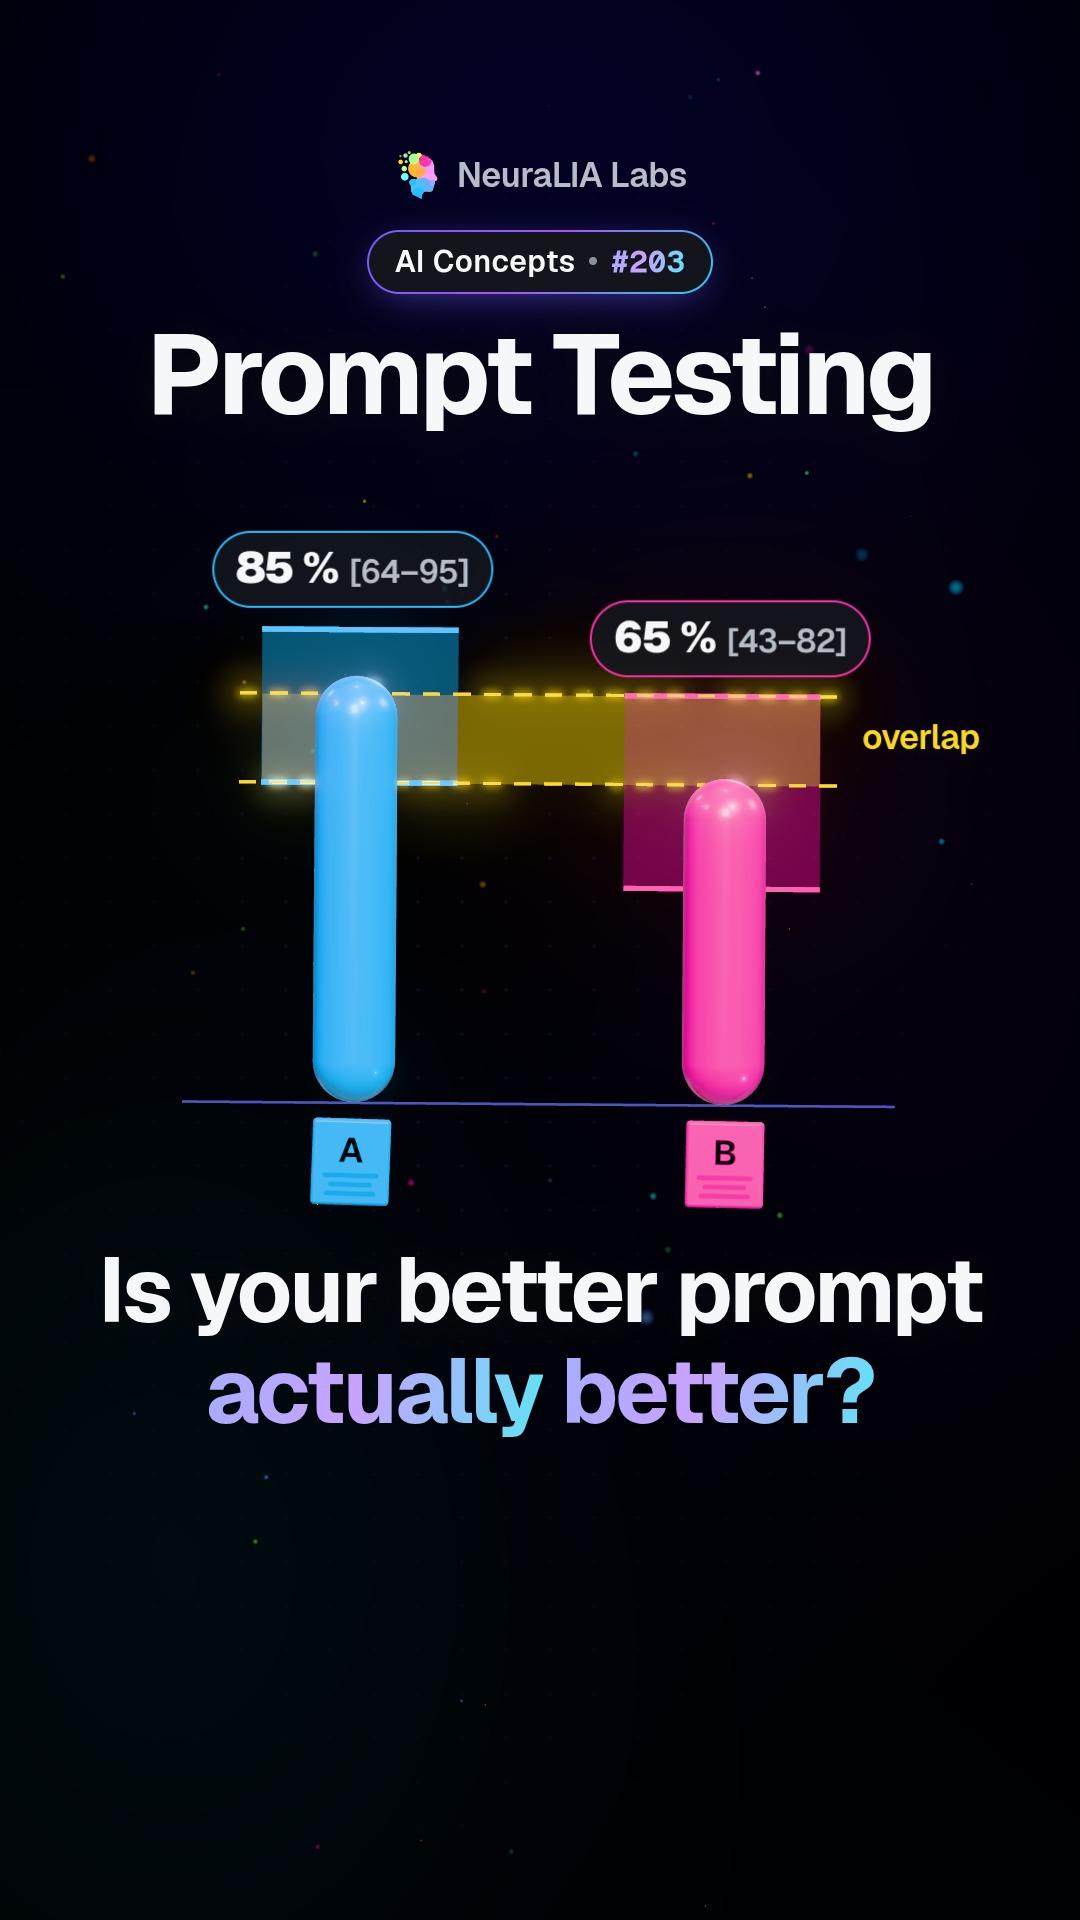
The margins of error on the best and worst rows overlap, so a quick glance would say the table proves nothing. That glance is wrong. Every version was tested on the same 60 tickets, so you can compare them ticket by ticket and count only the ones where they disagreed:
- Quotes vs XML tags: 12 tickets went from wrong to right and just 1 went the other way. That is a real difference.
- "Ticket:" label vs XML tags: the tags scored 8.3 points higher, exactly the kind of number that ends up in a blog headline. Ticket by ticket, it was 6 gained and 1 lost. That is too few to be sure. The famous-sounding improvement rests on seven tickets.
So there are two different questions, and each needs its own tool. "How good is this prompt?" needs a margin of error around its score; that is the number you report to whoever decides whether to ship. "Is B better than A?" needs the paired, ticket-by-ticket comparison, which is far more sensitive because the difficulty the two versions share cancels out.
Why it matters
This is not a quirk of one small model. Other researchers (Sclar and colleagues) changed nothing but separators, spacing and capital letters across dozens of tasks, and the swings were big enough to flip published rankings of which model is best. The lesson is not "always use XML tags". It is that formatting is a setting worth trying, testing it costs nothing, and any comparison of two AI models done with one fixed format is partly a comparison of formats.
Learn it step by step in Chapter 15 of our free course AI From Scratch: Prompt Engineering, Measured: What Changes the Output.
Также на
Ещё из этой главы
- #203
 #204
Option order bias: when an AI picks a position, not an answer
 #205
Prompt order: the same words, rearranged, can double AI accuracy
 #206
System prompt: why where you put AI instructions changes results
 #208
Few-shot prompting: how many examples an AI prompt really needs
 #209
Prompt myths: what tips, pep talks and threats did in a real test
Текст написан с помощью AI по главе 15 нашего бесплатного курса.