
 #05
Este vídeo e o respetivo texto estão em inglês.
Vocabulary size: how many text pieces an AI model should know
A bigger token vocabulary makes texts shorter but makes every step of writing more expensive. Here is the trade-off, measured, and where real models land.
Em detalhe
What vocabulary size is
A language model reads and writes text as pieces called tokens. Its vocabulary is the fixed list of every piece it knows, and the vocabulary size is simply how many entries that list has. It is not a dictionary of words: many entries are word fragments, words with a space stuck to them, or single bytes. Choosing the size is a real engineering decision, with a cost on each side.
What the video shows
The video explains that an AI's dictionary of text pieces has a fixed size. A bigger one makes texts shorter, but every piece of text the model writes means giving a score to every entry. Today's models sit somewhere between 32,000 and 200,000 entries.
The trade-off in numbers
Each time the tokenizer (the program that cuts text into pieces) learns a new piece, the list gets one entry longer and texts get a little shorter, because a common chunk now fits in one token. The course measured this on one English sample of 151,191 bytes:
| Vocabulary size | Tokens needed | Bytes of text per token | |---|---|---| | 300 | 101,065 | 1.50 | | 1,024 | 50,369 | 3.00 | | 4,096 | 30,757 | 4.92 |
Going from 300 to 1,024 entries doubled how much text fits in each token. Quadrupling the list again, to 4,096, did not double it a second time. On a small sample like this one the gains hold up longer than usual; on a realistic amount of text the curve flattens hard.
The hidden cost of a big vocabulary
The price is not just memory. Two things grow with the list:
- Every piece needs its own row of numbers. The model stores a list of learned numbers, called an embedding, for every entry in its vocabulary.
- Every step means scoring every entry. When a model writes, it picks the next piece by first giving a score to each entry in its vocabulary. With 200,000 entries, that is 200,000 scores for every single piece it writes, and the work in this last step grows in direct proportion to the vocabulary size.
An everyday example
Imagine printing a poster with a box of rubber stamps. A box of single letters is small, but the poster takes many stampings. Add stamps for whole common words and you finish in far fewer stampings. But the box gets heavier, and every time you reach in, there are more stamps to look through before you find the right one. Somewhere in between is the best box for the job.
Where real models land
Real models use between 32,000 and 200,000 entries. GPT-2 used 50,257. The tokenizer behind GPT-4, called cl100k, has 100,277. The one behind GPT-4o, called o200k, has roughly twice that. The trend is upward, and the main driver is not squeezing text for its own sake but treating languages other than English more fairly, cutting the uneven cost we call the token tax.
Why it matters
Vocabulary size quietly shapes how much text fits into a model's working memory, how much work each written piece costs and how the bill adds up. It is also one reason two models can count a different number of tokens for exactly the same text.
Learn it step by step in Chapter 7 of our free course AI From Scratch: Build a BPE Tokenizer: Why Your Model Can't Count the R's.
Também em
Mais deste capítulo
- #05
 #084
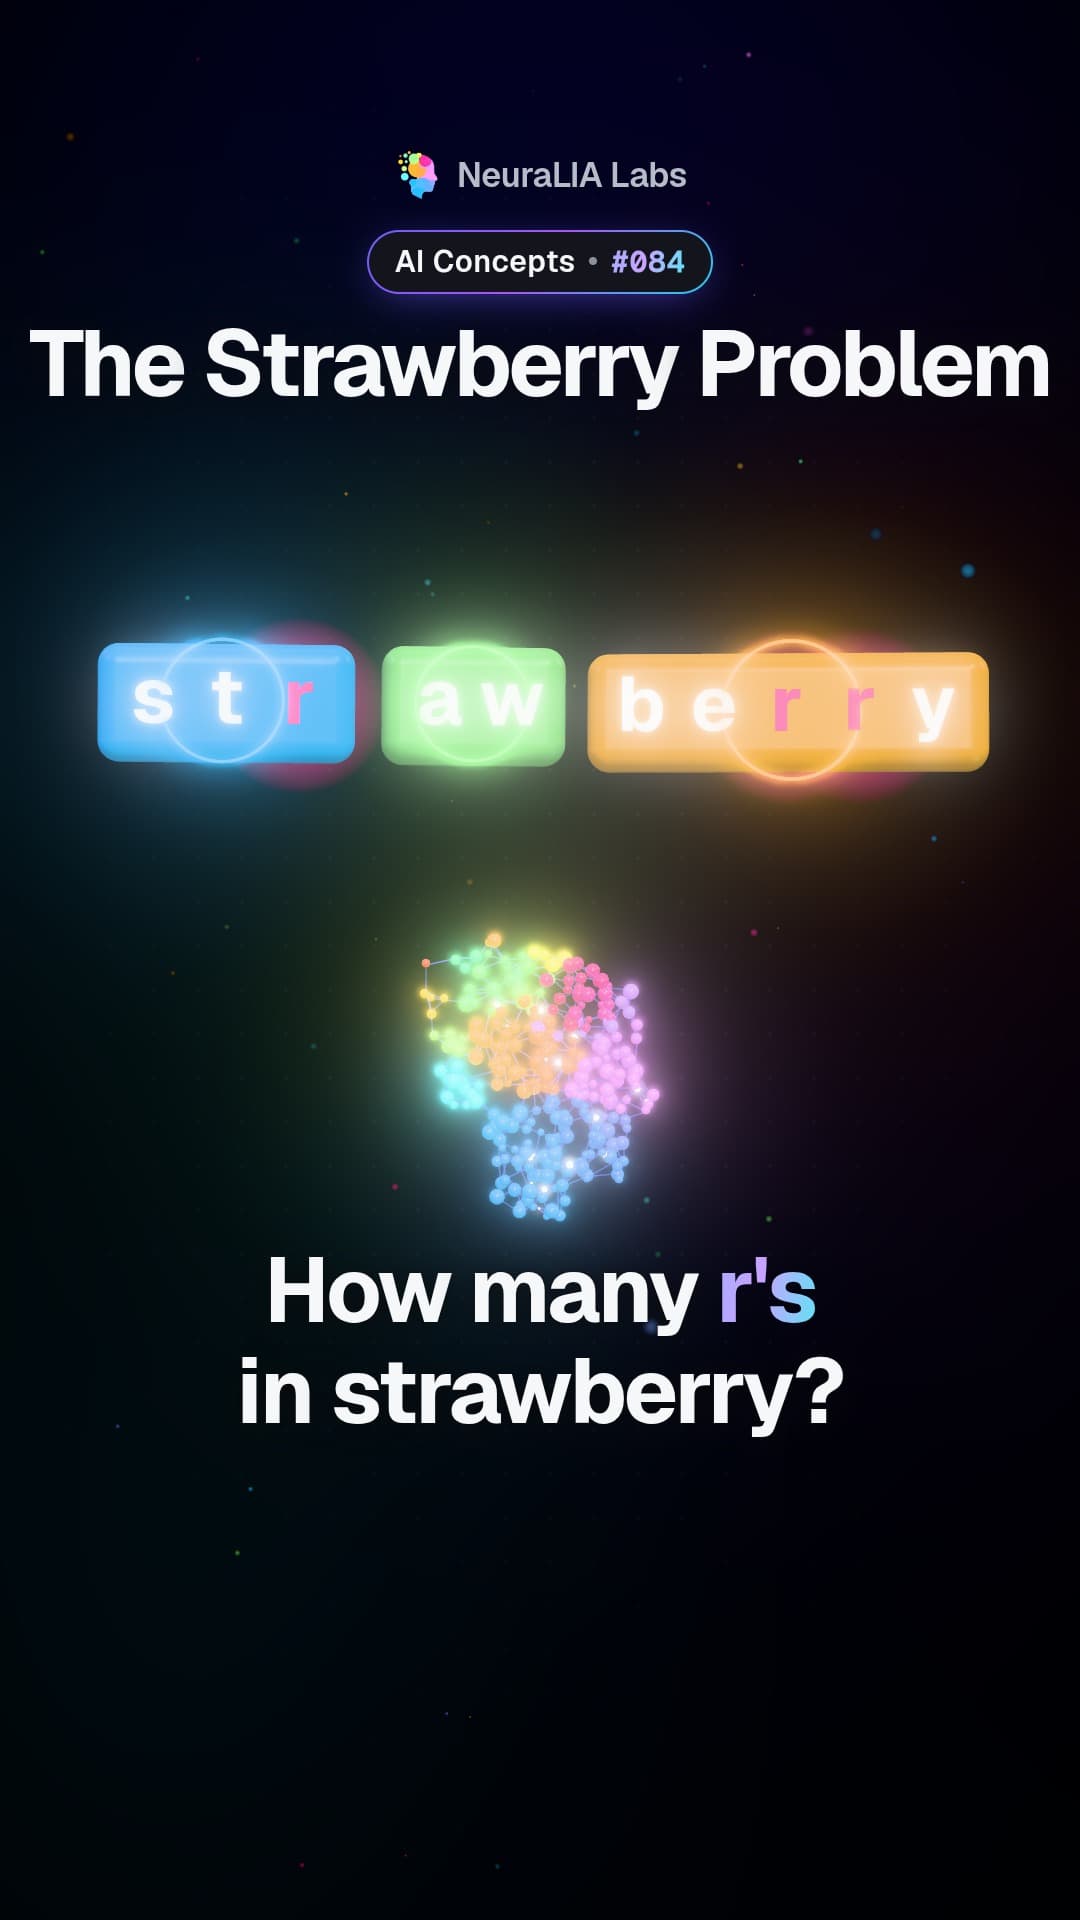
The strawberry problem: why AI can miscount the r's in a word
 #085
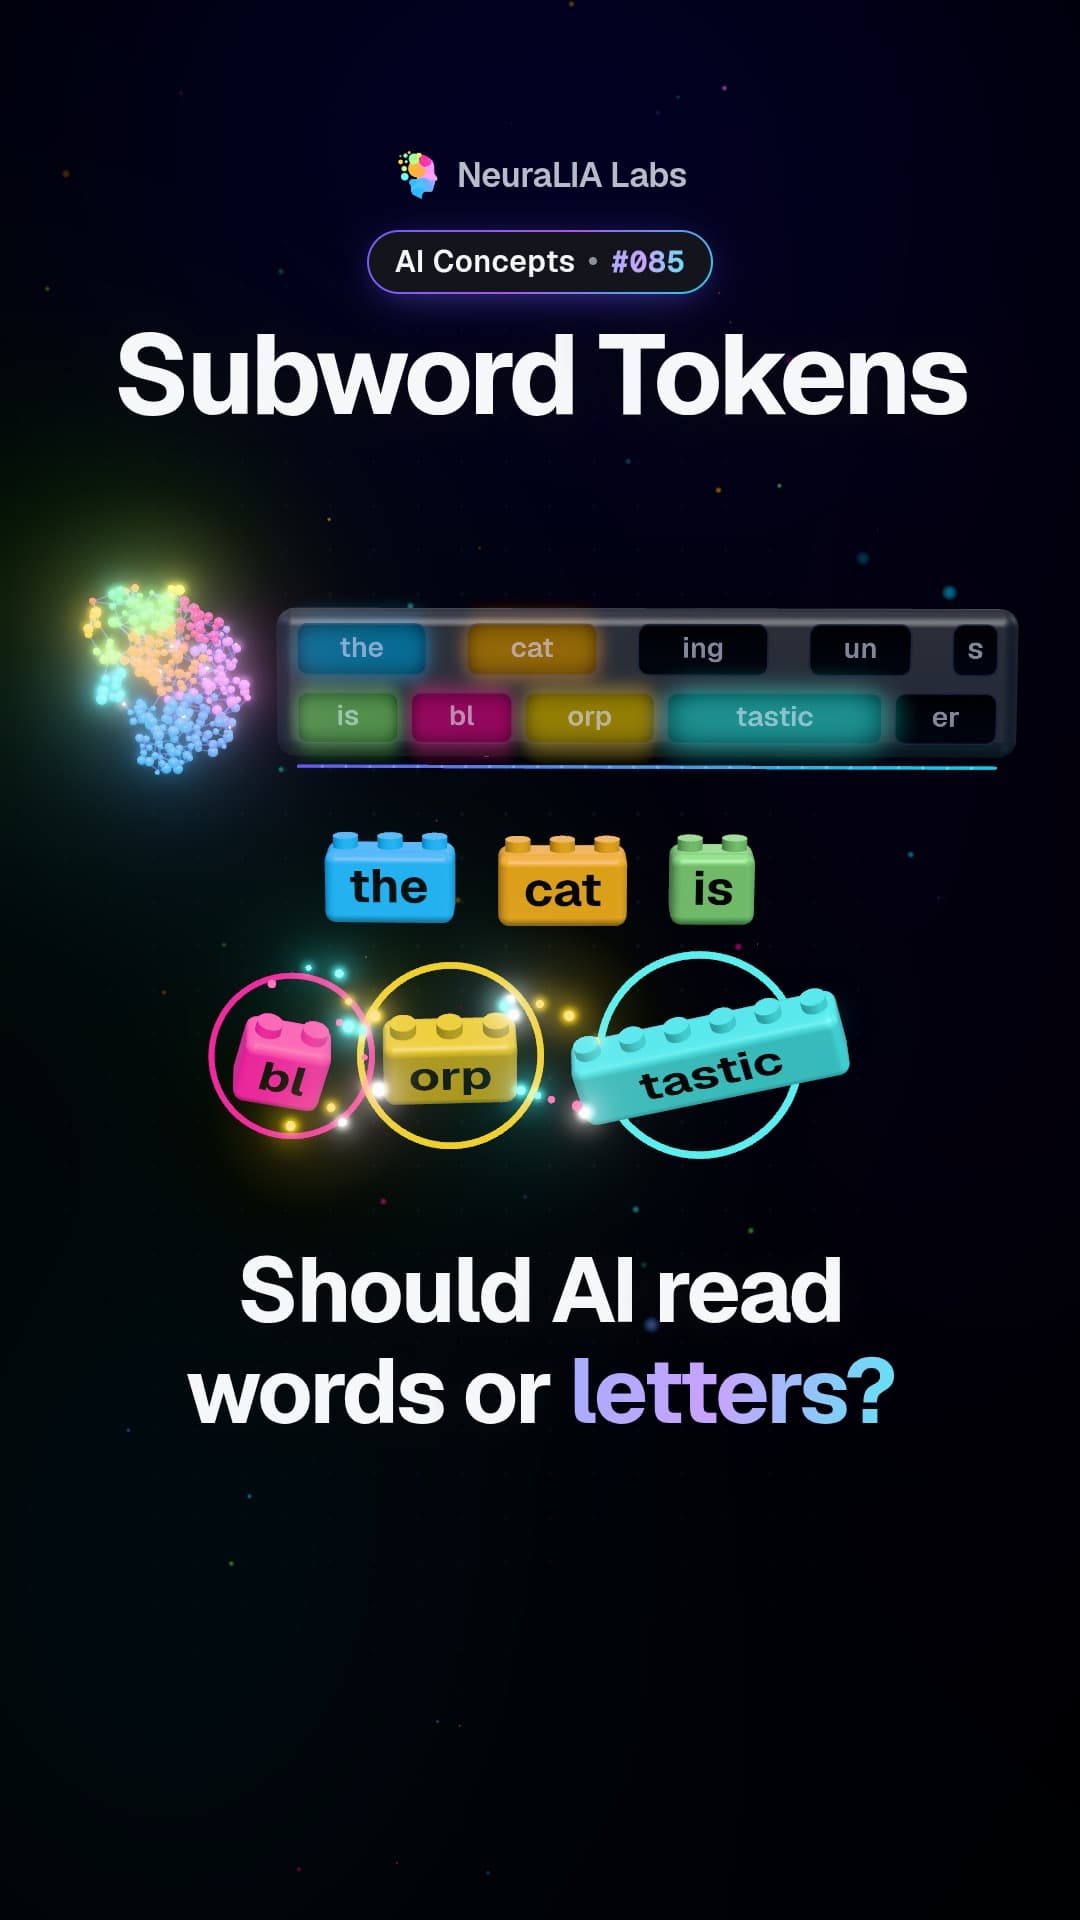
Subword tokens: the middle ground between whole words and letters
 #086
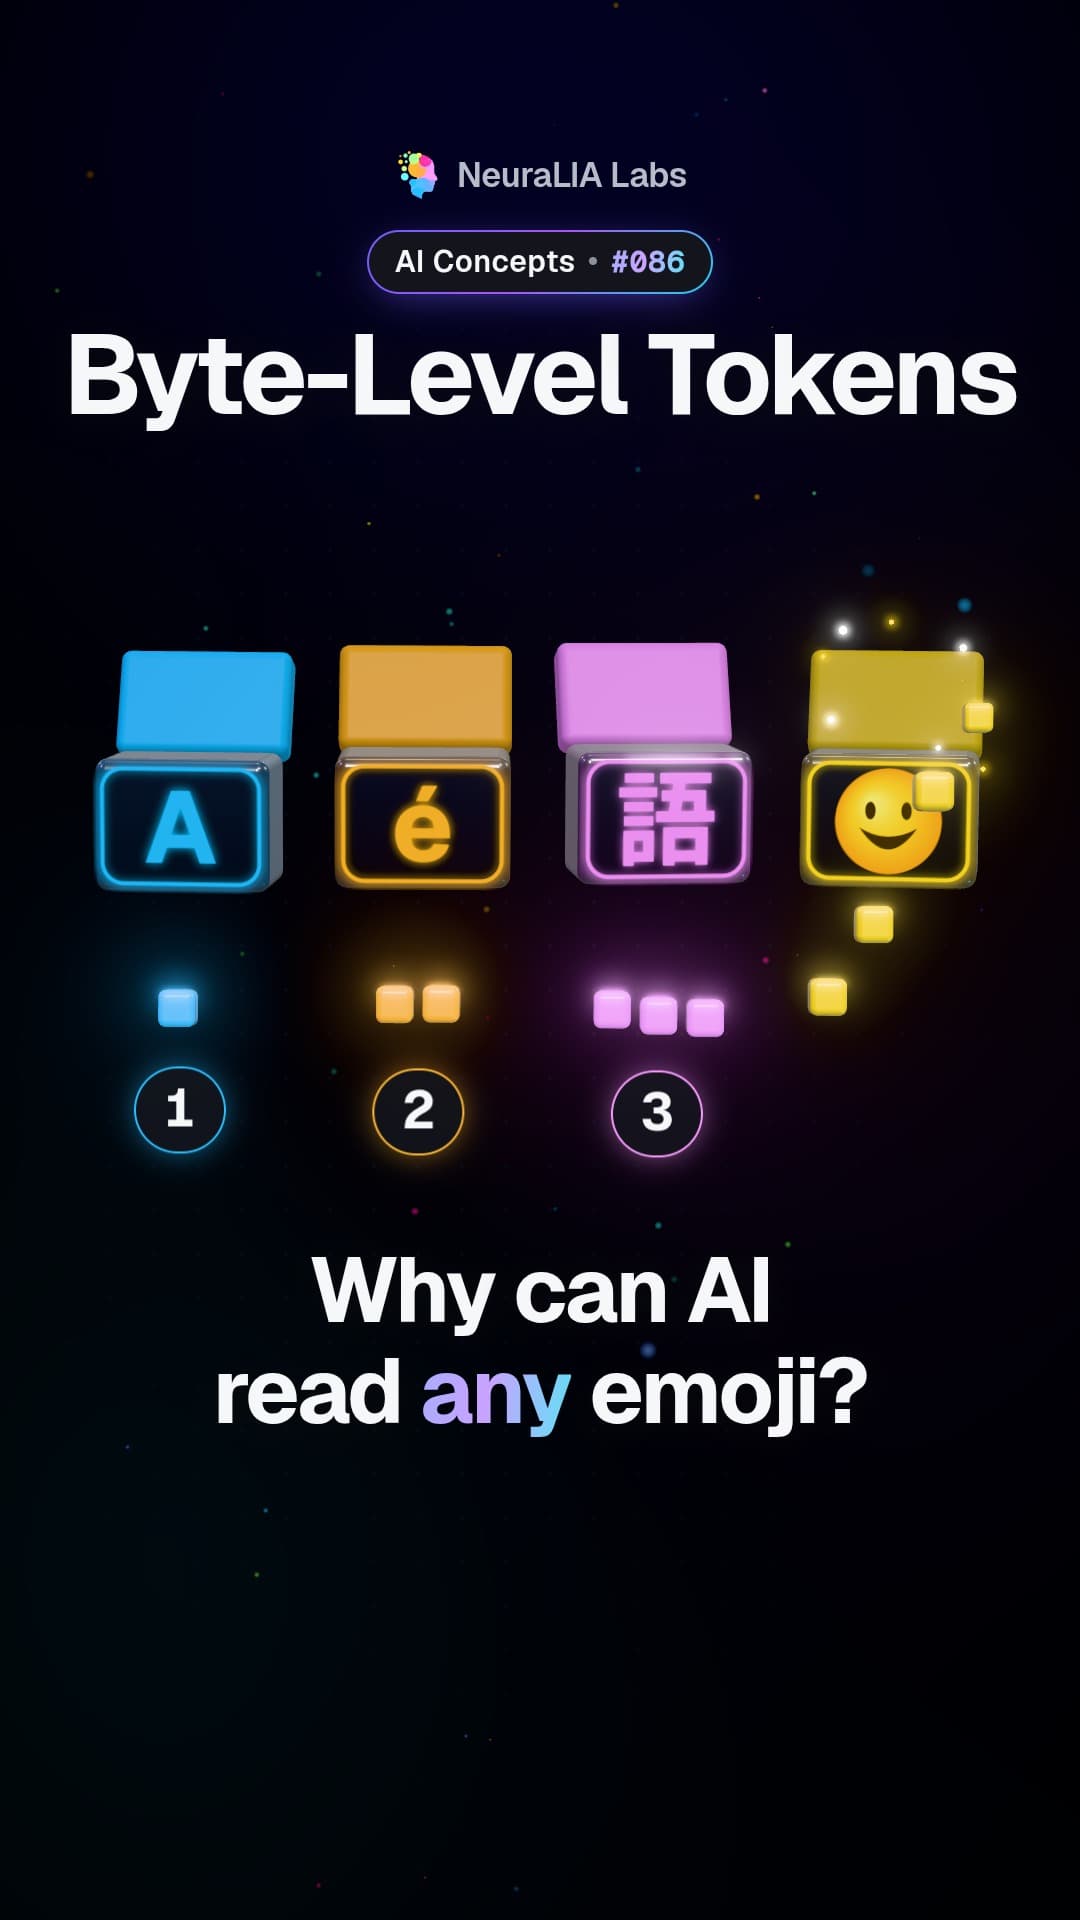
Byte-level tokens: how AI can read any language, symbol or emoji
 #087
Byte-pair encoding: the 1994 compression trick that splits text for AI
 #089
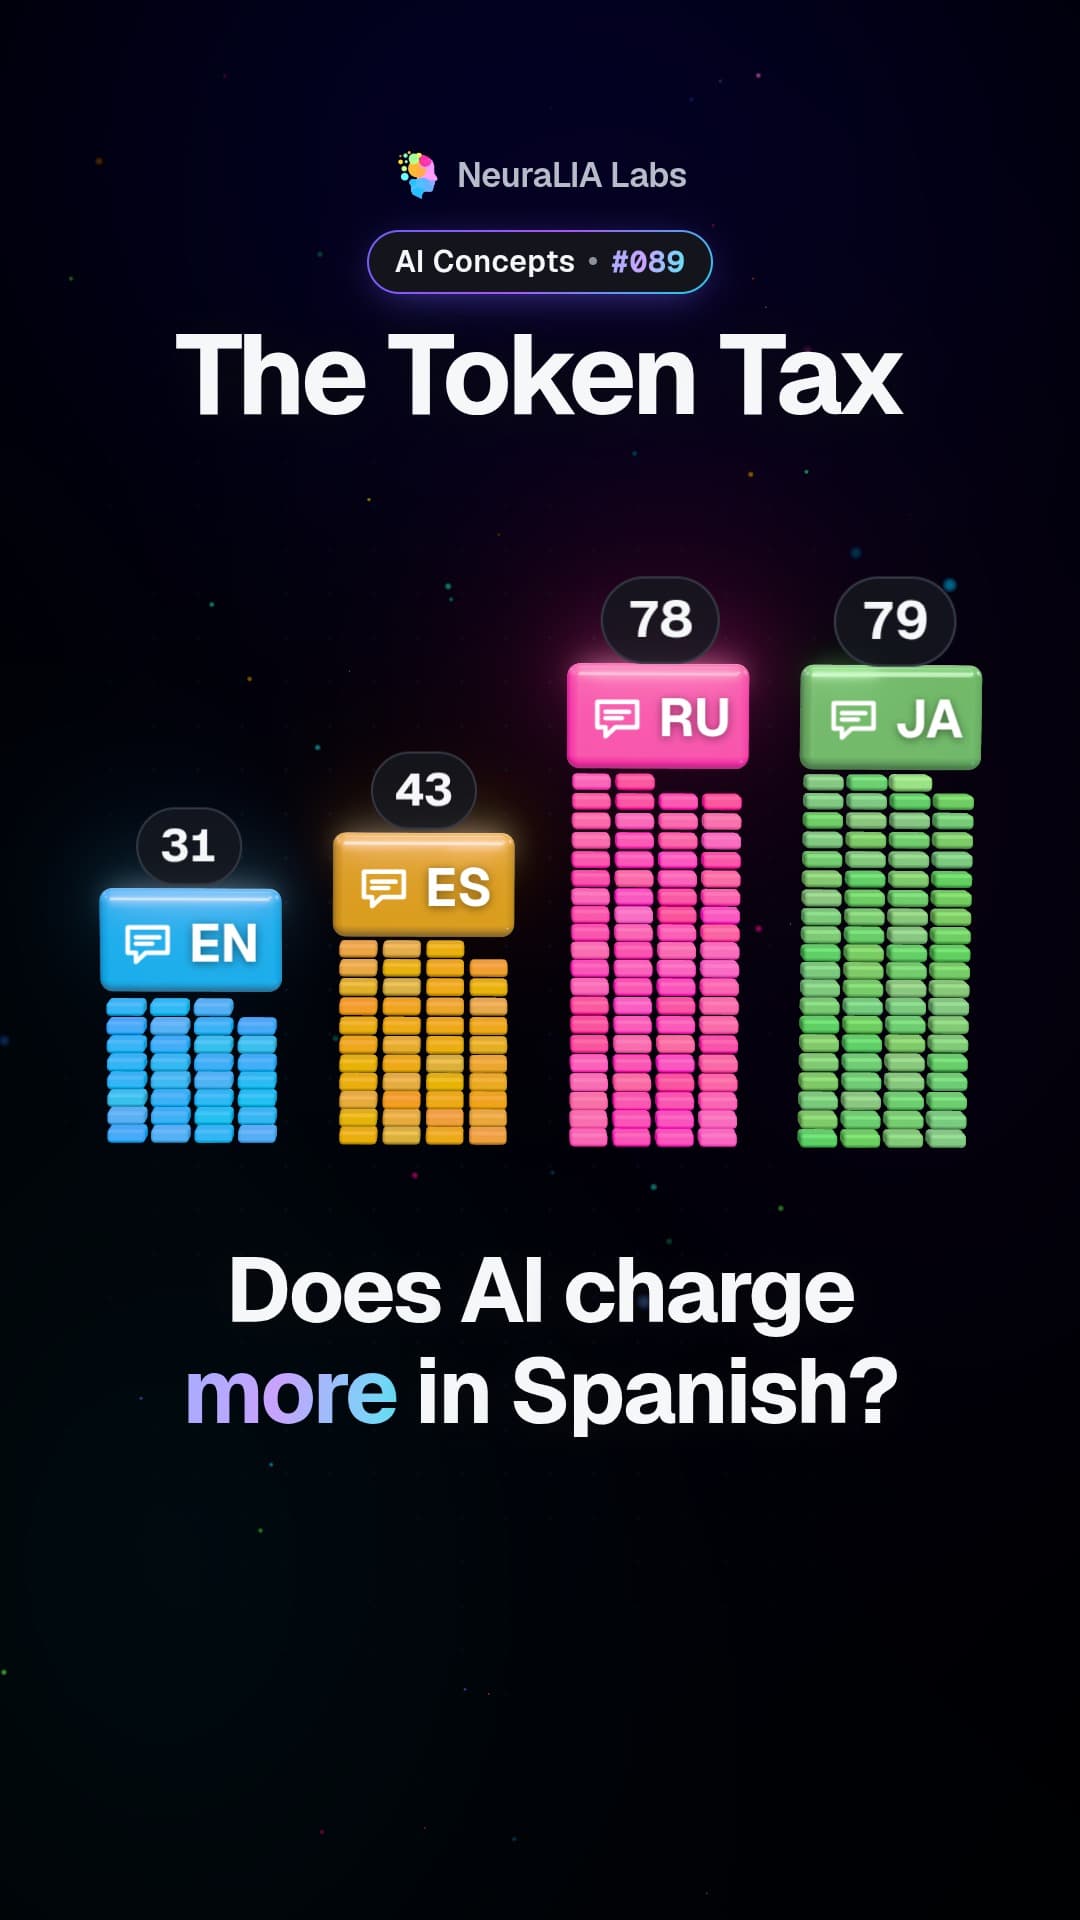
The token tax: why the same message costs more in some languages
Texto escrito com assistência de IA a partir do capítulo 7 do nosso curso gratuito.