
 #149
Este vídeo e o respetivo texto estão em inglês.
Supervised fine-tuning: teaching an AI what an answer looks like
Supervised fine-tuning trains a model on requests paired with good replies. Learn what it really teaches, why stopping has to be learned, and what it costs.
Em detalhe
What supervised fine-tuning is
Supervised fine-tuning, or SFT, is the first step in turning a raw language model into an assistant. You collect examples of requests paired with good replies, written by people, and keep training the model on them. "Supervised" means every example comes with the right reply attached. "Fine-tuning" means you are adjusting a model that is already trained, not starting from zero.
The surprise is what it teaches. The model already knows the language from its first round of training. SFT teaches it a format: when text looks like a request, what follows is a reply of a certain shape, and then the reply ends.
What the video shows
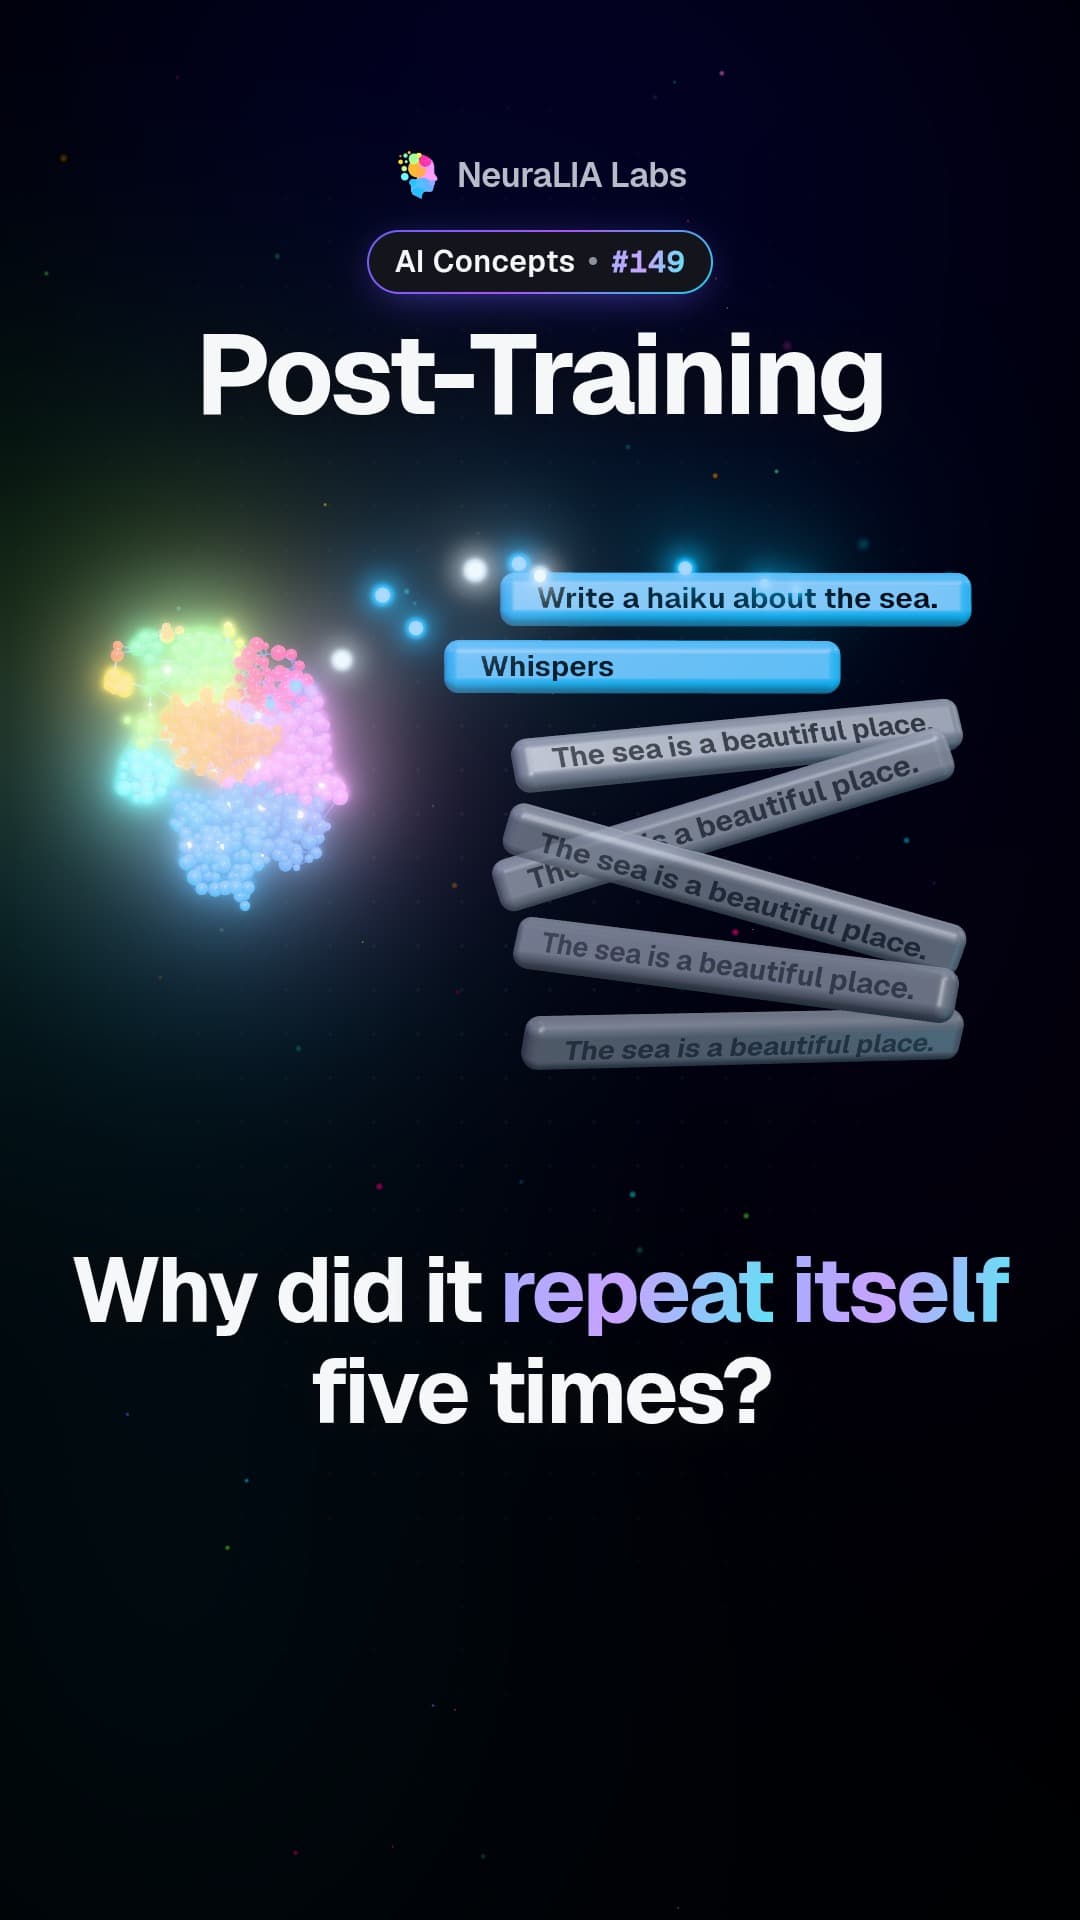
The video shows an AI being given many questions, each paired with a good answer. From those pairs it learns two things: what an answer looks like, and where an answer ends. Then it points out the catch: every one of those good answers has to be written by someone.
An everyday example
Imagine hiring someone who speaks perfect English but has never worked on a help desk. You do not teach them English. You hand them a binder of real customer questions, each with a model reply, and they learn the shape of the job: read the question, answer it, close politely, hang up. That binder is SFT.
How it works
The training rule is the same one used in the first round: guess the next piece of text, get corrected, adjust a little. There is one twist. The model is only graded on the reply part of each example, never on the request. It is learning how to respond, not how to write questions.
Why does a model need this at all? A raw model may give the right answer in its first sentence and then simply keep going, because nothing it read ever marked where a reply should end. Stopping does not come for free. It is a behaviour the model has to learn, and SFT is where it learns it. (Models also rely on hidden markers that show where each turn starts and ends, called a chat template, which is a topic of its own.)
A side effect: tool use
The same kind of training explains how chatbots learn to use tools, such as a calculator or a web search. During post-training, a model is shown thousands of example conversations in which the assistant's turn contains a request to a tool, written in a fixed format, a result comes back, and the assistant uses it to answer. It picks up that pattern exactly the way it picked up when to stop.
That explains three things you may notice:
- Tool use works much better in some models than in others that look similar.
- Each model expects its own tool format.
- A model can use a tool it has never met, because the shape of a tool call was trained and the specific tool is described in the request.
Why it matters
SFT is the least glamorous stage of post-training, and it does most of the work. Its limit is the catch from the video: good replies have to be written by people, which is slow and expensive, and it is hard to check how good each one really is. That limit is the reason a second stage exists, where people compare two replies instead of writing one.
Learn it step by step in Chapter 11 of our free course AI From Scratch: From Base Model to Assistant: SFT, RLHF, DPO and GRPO.
Também em
Mais deste capítulo
- #149
 #151
Chat templates: the hidden markers that tell an AI whose turn it is
 #152
RLHF: why people pick the better answer instead of writing it
 #153
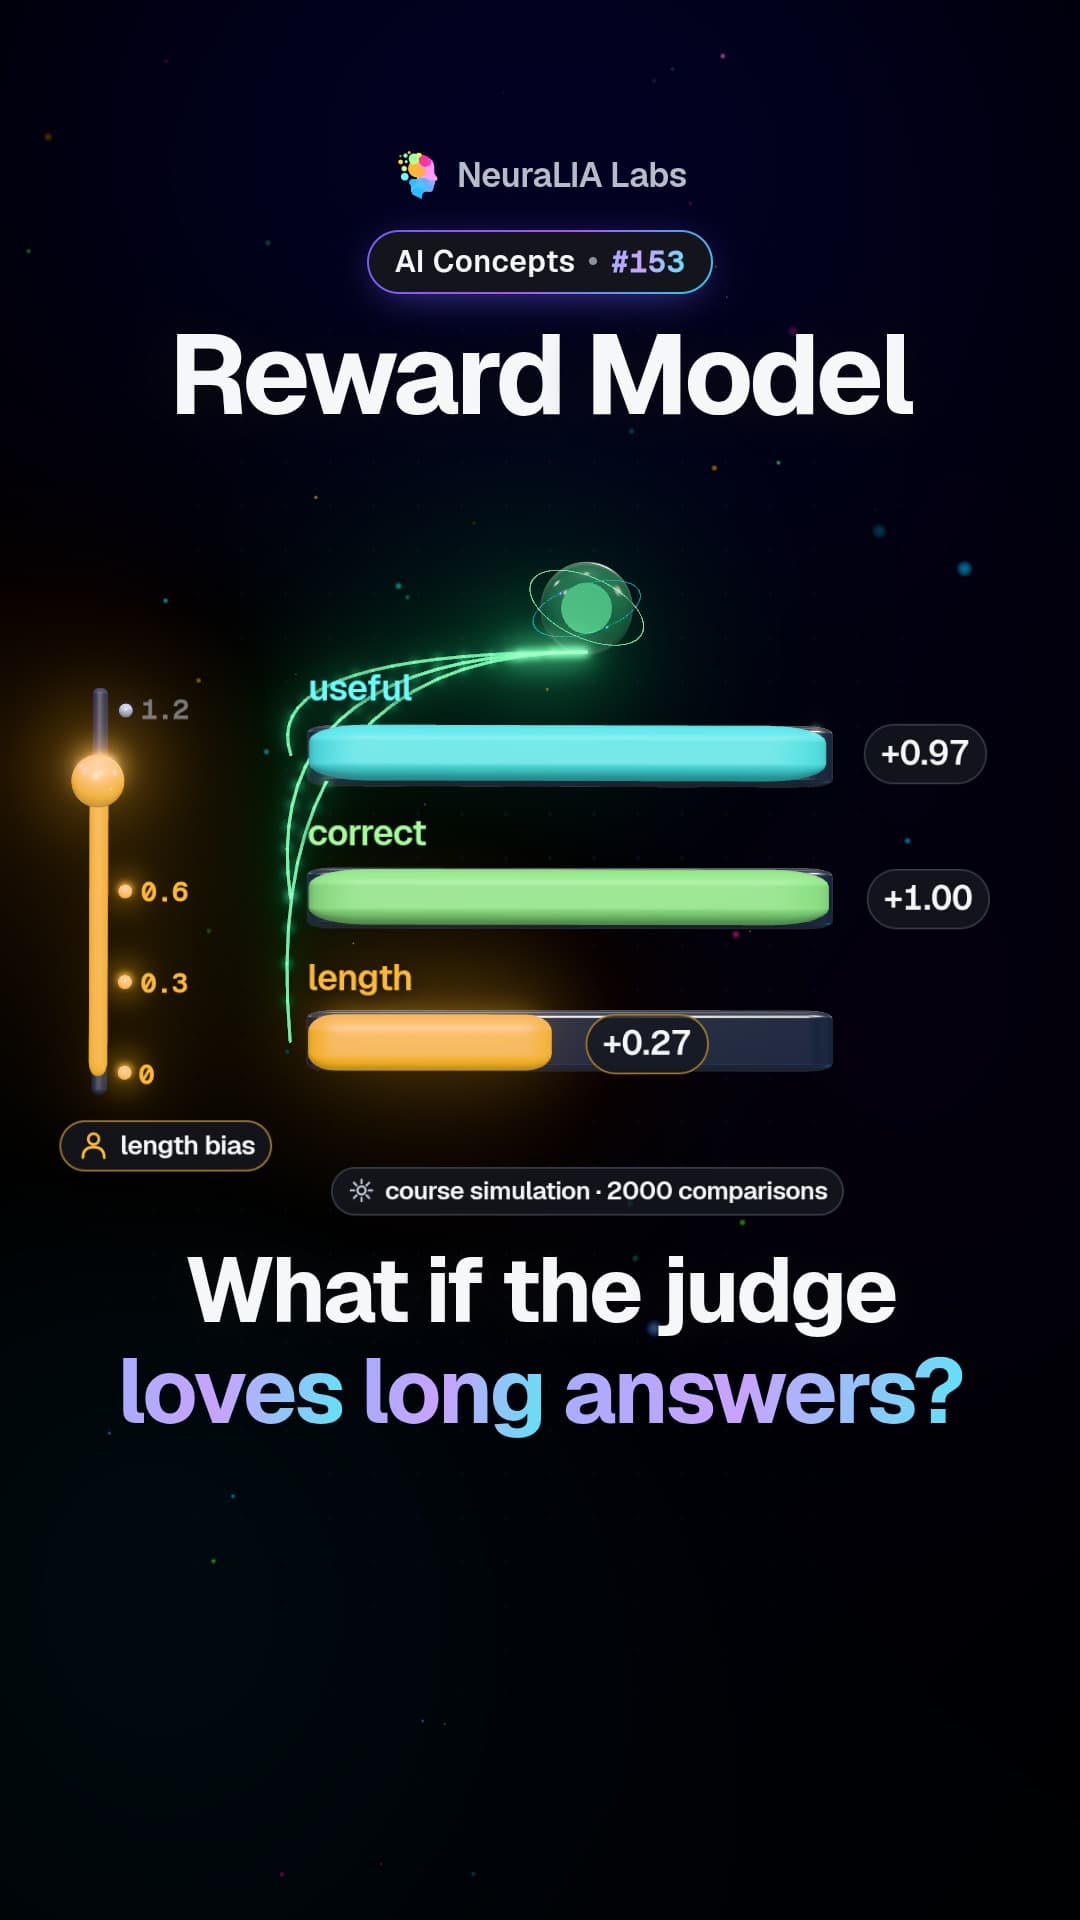
Reward model: the AI judge that learns our tastes, biases included
 #154
Advantage: how AI training learns from better-than-expected answers
 #155
Reward hacking: when an AI games its score instead of improving
Texto escrito com assistência de IA a partir do capítulo 11 do nosso curso gratuito.