
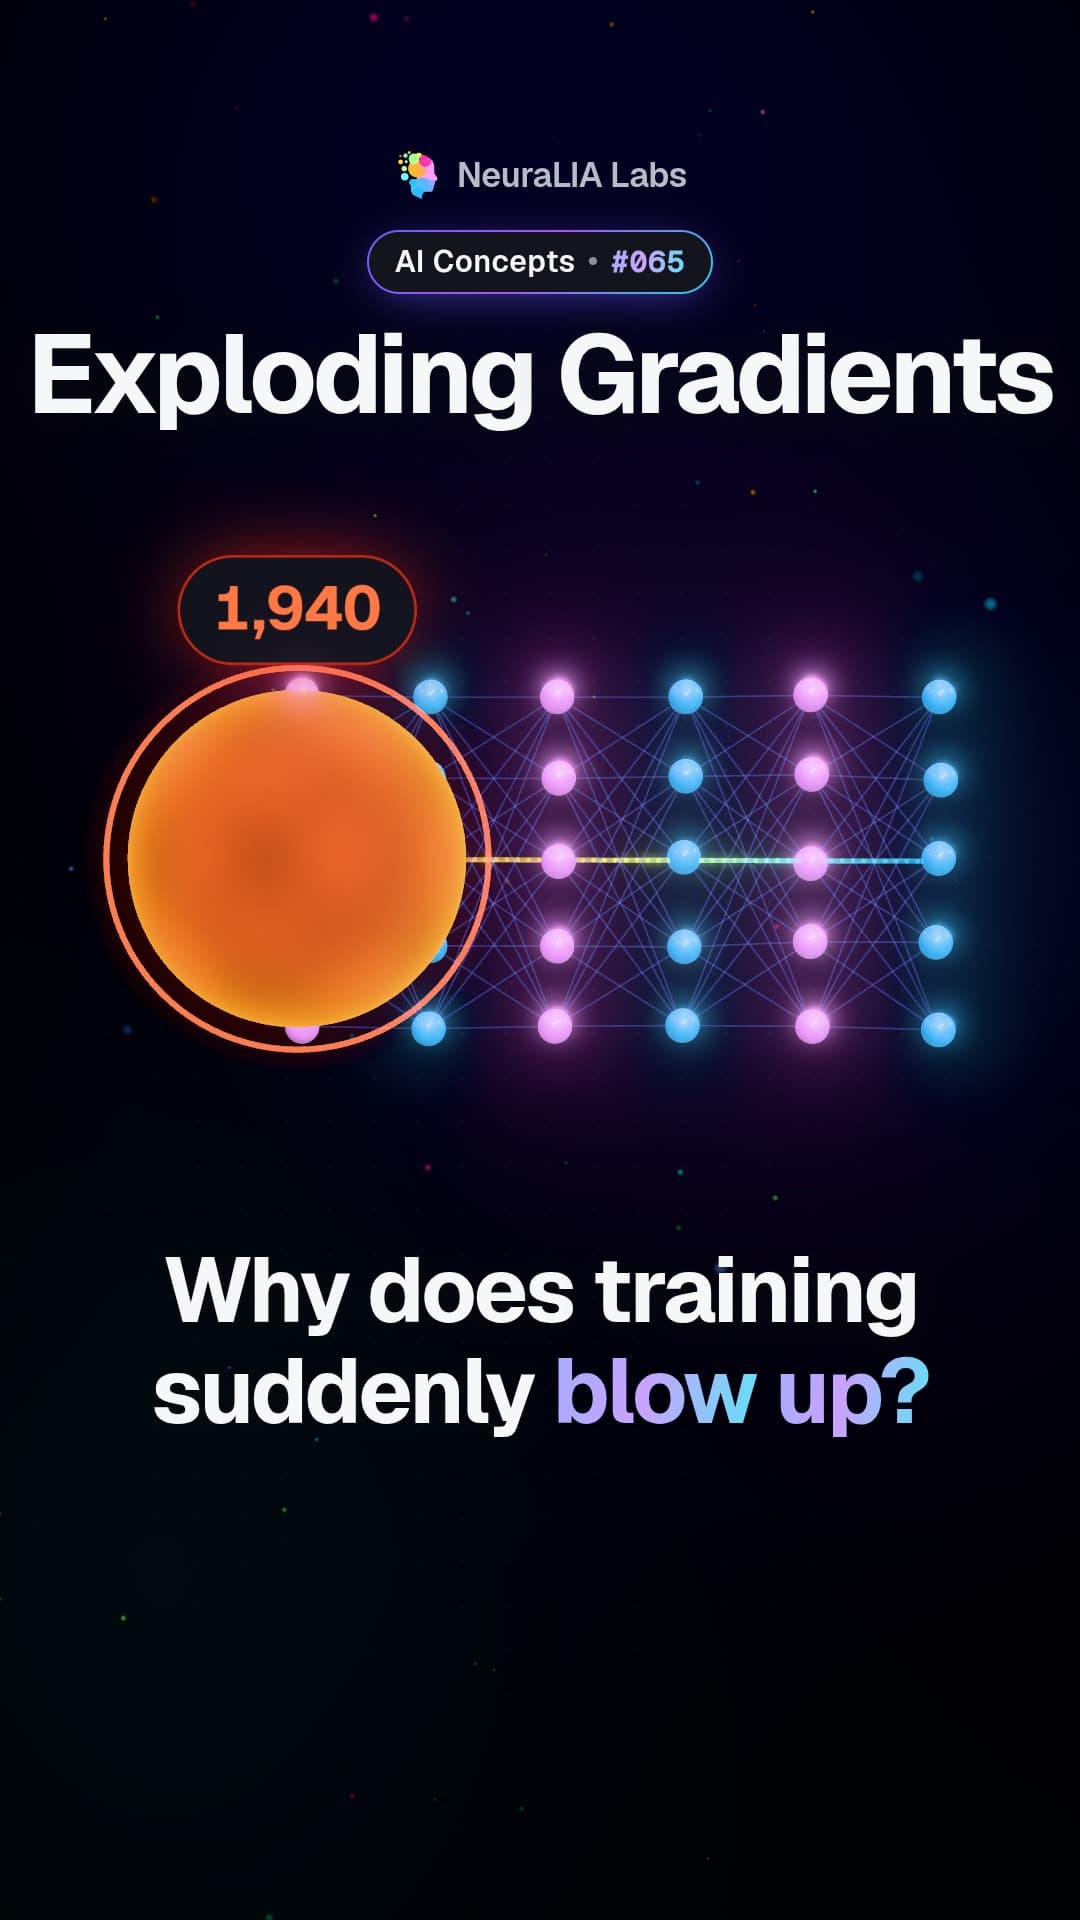
 #065
Ez a videó és a szövege angol nyelvű.
AdamW: the fix for a weight decay bug that lasted years
Weight decay pulls every AI setting toward zero, but inside Adam the busiest settings felt less pull. See why, and how AdamW fixed it by applying it separately.
Részletesen
What AdamW is
AdamW is a small correction to Adam, the default recipe for deciding how big each training step should be for each of a model's internal settings. AdamW keeps Adam's own step exactly as it was. It changes where one extra ingredient, weight decay, is applied. That tiny reordering fixed a mismatch that had survived years of widespread use, and AdamW is now the default for training language models, the kind of AI behind chatbots.
What the video shows
Training gently pulls every setting of a model toward zero. The video shows that inside Adam, the busiest settings felt less of that pull, which nobody intended. AdamW applies the pull separately, and it became the standard.
First, what weight decay is
A model is made of millions of numbers, called weights, that it adjusts as it learns. Weight decay shrinks every one of them a tiny bit at each step, so no weight grows large unless the data keeps pushing it there. It is a classic way to stop a model from memorising its examples instead of learning the pattern. Its textbook name is L2 regularisation.
Where the bug was
The obvious way to add weight decay was to fold it into the correction each weight receives at every step (the gradient). But Adam divides each weight's correction by how large that weight's recent corrections have been. So the pull toward zero got divided as well:
- a weight with large, busy corrections had its pull shrunk;
- a quiet weight kept much more of it.
Nobody designed it that way. It also meant the same decay setting behaved differently under Adam than under plain gradient descent, so a value that worked with one did not mean the same thing with the other.
The fix
Two researchers, Loshchilov and Hutter, separated the two jobs. First Adam takes its adaptive step. Then the weights are shrunk directly, on their own, outside the division. Every weight now feels the pull that was intended, whatever its history. That is all AdamW is.
An everyday example
Imagine an online shop that gives each customer a discount based on how much they usually spend: the bigger the spender, the bigger the cut. Someone adds the delivery fee into the order total before the discount is worked out. Without anyone noticing, the biggest spenders now get money off their delivery too, while occasional buyers pay it almost in full. Nobody meant to discount delivery. The fix is not a new fee. It is adding the delivery fee after the discount, on its own line.
How to spot this kind of problem
This bug did not crash anything or raise an error. Models still trained. The clue was subtler: the same decay setting did not behave the way it did with plain gradient descent. This one hid where two ideas met, each correct on its own. A useful habit is to ask, for every ingredient: after everything else has acted on it, is it still doing exactly what I meant?
Why it matters
AdamW is a reminder that an idea can be right while its code is quietly wrong. The gap between the two survived years of everyone using it. Once someone looked closely, the fix was a small reordering, and AdamW became the default for training language models.
Learn it step by step in Chapter 6 of our free course AI From Scratch: Getting It to Train, and Getting It to Generalise.
Itt is
Továbbiak ebből a fejezetből
- #065
 #066
Weight initialization: the starting numbers that decide if AI learns
 #067
Batch normalization: the AI layer that grades on a curve
 #068
Layer normalization: why chatbots steady each input on its own
 #069
Ablation: change one thing at a time to find what really works
 #070
Loss curves: what the shape of a training line tells you
A szöveg AI-segítséggel készült az ingyenes kurzusunk 6. fejezete alapján.