
 #174
Deze video en de bijbehorende tekst zijn in het Engels.
Quantization: shrinking an AI by storing its numbers more roughly
Quantization makes AI models smaller and faster by rounding their numbers. Learn why 8 bits cost almost nothing while careless 4-bit rounding broke a model.
In detail
What quantization is
An AI language model is, underneath, an enormous list of numbers called weights: the settings it learned during training. Each weight is normally stored with 32 or 16 bits (bits are the 0s and 1s a computer saves; more bits means a more precise number). Quantization stores each weight with fewer bits, such as 8 or 4. Put simply, it rounds the model's numbers so they take up less room.
The saving is easy to see. The course uses a small model with half a billion weights. It needs about 2 GB of memory at 32 bits, about 1 GB at 16 bits and about 0.5 GB at 8 bits. There is a speed bonus too. When a model writes text, each step is held back mainly by how fast its numbers can be fetched from memory, not by the arithmetic. Fewer bytes to fetch means faster steps.
What the video shows
The video shows the basic trade: store an AI's numbers more roughly to save memory and run faster. Then it shows the course's test. Careful 8-bit rounding cost nothing measurable. Careless 4-bit rounding broke the model completely.
"Broke" is not an exaggeration. The course scores the model with perplexity, a measure of how confused it is by real text, where lower is better. With the careless 4-bit version, that score shot into the hundreds of millions. The model was effectively producing noise.
An everyday example
Imagine saving a photo with fewer colours. With 256 shades to pick from, the copy usually looks close to the original, and the file is much smaller. With only 16 shades, everything depends on which 16 you choose. Choose badly and a sunset turns into a few flat blobs.
Quantization makes the same trade with numbers. At 8 bits each weight can take one of 256 values. At 4 bits it can take only 16.
How the simplest version works
The most basic recipe has three steps:
- Look at a whole table of weights and find the one furthest from zero. Choose a scale so that this weight lands on the biggest whole number available.
- Divide every weight by that scale and round it to the nearest whole number. Keep those whole numbers plus the single scale.
- When the model runs, multiply back by the scale to get approximate weights.
At 8 bits this is good enough: with 256 steps, a typical weight still lands near its true value. At 4 bits, with one scale per table, it collapses. A few unusually large weights decide how wide every step is. The steps end up far too wide for everyone else, and millions of ordinary weights get squashed onto the same two or three values.
A cliff, not a slope
It is tempting to picture each bit you remove making a model a little worse, one small step at a time. The course's numbers look more like a cliff. The simple one-scale recipe holds up at 8 bits, yet the very same recipe at 4 bits breaks the model. Across the model's weight tables, the average rounding error grows about fifteenfold between the two. How you round matters as much as how much you round.
Why it matters
Quantization is one of the main levers for making a model cheaper to store and faster to run. Knowing where it breaks tells you what to ask about any shrunken model: how many bits, and how were the scales chosen? The repairs that make 4 bits work, such as giving small groups of weights their own scale or spacing the steps unevenly, each get their own explanation in this series.
Learn it step by step in Chapter 13 of our free course AI From Scratch: Making Inference Cheap: KV Cache, Batching and Quantization.
Ook op
Meer uit dit hoofdstuk
- #174
 #175
Prefill vs decode: why a chatbot pauses first, then streams smoothly
 #176
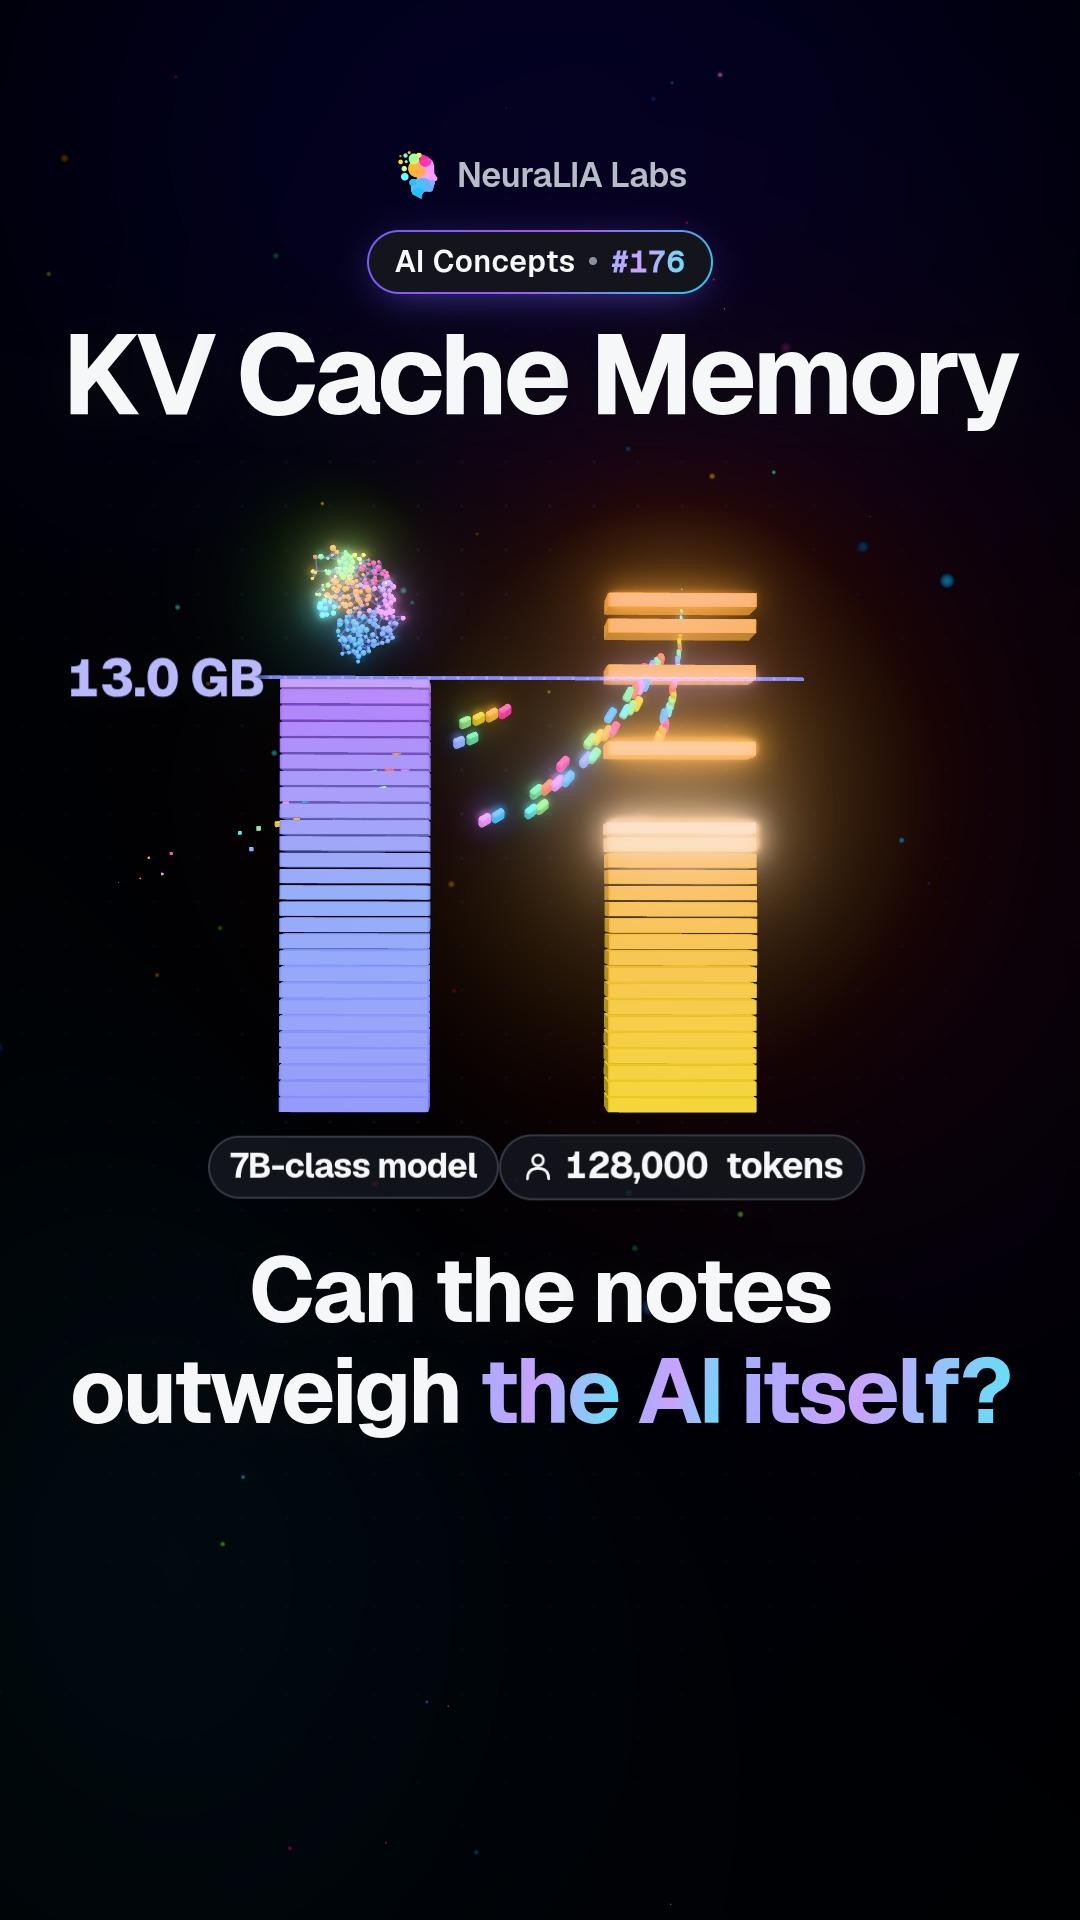
KV cache memory: when a chatbot's notes outgrow the model itself
 #177
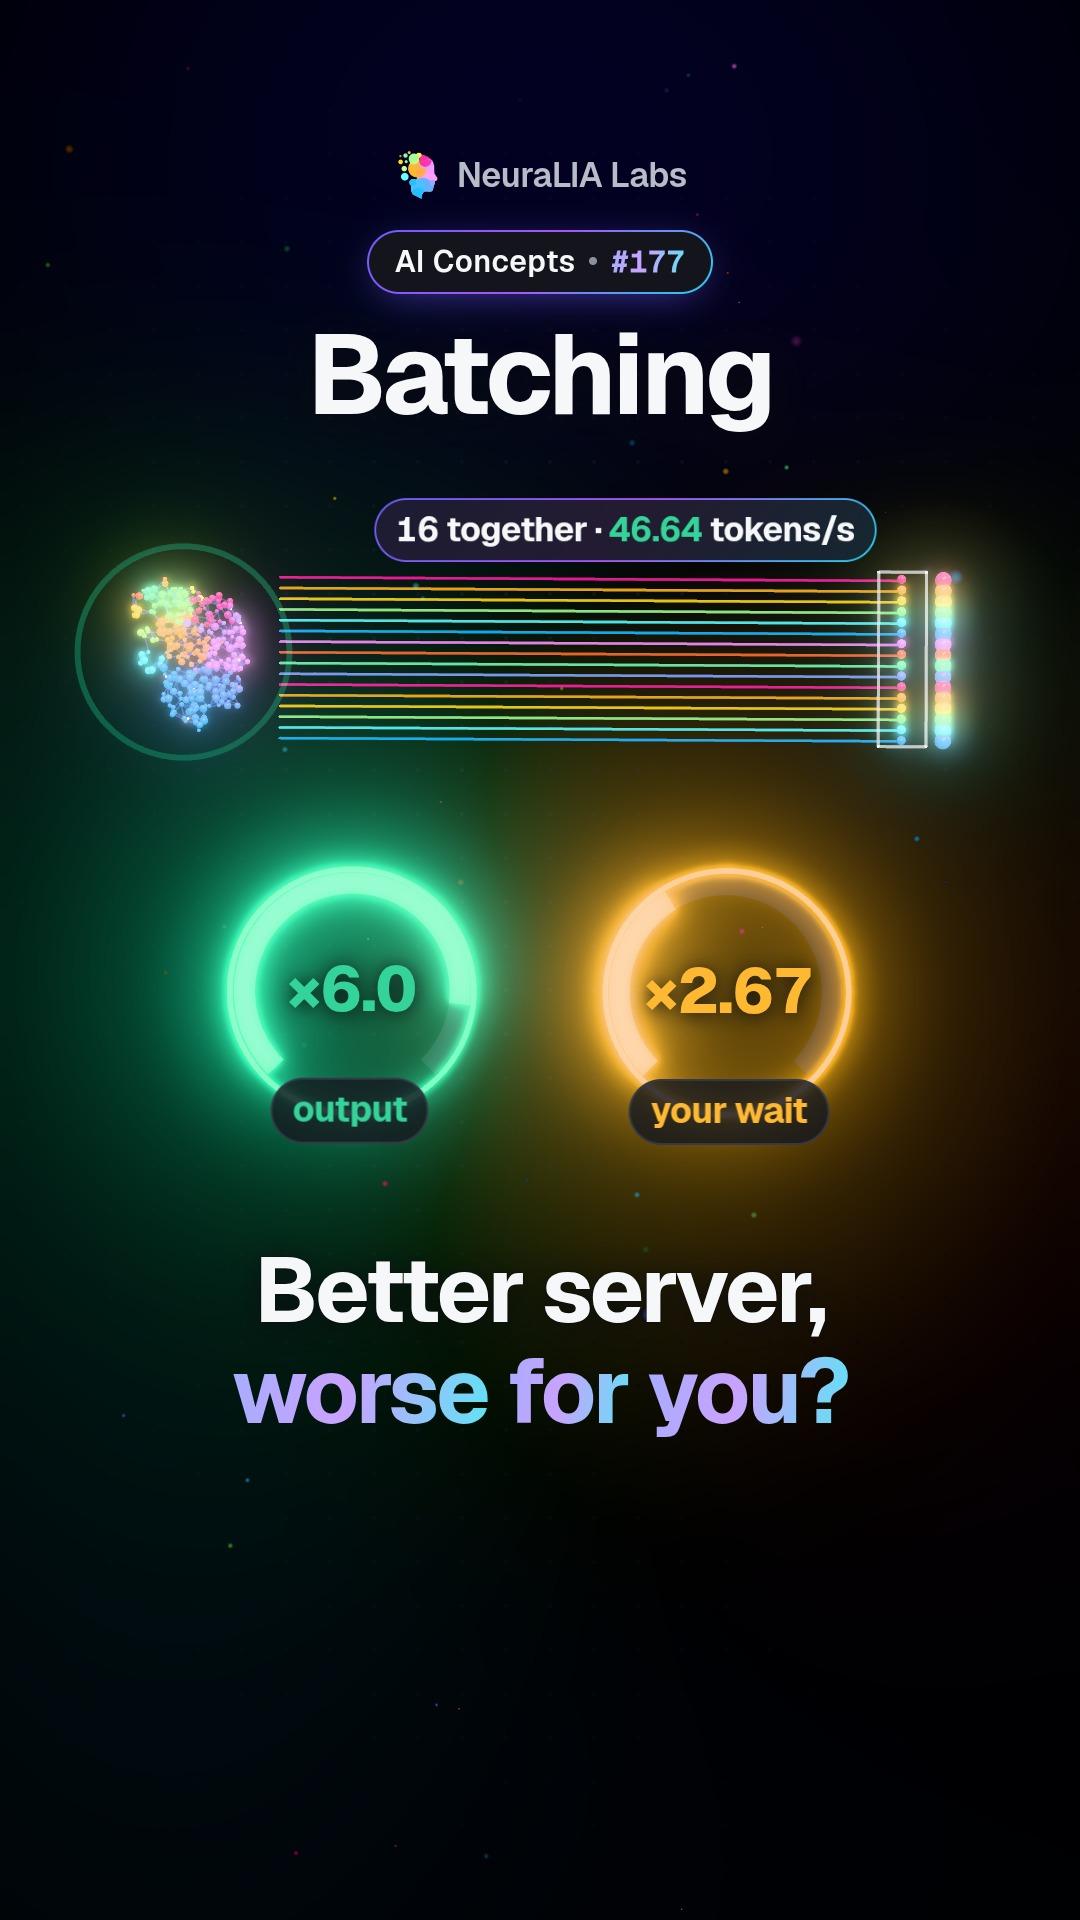
Batching: more output per second, but a longer wait for each user
 #178
Continuous batching: no more waiting for the slowest reply
 #179
PagedAttention: the parking-lot trick behind busy AI servers
Tekst geschreven met AI-hulp op basis van hoofdstuk 13 van onze gratis cursus.