
 #174
Deze video en de bijbehorende tekst zijn in het Engels.
GPTQ: rounding an AI's numbers and fixing the errors as you go
GPTQ shrinks an AI model by rounding its numbers one column at a time and correcting each small error as it goes. The idea, with a bill-splitting example.
In detail
What GPTQ is
GPTQ is a way to shrink a large AI model so it needs less memory. A model is made of billions of learned numbers, called weights. Shrinking it usually means quantization: storing each weight with fewer digits, a bit like rounding prices to the nearest euro. The simple approach rounds every number on its own and hopes for the best. GPTQ is more careful. It does not just round; it chooses how to round, so the model keeps giving almost the same answers.
What the video shows
The video shows the core move. The model's numbers are rounded one column at a time. After each column, the numbers that have not been rounded yet get a small nudge to make up for the error that was just introduced. By the end every number has been rounded, yet what the model produces has barely changed.
An everyday example
Imagine five friends splitting a restaurant bill of 87.40 euros, and everyone wants to pay in whole euros. Each share is 17.48. If every share is rounded to the nearest euro on its own, everyone pays 17 and the group is 2.40 short.
Now try it the GPTQ way. The first friend pays 17, and the 48 cents left over are added to the second friend's share, which becomes 17.96, so they pay 18. The 4 cents they overpaid are taken off the third share, and so on down the table. The five payments come out as 17, 18, 17, 18 and 17. Nobody's share is exact, but the group is only 40 cents short instead of 2.40.
The bill total is what matters, not whether each share matches 17.48. GPTQ thinks the same way. What it protects is a layer's output, the result one stage of the model hands to the next, not each weight's original value.
How it works
- Column by column. GPTQ handles one layer of the model at a time and, inside it, one column of weights at a time.
- Fix the rest. After rounding a column, it adjusts the columns still at full precision so they soak up the error it just made.
- Judged on real inputs. To know which errors matter, it passes a small sample of real text through the layer. This sample is called a calibration set. The aim is to keep the layer's output on those real inputs close to the original.
- No retraining. It needs no gradients, the learning signals used when a model is trained, so there is no retraining step.
The rounded weights it produces are built to run on graphics cards (GPUs). If a model download is labelled GPTQ, its numbers were rounded this way and it is meant for a graphics card.
A common misconception
It is tempting to think the best rounding keeps every number as close as possible to the original. Plain rounding does exactly that, and it never asks what the numbers are for. GPTQ is willing to move the numbers it has not rounded yet, because the thing it guards is the answer the layer gives. A sibling method, AWQ, takes another route and protects the most important numbers up front.
Why it matters
Shrinking a model, for example down to 4 bits per number, lets it run on smaller and cheaper hardware. The open question is always how much quality is lost on the way. GPTQ's answer is to stop the small errors from piling up: each rounding mistake is paid back by the numbers that come after it.
Learn it step by step in Chapter 13 of our free course AI From Scratch: Making Inference Cheap: KV Cache, Batching and Quantization.
Ook op
Meer uit dit hoofdstuk
- #174
 #175
Prefill vs decode: why a chatbot pauses first, then streams smoothly
 #176
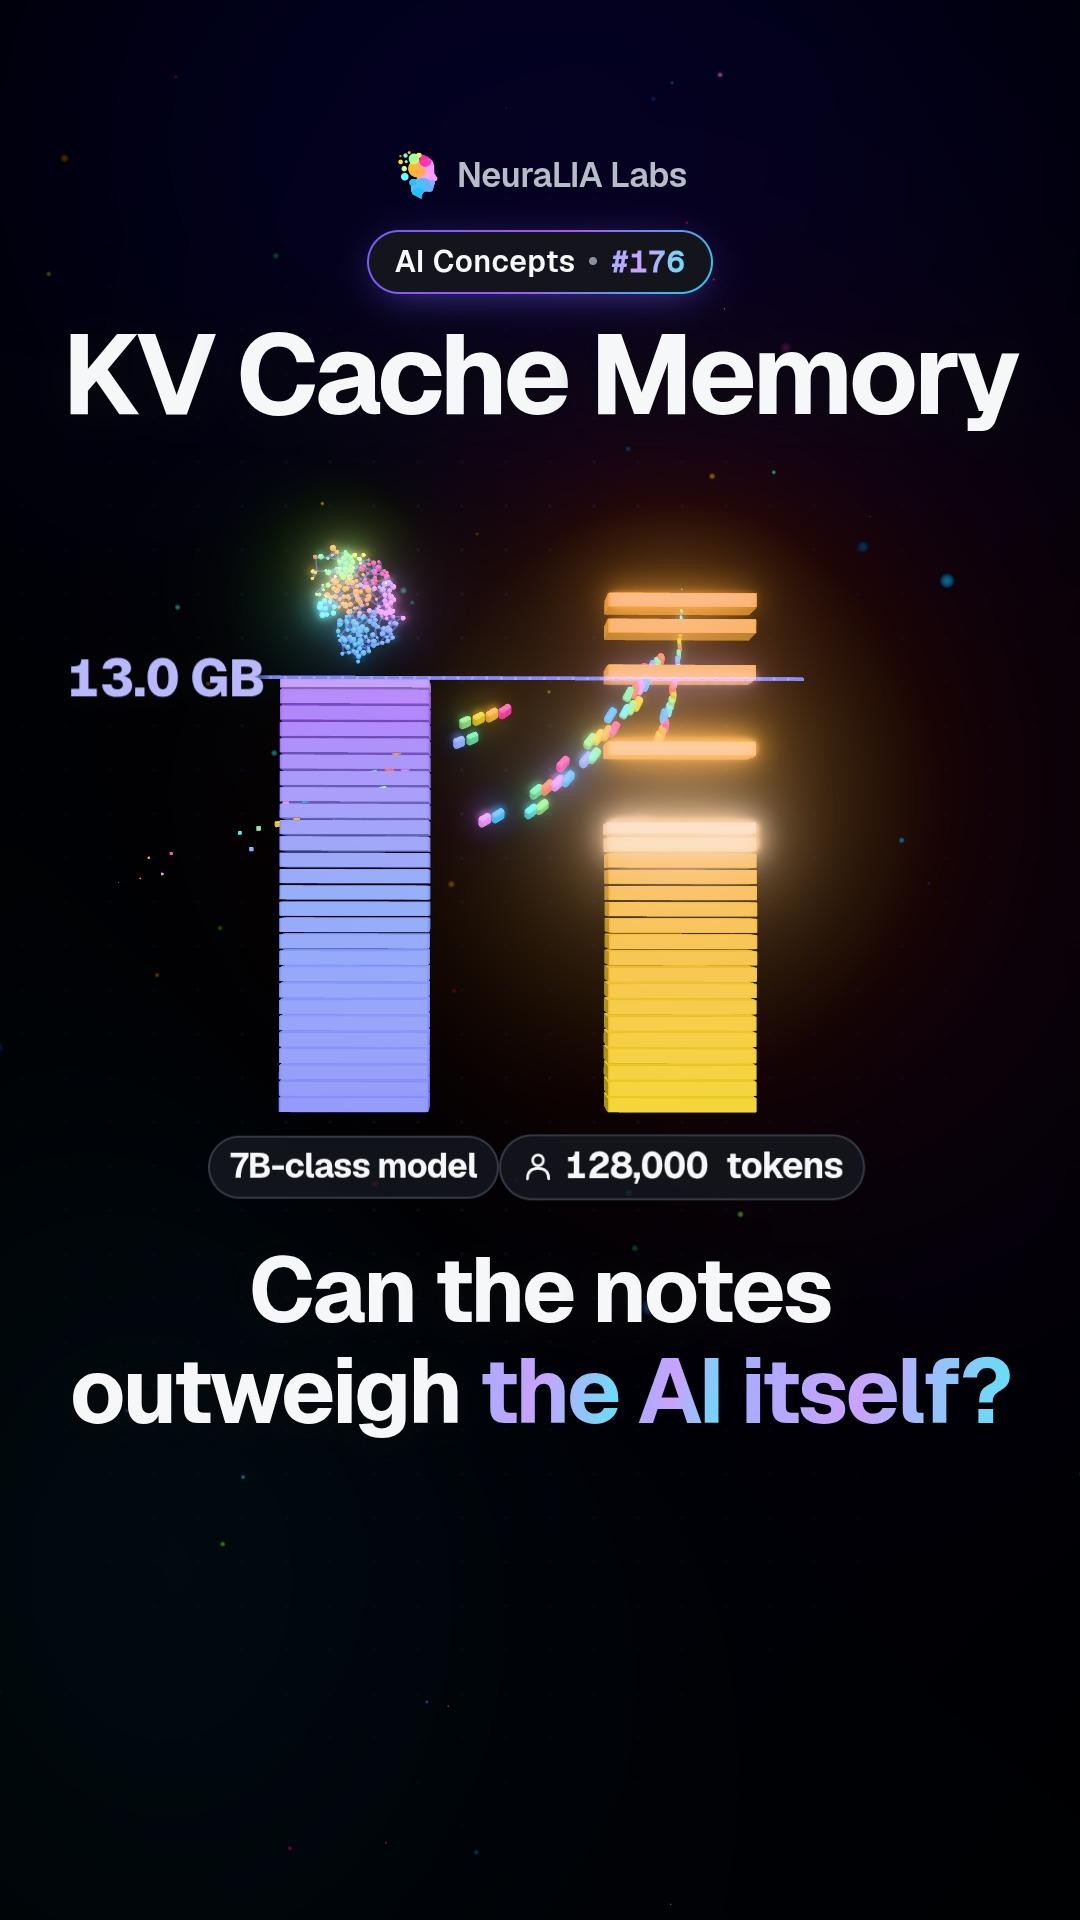
KV cache memory: when a chatbot's notes outgrow the model itself
 #177
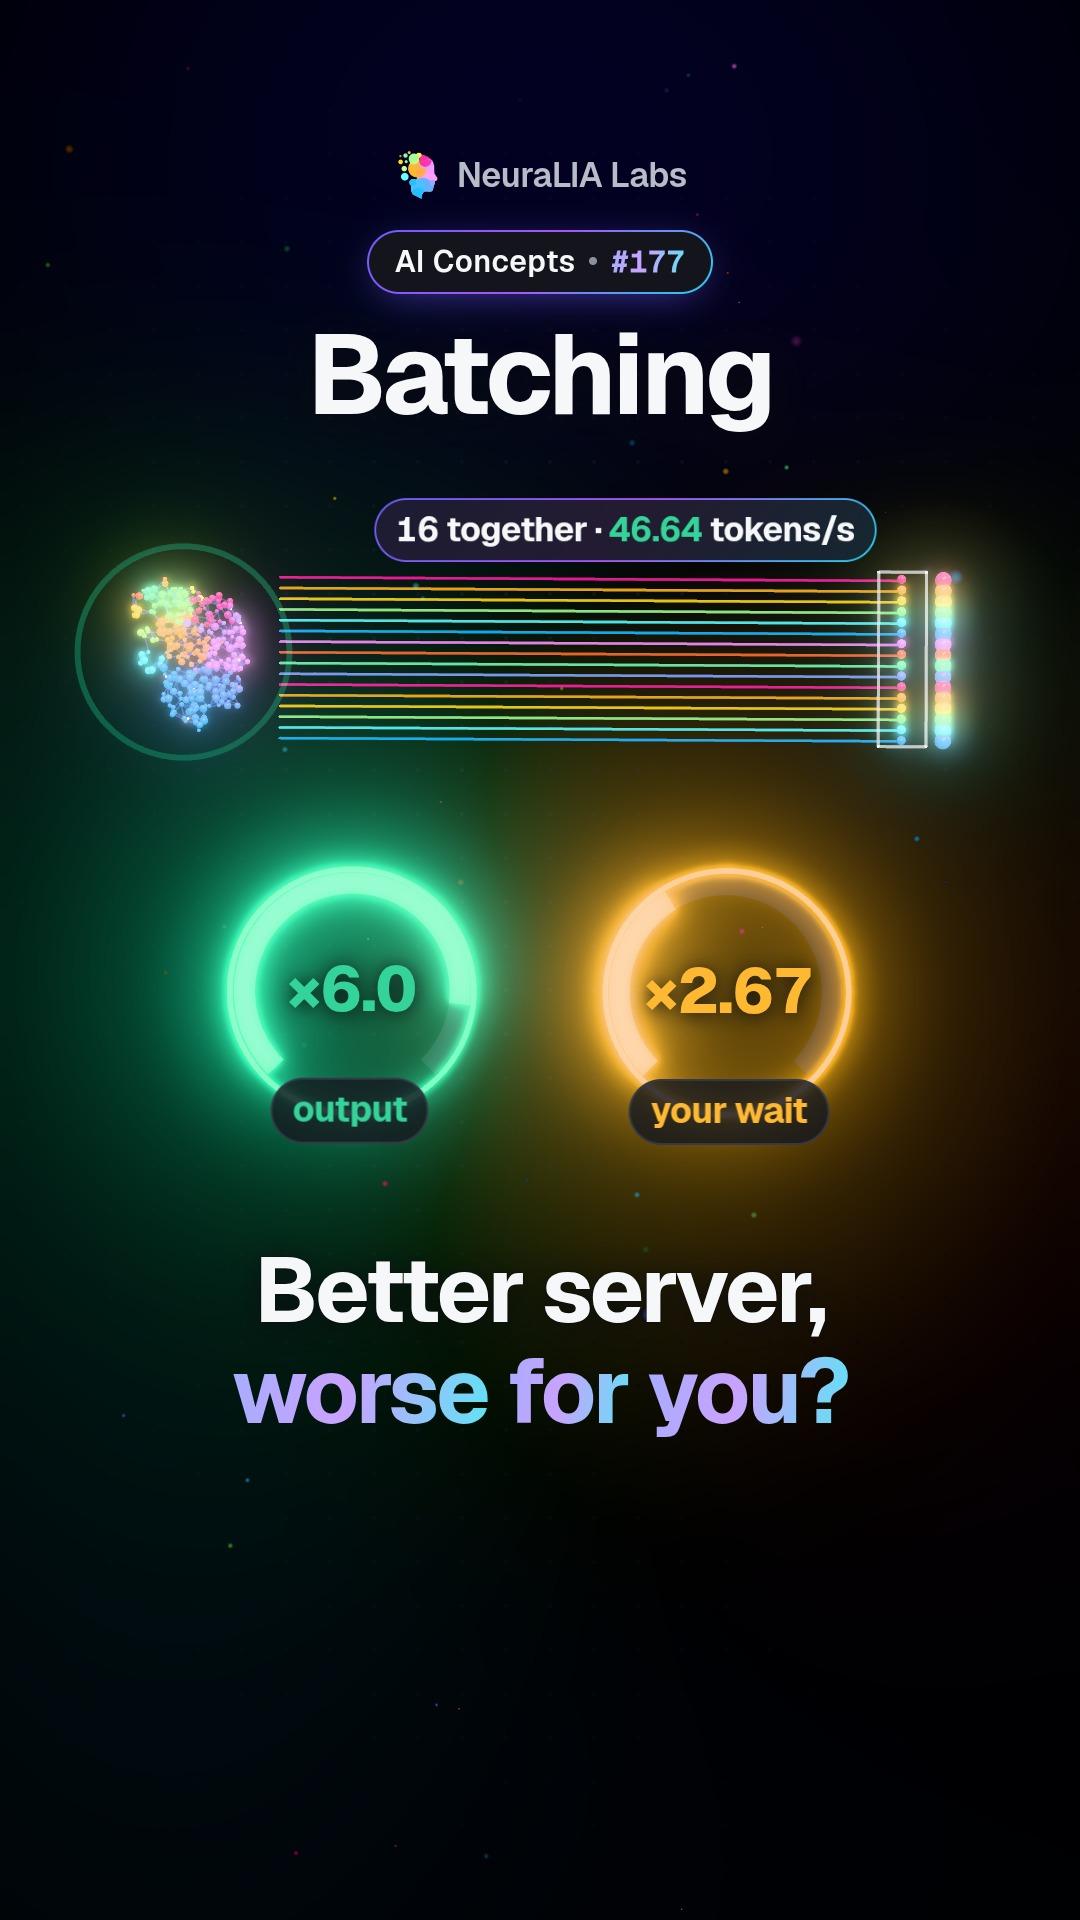
Batching: more output per second, but a longer wait for each user
 #178
Continuous batching: no more waiting for the slowest reply
 #179
PagedAttention: the parking-lot trick behind busy AI servers
Tekst geschreven met AI-hulp op basis van hoofdstuk 13 van onze gratis cursus.