
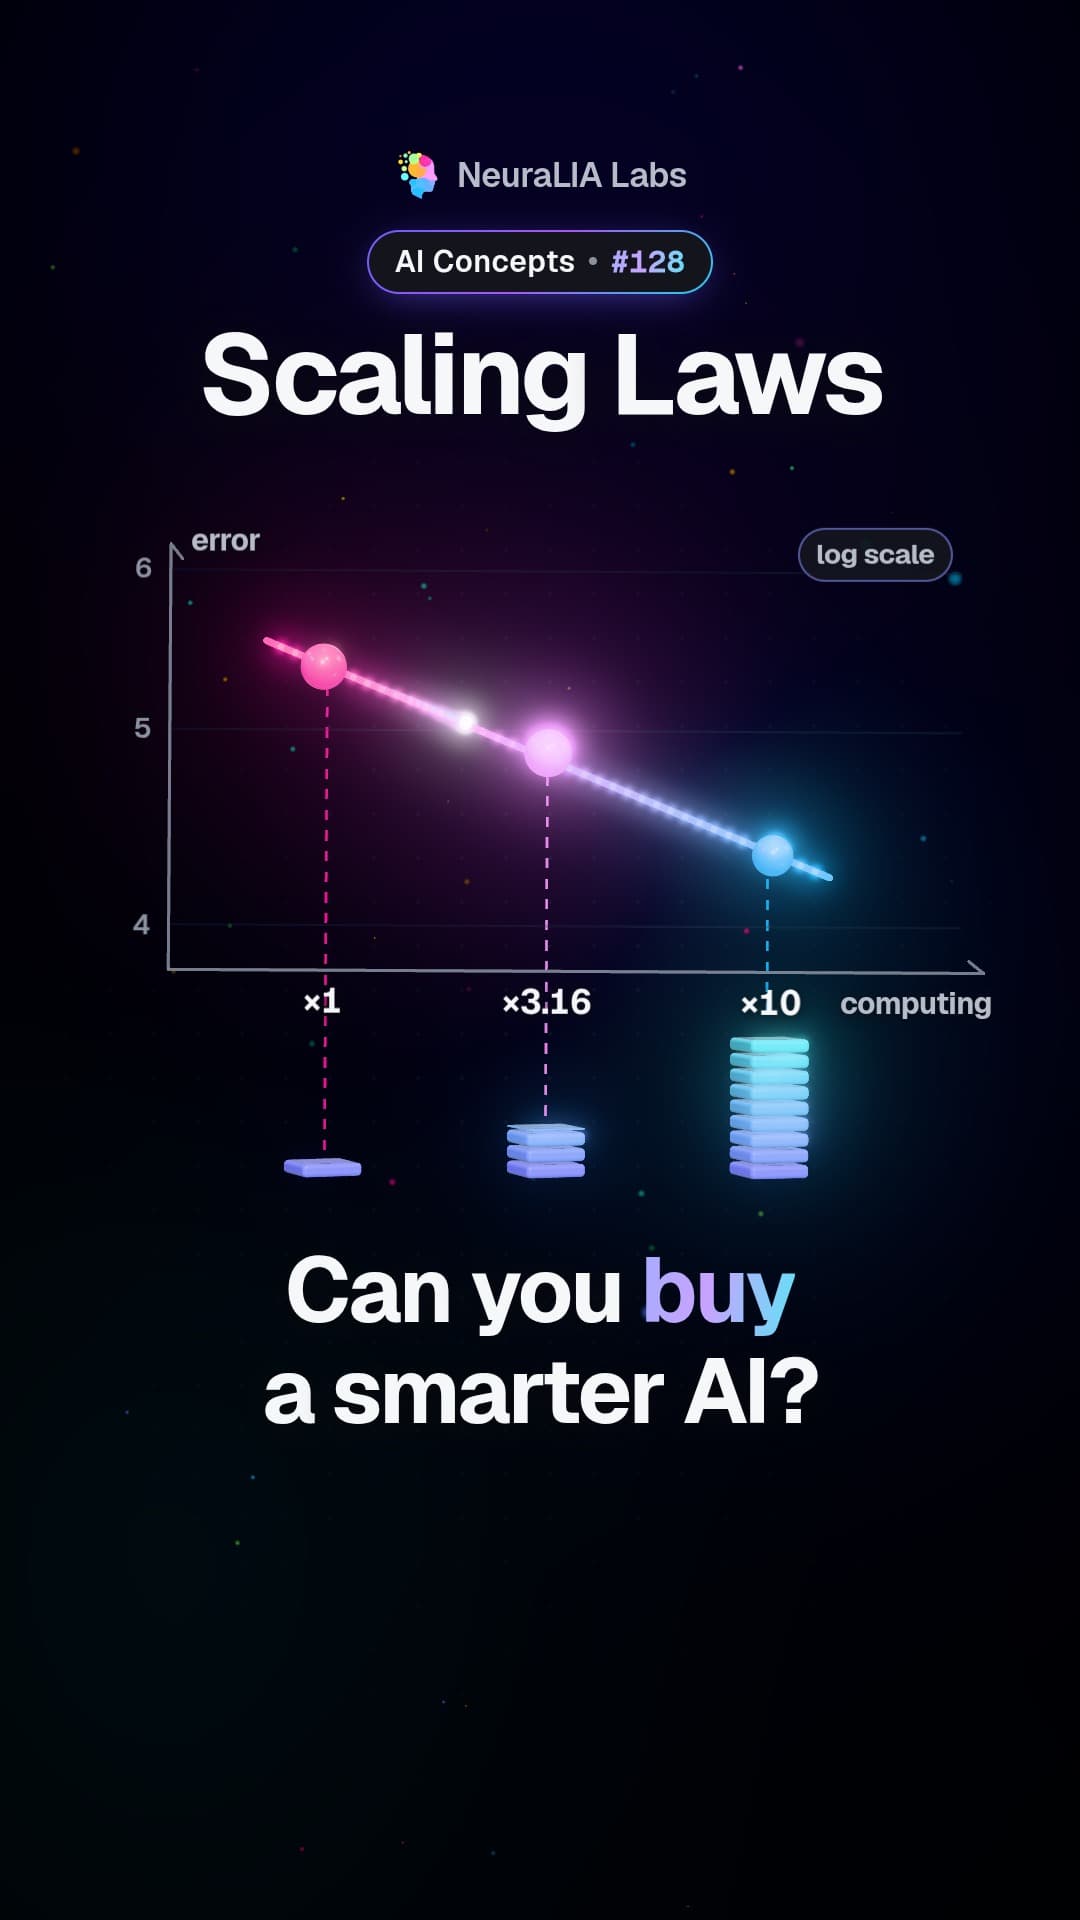
 #128
이 영상과 텍스트는 영어로 제공됩니다.
Pretraining: the guess-the-next-word game played on a whole library
Pretraining is not a new algorithm. It is the same next-word guessing game, run on so much text that every choice has a price. Here is how it works.
자세히
What pretraining is
Pretraining is the expensive first stage in building a large language model, the kind of AI behind chatbots. The model is taught one thing: to predict the next token, a small piece of text such as a word or part of a word. It does this over and over, across an enormous collection of text.
The surprise is that nothing about the method is new. It is the same guessing game, with the same scoring rule and the same way of adjusting the model, that the course uses on small models in earlier chapters. What changes is the size. The pile of text is so large that the training run has to be planned and paid for like a building project.
What the video shows
The video sums it up simply. Pretraining is the same guess-the-next-word game, played on an enormous library. That library is so big that every choice becomes a purchase. And what comes out at the end continues text; it does not answer questions yet.
The choices in question are the ones every training run has to make: how large the model is, how much text it reads and how long it trains.
An everyday example
Imagine turning any book into a quiz. Cover everything after the first word, guess the next word, uncover it, check, and move on. Nobody has to write an answer key, because the book already is the answer key.
That is the quiet trick that makes pretraining possible. Many AI projects need people to label examples by hand, for example tagging thousands of photos as "cat" or "dog". Here, the correct answer for every position is simply the token that comes next, and it is already sitting in the text. The labels are free, so the only limit is how much text you can collect and how much computing you can pay for.
How it works
Every training step follows the same loop:
- The model reads a stretch of text and, at each position, gives a probability to every possible next token.
- A scoring rule called cross-entropy measures how surprised the model was by the token that really came next. A big surprise means a big penalty.
- An adjustment method (the course uses one called AdamW) nudges the model's settings so that, next time, the right token looks a bit less surprising.
Then it repeats, across the whole library.
Why a giant model does not simply memorise
An old rule of thumb said that a model with far more adjustable settings than training examples would just memorise its data and fail on anything new. If that were the whole truth, giant models would be pointless. An effect called double descent (the name refers to the error dropping, rising for a while, then dropping a second time as the model grows), covered earlier in the course, removed the objection: models far larger than the classical rules allow keep getting better instead of falling apart.
A common misconception
It is tempting to imagine pretraining as a special, secret kind of learning. It is not. It is the ordinary next-token recipe, run at a scale where the hard questions become about budget: how much compute, how much memory, how much money. Those questions each have their own story in the rest of the chapter.
Why it matters
Knowing that pretraining is "just" a guessing game explains both its power and its limits. The power comes from free labels and sheer volume. The limit is what it produces: a base model, a text continuer that has not yet learned to act as an assistant. That takes a later stage of training.
Learn it step by step in Chapter 10 of our free course AI From Scratch: Pretraining an LLM: Data, Compute, Scaling Laws and Cost.
다른 플랫폼
이 챕터의 다른 영상
- #128
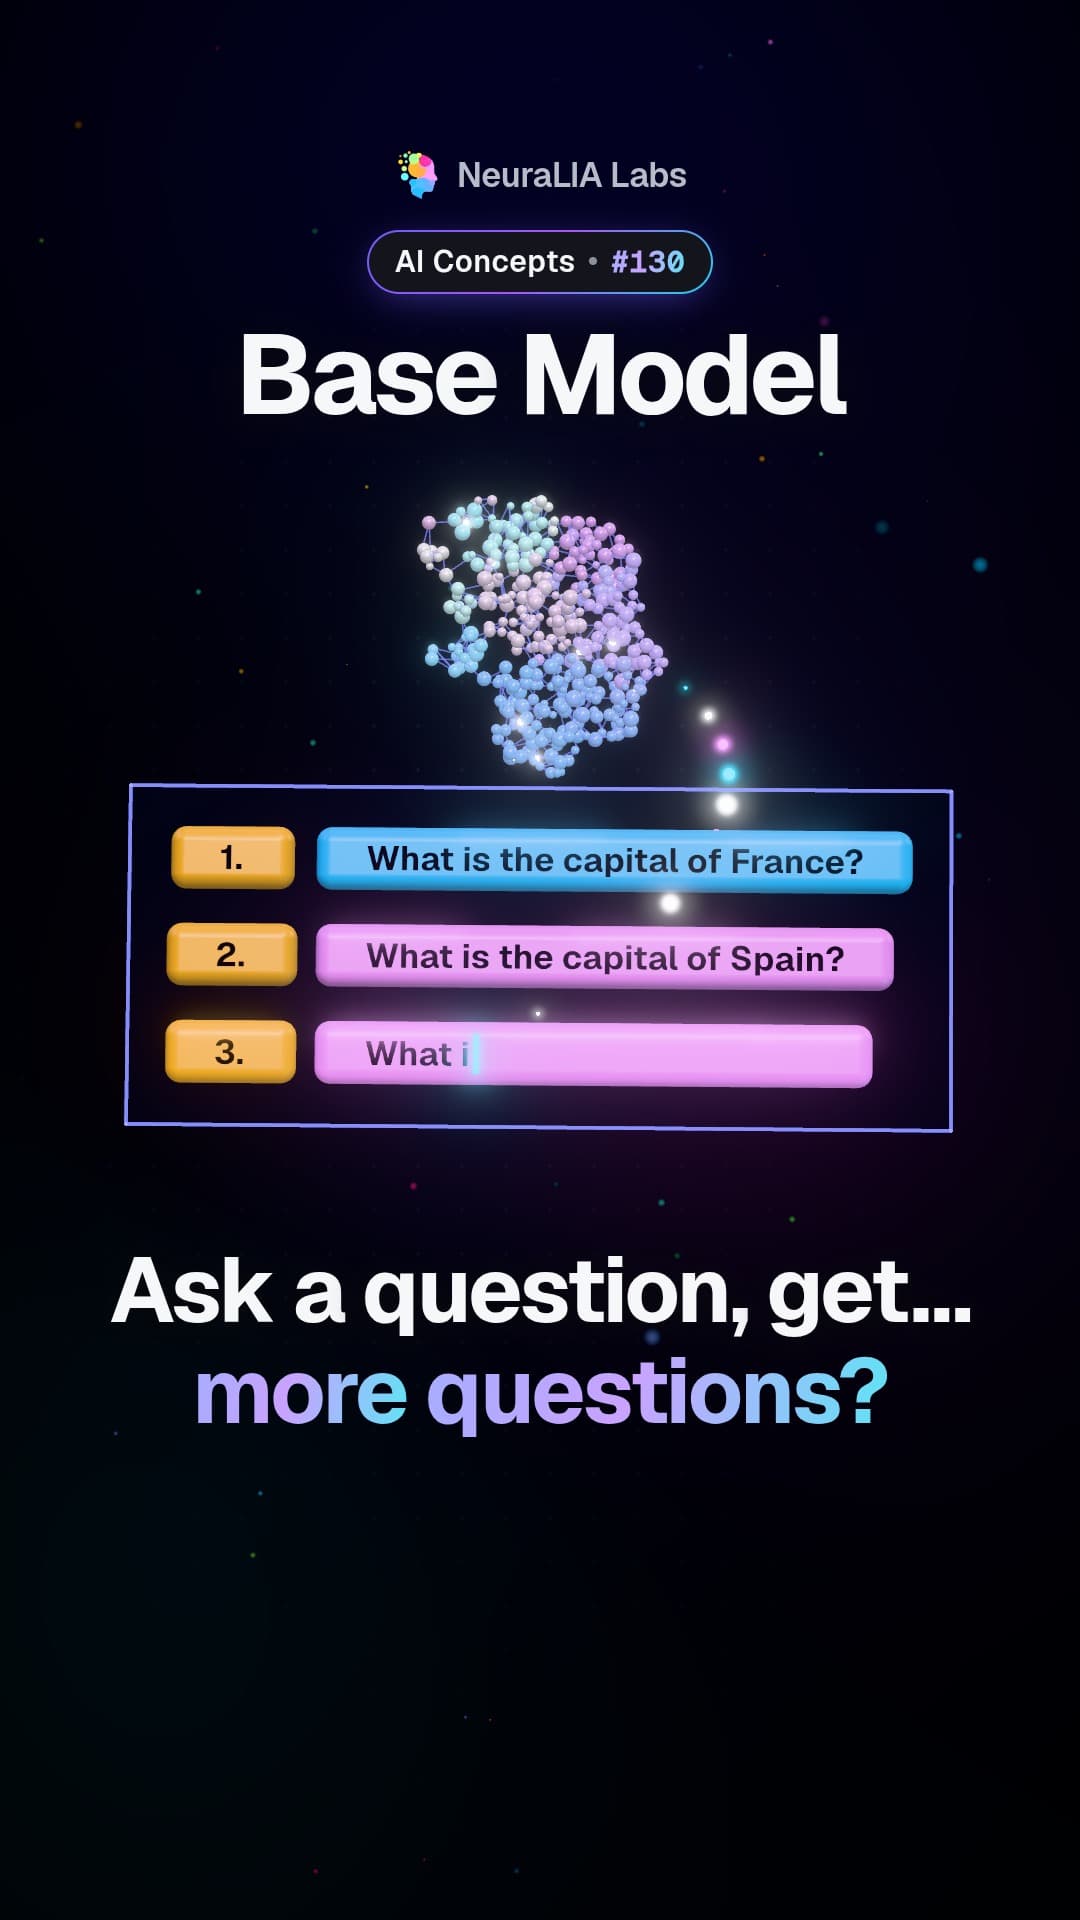 #130
Base model: the AI that continues your text instead of answering
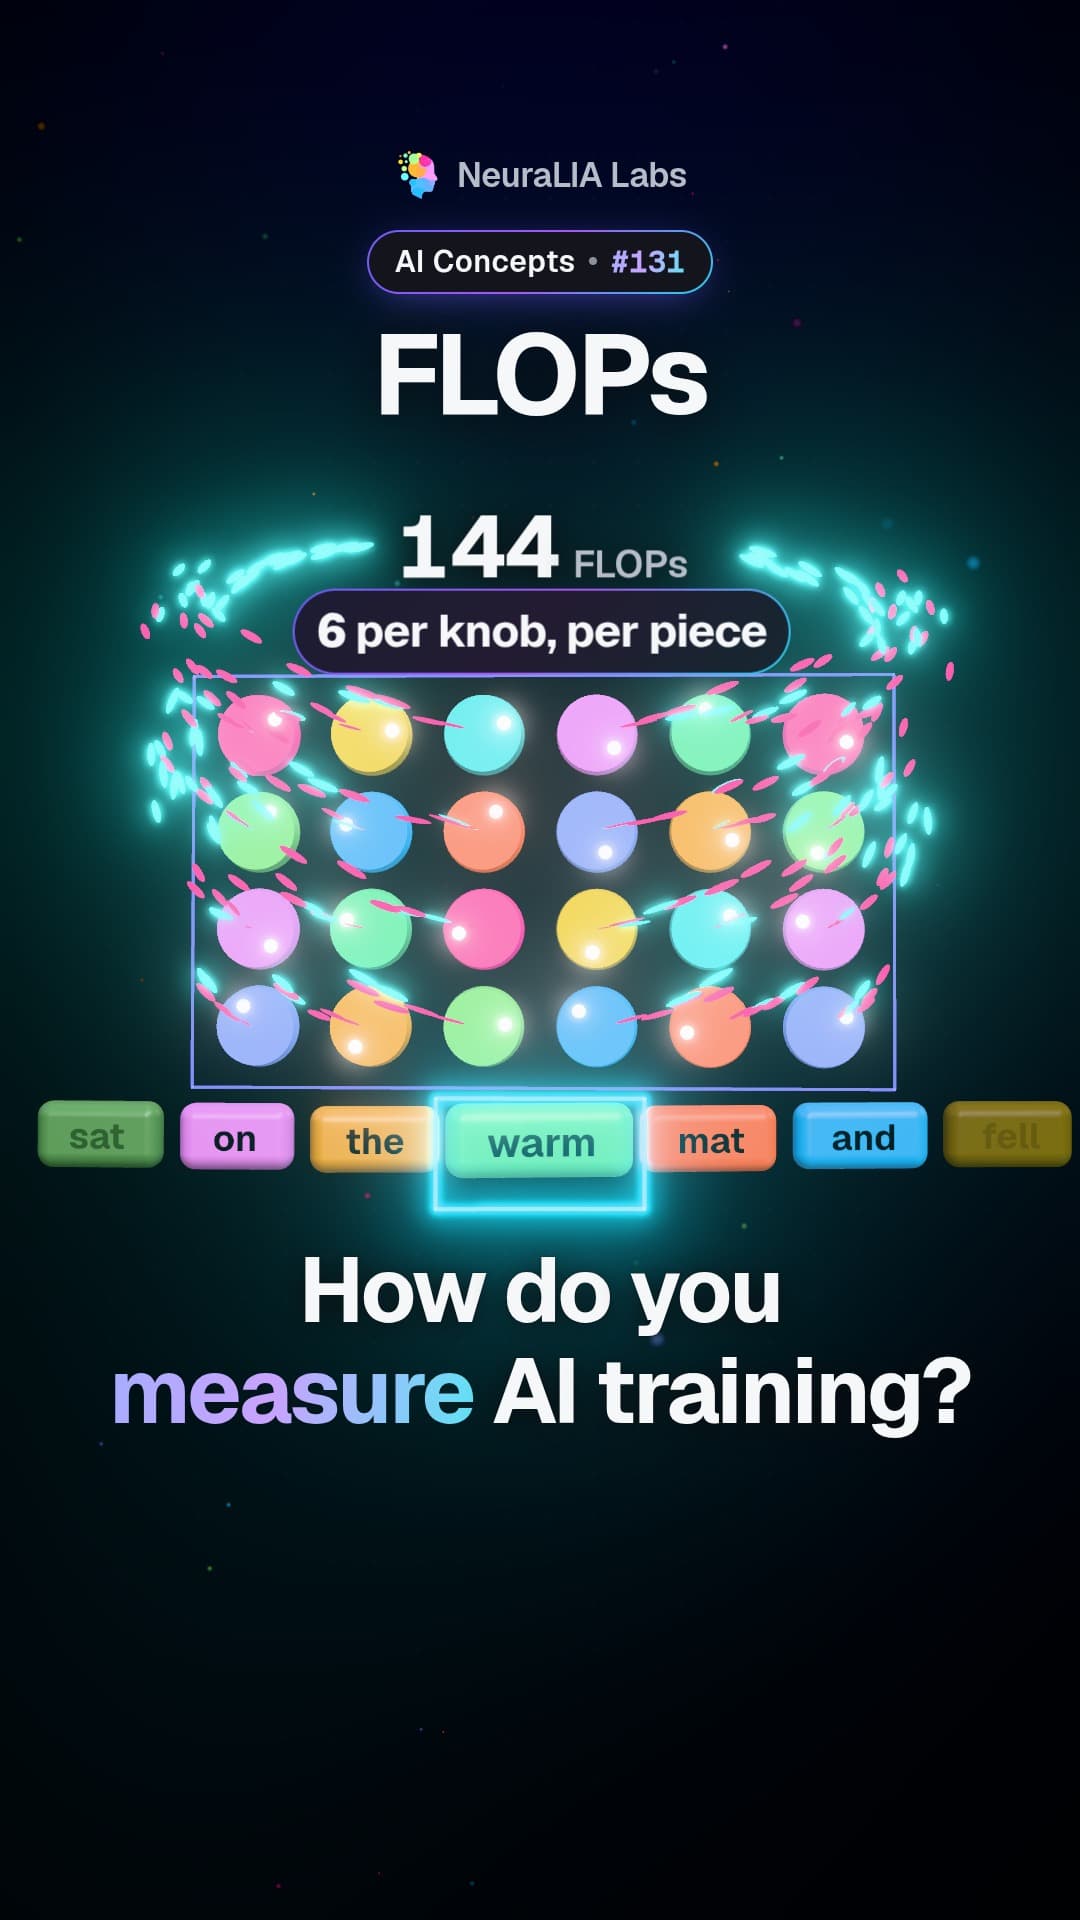 #131
FLOPs: the six-operation rule for sizing an AI training run
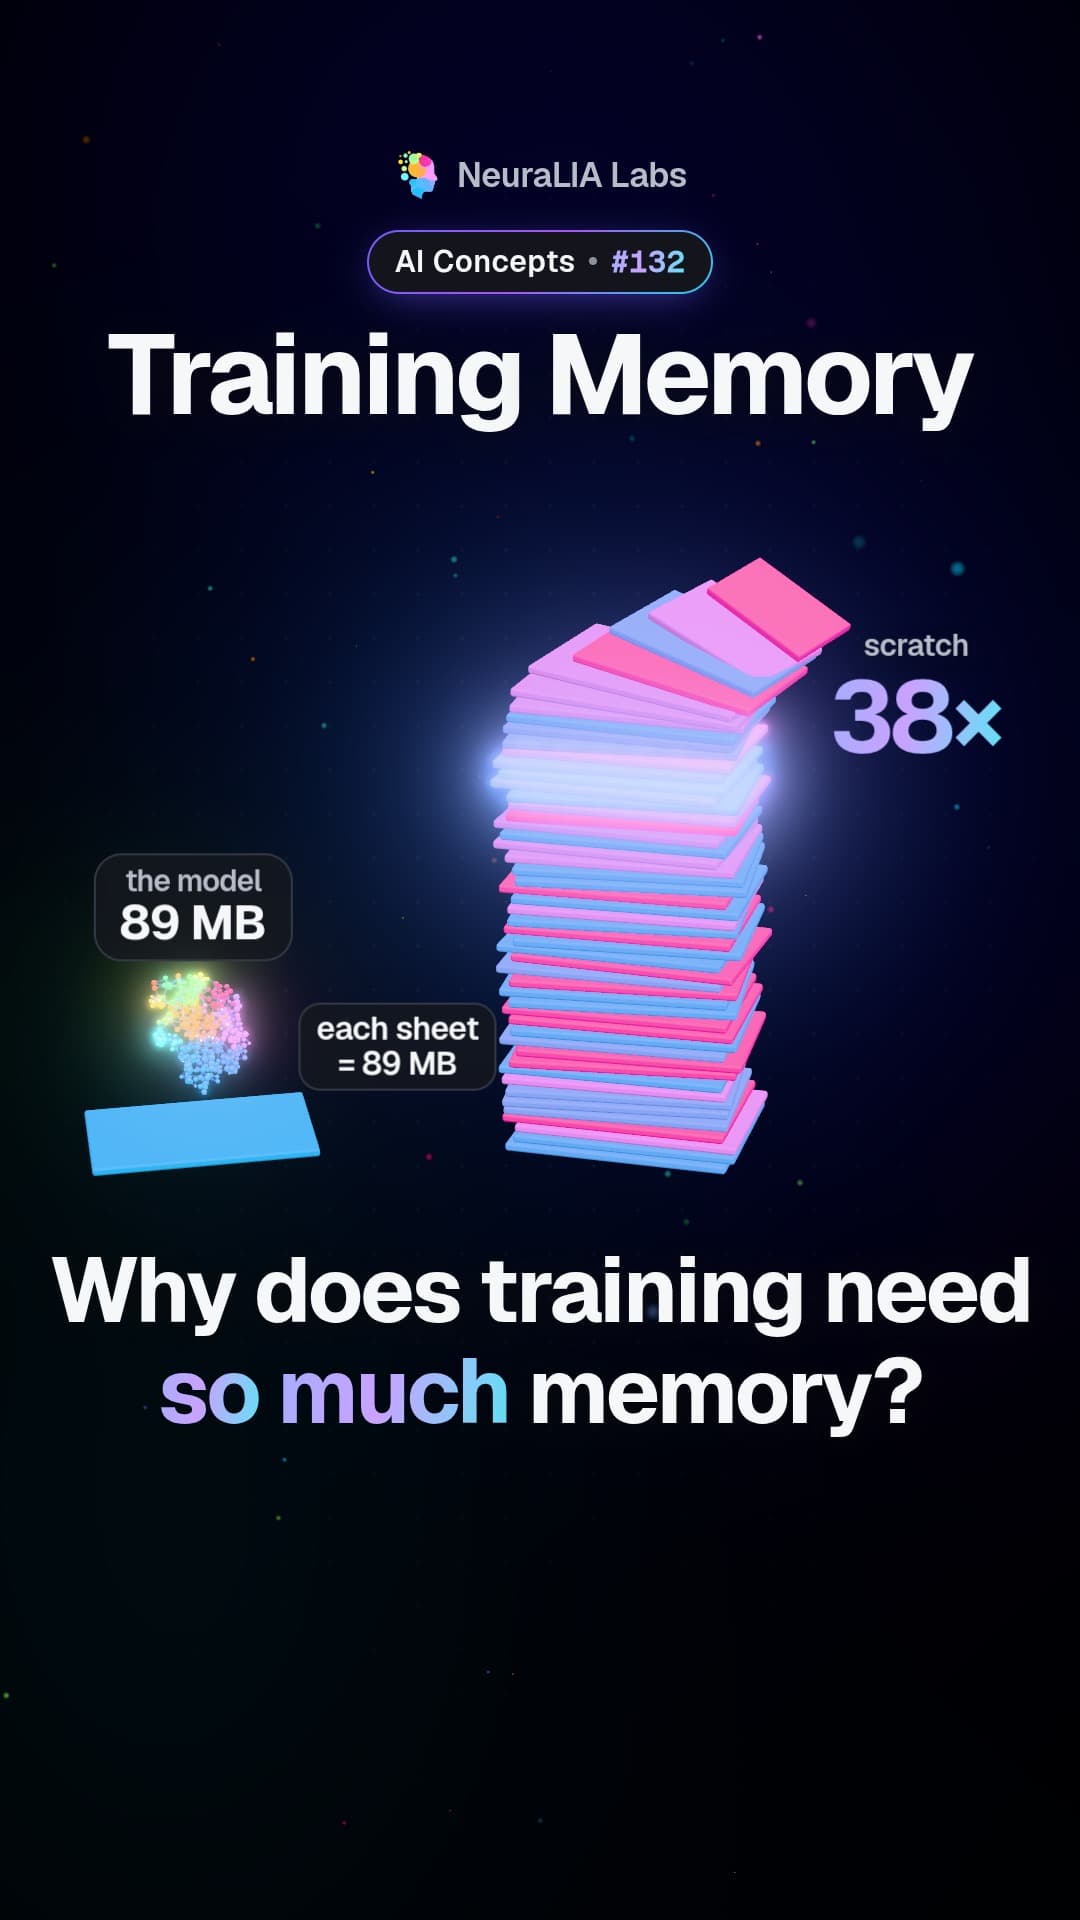 #132
Training memory: 16 bytes per setting, plus a mountain of scratch work
 #133
Mixed precision: faster AI training without losing the tiny updates
 #134
Loss scaling: how AI training saves corrections too small to count
무료 강좌 챕터 10의 내용을 바탕으로 AI 도움을 받아 작성한 글입니다.