
 #174
Tämä video ja sen teksti ovat englanniksi.
PagedAttention: the parking-lot trick behind busy AI servers
Reserving a big chunk of memory for every chat wastes most of it. PagedAttention stores an AI's notes in small blocks with a map, so a server fits more chats.
Tarkemmin
What PagedAttention is
While it writes, a language model keeps notes on every token of a conversation. A token is a word or a piece of a word. Those notes, called the KV cache, live in the memory of the server's graphics chips, and they stay there for as long as the conversation is running.
PagedAttention is a way of organising that memory: it cuts the notes into small pieces of equal size and keeps track of which pieces belong to which conversation.
What the video shows
The video calls it the parking-lot trick. The old way reserves a big chunk of memory for each chat. The new way stores the notes in small blocks wherever there is room, and keeps a map of where they went. The payoff it points to: less wasted memory, and more chats running at the same time.
The problem it solves
A busy AI server handles a constant stream of requests that start and finish at different moments. That creates two kinds of waste:
- Over-reserving. Nobody knows in advance how long a conversation will get. If the server sets aside room for the longest possible one every time, most of that reservation sits empty.
- Fragmentation. As conversations end, they leave gaps of different sizes scattered around memory. A new conversation that needs one big unbroken chunk may not fit, even when the free space adds up to more than enough.
An everyday example
Imagine a car park that blocks off an entire row for every family that drives in, just in case their relatives turn up later. Most rows end up half empty, and new families get turned away while plenty of spaces sit free. A smarter car park lets each car take any free space and keeps a list of where every family's cars are. Nothing is held back, and almost nothing is wasted.
How it works
The idea is borrowed from operating systems, the software that runs your computer, which organise their own memory in a similar way, a technique called paging.
- The notes are cut into blocks of a fixed size.
- Each conversation gets a block table: a list saying which blocks hold its notes, and in what order.
- The blocks can sit anywhere in memory, yet the model reads them as one continuous run. Physically scattered, logically in order.
- A conversation only takes a new block when it actually needs one.
There is a bonus. When several conversations begin with exactly the same text, for example the same opening instructions, they can all point to the same blocks for that shared beginning instead of each storing a copy.
Why it matters
Each conversation's notes take up memory for as long as it runs, so memory decides how many conversations fit on a server at once. Wasting less of it means serving more people on the same machine.
PagedAttention is the natural partner of continuous batching, where requests constantly join and leave. The serving engine vLLM, software that runs a model for many users at once, is built on it. The course puts the lesson in one line: a modern serving engine is, above all, a memory manager with an AI model attached.
Learn it step by step in Chapter 13 of our free course AI From Scratch: Making Inference Cheap: KV Cache, Batching and Quantization.
Myös palvelussa
Lisää tästä luvusta
- #174
 #175
Prefill vs decode: why a chatbot pauses first, then streams smoothly
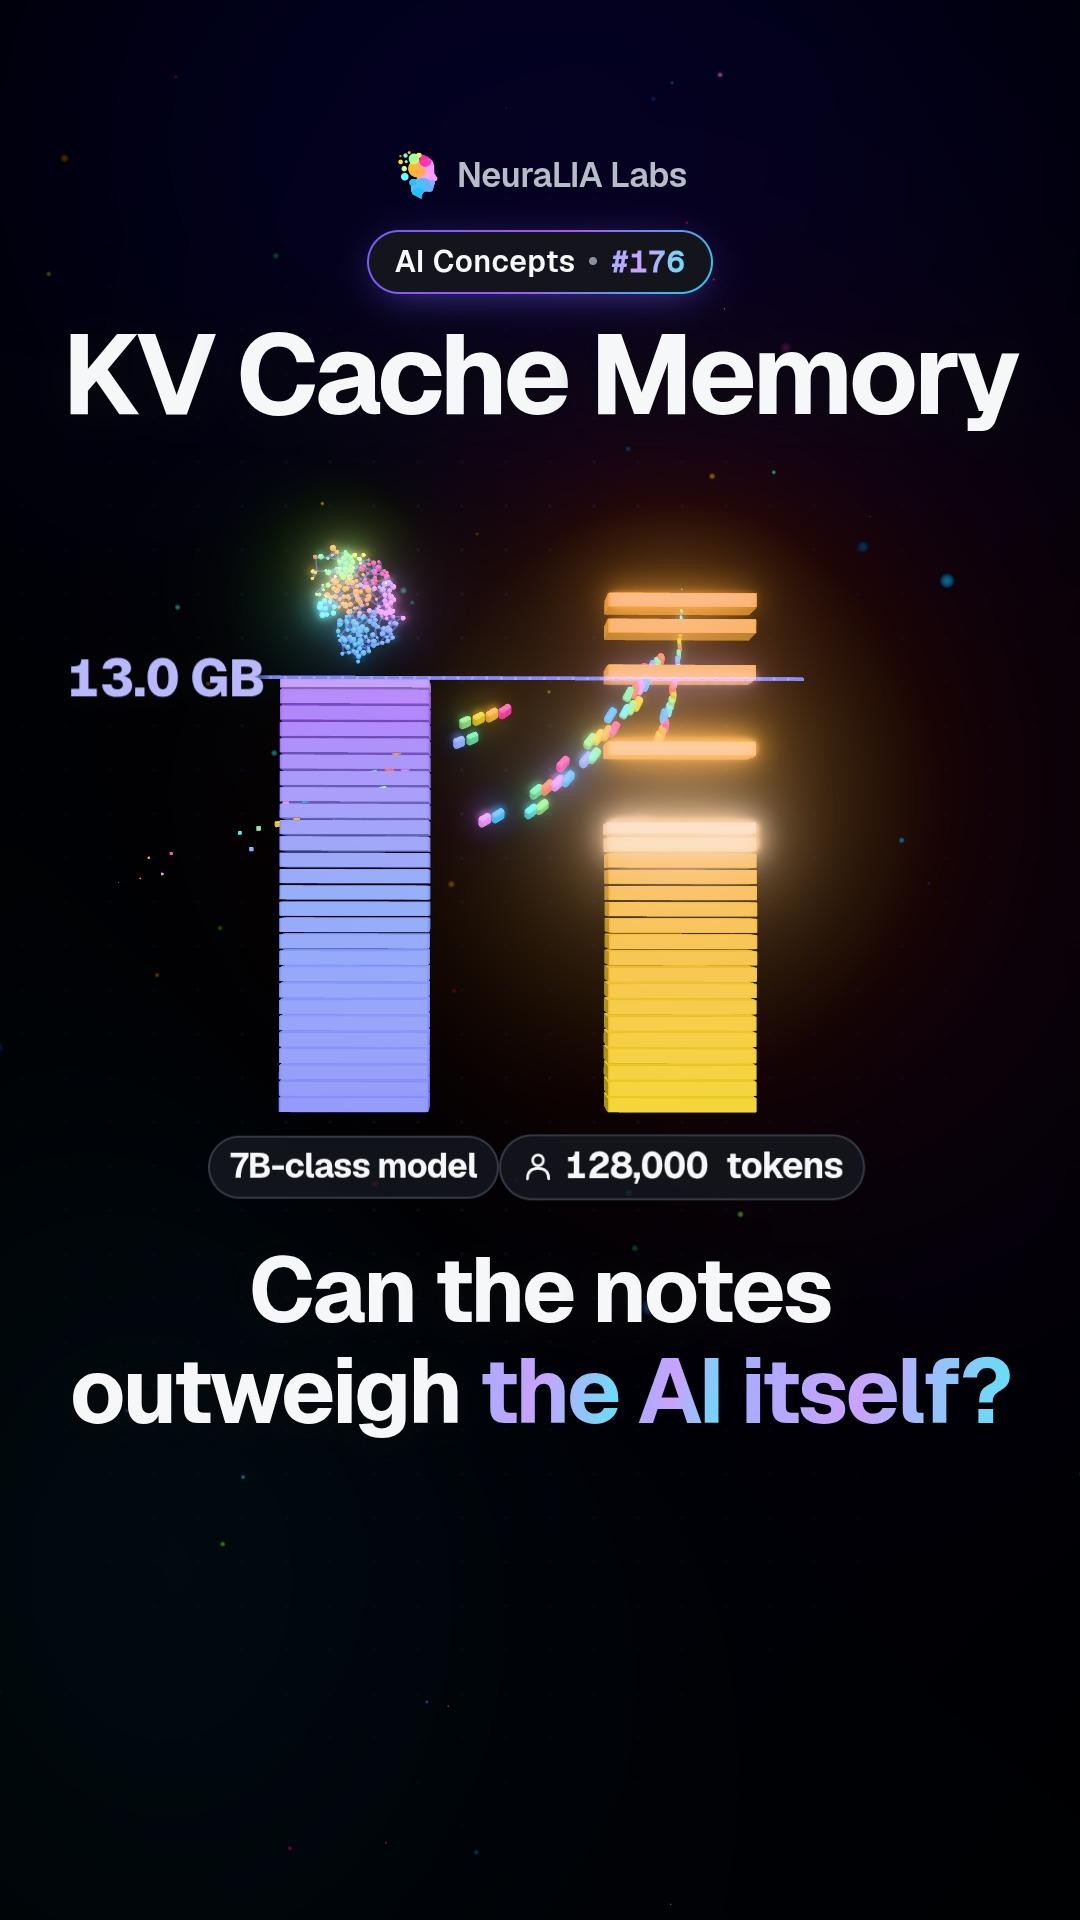 #176
KV cache memory: when a chatbot's notes outgrow the model itself
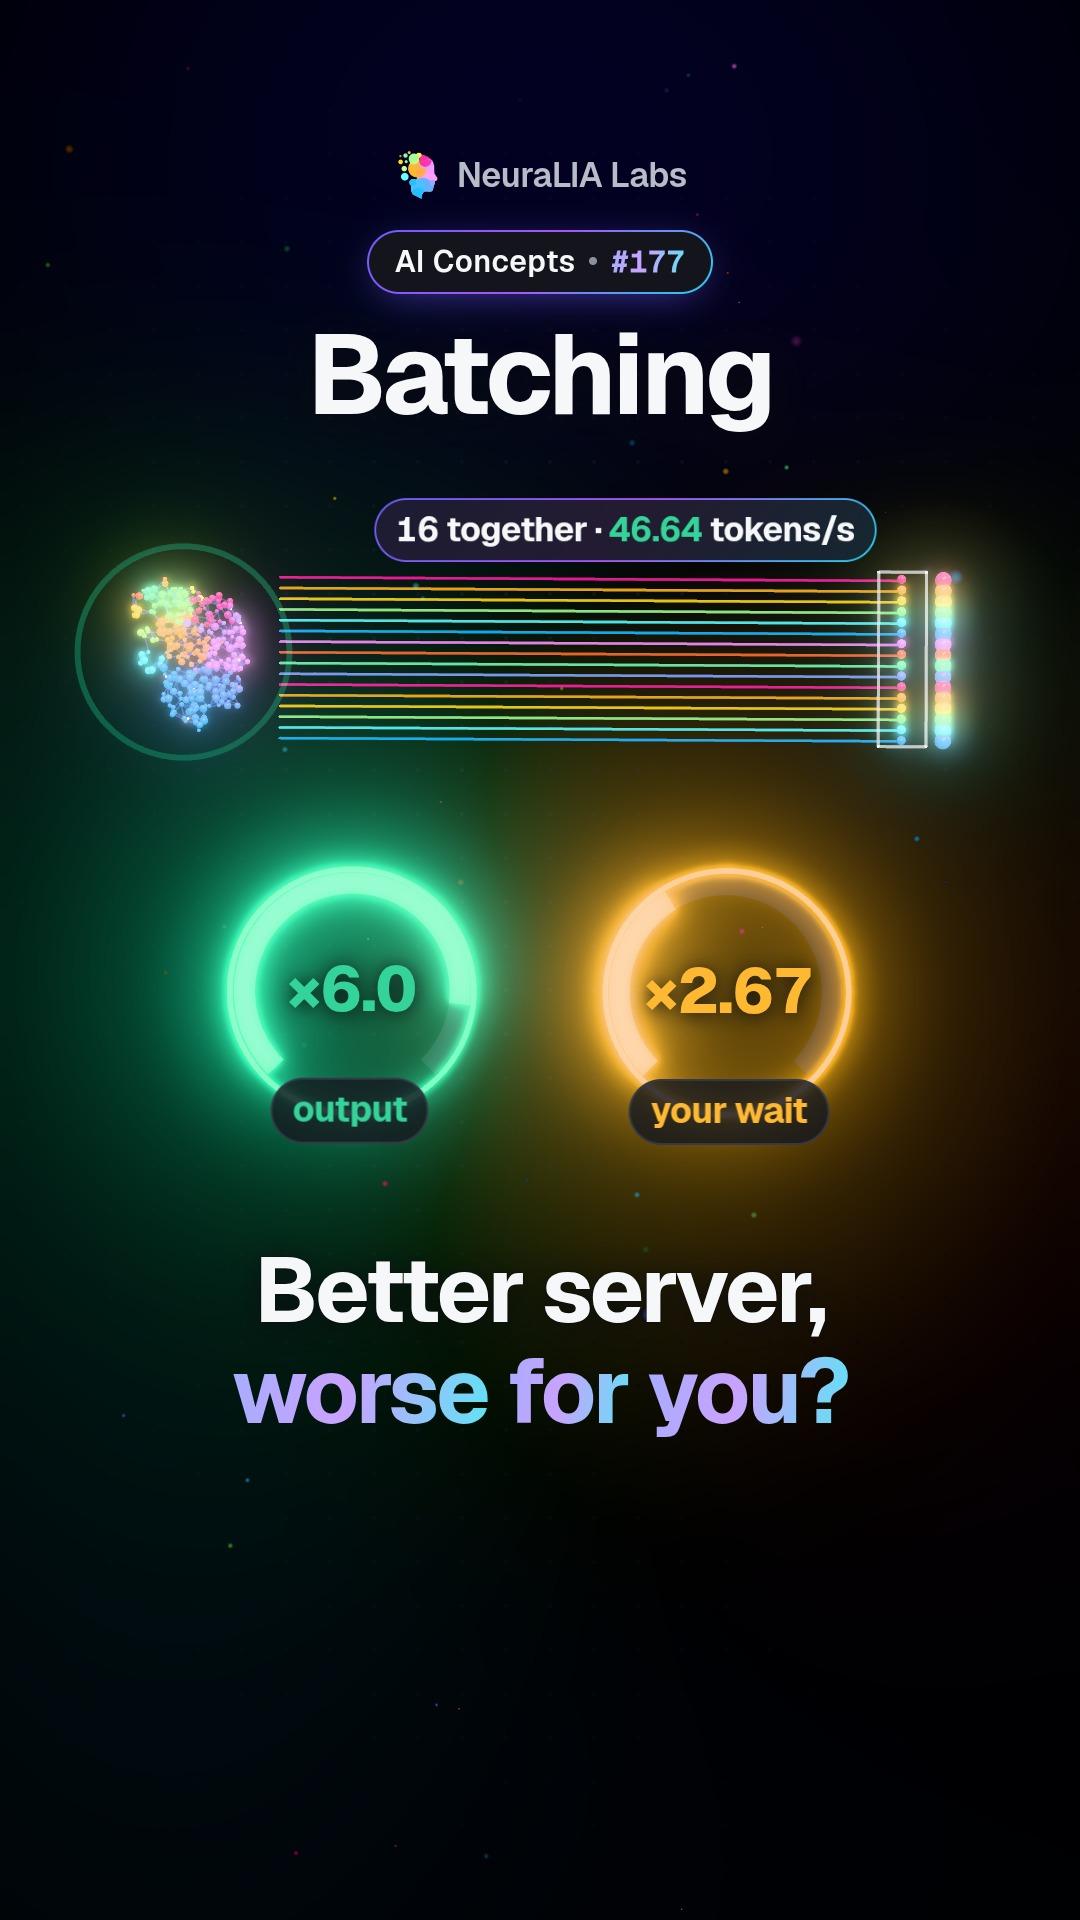 #177
Batching: more output per second, but a longer wait for each user
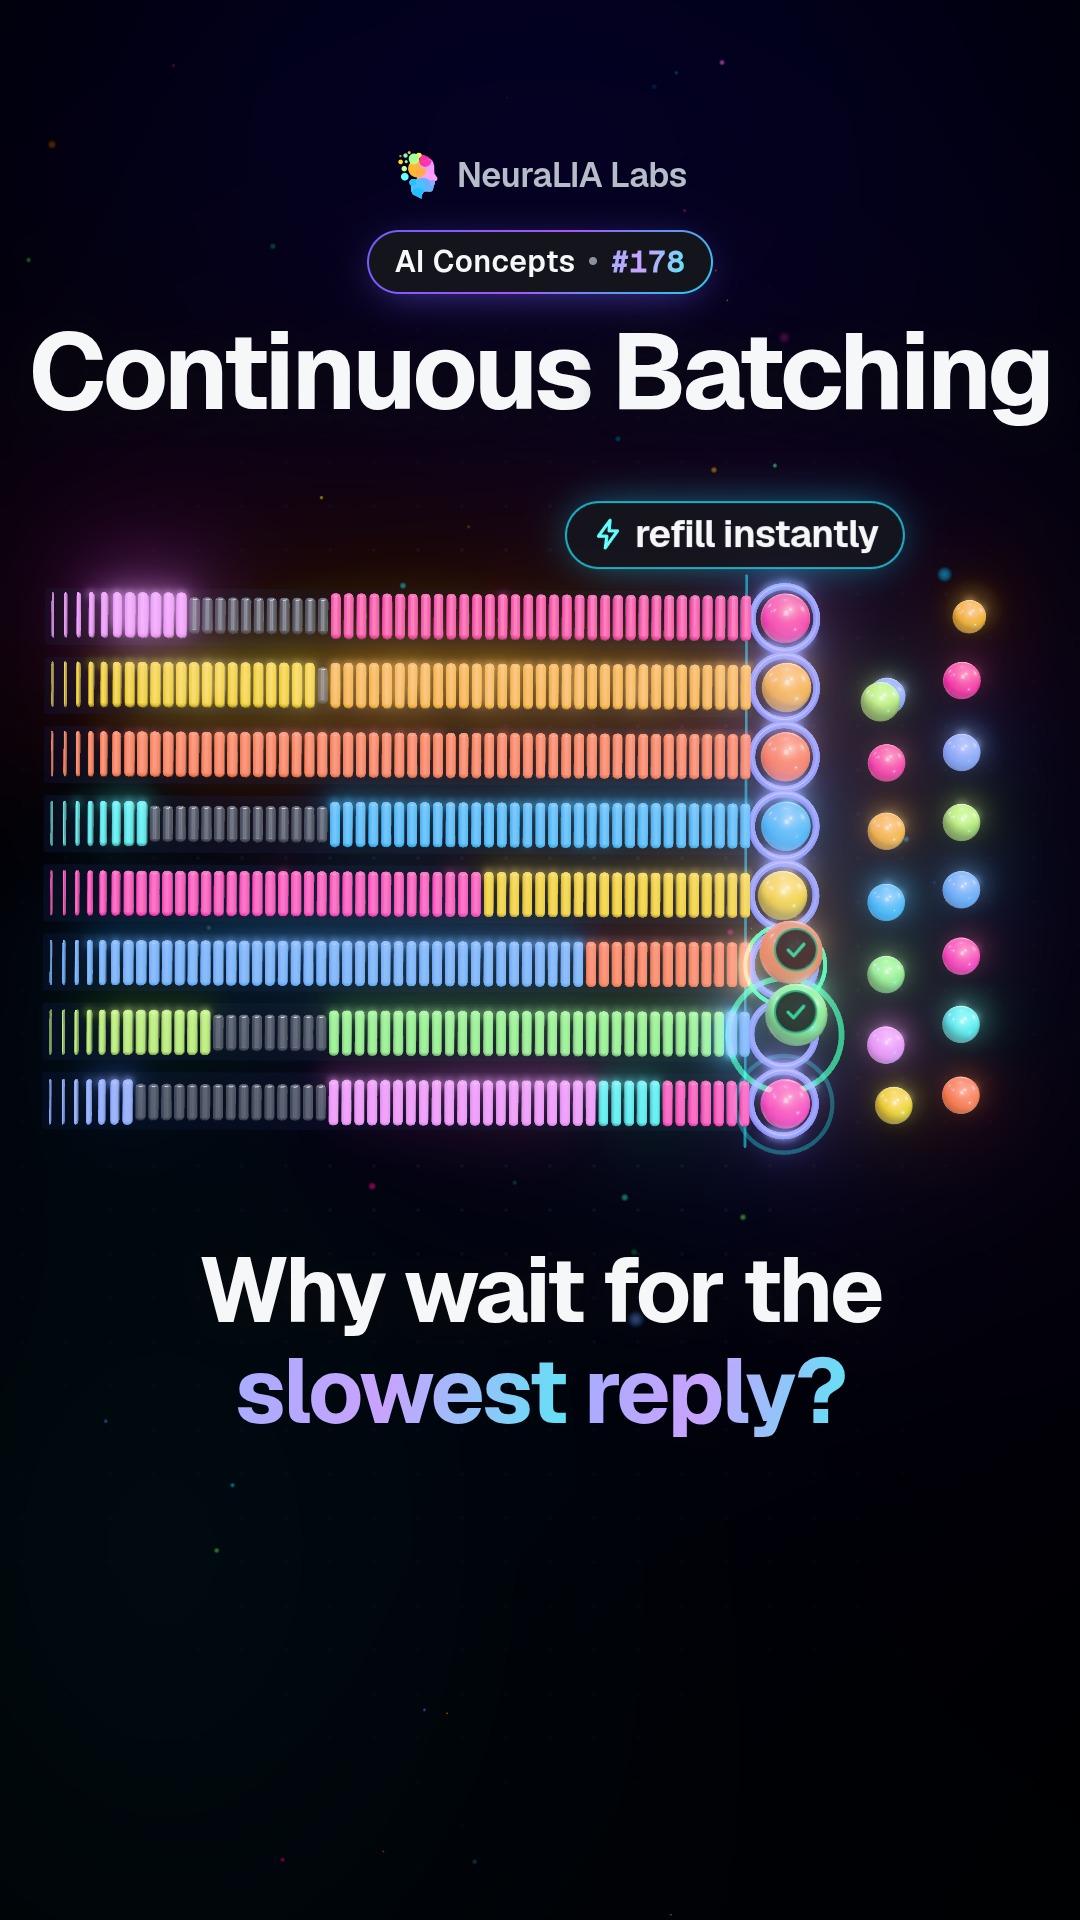 #178
Continuous batching: no more waiting for the slowest reply
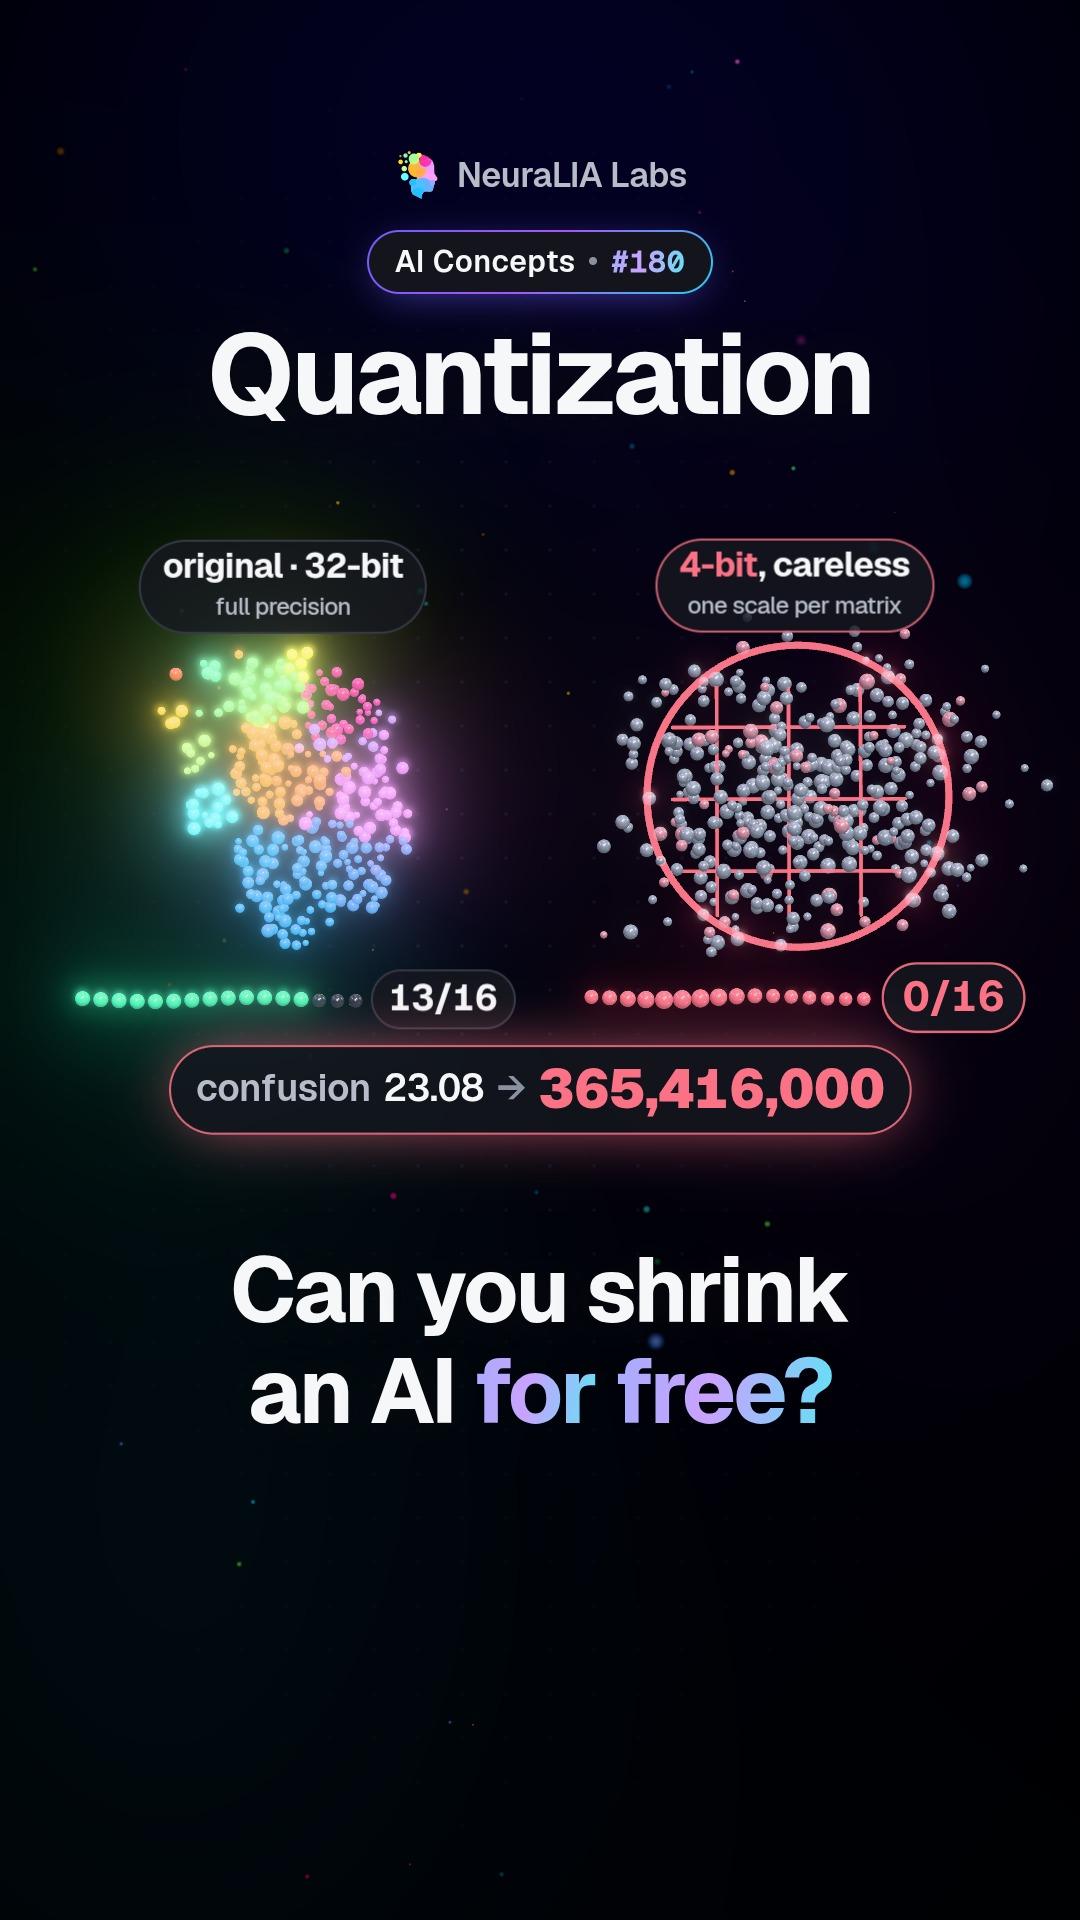 #180
Quantization: shrinking an AI by storing its numbers more roughly
Teksti on kirjoitettu AI-avusteisesti ilmaisen kurssimme luvun 13 pohjalta.