
 #174
Αυτό το βίντεο και το κείμενό του είναι στα Αγγλικά.
SmoothQuant: shift the hard-to-round numbers to where they fit
SmoothQuant shrinks an AI's extreme values and grows their partner numbers by the same amount: same result, easier rounding. Learn how the trick works.
Αναλυτικά
What SmoothQuant is
SmoothQuant is a trick for rounding a language model to 8 bits (just 256 possible values per number) when some of its numbers are too extreme to round well. A model works with two kinds of numbers. Weights are the fixed settings it learned in training, and they are known in advance. Activations are the numbers it computes on the fly while reading your text, and a few of their positions carry giant values (this series calls them outlier features). Activations handle rounding badly; weights handle it much better. SmoothQuant moves the difficulty from the first kind to the second, without changing the model's answer.
What the video shows
The video compares it to balancing two backpacks. Some values inside an AI are too extreme to round well. SmoothQuant shrinks them and grows their partner numbers by the same factor. The result of the calculation stays exactly the same, but now both sides are easy to round.
An everyday example
Imagine a garden plot that is 1,000 metres long and 1 metre wide. Its area is 1,000 square metres. Divide the length by 10 and multiply the width by 10, and you get a plot 100 metres by 10 metres. The area is identical, but neither side is absurd any more. Nothing about the answer changed; only how the size is shared between the two numbers.
How it works
In each layer, the model multiplies activations by weights, and every activation position has a matching column of weights it is multiplied with. SmoothQuant works position by position:
- Pick a factor for each activation position, large where the values are giant and modest where they are calm.
- Divide that position's activations by the factor, so the giant values shrink.
- Multiply the matching column of weights by the same factor.
- The product is unchanged, because dividing by a number and then multiplying by it cancels out.
The weights only need adjusting once, ahead of time, because they never change after training. After that, both the activations and the weights can be rounded to 8 bits.
Why the activations need help
The course shows how bad the problem is. In a small model, one activation position reaches about 1,580 while a typical one stays under 1.6. Rounded to 8 bits with one shared scale, only 14 of the 256 possible values get used, and ordinary positions collapse to a single value. Weights are far more forgiving: in the same course, rounding them to 8 bits with a scale for each row leaves only about 1% error.
An honest note
The course explains SmoothQuant but does not benchmark it. Its evidence is the outlier measurement above, which shows why activations need help in the first place. The other well-known answer to the same problem, LLM.int8(), sets the giant values aside instead of moving them.
Why it matters
SmoothQuant is a neat example of a general engineering idea: when one part of a system cannot absorb a problem, move the problem to a part that can, while keeping the final answer the same. Here, the fragile side is the stream of numbers computed for every input, and the sturdy side is the set of weights that can be prepared in advance.
Learn it step by step in Chapter 13 of our free course AI From Scratch: Making Inference Cheap: KV Cache, Batching and Quantization.
Επίσης στο
Περισσότερα από αυτό το κεφάλαιο
- #174
 #175
Prefill vs decode: why a chatbot pauses first, then streams smoothly
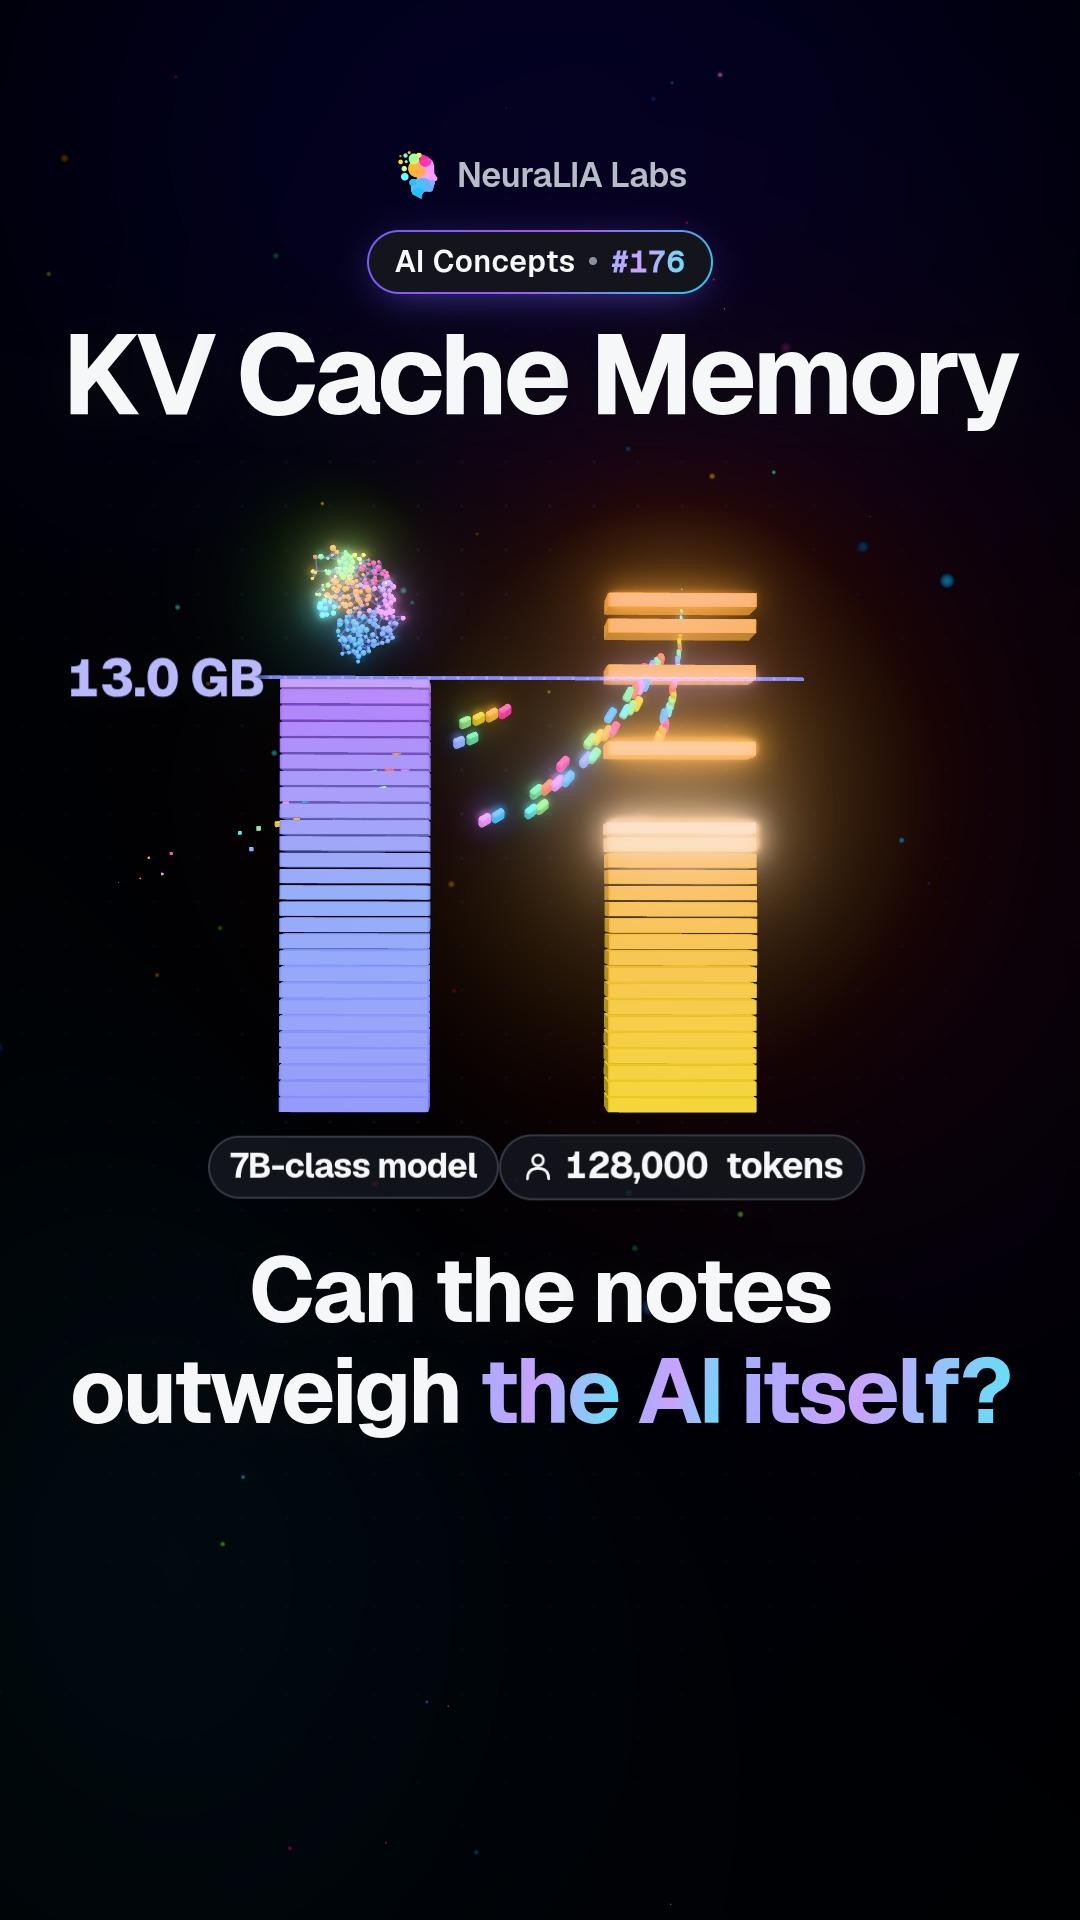 #176
KV cache memory: when a chatbot's notes outgrow the model itself
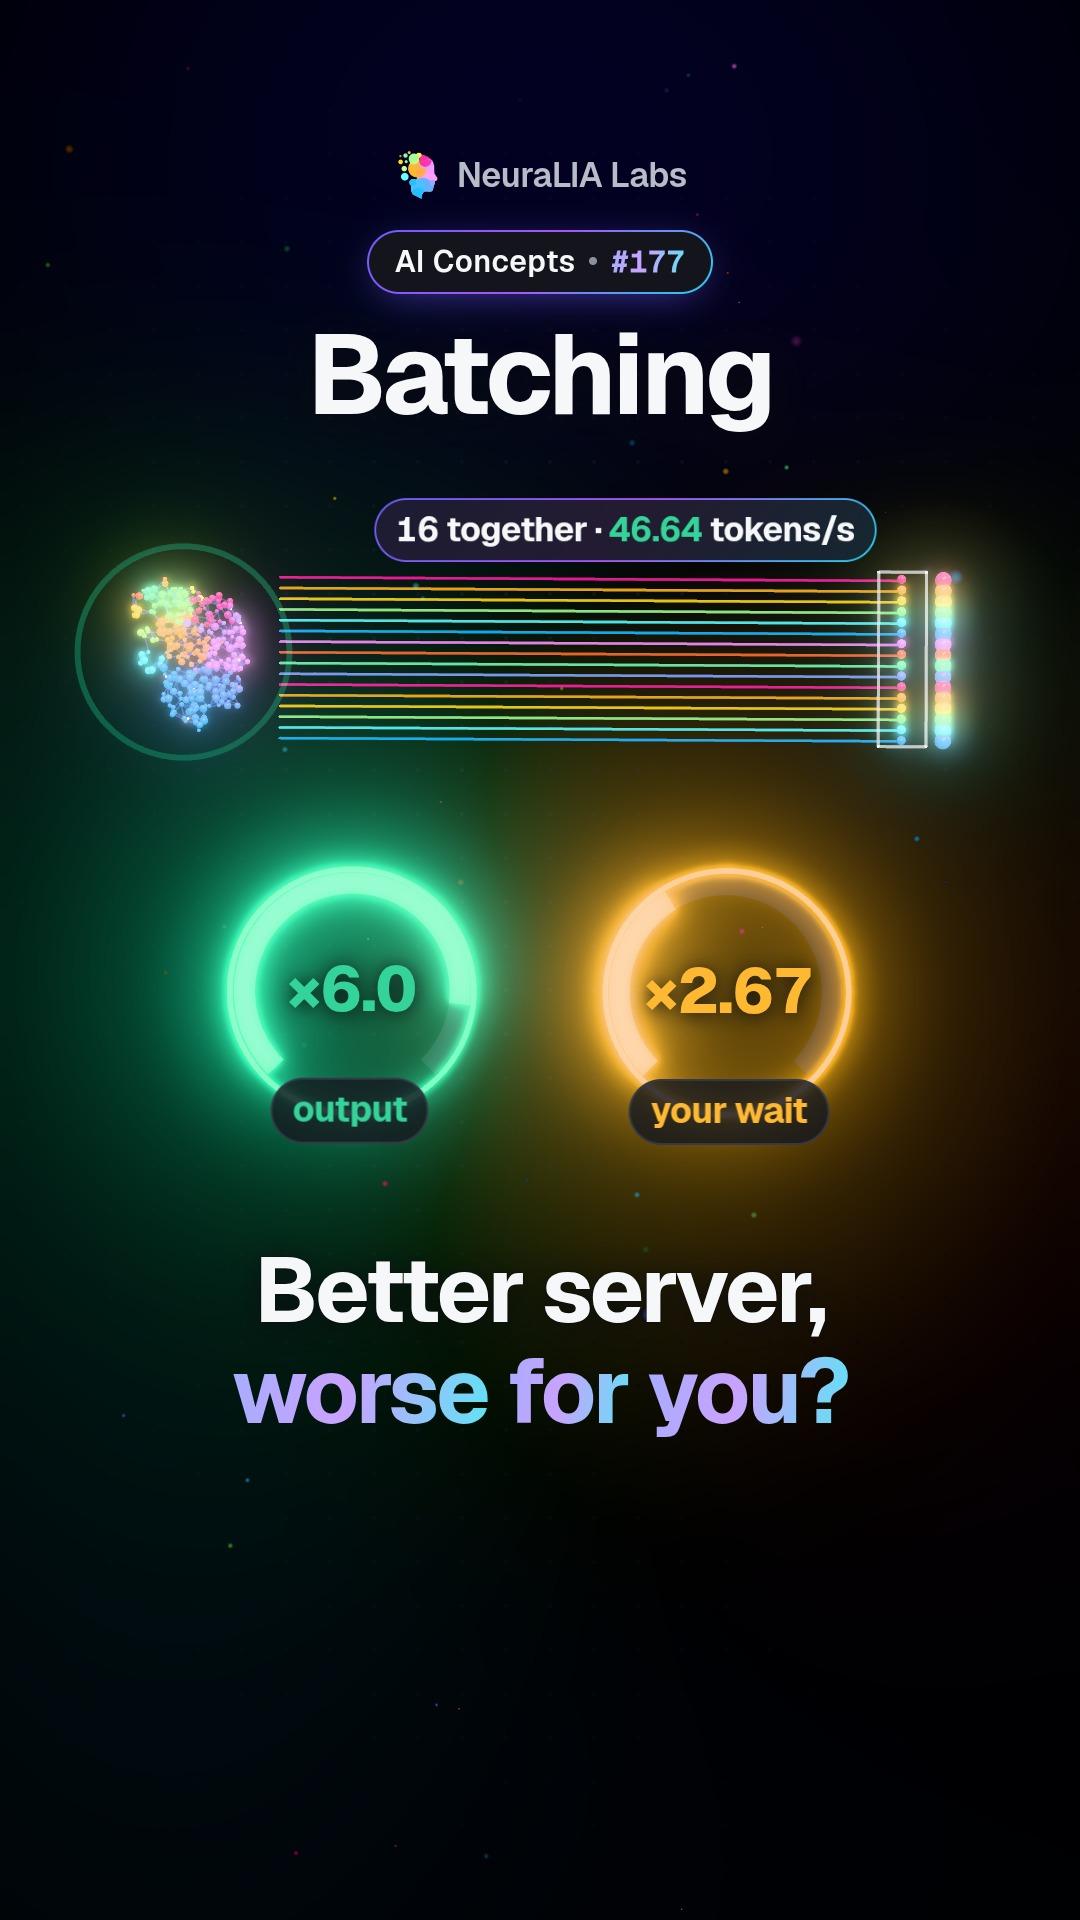 #177
Batching: more output per second, but a longer wait for each user
 #178
Continuous batching: no more waiting for the slowest reply
 #179
PagedAttention: the parking-lot trick behind busy AI servers
Το κείμενο γράφτηκε με τη βοήθεια AI από το κεφάλαιο 13 του δωρεάν μαθήματός μας.