
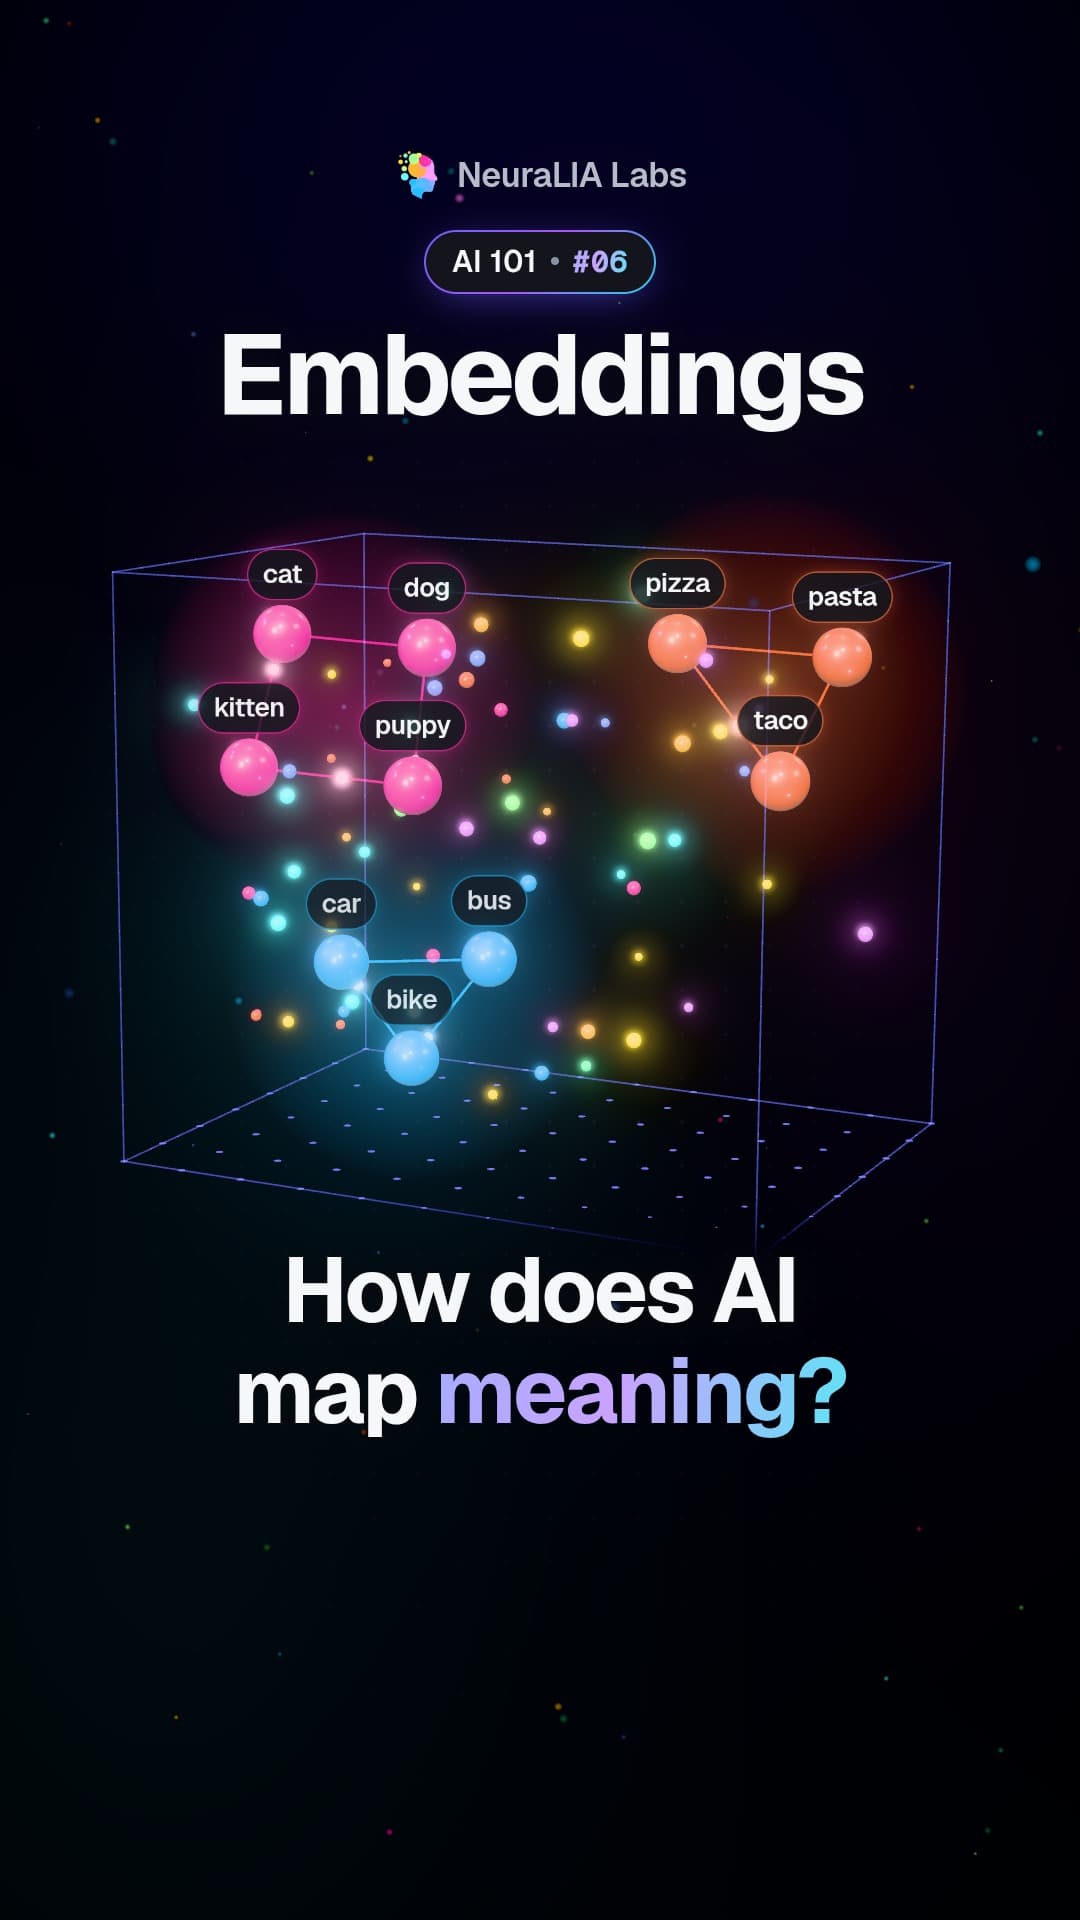
 #06
此视频及其文本为英文。
Neural language model: why seeing more letters beat a bigger brain
A network 11 times bigger than a counting table guessed no better. Letting it see three letters did. Here is what a neural language model adds, and why.
详细说明
What a neural language model is
A language model is a system that guesses what comes next: the next letter, or in bigger systems the next word piece. A neural language model does that guessing with a neural network, a stack of adjustable number grids that learns from examples, instead of with a plain table of counts.
The design in the course follows a 2003 architecture by the researcher Bengio, the direct ancestor of the bigger models that come later. It works in four steps:
- Take the last few letters of the text.
- Look each one up in an embedding table: a list with one row of numbers per letter (10 numbers each here).
- Join those rows into one longer list and pass it through a hidden layer, a middle stage of the network (200 units wide in the course).
- Produce one score for every possible next letter, then turn the scores into probabilities.
What the video shows
A bigger network that sees only one letter does no better than simple counting. Let it see three letters and its confusion drops by 29%, because letters that behave alike can share what they learn.
An everyday example
Imagine a word game where you must guess the next letter, but you may only look at the one before it. You see "e". Many letters could follow. A genius does no better than someone keeping a simple tally of which letters usually come after "e", because the clue itself is too thin. Now you may look at "bre". The options shrink fast. That is the heart of the video: the improvement came from more clues, not from a bigger brain.
How it works: context, not capacity
The course trains the same code several times and changes only how many previous letters the model can see. It scores each version with perplexity, a measure of how confused the model is about the next letter (lower is better; roughly, how many letters it is still torn between).
| Model | Adjustable numbers | Perplexity | |---|---|---| | Counting, 1 letter | 729 | 11.64 | | Network, 1 letter | 7,897 | 11.68 | | Network, 3 letters | 11,897 | 8.29 | | Network, 8 letters | 21,897 | 7.77 |
The second row is the surprise. About eleven times as many adjustable numbers as the counting table, and no gain at all. One letter of context holds only so much information, and no amount of extra network can squeeze out more.
With three letters, the picture changes. A counting table would need 27 × 27 × 27 = 19,683 rows, most of them empty or seen just once, and it would have to learn each row separately. The network shares instead. If "a", "e" and "i" end up with similar rows in the embedding table, then what it learns after "bra" also helps after "bre", even if it has never seen "bre". That sharing is the real value of the embedding table.
Why it matters
The invented names get better too. The counting model's longest sample ran to 19 letters; the network's longest was 13, and some, like "nellara" or "kael", could pass for real names.
The lesson carries into every later model: a model can only use information it can see, so adding size without adding context bought nothing here. The course adds one practical note. The last layer, which scores every possible next word piece, is the expensive part of any language model, because a real vocabulary has around 100,000 entries.
Learn it step by step in Chapter 8 of our free course AI From Scratch: Next-Token Prediction: Embeddings, and What Perplexity Means.
也可在
本章更多内容
- #06
 #095
Self-supervised learning: how text becomes its own answer key
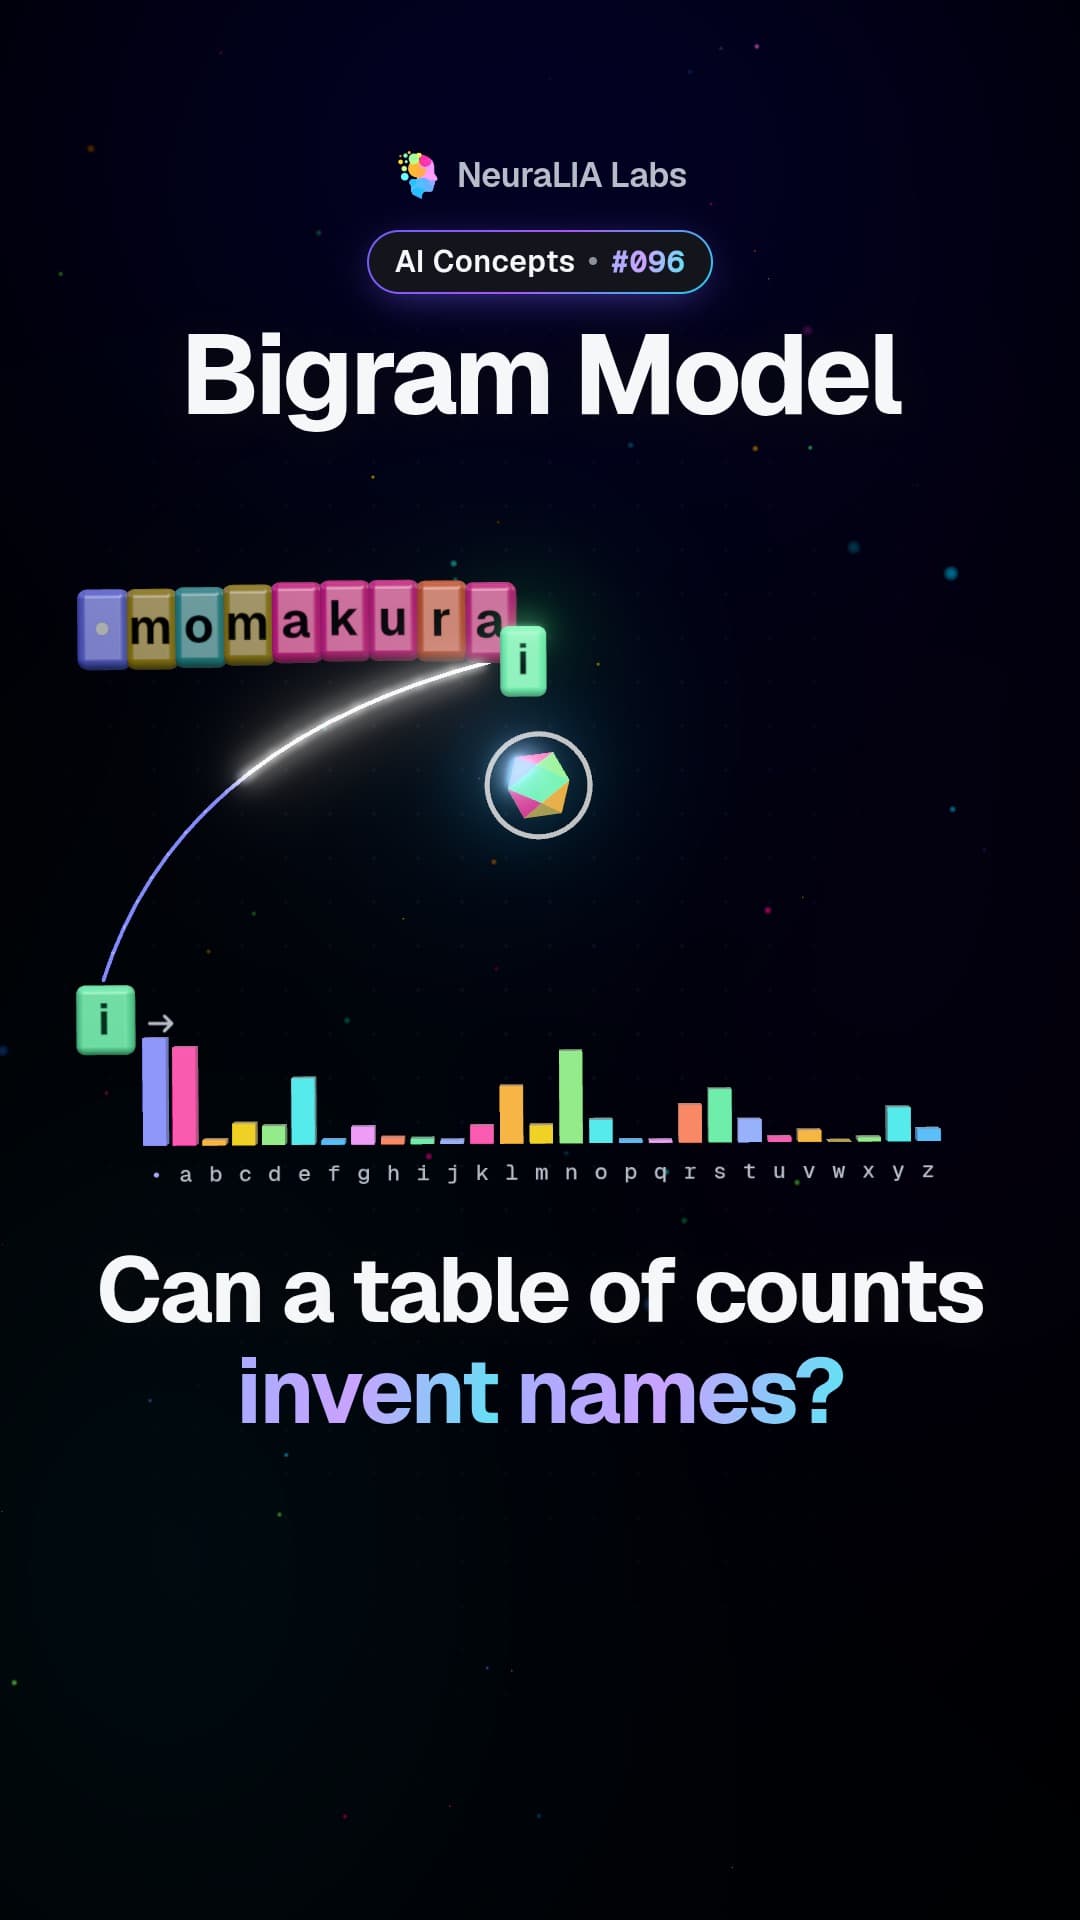 #096
Bigram model: an AI name-maker built from a table of letter pairs
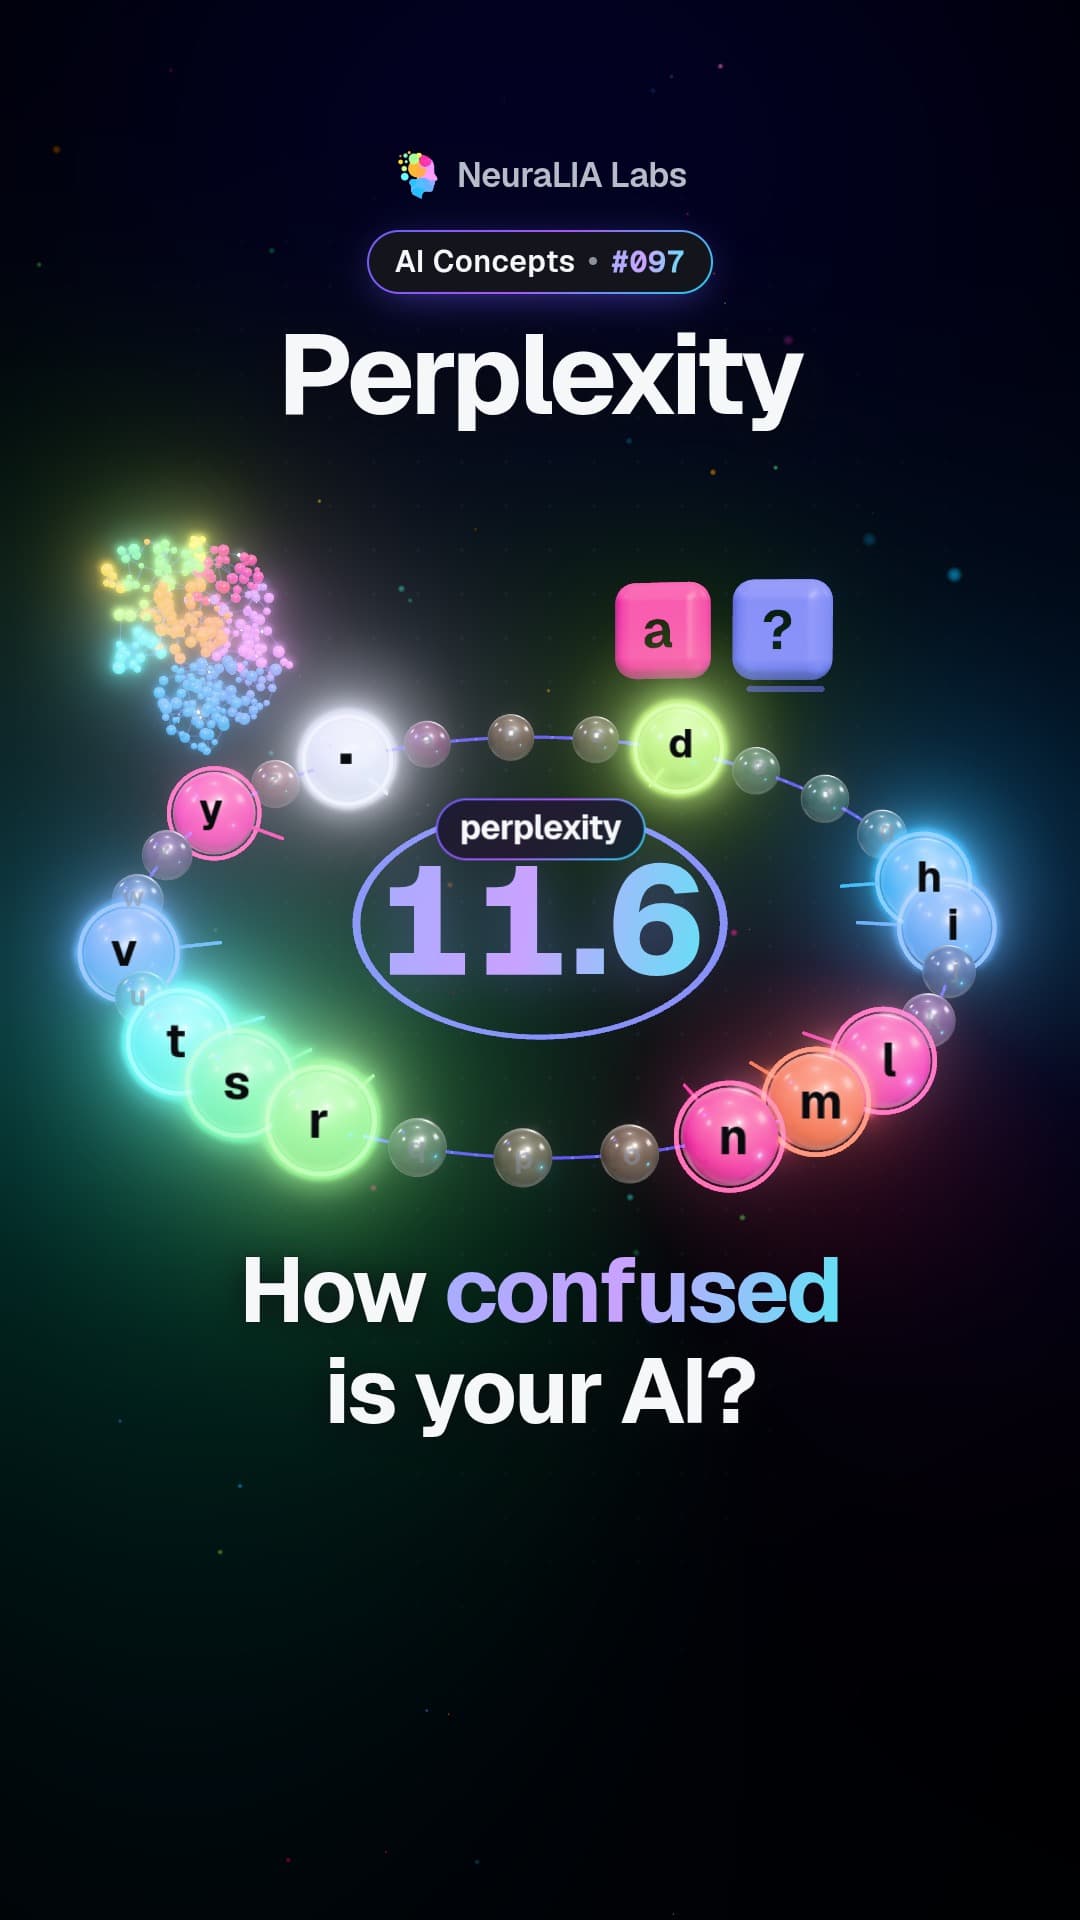 #097
Perplexity: how many options an AI is really torn between
 #098
Smoothing: why an AI must never treat the unseen as impossible
 #099
Bits per character: the fair way to compare language models
文案由 AI 辅助撰写,基于我们免费课程第 8 章。