
 #174
此视频及其文本为英文。
LLM.int8(): round most numbers, keep the giant few precise
A few giant values inside a language model ruin simple 8-bit rounding. LLM.int8() handles them apart and rounds the rest. Here is how, and what it buys.
详细说明
What LLM.int8() is
LLM.int8() is a way to run a large language model with 8-bit numbers without letting a few giant values spoil the rounding. 8-bit integers are whole numbers with only 256 possible values, which makes them compact. The catch is that inside these models a handful of positions carry values about a thousand times larger than the rest; they are known as outlier features. LLM.int8() deals with them separately. Those few are computed with 16-bit precision, everything else with 8-bit integers, and the two results are added together.
What the video shows
The video frames it as moving day: the piano goes separately. A few giant values inside an AI ruin simple rounding, so this method keeps those few precise and rounds the rest. In the course's test, setting aside just four of them cut the rounding error almost fourfold.
An everyday example
Imagine packing for a move under one strange rule: every box must be the same size, and it must be big enough for the largest thing you own. If that is a piano, every box is piano-sized, and your socks rattle around in crates. The sensible plan is the obvious one. Standard boxes for the thousands of ordinary things, and a separate crew for the piano.
How it works
A language model spends most of its effort on one kind of calculation: each layer takes the list of numbers for every word piece and combines it with its own table of learned weights (the technical name is matrix multiplication). That calculation is really a long sum of smaller pieces, one per position in the list. And a sum can be split. You can total the ordinary pieces, total the special pieces, and add the two totals at the end. The answer is the same as doing it all at once.
LLM.int8() uses exactly that:
- Find the few positions whose values are extreme.
- Compute those in 16 bits, which has room for big values.
- Compute all the others in 8 bits, with a scale that now fits ordinary values instead of the giants.
- Add the two results.
What the course measured
The course captures the activations (the numbers flowing between layers while the model reads a prompt) of a small model and rounds them to 8 bits with one shared scale. Only 14 of the 256 possible values get used, because one position near 1,580 sets the step size for everything.
Then it keeps just 4 extreme positions out of the rounding. The scale becomes 22 times finer, 57 values get used instead of 14, and the rounding error drops by a factor of almost four. Keeping 16 positions out shrinks the error further still. The course does not rebuild the full method; this measurement is the evidence for its central idea.
Why it matters
The research paper behind LLM.int8() is also where the finding comes from that these outlier features show up systematically as models grow. So the problem is not a quirk of one model; it is something anyone rounding a large model has to plan for. LLM.int8() plans for it in a very direct way: do not force the giants into the same boxes as everything else.
It also shows a general habit worth copying. When a few extreme cases break a simple rule, handling those few apart can work better than stretching the rule to fit them.
Learn it step by step in Chapter 13 of our free course AI From Scratch: Making Inference Cheap: KV Cache, Batching and Quantization.
也可在
本章更多内容
- #174
 #175
Prefill vs decode: why a chatbot pauses first, then streams smoothly
 #176
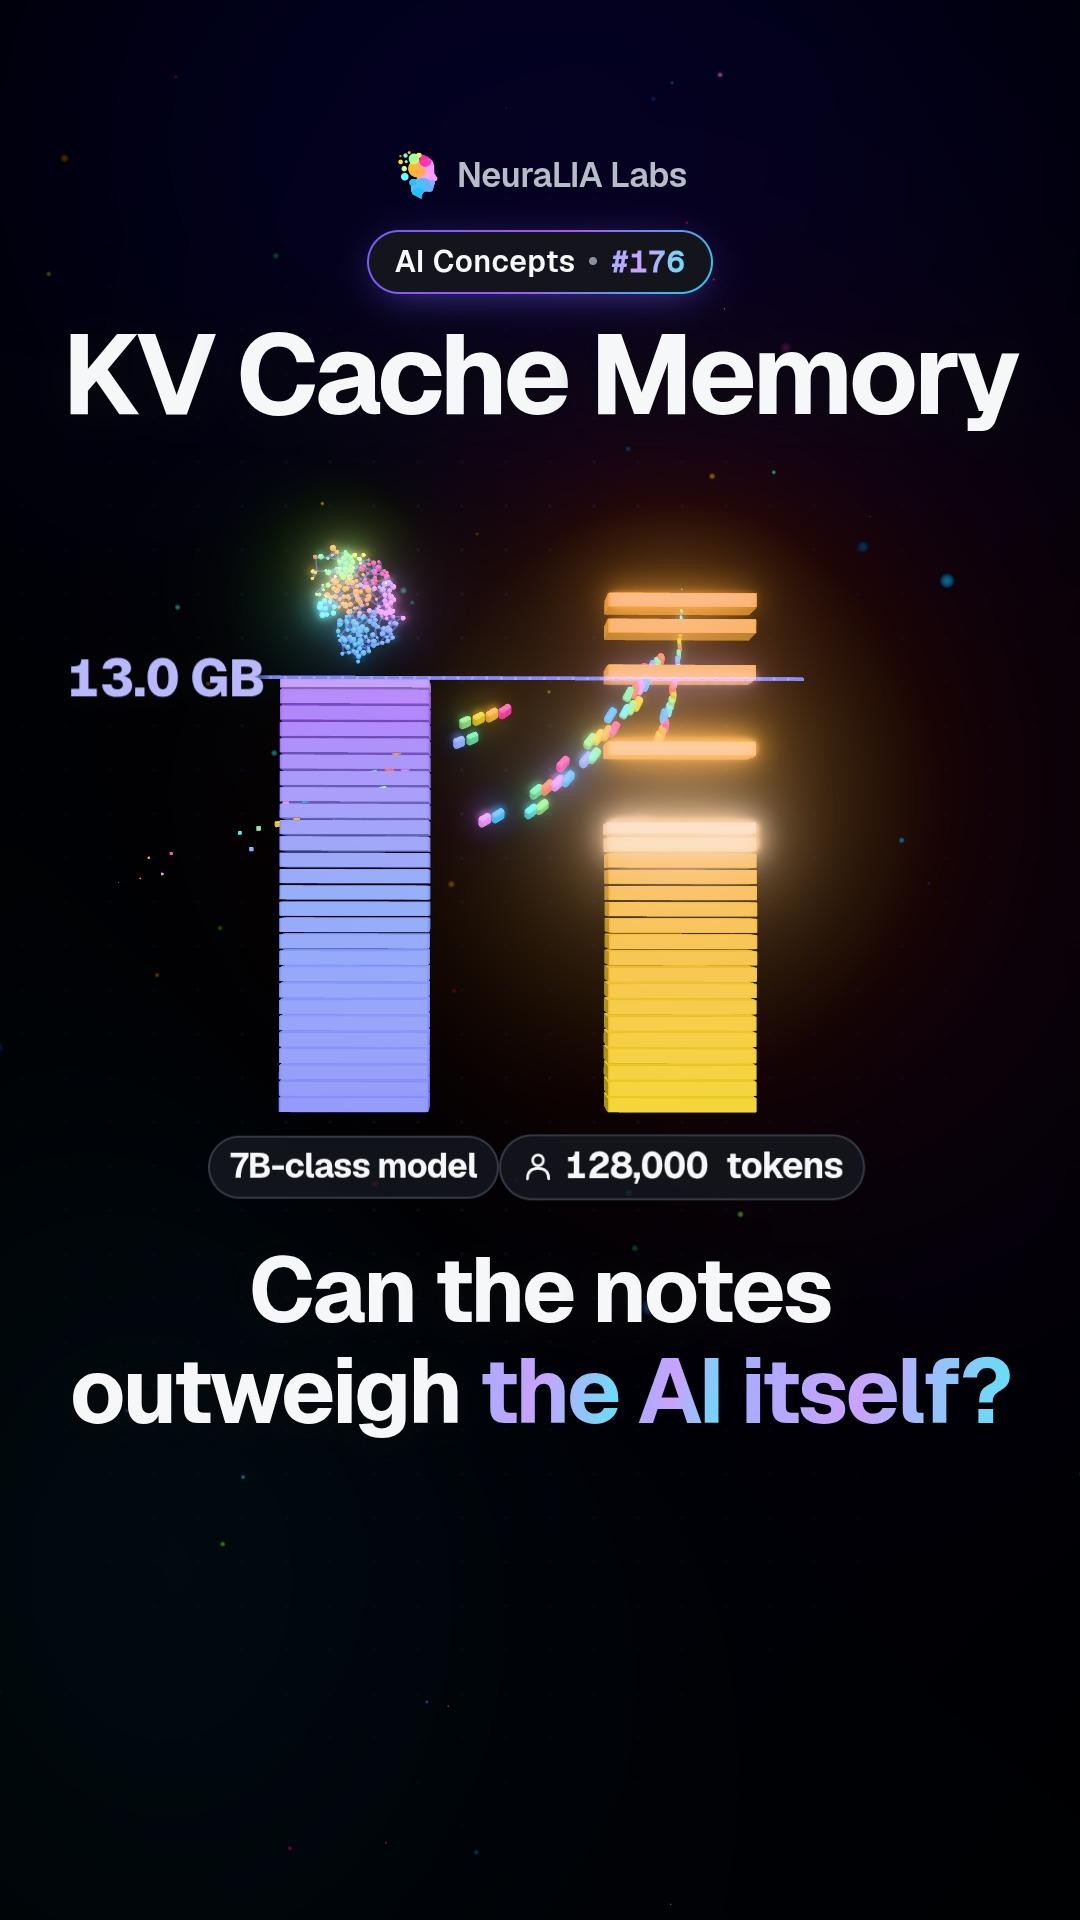
KV cache memory: when a chatbot's notes outgrow the model itself
 #177
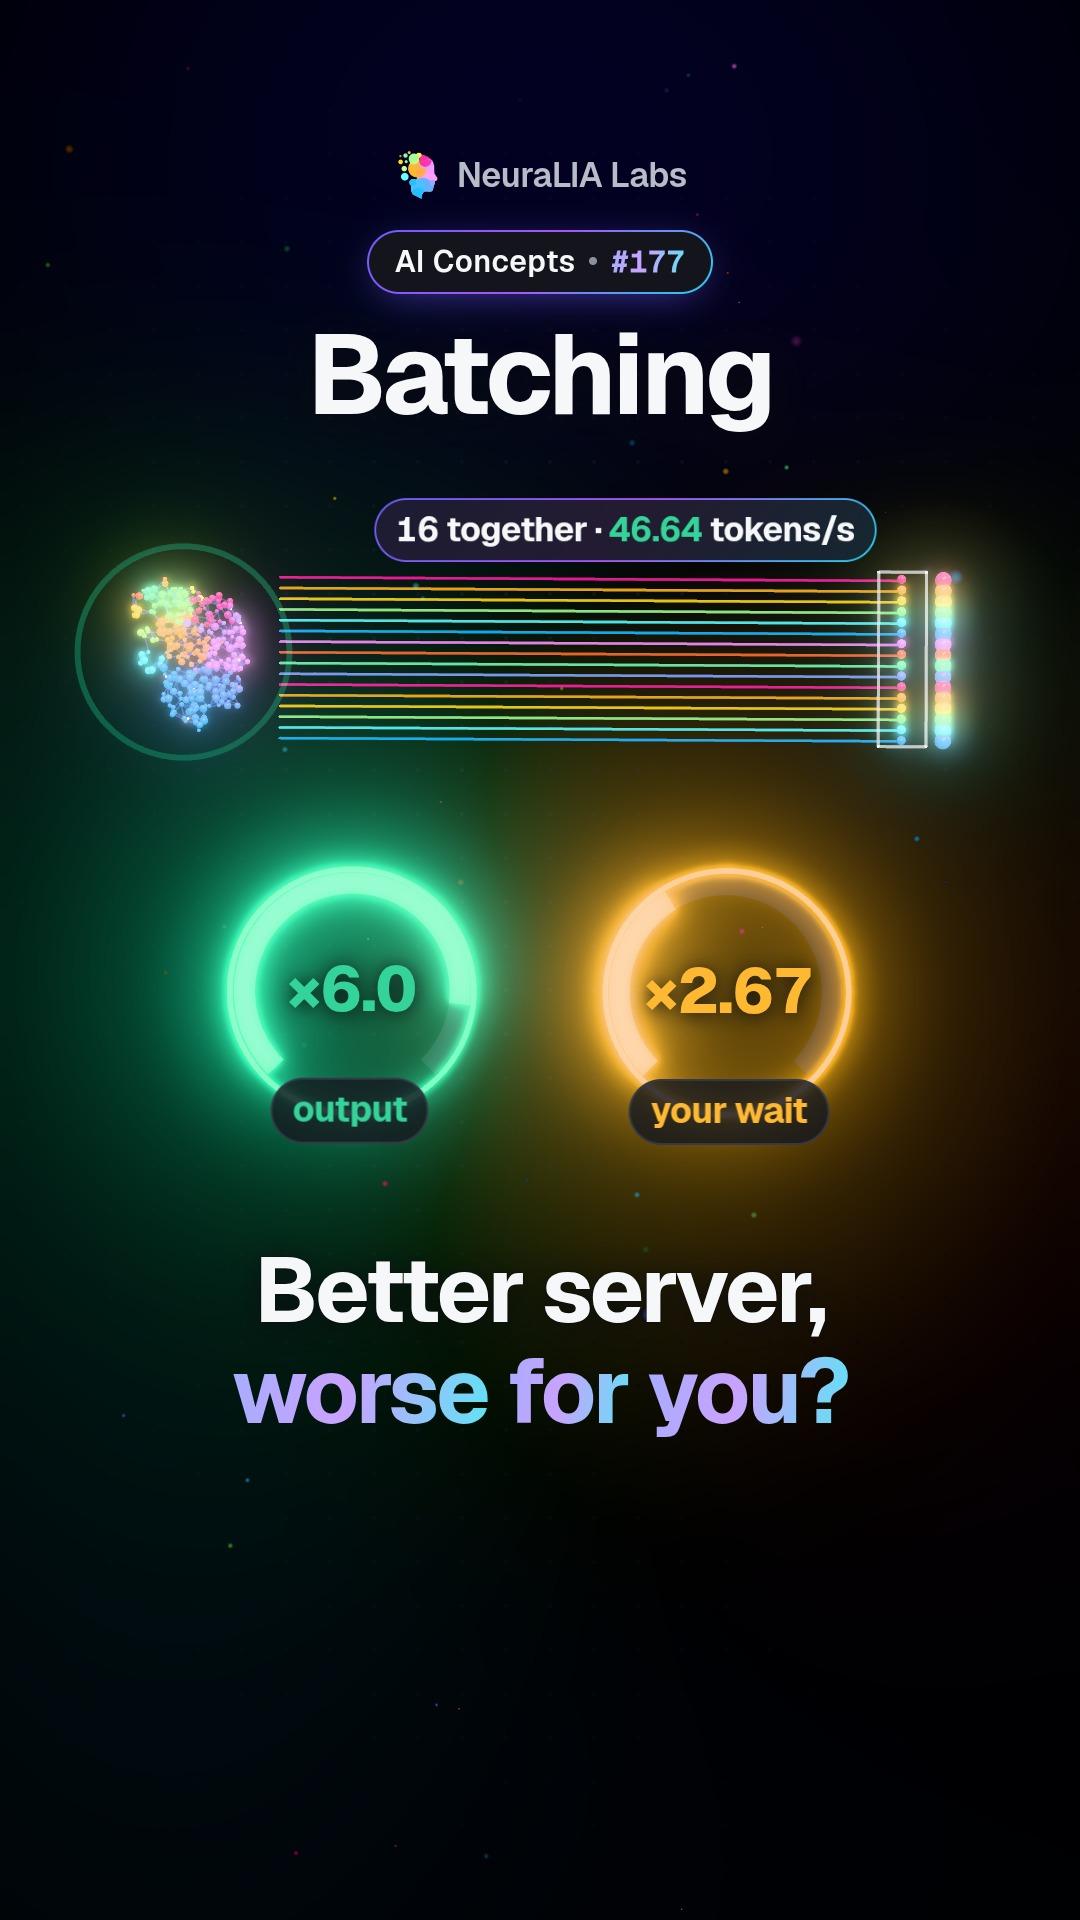
Batching: more output per second, but a longer wait for each user
 #178
Continuous batching: no more waiting for the slowest reply
 #179
PagedAttention: the parking-lot trick behind busy AI servers
文案由 AI 辅助撰写,基于我们免费课程第 13 章。