
 #174
Bu video ve metni İngilizcedir.
Outlier features: the giant numbers hiding inside language models
A few values inside a language model run about a thousand times larger than the rest. See how they wreck simple rounding, and why they are no glitch.
Ayrıntılı olarak
What outlier features are
While a language model reads your text, it turns every word piece into a long list of numbers and passes that list from layer to layer, updating it as it goes. These in-flight numbers are called activations, to tell them apart from the weights, the fixed settings learned in training. Outlier features are a few positions in that list whose values are vastly larger than all the others.
What the video shows
The video shows that inside an AI, a handful of values run about a thousand times larger than the rest. If you round all of them together with one shared scale, the ordinary values lose all their detail.
What the course measured
The course feeds an ordinary prompt of 84 tokens (word pieces) into a small model whose lists hold 896 numbers each, and records the largest value each position reaches:
- One position, number 62, climbs to about 1,580. The typical position never gets past about 1.6. That is roughly a thousand times larger.
- It is not a fluke. The same position is already extreme at layer 4 and still extreme at layer 20, at almost the same value. It belongs to the trained model itself, not to one particular input.
- Drawn as a chart, nearly all 896 positions sit in a tidy pile below 8. Then comes a long empty gap, and then one position alone at the far end.
Why that breaks rounding
Now round those activations to 8 bits, which allows 256 values, using one scale for the whole set. The scale has to stretch all the way to 1,580, so each rounding step becomes about 12.4 wide. A typical activation, though, is around 0.26. It has nowhere to land.
The result: only 14 of the 256 available values are ever used. For ordinary positions, every single token rounds to one and the same number. The rest of the model is handed a constant instead of information.
Then the course tries one change: keep just the 4 most extreme positions out of the rounding. The scale becomes 22 times finer, and the rounding error falls almost fourfold.
An everyday example
Imagine a weighbridge built for lorries that only shows weight in steps of half a tonne. Put a child, an adult and a weightlifter on it one after another. All three read zero. The weighbridge is not broken; it is simply sized for something else. Weigh the lorries on the weighbridge and the people on a bathroom scale, and everyone gets a real number.
A common misconception
It is natural to assume that a value 1,000 times too big must be a glitch, caused by a strange word or one bad layer. The measurement says otherwise. The same position stays extreme from layer 4 all the way to layer 20, and the course concludes that it comes from the trained model, not from the prompt. Outlier features are a stable part of how the model works, so any method that rounds activations has to plan for them.
Why it matters
Outlier features explain why rounding everything with one shared scale fails on activations even at 8 bits, where the same simple recipe holds up on weights. They are the reason behind the fixes people actually use, such as LLM.int8(), which keeps the giant positions apart, and SmoothQuant, which moves the difficulty somewhere it can be handled.
Learn it step by step in Chapter 13 of our free course AI From Scratch: Making Inference Cheap: KV Cache, Batching and Quantization.
Şurada da
Bu bölümden daha fazlası
- #174
 #175
Prefill vs decode: why a chatbot pauses first, then streams smoothly
 #176
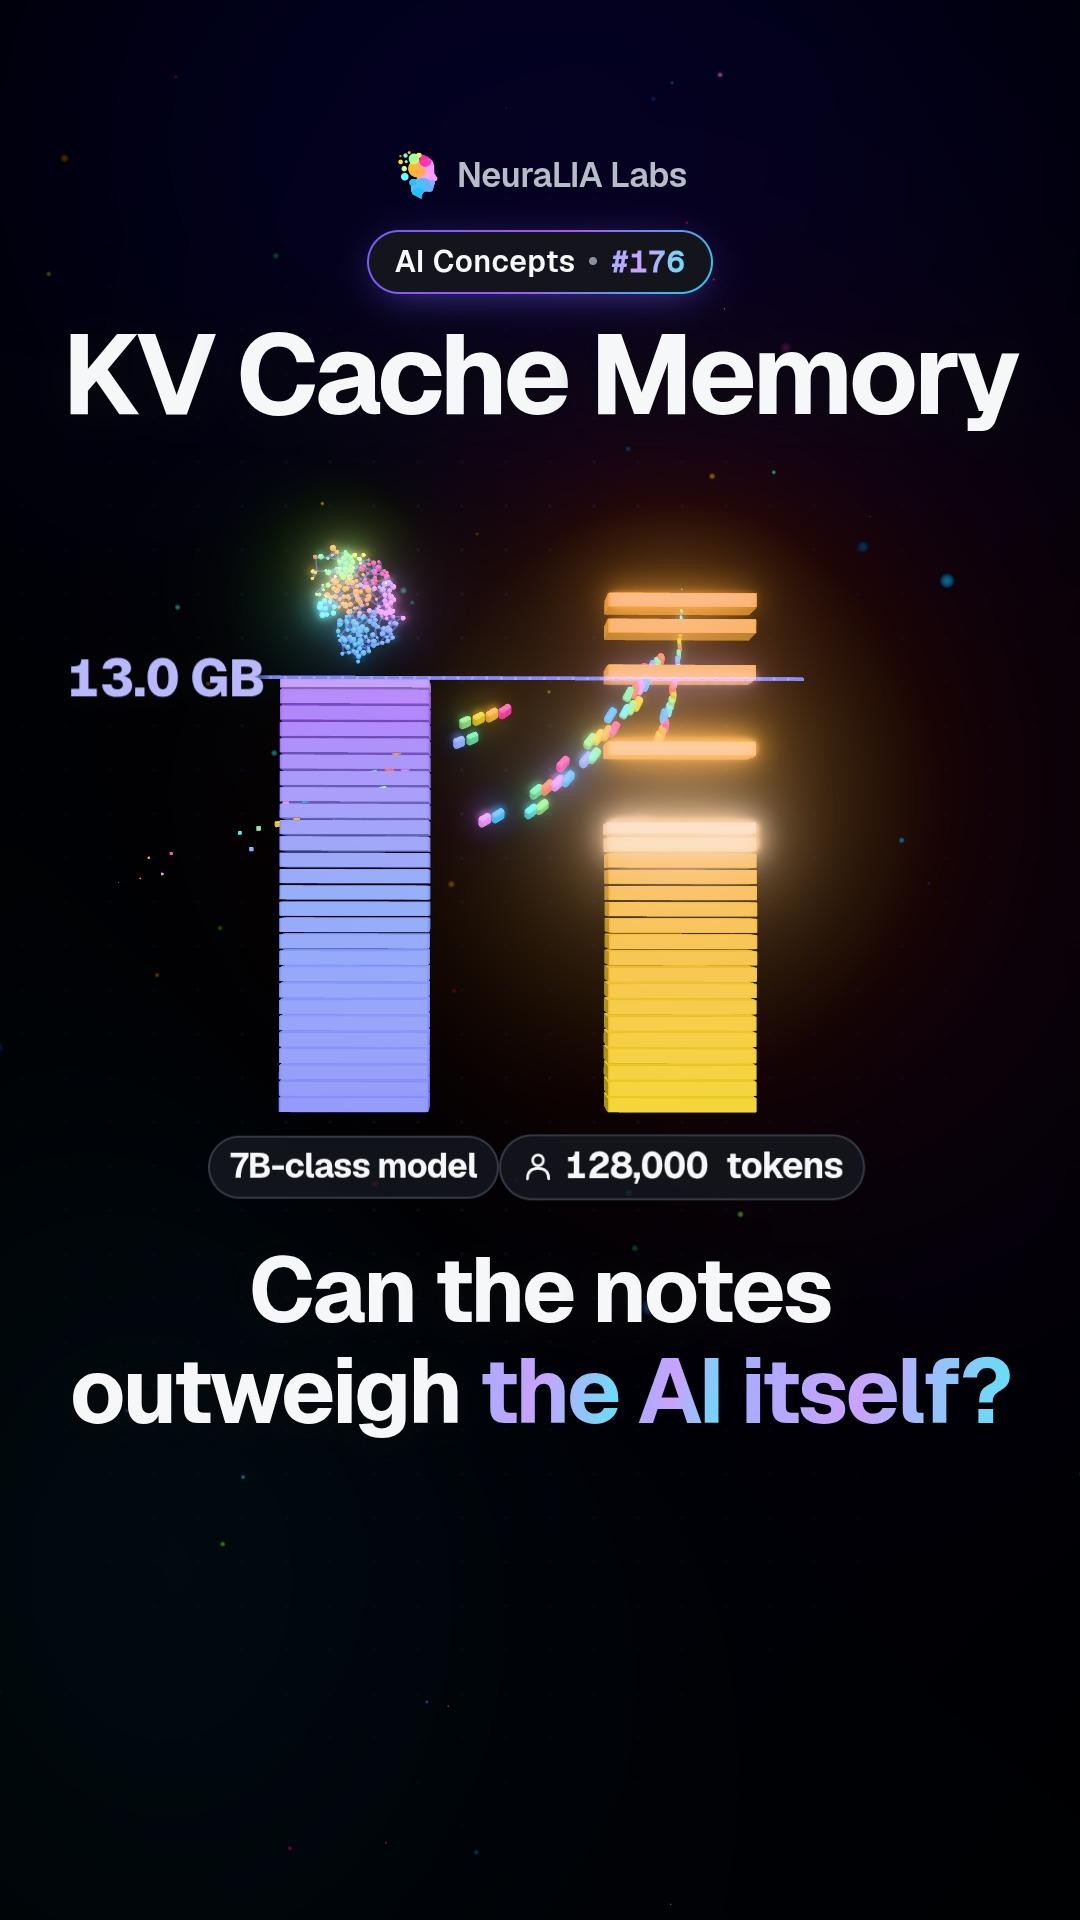
KV cache memory: when a chatbot's notes outgrow the model itself
 #177
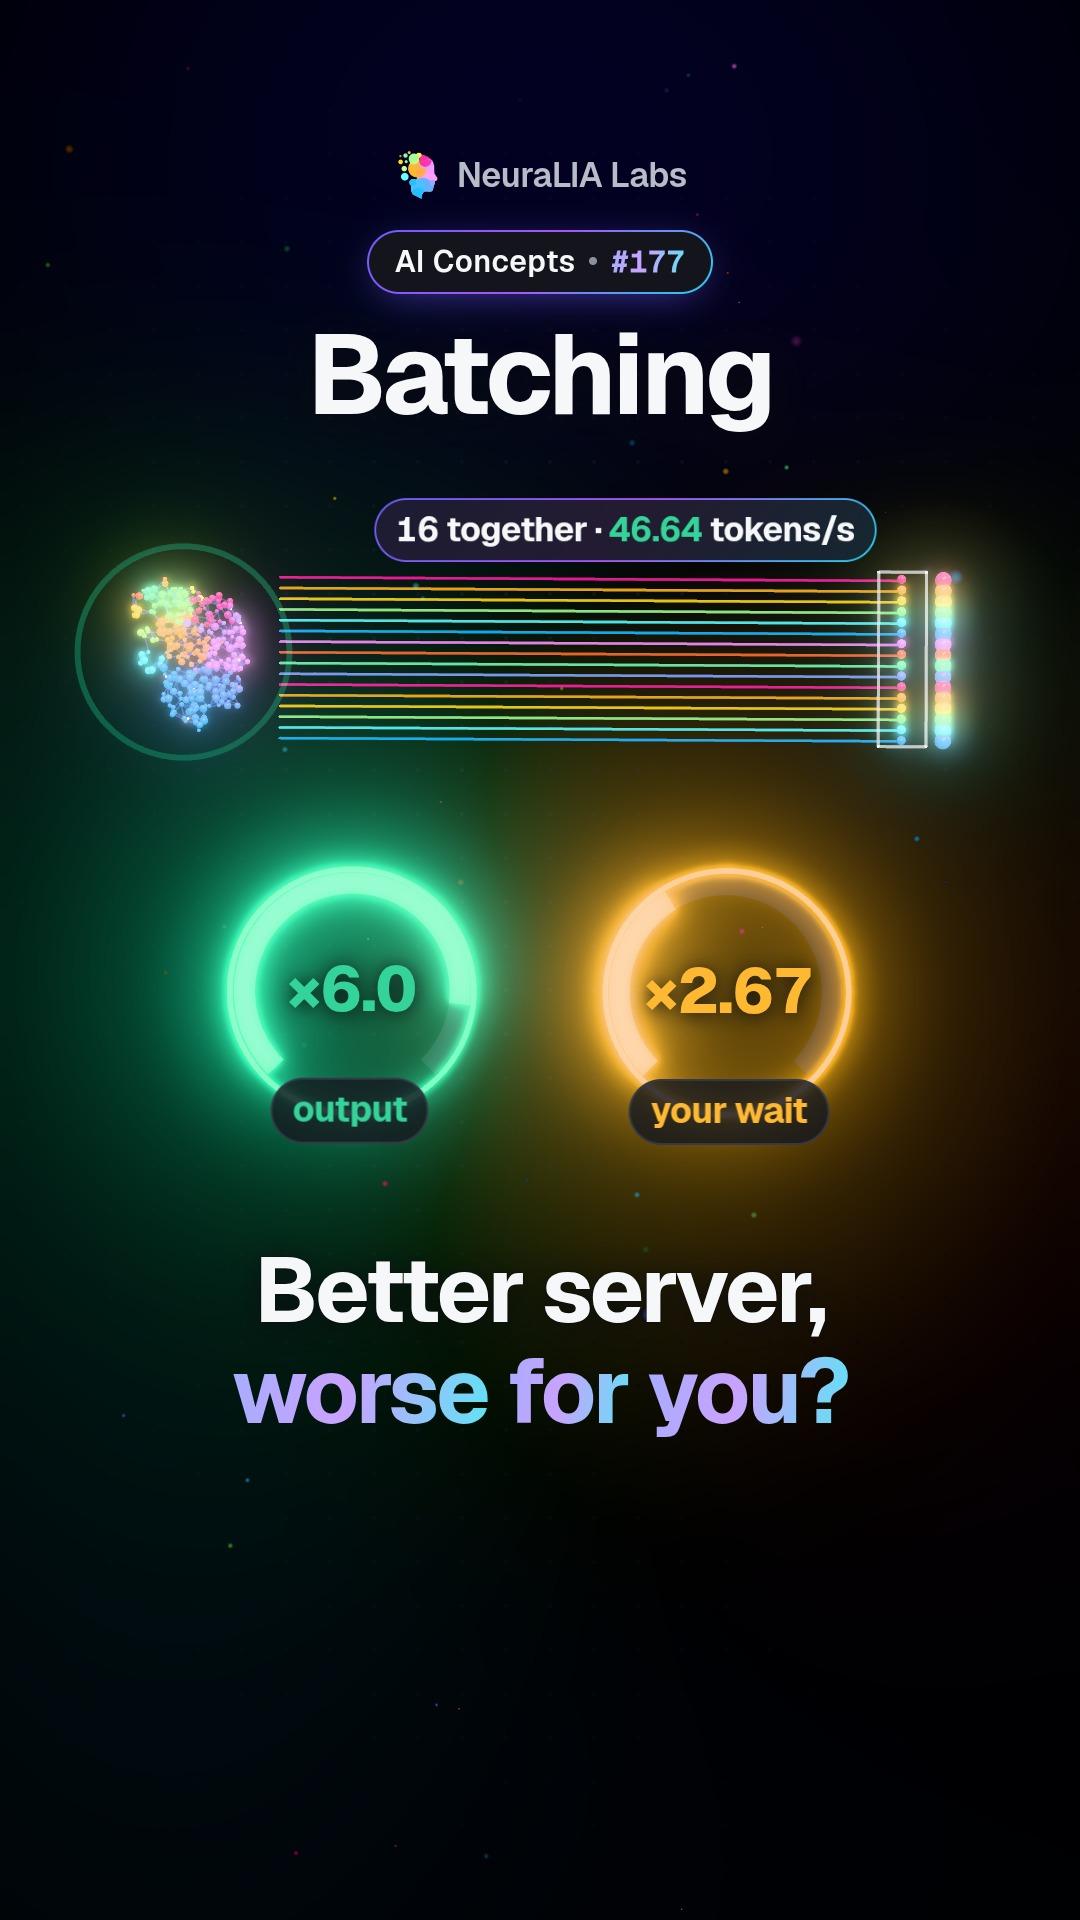
Batching: more output per second, but a longer wait for each user
 #178
Continuous batching: no more waiting for the slowest reply
 #179
PagedAttention: the parking-lot trick behind busy AI servers
Metin, ücretsiz kursumuzun 13. bölümünden AI desteğiyle yazıldı.